# Knock Documentation
# Getting started
An introduction to the basics of Knock.
## What is Knock?
Learn more about what Knock does and how it helps power your product messaging.
---
title: What is Knock?
description: Learn more about what Knock does and how it helps power your product messaging.
tags: ["getting started", "explainer", "explained"]
section: Getting started
---
Knock is product and customer messaging infrastructure. You can use Knock to power all of your product's messaging needs, including transactional messaging, lifecycle marketing, one-time announcements, and in-product messaging, without the effort of building and maintaining your own in-house messaging system.
In this overview, we'll cover the foundational concepts of Knock. Knock is designed to be used collaboratively by engineering, product, and growth teams. It's quick for developers to implement, and simple for non-technical roles to manage.
## Sending messages with Knock
Knock enables three core messaging experiences:
- **Workflows.** Transactional and lifecycle messaging flows that respond to user actions and events.
- **Broadcasts.** One-time messages sent to groups of users for announcements, updates, and campaigns.
- **Guides.** In-app lifecycle messaging that helps users discover features and complete key actions.
### Workflows
Workflows enable you to model complex messaging flows across channels using a variety of logical function steps while respecting a user's individual preferences. Workflows power both transactional messaging (such as order confirmations, password resets, and account updates) and lifecycle messaging (such as onboarding sequences, engagement campaigns, and retention flows).
Workflows can be triggered in several ways: via a direct API call, from a source event in a CDP like Segment, on a recurring or one-off schedule, or automatically when a user joins an audience.
Trigger workflows programmatically using our [REST API](/reference) or any
of our [available SDKs](/developer-tools/sdks) when events happen in your
application.
Connect a CDP like [Segment](/integrations/sources/segment) as an event
source to automatically trigger workflows based on events tracked in your
analytics platform.
```javascript title="Segment track call"
analytics.track("New Comment", {
userId: "user_123",
properties: {
comment_id: "comment_456",
project_name: "My Project",
commenter: {
id: "user_789",
name: "John Hammond"
}
}
});
```
[Schedule workflows](/concepts/schedules) to run at specific times or
intervals for time-based notifications like reminders or recurring updates.
```typescript title="Create a recurring schedule"
import Knock from "@knocklabs/node";
const client = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await client.schedules.create({
recipients: ["user_123", "user_456"],
workflow: "weekly-digest",
repeats: [
{
frequency: "weekly",
days: ["mon"],
hours: 9,
},
],
});
```
Automatically trigger workflows when users are added to an
[audience](/concepts/audiences). With static audiences, you add users via
the API, a CSV upload, or a reverse ETL tool. With dynamic audiences, users
automatically enter and exit based on query rules you define on their
properties.
```typescript title="Add users to a static audience"
import Knock from "@knocklabs/node";
const client = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await client.audiences.addMembers("new-signups", {
members: ["user_123", "user_456"],
});
```
### Broadcasts
Broadcasts enable you to send one-time messages to groups of users for communications that aren't triggered by individual user actions. Unlike workflows that are event-driven, broadcasts are initiated directly from the Knock dashboard and can target specific audiences you've created in Knock.
Broadcasts are perfect for:
- Product announcements and feature releases
- Marketing campaigns and promotional messages
- System maintenance notifications
- Company updates and newsletters
- Time-sensitive alerts and emergency communications
### Guides
Guides power in-app lifecycle messaging using your own components and design system. Unlike traditional messaging that happens outside your app, guides appear contextually within your product interface to provide timely, relevant guidance.
Guides enable you to:
- Create interactive onboarding flows
- Highlight new features and updates
- Guide users through complex workflows
- Drive adoption of key product features
- Provide contextual help and tips
## Mapping your data into Knock
### Users
In most cases, recipients are [users](/concepts/users) in your application. As you trigger workflows for recipients, Knock creates a cache of the data needed to notify them on different platforms, such as an email address, phone number, avatar URL, or push token. Knock also stores custom properties you pass from your application to customize their notifications, such as a plan type, user role, or timezone.
```javascript title="An object used to create a User"
{
// Id is a required prop
id: "1",
// Knock also supports default props for common channels
name: "John Hammond",
email: "hammondj@ingen.net",
phone_number: "555-555-5555",
avatar: "https://ingen.net/headshots/hammondj.jpg",
timezone: "America/Costa_Rica"
// You can add as many custom props as needed. These will be
// merged onto the top-level User object
properties: {
"title": "CEO",
"planType": "allAccess",
"userType": "admin"
}
}
```
### Audiences
[Audiences](/concepts/audiences) are defined user segments that can be used to target workflows, guides, and broadcasts. You can build static audiences by manually adding users via a reverse ETL source such as Hightouch or Census, a CSV upload, the API, or manually in the Knock dashboard, or you can build dynamic audiences with a set of query rules on top of the user data in Knock.
### Tenants
[Tenants](/concepts/tenants) represent accounts, organizations, or workspaces your users belong to. They allow you to map your product's structure into Knock to power tenant-specific features like branding or preferences.
### Objects
[Objects](/concepts/objects) allow you to map custom entities into your project and relate them to users with a subscription. They can help you ensure Knock always has the most up-to-date information required to send your notifications, and they enable you to send notifications to non-user recipients.
## Channels
Channels in Knock represent a specific provider you have configured to send messages. You can include channel steps in your workflows or use them in broadcasts to send messages with the providers you already use in production. Knock supports the following channel types and providers:
Knock comes with a [built-in email channel](/integrations/email/knock-test)
and also supports sending email with [Amazon
SES](/integrations/email/aws-ses),
[Mailersend](/integrations/email/mailersend),
[Mailgun](/integrations/email/mailgun),
[Mailjet](/integrations/email/mailjet),
[Mailtrap](/integrations/email/mailtrap),
[Mandrill](/integrations/email/mandrill),
[Postmark](/integrations/email/postmark),
[Resend](/integrations/email/resend),
[Sendgrid](/integrations/email/sendgrid), [SMTP](/integrations/email/smtp),
and [Sparkpost](/integrations/email/sparkpost).
Knock supports sending SMS with [Africa's
Talking](/integrations/sms/africas-talking), [AWS
SNS](/integrations/sms/aws-sns), [Mailersend](/integrations/sms/mailersend),
[MessageBird](/integrations/sms/messagebird),
[Plivo](/integrations/sms/plivo), [Sinch](/integrations/sms/sinch), [Sinch
MessageMedia](/integrations/sms/sinch-message-media),
[Telnyx](/integrations/sms/telnyx), [Twilio](/integrations/sms/twilio), and
[Vonage](/integrations/sms/vonage).
Knock supports sending push messages with [Apple Push Notification Service
(iOS)](/integrations/push/apns), [Expo (React
Native)](/integrations/push/expo), [Firebase Cloud Messaging
(Android)](/integrations/push/firebase), and
[OneSignal](/integrations/push/one-signal).
Knock supports sending chat messages with [Slack](/integrations/chat/slack),
[Discord](/integrations/chat/discord), [Microsoft
Teams](/integrations/chat/microsoft-teams),
[WhatsApp](/integrations/chat/whatsapp).
Knock provides [a real-time in-app feed API](/integrations/in-app/knock) for
receiving notifications, along with drop-in components to display them to
your users.
Knock enables you to build [in-app guides](/in-app-ui/guides/overview) that
display contextual messages within your product using your own components
and design system.
A message that is generated as a part of a workflow or broadcast is called a Message, and Knock enables you to define dynamic message templates using a combination of a drag-and-drop editor and the Liquid templating language.
This helps product and marketing teams standardize on one templating system instead of using different templating languages for different providers. It also has the added benefit of lifting these messages out of your codebase so you can iterate quickly on customer communications without a developer.
## Functions
Each workflow can combine multiple function steps to model complex logic that creates better notification experiences. You can combine the following function steps with any number of channel steps to create personalized notifications for your users:
[A batch step](/designing-workflows/batch-function) condenses multiple
activities into one notification, e.g. batch all of the comments on this
document for one hour and then send one email with all of the activities.
[A delay step](/designing-workflows/delay-function) waits for a specified
duration before proceeding to the next step in a workflow, e.g. send the new
user a follow-up email ten days after they sign up.
[A branch step](/designing-workflows/branch-function) uses multiple
conditions to execute different branches of logic, e.g. if `user.planType
=== 'pro'` send them email A, else send them email B.
[An experiment step](/designing-workflows/experiment-function) splits
recipients into randomized, percentage-based cohorts for A/B testing and
experimentation, e.g. send 50% of recipients email template A and 50% email
template B to measure engagement.
[A throttle step](/designing-workflows/throttle-function) controls how many
times a user is notified for a particular workflow over a specified
duration, e.g. trigger the `server is down` workflow every minute while the
server is down, but only send a max of one email every 5 minutes.
[A fetch step](/designing-workflows/fetch-function) makes an HTTP request to
an external service and uses the returned data in subsequent steps, e.g.
query an MLS API for recent home sales in the user's zip code and render
them in an email.
[An AI agent step](/designing-workflows/ai-agent-function) runs a prompt on
an AI model and merges the response into workflow state, e.g. enrich
recipient data using their domain to personalize welcome messaging.
[A trigger workflow step](/designing-workflows/trigger-workflow-function)
allows you to trigger another workflow from within the current workflow,
e.g. trigger a "welcome_sequence" workflow after recieving an
"account_setup" notification.
In addition to combining channel steps and function steps to create complex workflows, you can augment these steps with additional logic based on the user recipient, inputs from your application, or the status of previous workflow steps. These are called step conditions.
## Step conditions
Step conditions exist across both channel and function steps, and they allow you to conditionally execute steps based on trigger payload data, user properties, or the status of previous steps.
**Examples:**
- Only send an email message if an in-app message has not been seen
- Only send an in-app notification if `recipient.plan === "pro"`
- Only execute a delay step if `delay === true` in the trigger payload
In addition to giving your technical and non-technical users the ability to construct these workflows via a drag-and-drop editor, Knock also enables your users to exercise control over their own notification experience using a flexible preferences model.
## Preferences
In Knock, each workflow run and broadcast is executed on behalf of a recipient, and each recipient can specify their preferences to receive messages across a number of different criteria: channel types, individual workflows, workflow categories, and broadcast types.
Application developers have control over how these preference sets are presented to the user and which options to surface, but Knock enforces these preferences during every workflow run and broadcast automatically.
You can learn more about how to set a user's preferences in our [preferences overview](/preferences/overview).
## Next steps
Now that you understand some of the core concepts of Knock, you can either start building with Knock or explore some of the more advanced features Knock offers.
### Build something
If you want to start by adding Knock to your existing system, you can check out our quick start guide to implement your first workflow. This quick start will help you integrate Knock with your backend codebase.
If you want to keep learning about Knock using a curated example application, check out our catalog of [examples apps](/getting-started/example-apps). Here are some recommendations:
### Keep learning
While workflows, broadcasts, and guides are at the heart of Knock, our goal is to build a complete messaging system for our customers. Here is an overview of some of the more-advanced features that we provide.
#### UI components
Knock provides developers with React components like `` and `` to use in their applications. You can read more about building in-app UI with Knock for both web and mobile [here](/in-app-ui/overview).
#### Advanced concepts
There is a lot more to learn about Knock, and our [concepts overview page](/concepts/overview) is a good place to start. Here are use cases our customers commonly solve with Knock:
- Powering [translation and localization](/template-editor/translations) and managing timezone-aware delivery.
- Creating advanced messaging logic using [subscriptions](/concepts/subscriptions) and [schedules](/concepts/schedules).
- Integrating Knock with your application's data model, using [tenants](/concepts/tenants) and [objects](/concepts/objects) to power customized experiences.
- Using [the template editor](/template-editor/overview) to standardize messaging templates across providers.
#### Developer tools
Knock is a developer-first platform, with both [environment](/concepts/environments) and [commit models](/concepts/commits). If you want to work with Knock resources in code, you can use our [Management API](/developer-tools/management-api) or [CLI](/developer-tools/knock-cli).
Knock also supports an [MCP](/ai/mcp-server) server, which allows you to work with Knock resources in your IDE, entirely using natural language. Our MCP server is a great way to migrate from a legacy system to Knock, or to make updates across many Knock resources at once.
Once you're sending messages through Knock, we offer observability tools like [workflow run logs](/send-notifications/debugging-workflows) (to examine all steps of workflow execution in your dashboard) and data streaming into a monitoring system like Datadog with [extensions](/integrations/extensions/overview).
## Quick start
## General
Set up Knock with an agent, or follow the manual steps.
---
title: Get started with Knock
description: Set up Knock with an agent, or follow the manual steps.
tags: ["getting started"]
section: Getting started
---
First, create a Knock account if you don't already have one and log into the Knock dashboard.
We have SDKs available in [most major languages](/developer-tools/sdks). Don't see your language listed here? [Let us know](mailto:support@knock.app)!
You can find your public and secret API keys under the **Platform** section of the Knock dashboard. Since we're working on the backend here, you'll want to use the secret key.
As a best practice, your API key should be set as an environment variable and should not be checked into source control.
```bash
KNOCK_API_KEY='sk_example_123456789'
```
Next we'll design our first workflow in Knock via the dashboard.
A workflow encapsulates a notification in Knock. Each workflow takes a trigger call via the Knock API, runs the data you provide through a set of logic you configure, and outputs the actual messages that will be sent to your end users. All channel routing and message design takes place within the workflow.
Here's how to build your first workflow:
Click the "+ Workflow" button in the top right corner of the Knock dashboard. Name it whatever you like.
To send a notification, a workflow needs at least one [channel step](/designing-workflows/channel-step). To add this step, we'll click “edit steps” to enter the workflow canvas editor.
Here we can see a number of steps available for us to add to our workflow, including functions (such as [batch](/designing-workflows/batch-function) and [delay](/designing-workflows/delay-function)) and channels.
Choose the delivery channel you'd like to use in your workflow and drag it onto the workflow canvas.
After adding a channel step, we can configure the notification's content by clicking on "Edit template" in the channel's edit step view to see that step's [message template](/template-editor/overview).
The template starts with default copy, so we'll just use that for now.
Before we leave the workflow canvas and head back to your backend, let’s click on the trigger step to grab a payload data sample to use when we call Knock.
This sample payload is auto-generated when you create a workflow within the Knock dashboard. It gives us the JSON blob we'll need to pass through as `data` in our trigger call in order to populate any of the custom properties defined in our workflow.
Knock follows a versioning model similar to Git. This means that before you can trigger your new workflow via the API, you'll need to commit it to your current environment to activate the workflow.
You do this using the `Commit` button in the header of the workflow canvas. You can review your changes using a diff viewer and leave a meaningful commit message about what has changed.
Now we're ready to trigger our workflow via the Knock API. You can also learn more about workflows and channels in Knock via our [documentation on designing workflows](/send-notifications/designing-workflows).
Now, you'll trigger your workflow to notify a set of users. When triggering workflows, you need to provide the following required pieces of data in your call to the Knock API:
- `recipients` – The list of users to notify.
- `data` – The variable data that will populate your notification templates. Here you'll use the sample data payload we grabbed in the previous step.
In the example below, we trigger a new comment notification workflow for two project members, using [inline identification](/managing-recipients/identifying-recipients#inline-identification).
Learn more about trigger calls in our [API reference](/api-reference/workflows/trigger).
Knock uses [logically separated environments](/concepts/environments) to control the roll-out of your notifications. When you're happy with the way your workflows work and look, ensure they're in your production environment to start sending notifications to your real users. You can create workflows directly in production, or create them in development and promote them to production.
See our [going to production](/tutorials/implementation-guide#going-to-production) checklist to review a complete set of steps you'll need to take to push your workflows to production.
This was a simple overview to send your first notification with Knock. Read on to see how Knock can drive your notification needs, no matter their complexity.
- [Learn about Knock's core data concepts](/concepts/overview)
- [Learn how to set up a real-time, in-app notification feed in minutes](/notification-feeds/getting-started)
## Go further
## Next.js
Set up Knock with an agent, or follow the manual steps.
---
title: Get started with Knock
description: Set up Knock with an agent, or follow the manual steps.
tags: ["getting started"]
section: Getting started
---
This page covers how to integrate Knock's `NotificationFeed` component in Next.js and send your first notification using a server action.
First, create a Knock account if you don't already have one and log into the Knock dashboard.
Run the following command to create a new Next.js application.
```bash title="Command to create a new Next.js app"
npm create next-app@latest knock-next-quickstart
```
Follow the CLI prompts and use all of the defaults selections, then run the following command to change into your project directory:
```bash title="Install dependencies and test dev server"
cd knock-next-quickstart
npm install
npm run dev
```
Install the following dependencies so you can use the Knock `NotificationFeed` component in your app and trigger workflows from server actions.
```bash title="Install Knock dependencies"
npm install @knocklabs/react @knocklabs/node
```
Run the following command to generate a new `env.local` file and add the following environment variables to authenticate your requests to Knock:
```bash title="Create an env file"
touch .env.local
```
You can find your [public and secret API keys](/developer-tools/api-keys) under the **Platform** section of the Knock dashboard.
You can find the `id` of your Knock in-app feed channel in **Settings** > **Integrations** > **Channels**.
```javascript title="Add these values to .env.local"
KNOCK_API_KEY='sk_example_123456789'
NEXT_PUBLIC_KNOCK_PUBLIC_API_KEY='pk_example_123456789'
NEXT_PUBLIC_KNOCK_FEED_CHANNEL_ID='f9923d96-bee5-48bd-a1ff-31b6637b7385'
```
You'll need to create a component to render the default Knock components. Run the following command to create a new component file called `inbox.tsx` inside of the `app`:
```bash title="Create an inbox.tsx file"
touch ./app/inbox.tsx
```
Since this file uses client-side React APIs, it will need to be a client component. You can add the following code to the empty `inbox.tsx` file:
```javascript title="Add this code to inbox.tsx"
"use client";
import {
KnockProvider,
KnockFeedProvider,
NotificationFeed,
NotificationIconButton,
} from "@knocklabs/react";
// Required CSS import, unless you're overriding the styling
import "@knocklabs/react/dist/index.css";
const Inbox = () => {
// An example of fetching the current authenticated user
const user = {
id: "12c23775-5902-481a-b8ea-d1704aabc769",
};
return (
<>
{}} />
);
};
export default Inbox;
```
In production, you will want to colocate `KnockProvider` and `KnockFeedProvider` at a higher level in your application.
If you pass a `user` that doesn't exist, Knock will automatically create one with the specified `id` using [client-side inline identification](/managing-recipients/identifying-recipients#inline-identification).
Next, replace the contents of `/app/page.tsx` with the code below to import the `Inbox` component and render it in `page.tsx`.
```javascript title="Render the Inbox component"
import Inbox from "./inbox";
const Page = () => {
return (
Knock Inbox Test
);
};
export default Page;
```
Next, run your development server to render the `Inbox` component. There will be no messages, but you should be able to switch between tabs.
```bash title="Run Next.js dev server"
npm run dev
```
Next we'll design our first workflow in Knock via the dashboard.
A workflow encapsulates a notification in Knock. Each workflow takes a trigger call via the Knock API, runs the data you provide through a set of logic you configure, and outputs the actual messages that will be sent to your end users. All channel routing and message design takes place within the workflow.
Here's how to build your first workflow:
Navigate to the **Workflows** section of the Knock dashboard. Click the "+ Workflow" button in the top right corner of the Knock dashboard. Name it `knock-quickstart` to test your integration.
To send a notification, a workflow needs at least one [channel step](/designing-workflows/channel-step). To add this step, we'll click “edit steps” to enter the workflow canvas editor.
Here we can see a number of steps available for us to add to our workflow, including functions (such as [batch](/designing-workflows/batch-function) and [delay](/designing-workflows/delay-function)) and channels.
Drag the 'In-app feed' step onto the workflow canvas.
After adding your channel step, you can configure the notification's content by clicking on "Edit content" in the channel's edit step view to see that step's [message template](/template-editor/overview).
The template starts with default copy, so we'll just use that for now.
Knock follows a versioning model similar to Git. This means that before you can trigger your new workflow via the API, you'll need to commit it to your current environment to activate the workflow.
You do this using the `Commit` button in the header of the workflow canvas. You can review your changes using a diff viewer and leave a meaningful commit message about what has changed.
Now we're ready to trigger our workflow via the Knock API. You can also learn more about workflows and channels in Knock via our [documentation on designing workflows](/send-notifications/designing-workflows).
Now, you'll trigger your workflow to notify your user using a server action. Run the following command to create a file named `trigger.action.ts` in the `app` directory:
```bash title="Create a file named trigger.action.ts"
touch ./app/trigger.action.ts
```
When triggering workflows, you need to provide the following required data in your Knock API request:
- `recipients` – The list of users to notify. This list should contain the same user `id` you used when configuring the `Inbox` component.
- `data` – The variable data that will populate your notification templates. Here you'll include a object with a `message` key.
Add the code below to `trigger.action.ts` to trigger the `knock-quickstart` workflow.
```javascript title="Add this code to trigger.action.ts"
"use server";
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
const user = {
id: "12c23775-5902-481a-b8ea-d1704aabc769",
};
export default async function triggerWorkflow() {
const workflow_run_id = await knock.workflows.trigger("knock-quickstart", {
data: { message: "Here's a message" },
recipients: [user.id],
});
return workflow_run_id;
}
```
Learn more about trigger calls in our [API reference](/api-reference/workflows/trigger).
To trigger your workflow, you'll need to connect the server action in `trigger.action.ts` to a UI element in `page.tsx`. First, run the following command to create a new component file called `workflow-trigger.tsx` in the `app` directory:
```bash title="Create a new component file called workflow-trigger.tsx"
touch ./app/workflow-trigger.tsx
```
This client component will import the `triggerWorkflow` server action and tie it to the `onClick` prop of a `button`. Replace the contents of `workflow-trigger.tsx` with the following code:
```javascript title="Add this code to workflow-trigger.tsx"
"use client";
import triggerWorkflow from "./trigger.action";
export default function WorkflowTrigger() {
return (
);
}
```
Next, add the `WorkflowTrigger` component to `page.tsx`. You can
replace the contents of `page.tsx` with the following code:
```javascript title="Completed page.tsx"
import Inbox from "./inbox";
import WorkflowTrigger from "./workflow-trigger";
const Page = () => {
return (
Knock Inbox Test
);
};
export default Page;
```
With the server started, you can click the **Trigger Workflow** button and the application will run the `triggerWorkflow` server action and produce a notification in the feed.
Knock uses [logically separated environments](/concepts/environments) to control the roll-out of your notifications. When you're happy with the way your workflows work and look, ensure they're in your production environment to start sending notifications to your real users. You can create workflows directly in production, or create them in development and promote them to production.
See our [going to production](/tutorials/implementation-guide#going-to-production) checklist to review a complete set of steps you'll need to take to push your workflows to production.
This was a simple overview to send your first notification with Knock. Read on to see how Knock can drive your notification needs, no matter their complexity.
- [Learn about Knock's core data concepts](/concepts/overview)
- [Learn how to set up a real-time, in-app notification feed in minutes](/notification-feeds/getting-started)
## Go further
## React
Set up Knock with an agent, or follow the manual steps.
---
title: Get started with Knock
description: Set up Knock with an agent, or follow the manual steps.
tags: ["getting started"]
section: Getting started
---
This page covers how to integrate Knock's `NotificationFeed` component in a React application and send your first notification using Knock's test runner.
First, create a Knock account if you don't already have one and log into the Knock dashboard.
Run the following command to create a new React application.
```bash title="Command to create a new React app"
npm create vite@latest knock-react-quickstart -- --template react-ts
```
Follow the CLI prompts and use all of the default selections, then run the following command to change into your project directory:
```bash title="Install dependencies and test dev server"
cd knock-react-quickstart
npm install
npm run dev
```
Install the following dependencies so you can use the Knock `NotificationFeed` component in your app and trigger workflows from server actions.
```bash title="Install Knock dependencies"
npm install @knocklabs/react
```
Run the following command to generate a new `env.local` file and add the following environment variables to authenticate your requests to Knock:
```bash title="Create an env file"
touch .env.local
```
You can find your [public and secret API keys](/developer-tools/api-keys) under the **Platform** section of the Knock dashboard.
You can find the `id` of your Knock in-app feed channel in **Settings** > **Integrations** > **Channels**.
```javascript title="Add these values to .env.local"
VITE_KNOCK_PUBLIC_API_KEY='pk_example_123456789'
VITE_KNOCK_FEED_CHANNEL_ID='f9923d96-bee5-48bd-a1ff-31b6637b7385'
````
You'll need to create a component to render the default Knock components. Run the following command to create a new component file called `inbox.tsx` inside of the `app`:
```bash title="Create an inbox.tsx file"
mkdir ./src/components
touch ./src/components/inbox.tsx
```
Since this file uses client-side React APIs, it will need to be a client component. You can add the following code to the empty `inbox.tsx` file:
```javascript title="Add this code to inbox.tsx"
import {
KnockProvider,
KnockFeedProvider,
NotificationFeed,
NotificationIconButton,
} from "@knocklabs/react";
// Required CSS import, unless you're overriding the styling
import "@knocklabs/react/dist/index.css";
const Inbox = () => {
// Use the authenticated user's ID in KnockProvider below to inline identify the current user
const user = {
id: "12c23775-5902-481a-b8ea-d1704aabc769",
};
return (
<>
{}} />
);
};
export default Inbox;
````
In production, you will want to colocate `KnockProvider` and `KnockFeedProvider` at a higher level in your application.
If you pass a `user` that doesn't exist, Knock will automatically create one with the specified `id` using [client-side inline identification](/managing-recipients/identifying-recipients#inline-identification).
Next, replace the contents of `/src/App.tsx` with the code below to import the `Inbox` component and render it in your `App` component.
```javascript title="Render the Inbox component"
import "./App.css";
import Inbox from "./components/inbox";
function App() {
return (
<>
Knock Inbox Test
);
}
export default App;
```
Next, run your development server to render the `Inbox` component in a browser. There will be no messages, but you should be able to switch between tabs.
```bash title="Run Vite dev server"
npm run dev
```
Next we'll design our first workflow in Knock via the dashboard.
A workflow encapsulates a notification in Knock. Each workflow takes a trigger call via the Knock API, runs the data you provide through a set of logic you configure, and outputs the actual messages that will be sent to your end users. All channel routing and message design takes place within the workflow.
Here's how to build your first workflow:
Navigate to the **Workflows** section of the Knock dashboard. Click the "+ Workflow" button in the top right corner of the Knock dashboard. Name it `knock-quickstart` to test your integration.
To send a notification, a workflow needs at least one [channel step](/designing-workflows/channel-step). To add this step, we'll click “edit steps” to enter the workflow canvas editor.
Here we can see a number of steps available for us to add to our workflow, including functions (such as [batch](/designing-workflows/batch-function) and [delay](/designing-workflows/delay-function)) and channels.
Drag the 'In-app feed' step onto the workflow canvas.
After adding your channel step, you can configure the notification's content by clicking on "Edit content" in the channel's edit step view to see that step's [message template](/template-editor/overview).
The template starts with default copy, so we'll just use that for now.
Knock follows a versioning model similar to Git. This means that before you can trigger your new workflow via the API, you'll need to commit it to your current environment to activate the workflow.
You do this using the `Commit` button in the header of the workflow canvas. You can review your changes using a diff viewer and leave a meaningful commit message about what has changed.
Now we're ready to trigger our workflow via the Knock API. You can also learn more about workflows and channels in Knock via our [documentation on designing workflows](/send-notifications/designing-workflows).
Now, you'll trigger your workflow to a user and produce a notification in the feed. You can do that through the test runner in the workflow editor, or via API call. Your recipient should be the `id` of the `user` we identified in our `Inbox` component.
When triggering workflows, you need to provide the following required pieces of data in your call to the Knock API:
- `recipients` – The list of users to notify.
- `data` – The variable data that will populate your notification templates. Here you'll use the sample data payload we grabbed in the previous step.
In the example below, we trigger the `knock-quickstart` workflow for the `user` we identified with the feed.
```javascript title="Example server code to trigger workflow"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
const user = {
id: "12c23775-5902-481a-b8ea-d1704aabc769",
};
await knock.workflows.trigger("knock-quickstart", {
data: { message: "Here's a message" },
recipients: [user.id],
});
```
Learn more about trigger calls in our [API reference](/api-reference/workflows/trigger).
Knock uses [logically separated environments](/concepts/environments) to control the roll-out of your notifications. When you're happy with the way your workflows work and look, ensure they're in your production environment to start sending notifications to your real users. You can create workflows directly in production, or create them in development and promote them to production.
See our [going to production](/tutorials/implementation-guide#going-to-production) checklist to review a complete set of steps you'll need to take to push your workflows to production.
This was a simple overview to send your first notification with Knock. Read on to see how Knock can drive your notification needs, no matter their complexity.
- [Learn about Knock's core data concepts](/concepts/overview)
- [Learn how to set up a real-time, in-app notification feed in minutes](/notification-feeds/getting-started)
## Go further
## Example apps
Example applications to help you get started with Knock.
---
title: Knock example apps
description: Example applications to help you get started with Knock.
tags: ["nodejs", "using knock", "getting started", "react"]
section: Getting started
---
Below you'll find a number of Knock example apps to learn from or incorporate into your project.
## In-app notification examples (web)
## Web app examples
## Mobile examples
# Concepts
Learn about the key concepts in Knock.
## Overview
Learn about the key concepts in Knock.
---
title: Core concepts
description: Learn about the key concepts in Knock.
tags: ["how knock works"]
section: Concepts
---
## Workflows
Workflows are triggered journeys that send notifications to your recipients. They can be triggered via an API call, an event, on a schedule for a recipient, or when a user enters a specific audience. Workflows consists of channel and function steps.
Workflows are useful for transactional notifications and lifecycle-based messaging such as onboarding flows.
[Learn more →](/concepts/workflows)
## Broadcasts
Broadcasts are a way to send one-time, cross-channel notifications to your users through Knock. They use the Knock workflow engine, but are configured in the Knock dashboard to run once.
Broadcasts are useful for one-time notifications such as email announcements or system status updates.
[Learn more →](/concepts/broadcasts)
## Guides
Guides enable you to power in-product messaging using your own components. Unlike workflows which have to be triggered, guides are rendered when eligible users visit relevant pages in your application.
Guides are useful for announcements, paywalls, nudges, banners, and other in-product messaging that doesn't fit into a feed-based notification center.
[Learn more →](/concepts/guides)
## Channels
A channel in Knock represents a configured provider, such as Sendgrid for email, to send notifications to your recipients. Most providers within Knock use credentials that you supply to deliver notifications on your behalf. These credentials and other settings are what make a configured channel.
[Learn more →](/concepts/channels)
## Commits
Knock uses a commit model to version changes that you make to all of your Knock resources. When you make a change to a workflow or a layout in the Knock dashboard, you'll need to commit it to your development environment before those changes will appear in workflows triggered via the API.
[Learn more →](/concepts/commits)
## Environments
Knock uses the concept of environments to ensure logical separation of your data and configuration. This means that users and preferences created in one environment are **never** accessible to another. Environments usually map to the environments you have in your software development life cycle (SDLC).
[Learn more →](/concepts/environments)
## Recipients
A Recipient within Knock is any [User](#users) or [Object](#objects) that may wish to receive notifications.
[Learn more →](/concepts/recipients)
## Users
A user in Knock represents an individual who should receive a message. A user's profile information contains important attributes about the user that will be used in messages (name, email). The user object can contain other key-value pairs that can be used to further personalize your messages.
[Learn more →](/concepts/users)
## Preferences
Preferences enable your users to opt-out of the notifications you send using Knock.
[Learn more →](/concepts/preferences)
## Objects
An object represents a resource in your system that you want to map into Knock. Objects are a powerful and flexible way to ensure Knock always has the most up-to-date information required to send your notifications. They also enable you to send notifications to non-user recipients.
You can use objects to:
- send in-app notifications to non-user resources in your product (the activity feed you see on a Notion page is a good example)
- send out-of-app notifications to non-user recipients (such as a Slack channels)
- reference mutable data in your notification templates (such as when a user edits a comment before a notification is sent)
[Learn more →](/concepts/objects)
## Subscriptions
A subscription represents a relationship between a non-user entity (an Object) and a Recipient (the subscriber). Subscriptions are used to model pub/sub behavior and lists of recipients that Knock will automatically fan out a workflow trigger to on your behalf.
[Learn more →](/concepts/subscriptions)
## Schedules
A schedule allows you to automatically trigger a workflow at a given time for one or more recipients. You can think of a schedule as a managed, recipient-timezone-aware cron job that Knock will run on your behalf.
[Read more →](/concepts/schedules)
## Tenants
Tenants represent segments your users belong to. You might call these "accounts," "organizations," "workspaces," or similar. This is a common pattern in many SaaS applications: users have a single login joined to multiple tenants to represent their membership within each. Within Knock you can model your tenant objects as first-class entities and use them to scope features.
[Learn more →](/concepts/tenants)
## Messages
A message in Knock represents a notification delivered to a recipient on a particular channel. Messages contain information about the request that triggered its delivery, a view of the data sent to the recipient, and a timeline of its lifecycle events.
[Learn more →](/concepts/messages)
## Translations
Translations support localization in Knock. They hold the translated content for a given locale, which you can reference in your message templates with the `t` Liquid function filter.
[Learn more →](/template-editor/translations)
## Conditions
Knock uses conditions to model checks that determine variations in your workflow runs. They provide a powerful way to create more advanced notification logic flows.
[Learn more →](/concepts/conditions)
## Variables
Variables within Knock let you set shared constants or secrets that you can use in all of the workflows and templates under your account. Variables can be overridden at the environment level to set per environment constants.
[Learn more →](/concepts/variables)
## Audiences
Audiences are user segments that you can notify. You can bring audiences into Knock programmatically with our API or a supported reverse-ETL source.
[Learn more →](/concepts/audiences)
## Workflows
Learn more about what a workflow in Knock is, and how to think about grouping together your cross-channel notifications into different workflows.
---
title: Workflows
description: Learn more about what a workflow in Knock is, and how to think about grouping together your cross-channel notifications into different workflows.
tags: ["categories", "archive", "archived"]
section: Concepts
---
Workflows are triggered journeys that send notifications to your recipients.
Workflows are represented as a set of steps, which are either function or channel steps. Functions apply logic to your workflow run, like batching and branching. Channel steps produce notifications that are delivered via your [configured channels](/concepts/channels).
Workflows in Knock:
- Have a unique `key`
- Execute for a single recipient at a time
- Contain all of the logic and templates for the notifications you send
- Evaluate recipient [preferences](/preferences/overview) automatically
- Are triggered via API calls, events, audience events, or recipient schedules
if you're looking to send a one-time message to a set of recipients, you
should use a broadcast instead.
}
/>
You can read more about how to build your workflows and the features available within the workflow builder under the [designing workflows section of the documentation](/designing-workflows).
## Workflows and notification templates
Each workflow you build will contain one or more [channel steps](/designing-workflows/channel-step). It's these channel steps that contain the templates that will be rendered to produce a notification sent to the recipient of the workflow run.
The templates associated with a channel step **only** exist in the context of that channel step. That means that templates cannot currently be shared across workflows, or even across other channel steps within the same workflow.
## Managing workflows
Knock workflows can be managed either via the Knock dashboard or programmatically via the [Management API](/mapi-reference). The [Knock CLI](/cli/overview) offers a convenient way to work with the management API locally to make updates to workflows and their templates.
### Workflow categories
Each workflow can have one or more categories associated with it. Categories are useful for grouping related types of workflows together and offer a way to apply a user's preferences across many workflows.
To set a `category` for a given workflow, go to that workflow's page in the dashboard, click the "..." menu, and select "Manage workflow." From there, you'll be able to add categories.
Workflow categories are case sensitive and may contain
special characters and spaces.
}
/>
### Version control for workflows
All changes to workflows, including changes made to the templates inside of a workflow, are version controlled. Versions are stored in commits. You can create workflows directly in production, or, for production-critical use cases, create them in development and promote them to production when you're ready to go live.
Read more about [environments](/version-control/environments) and [versioning](/version-control/commits) in Knock.
### Workflow status
Each workflow has an `Active`/`Inactive` status that is displayed in your dashboard's **Workflows** section. The status defaults to `Active` and can be set by clicking on the workflow and using the **Status** selector in the **Details** section of the **Overview** tab.
This is your kill switch for a given workflow should you need it; any attempt to trigger an `Inactive` workflow will result in a `workflow_inactive` [error](/api-reference/overview/errors) and no workflow runs will be enqueued.
The status setting operates independently from the commit model so that you can immediately enable or disable a workflow in any environment without needing to go through environment promotion. **It is environment-specific and will only be applied to the current environment.**
See the [frequently asked questions](#frequently-asked-questions) section below for more information on how in-progress workflow runs are affected when you set a workflow's status to `Inactive`.
### Archiving workflows
Archiving a workflow allows you to permanently remove a workflow from Knock. When you archive a workflow it will be removed from **all environments** and cannot be called via API. Once a workflow is archived, it **cannot be undone**. If you have delayed runs for a workflow that is archived, when the workflow run resumes after the delay it will immediately terminate.
## Running workflows
Workflows defined in Knock are executed via trigger, which starts a workflow run for the recipients specified using the `data` passed to the workflow trigger.
it's important to know that in Knock a workflow run is{" "}
always executed against a single recipient. Workflows can
always be invoked for multiple recipients, but each run will only
be for a single recipient.
}
/>
### Triggering a workflow
In Knock, workflows can be triggered in three different ways:
- **API call**: workflows can be [triggered directly via an API call](/send-notifications/triggering-workflows) to our workflow trigger endpoint. This is the most common form of integration and means that Knock is integrated into your backend codebase, usually alongside your application logic.
- **Events**: using different [event sources](/integrations/sources/overview/), you can connect Knock to CDPs such as Segment and RudderStack and map the events those systems produce to workflows that should be triggered.
- **Schedules**: [workflows can be scheduled](/concepts/schedules) to be run for one or more recipients, in a recipient's local timezone on a one-off, or recurring basis.
### Canceling a workflow run
Any triggered workflow that has an active delay or batch step can also be canceled to halt the execution of that workflow run. Workflow cancellations today must happen through the cancellation API and can only occur when a `cancellation_key` has been specified on the workflow trigger.
[Read more about canceling workflows](/send-notifications/canceling-workflows)
### Workflow runs and recipients
When a workflow is triggered via the API we return a `workflow_run_id` via the API response. This ID represents the workflow run for all of the recipients that the workflow was triggered against.
For each recipient included in the workflow trigger or that the workflow should fan out to [via subscriptions](/concepts/subscriptions), a new workflow run is enqueued. We call this the recipient workflow run.
Recipient runs are visible within the Knock dashboard by going to **Observability** > **Logs**. Each run can be inspected to view its current state as well as the steps executed for the workflow. It's also possible from a workflow run log to see the messages (notifications) produced by the run.
### Workflow run scope
When a workflow run is executed, associated state is loaded to be used within the templates and conditions defined in the workflow. This state is known as the workflow run scope. The run scope can be modified during the duration of the workflow run by fetching additional data via the [fetch function](/designing-workflows/fetch-function).
[Read more about the properties available](/template-editor/variables)
## Automate workflow management with the Knock CLI
In addition to working with workflows in the Knock dashboard, you can programmatically create and update workflows using the [Knock CLI](/developer-tools/knock-cli) or our [Management API](/developer-tools/management-api).
If you manage your own workflow files within your application, you can automate the creation and management of Knock workflows so that they always reflect the state of the workflow files you keep in your application code.
The Knock CLI can also be used to commit changes and promote them to production, which means you can automate Knock workflow management as [part of your CI/CD workflow](/tutorials/integrating-into-cicd).
See the [Workflow file structure](/cli/workflow/file-structure) section in the CLI reference for details on how workflow files are organized when working with the CLI.
You can learn more about automating workflow management in the [Knock CLI reference](/cli/overview). Feel free to contact us if you have questions.
## Frequently asked questions
No, there's no limit to the number of workflows you can have within your
Knock environment.
It's highly recommended to build individual workflows for each use case. While it might be tempting to build a single workflow with conditional logic for all of your notification use cases that can be triggered from anywhere within your application with the same workflow `key`, modularizing your workflows by use case allows you to offer the highest level of configurability to your users via [Preferences](/concepts/preferences). Our customers also find that concise, use-case specific workflows are easier to maintain and iterate on.
As an example, if we're building a document collaboration app where users can comment on specific documents, we might group all of the logic about the cross-channel comment notifications we have into a single `new-comment` workflow.
While it's possible to create per-customer workflows using the management
API, we recommend avoiding doing this in favor of using [per-tenant
branding](/multi-tenancy/per-tenant-branding) and
[preferences](/concepts/preferences) to control individual workflows.
Yes, you can set a workflow's [status](/concepts/workflows#workflow-status)
to `Inactive` to disable it. While a workflow's status is set to `Inactive`,
any new workflow triggers will be rejected with a `workflow_inactive` error.
If a workflow step attempts to process for a workflow that is currently set to `Inactive`, the workflow run will be immediately terminated.
Workflow runs that are currently in a paused state (due to a [delay](/designing-workflows/delay-function) or [batch](/designing-workflows/batch-function) step) when you set your workflow to `Inactive` are not immediately affected; however, if the paused step completes and the workflow run progresses to the next step while the workflow remains `Inactive`, it will be terminated.
If you set a workflow to `Inactive` and back to `Active` while a given in-progress workflow run remains paused, that workflow run will resume at the end of the delay and continue to completion.
## Broadcasts
Power one-time, cross-channel messaging to your users through Knock.
---
title: Broadcasts
description: Power one-time, cross-channel messaging to your users through Knock.
tags:
[
"segmentation",
"user segmentation",
"lifecycle",
"marketing",
"audience",
"groups",
"segments",
"one-time",
"one-off",
"cross-channel",
"broadcast",
"broadcasts",
]
section: Concepts
---
Broadcasts are a way to power one-time, cross-channel messaging to your users through Knock. They are built on Knock's [workflow engine](/concepts/workflows), giving you the power to create intelligent messaging across all of the [channels you've configured in Knock](/concepts/channels).
## Broadcasts and the environment model
Unlike workflows and other resources in Knock, broadcasts do not have to be committed or promoted to an environment before they can be used. In fact, unlike workflows, broadcasts are **environment-specific** and can be created in any environment (including production).
If you wish to mirror a flow where you create a broadcast in development, and then use it in production you can do so by [cloning the broadcast](/version-control/environments#clone-resources-across-environments) to the production environment.
## Targeting users for a broadcast
Broadcasts can be targeted to a specific set of users [via an audience](/concepts/audiences), sent to all users in an environment, or sent to a specific set of users by uploading a CSV.
Your users **must** exist within Knock in order to send them a broadcast. If you're looking to send a broadcast to users who don't yet exist within Knock, you can use a CSV to upload a list of users who will first be identified before the broadcast is sent. Knock will upsert the users as they are added to the broadcast and skip any users with malformed or missing IDs. You can also create a new audience on the fly when uploading a CSV of users to a broadcast.
You can also include a tenant ID associated with each user when uploading a CSV of users to a broadcast. Each user-tenant pair will be treated as a distinct recipient for the purposes of the broadcast. See [using audiences with tenants](/concepts/audiences#using-audiences-with-tenants) for more details.
**Note**: Uploading the same user multiple times with a different tenant ID will always persist the last user properties uploaded in the list onto the user. If you want to use data specific to a tenant, you can categorize your fields as "broadcast data" so that it will be available for that particular user-tenant pair.
## Creating and managing broadcast content
To manage the contents of a broadcast, click the "Edit steps" button in the broadcast overview. This will open the broadcast builder, where you can add steps that will be executed for each user the broadcast is sent to.
In the broadcast builder, you can add:
- [Delay functions](/designing-workflows/delay-function): to pause the execution of a broadcast for a specific amount of time.
- [Wait for event functions](/designing-workflows/wait-for-event-function): to pause the execution of a broadcast until a matching event is received or until a wait time expires.
- [Branch functions](/designing-workflows/branch-function): to conditionally execute steps based on the value of a variable.
- [Experiment functions](/designing-workflows/experiment-function): to randomly assign recipients to percentage-based cohorts for A/B testing and experimentation.
- [Channel steps](/designing-workflows/channel-step): to send a message to a user on a specific channel.
- [In-app guide step](/designing-workflows/in-app-guide-step): to make a user eligible for an [in-app guide](/concepts/guides).
When adding a channel step, you can select from any of the channel types you've configured in Knock to send a message to a user on that channel. Once you've added a channel step, you can design and manage the template for the step by selecting the channel step and clicking the "Edit template" button.
### Working with the template editor
The broadcast template editor is the same template editor you've come to know and love from [workflows](/concepts/workflows). You can read more about working in the template editor [here](/template-editor/overview).
### Broadcast state
Knock will automatically expose the following variables to the broadcast builder and template editor which you can use to personalize and control the broadcast:
- `recipient`: the user that the broadcast is being sent to.
- `vars`: the environment variables available to the broadcast.
- `tenant`: in the event that your broadcast has been triggered to a user-tenant audience member, this will be the full tenant object linked.
You can access the broadcast state in the broadcast builder by toggling the state pane. All of these variables are also available [in the template editor](/template-editor/variables).
### Per-recipient data
When you upload a CSV of users to a broadcast, you can map any columns of your CSV to either the "User" or "Broadcast" schema. When you map them to the user, these properties will be persisted to the user object in Knock. When you map them to the broadcast, these properties will be available in the template editor for this broadcast only and cannot be reused in other broadcasts. You can access these properties in the template editor by using the `data` variable as you would with workflow data.
Due to the nature of the CSV format, all data values (user or broadcast)
that are upserted via CSV as part of a broadcast will be treated as
strings. You'll need to account for this when using your data in your
templates or conditions.
}
/>
## Scheduling broadcasts
Broadcasts can optionally be scheduled to send at a specific time. When a broadcast is scheduled, you will see the status of the broadcast reflected as scheduled on the date and time you specified. Scheduled broadcasts can be canceled before they are sent, should you wish to make any changes.
## Broadcast analytics
Broadcasts produce messages, exactly as workflows do. As such, messages sent as part of a broadcast will be visible in the **Analytics** page within the Knock dashboard. Additionally, broadcast engagement metrics are available in any [connected data warehouses](/integrations/extensions/data-sync).
Sent broadcasts include a recipient summary that highlights key delivery and engagement metrics, including:
- **Sent**: The number of messages that were successfully sent to the delivery provider.
- **Delivered**: The number of messages that were successfully delivered, as reported by the delivery provider. This may vary based on the configured channel. Learn more about the [delivered status](/send-notifications/message-statuses#7-delivered).
- **Bounced**: The number of messages that were dropped by the delivery provider due to bad recipient data.
- **Read**: The number of messages that were opened and read by the recipient at least once.
- **Interacted**: The number of messages that were interacted with (e.g. the recipient clicked a link).
To learn more, see our [message status documentation](/send-notifications/message-statuses).
## Testing broadcasts
You can test a broadcast by clicking the "Run test" button in the broadcast overview or on the broadcast builder. This will allow you to select a specific test user to send the broadcast to. When you've run a test, you'll see the run log for the broadcast in the "Runs" tab. You'll also see any messages generated as part of the test run in the "Messages" tab.
## Debugging and observing broadcasts
Broadcasts are processed in the same way as workflows, and as such, you can use the same tools to debug and observe broadcasts as you can workflows.
- **Messages** generated from a broadcast are available under the "Messages" logs, which you can find in the main sidebar on the dashboard, under a user's profile, or within a specific broadcast.
- **Runs** generated from executing broadcasts are available under the "Runs" tab, under a user's profile, or within a specific broadcast.
Additionally, developer tools and extensions are available for broadcasts as they are workflows.
- [Outbound webhooks](/developer-tools/outbound-webhooks/overview): all messages produced by a broadcast will emit outbound webhook events.
- [Observability extensions](/integrations/extensions/overview): all processing metrics produced by a broadcast will be sent to the observability tools you have configured (Datadog and New Relic).
- [CDP and analytics extensions](/integrations/extensions/overview): all message events produced by a broadcast will be sent to the CDP and analytics tools you have configured (Segment and Heap).
- [Data warehouse sync](/integrations/extensions/data-sync): all messages produced by a broadcast will be visible within your Knock `messages` table.
## Broadcasts and user preferences
Broadcasts respect all [user preferences](/concepts/preferences) that are configured in Knock. That means for any categories added to a broadcast, preferences linked to those categories will be respected. Additionally, any channel type preferences set for a user will be respected during the execution of a broadcast.
Knock also supports [commercial unsubscribe](/preferences/commercial-unsubscribe) preferences that will automatically add a 1-click unsubscribe header and link to your email messages, to respect CAN-SPAM compliance.
## Frequently asked questions
`owner`, `admin`, and `member`
[roles](/manage-your-account/roles-and-permissions) can create and send
broadcasts to users.
No, broadcasts are not callable via the API.
No, currently broadcasts cannot be managed via the Knock CLI.
No, currently broadcasts can only be sent to a set of users, not objects. If
you have an object sending use case, we'd [love to hear from
you](mailto:support@knock.app?subject=Broadcast%20to%20objects).
Your users must be identified as users in Knock before you can send them a
broadcast. When you upload a CSV of users to a broadcast, Knock will
automatically identify the users.
The maximum size of a CSV upload is capped at 10MB.
## Guides
Power in-product messaging such as announcements, paywalls, and banners using your own components.
---
title: Guides
description: Power in-product messaging such as announcements, paywalls, and banners using your own components.
tags: []
section: Concepts
---
## An overview
Guides enable you to power in-product messaging, everything from paywalls and badges, to one-time announcements and banners, using your own components. Your engineering team controls the UI via a new API, while your content team manages content, targeting, and activation rules in the Knock dashboard.
Guides are reactive and data-driven. At runtime, you can pass data from your app into a guide to influence both its content and targeting. For example, you might show a guide only when `currentProject.assetCount` exceeds 25. The API evaluates the current user and returns any eligible guides, enabling personalized, real-time experiences for your users.
## Guides analytics
Guides include an analytics summary that highlights key metrics over the last N days, based on your account's [retention period](/manage-your-account/data-retention). These metrics include:
- **Audience**: The total number of users in the target audience.
- **Seen**: The number of users who saw this guide.
- **Interacted**: The number of users who interacted with this guide.
- **Archived**: The number of users who archived this guide.
To learn more, see our [message status documentation](/send-notifications/message-statuses).
## Guides pricing
Guides usage is priced using **engaged users**, which is the distinct number of users who have **seen** or **engaged** with a guide in the billing period.
Messages produced by guides are **not** counted towards your message sent usage.
You can learn more about guide engagement in our [guide engagement documentation](/in-app-ui/guides/handling-engagement).
If you're an enterprise customer, and you don't have guides included in
your current agreement, you'll have the same guides usage limits as our
starter plan. You can use guides up to the limit, at which point we ask
that you contact us to increase your limit.
}
/>
## Learn more
To learn more about Knock guides and how you can use them to power activate, engage, and retain users, go to our [Guides overview](/in-app-ui/guides/overview).
## Channels
Learn about what a channel is in Knock and how you can use channels to power your cross-channel notification delivery.
---
title: Channels
description: Learn about what a channel is in Knock and how you can use channels to power your cross-channel notification delivery.
tags: []
section: Concepts
---
A channel in Knock represents a configured provider to send notifications to your recipients. Most providers within Knock use credentials that you supply to deliver notifications on your behalf. These credentials and other settings are what make a configured channel.
Within Knock, we split channels into different types, where each type has at least one provider associated that can be configured:
- [Email](/integrations/email/overview) (such as Sendgrid, Postmark)
- [In-app](/integrations/in-app/overview) (such as feeds and toasts)
- [In-app guide](/in-app-ui/guides/overview) (such as banners, modals, and other in-product messaging)
- [Push](/integrations/push/overview) (such as APNs, FCM)
- [SMS](/integrations/sms/overview) (such as Twilio, Telnyx)
- [Chat](/integrations/chat/overview) (such as Slack, Microsoft Teams, and Discord)
- [Webhook](/integrations/webhook/overview) (send webhooks to custom channels or enable your own customers to configure webhooks in your product)
You can read more about the various types of [channel integrations available here](/integrations/overview).
## Managing channels
You can create and manage channels within Knock from the dashboard by navigating to **Channels and sources** under your account settings. A created channel exists across all environments in your Knock account and uses the same ID for each environment.
**Please note**: only admins and owners on an account can manage channels.
## Channel settings
For each channel you create in the Knock dashboard, you will need to configure the channel per environment for it to be valid. Each provider requires different configuration data, and you can see the required settings in the [integrations overview](/integrations/overview).
Given that channel configuration is **per-environment** this makes it possible to have separate settings for your testing/sandbox environments vs your production environments. Channel settings can easily be cloned across environments when needed.
unlike other types of configuration in Knock, channel settings are never
versioned, meaning when they are saved the configuration is synchronized
to the Knock configuration store to immediately take effect.
}
/>
## Channel visibility
Channel visibility controls where a channel appears as a step in the dashboard when you build [workflows](/concepts/workflows) and [broadcasts](/concepts/broadcasts). Use it to keep your step panel focused on the channels that are relevant to each surface.
You can set a channel's visibility in two places:
- When you create a channel, in the **Create channel** modal.
- When you edit an existing channel, from **Channels and sources** under your account settings.
Each channel has two independent visibility settings:
| Setting | Description |
| ---------- | ---------------------------------------------------- |
| Workflows | Show the channel as a step in the workflow builder. |
| Broadcasts | Show the channel as a step in the broadcast builder. |
When a channel is visible, it appears as a draggable step card in the step panel. When it's hidden, it no longer appears in the panel, but you can still add it to the canvas by dragging in a step of that channel type and selecting the channel from the dropdown. Hiding a channel only changes what shows up in the builder; it doesn't disable the channel or stop existing steps from sending.
As with other channel management, only admins and owners can update channel visibility.
## Using channels to send messages
In Knock, all messages are sent via a channel step configured within a workflow or broadcast. Messages to be delivered will be forwarded to the channel using the settings that you provide in the channel configuration, which handles the communication to the underlying provider and the retry logic if a message delivery should fail.
For most providers, you can inspect the delivery logs produced when trying to send a message from under the **Messages** > **Logs** page from within the Knock dashboard.
## Setting additional, per-recipient data for a channel
Some providers may require additional, per-recipient data to send notifications. A good example of this is a push provider like [APNs](/integrations/push/apns), which requires a unique, device-specific token to know how to route a push notification to the recipient.
In Knock, we refer to this concept as "Channel Data" as it represents the data that exists for a recipient on a particular channel.
You can read more about [setting channel data here](/managing-recipients/setting-channel-data). You can also see channel data requirements in the documentation for each provider.
## Frequently asked questions
There's no restriction on how many different channels you can have,
including multiple channels for the same provider.
## Recipients
A Recipient in Knock represents a person or a non-user entity that receives notifications.
---
title: Recipients
description: A Recipient in Knock represents a person or a non-user entity that receives notifications.
tags:
[
"RecipientIdentifier",
"recipient",
"user",
"timezone",
"time zone",
"locale",
]
section: Concepts
---
A Recipient within Knock is any [User](/concepts/users) or [Object](/concepts/objects) that may wish to receive notifications. Knock persists information about recipients to send those recipients notifications and give a single source of truth for the notifications sent for debugging and logging purposes.
Recipients have:
- **Identifiers.** A string from your system that uniquely represents the recipient.
- **Properties.** Structured and unstructured data for the recipient, including but not limited to the name, email, and phone number.
- **Preferences.** The rules under which the recipient should or should not receive notifications.
- **Channel data.** Channel data send a recipient a notification on a particular channel, such as tokens for sending push notifications to a given channel or access tokens to send notifications to a chat channel like Slack.
## `RecipientIdentifier` definition
A recipient identifier can be one of:
- A string user ID for a previously identified user (`user-1`)
- An object reference dictionary (`{ "collection": "my-collection", "id": "object-1" }`) for a previously identified object
- A dictionary containing a recipient to be [identified inline](/managing-recipients/identifying-recipients#inline-identification)
This can be expressed as the following type:
```typescript
type RecipientIdentifier =
| string
| { collection: string; id: string }
| Record;
```
## Identifying recipients
For Knock to be able to send notifications to your recipients, you must first identify those recipients to synchronize them with Knock. We call this process "identification", and it can be done ahead of time, or lazily via inline-identification in your workflow triggers. Identifying sets the properties associated with your recipients into Knock, so that you can reference those properties in the notifications you send out.
[Read more about identifying your recipients ->](/managing-recipients/identifying-recipients)
## Custom properties
Recipients in Knock can have any number of custom properties set on them, which you set during the identification process. Some properties, like `email` or `phone_number` are required for notifications to be delivered to the recipient.
## Managing lists of recipients
You can use our [Subscriptions](/concepts/subscriptions) feature to create a Knock-managed list of recipients that should be notified. Subscriptions are useful for modeling pub/sub behavior.
## Recipient timezones
A recipient can have an optional `timezone` property, which should be a valid tz database time zone string, like `America/New_York` or `Europe/London`. By default, if no recipient timezone is set `Etc/UTC` will be used however a [default timezone](/manage-your-account/account-timezone) can be specified at the account level under "Settings" which will override this default for all recipients.
## Frequently asked questions
No, there's no limit on the number of recipients you can have within Knock.
We support non-user entities (Objects) receiving notifications in Knock
because some notifications are delivered to non-user entities. For example,
a Slack notification that sends to a channel. That notification is not
delivered to a user but to an entity that connects Slack and your system
(such as a Project or a Team).
Currently, there's no limit to the size of the properties you can add to a
recipient. We reserve the right to impose a limit here in the future,
however.
## Users
Learn more about Users in Knock and see code examples to get started.
---
title: Users
description: Learn more about Users in Knock and see code examples to get started.
tags: ["recipients", "identify", "actor"]
section: Concepts
---
A [User](/api-reference/users) represents a person who may need to be notified of some action occurring in your product. A user is a type of recipient within Knock and is the most common type of entity that you may wish to send a notification to.
## Sending user data to Knock
User data must be synchronized to Knock to send the user a notification or to reference that user in a notification. We refer to this process as identifying users.
[Read more about identifying users ->](/managing-recipients/identifying-recipients).
## Guidelines for use
### User identifiers
The identifier for a user is important as it's the unique key that we will use to merge users and determine recipients for a notification. Generally, the best practice here is to use your internal identifier for your users as the `id`.
The maximum number of characters for the identifier is 256, and it cannot
contain a "/" or "#". You cannot change{" "}
a user's id once it has been set, so we recommend that you use a
non-transient `id` like a primary key rather than a phone number or email
address.
}
/>
### Required attributes
The following attributes are required for each user you identify with Knock.
| Property | Description |
| -------- | -------------------------------------------------------------- |
| id | An identifier for this user from your system, should be unique |
### Optional attributes
The following attributes are optional, depending on the channel types you decide to use with Knock.
| Property | Description |
| ------------ | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| email | The primary email address for the user (required for email channels) |
| name | The full name of the user |
| avatar | A URL for the avatar of the user |
| phone_number | The E.164 phone number of the user (required for SMS channels) |
| timezone | A valid tz database time zone string (optional for [recurring schedules](/concepts/schedules#scheduling-workflows-with-recurring-schedules-for-recipients) or [send windows](/designing-workflows/send-windows)) |
### Storing user properties
In addition to the system attributes defined on the user schema above, Knock will keep track of any `properties` (key/value pairs) that you send to us. These _traits_ are always merged onto a user and returned to you.
Traits are useful for when you need to perform additional personalization on a user, like denormalizing the current plan they're on so you can use this to determine the portion of a notification they should receive.
You can nest the properties you send as deeply as needed, and Knock will perform a deep merge with these properties on each subsequent upsert. Note that this means that existing properties cannot be explicitly removed, but you can overwrite them with a `null` value.
### The user object
Once sent to Knock, the user object returned to you in the Knock payload looks like this:
```json title="User object"
{
"id": "user_1234567890",
"name": "Dummy User",
"email": "dummy@example.com",
"updated_at": "2021-03-07T12:00:00.000Z",
"created_at": null,
"__typename": "User"
}
```
| Property | Description |
| ------------ | ------------------------------------------------------------------ |
| id | The unique user identifier |
| properties\* | Traits sent for the user are merged back onto the main user object |
| created_at | The created at time (provided by you) |
| updated_at | The last time we updated the user |
\* All properties appear at the top level of the user object.
## Retrieving users
Users can be retrieved from Knock to see the current state of their properties using the `users.get` method.
## Deleting users
Users can be deleted from Knock via the `users.delete` method. Deleting a user from Knock will have the following effect:
- The user will no longer be able to be a recipient or an actor in a workflow
- The user will no longer appear in the dashboard under the "Users" list
- Any in-app messages that reference the user will be replaced by a "missing user" marker
## Frequently asked questions
Commonly you'll want to send notifications to entities in your system that are not currently registered users in your product (think guests or invited users). In these situations, we recommend:
1. Identifying the user with a unique identifier, such as their email address, or with a prefix (`guest_`) to denote the different type.
2. Where possible, if the notified user becomes a registered user in your system then using our [merge API](#merging-users) to merge the guest user and the registered user to preserve message sending history.
It might feel counterintuitive to store registered users and non-registered users under a single collection in your Knock environment, but Knock should always be viewed as a _cache_ of information about users and entities that may need to be notified in your system.
Yes, they are. Each environment has a separate, isolated set of users. If you need to share users across environments, you must re-identify them in each environment.
If you want to store and notify different types of users within your Knock environment, we recommend prefixing the id with the type. So if you had two distinct user types, `owners` and `customers` you can pass Knock ids like `customer_123` and `owner_456`.
If you need to send a notification to an entity in your system you should have a look at modeling those as [Objects](/concepts/objects). Objects can represent **any non-user entity**.
When you add new team members in the Knock dashboard, we automatically add them as "Users" within your Knock Development environment so you can send them notifications. We do this to help you with testing.
No, all users who are sent a notification are identified in your Knock environment and are persisted. If you have a use case here that you wish to discuss with us please [get in touch](mailto:support@knock.app).
If you need to edit or update a user's attributes in Knock, you can either use the [identify a user endpoint](/api-reference/users/update) or [inline identification](/managing-recipients/identifying-recipients#inline-identification) when triggering a workflow.
## Preferences
Learn how the notification preference system works in Knock.
---
title: "Preferences"
description: "Learn how the notification preference system works in Knock."
tags:
[
"recipients",
"conditions",
"prefs",
"preferences",
"users",
"user preferences",
]
section: Concepts
---
[Preferences](/api-reference/recipients/preferences) enable your users to opt-out of the notifications you send using Knock.
## How preferences work
A user has a `PreferenceSet`. A `PreferenceSet` is a JSON object that tells Knock which channels, categories, and/or workflows a user has opted out of receiving.
When Knock runs a workflow for a user, we evaluate their `PreferenceSet`. A message will not send if the user has opted out of receiving it.
With Knock preferences you can power standard preference use cases, such as the topic-channel preferences grid picture below, as well as advanced use cases such as per-workflow preferences, send time preferences, and more.
To learn more about how preferences work, how to choose between a hosted or custom preference center, and advanced concepts like per-tenant preferences, object preferences, and preference conditions, go to our [preferences overview](/preferences/overview). To launch a no-code preference center, see the [hosted preference center](/preferences/hosted-preference-center).
## Objects
Learn the basics of Objects in Knock.
---
title: Objects
description: Learn the basics of Objects in Knock.
tags: ["recipients", "identify"]
section: Concepts
---
An [Object](/api-reference/objects) represents a resource in your system that you want to map into Knock.
This page covers an overview of objects and how to use them. We'll walk through two common use cases for objects: Slack channel notifications and handling mutable data on long-running notifications (such as digests).
**Note:** Objects are an advanced feature within Knock. You can send multi-channel notifications across all channel types (except Slack) without touching the Objects API. If you're just getting started, we'd recommend coming back to objects when you've already started to leverage a few channels using Knock.
## An overview of objects
Objects are a powerful and flexible way to ensure Knock always has the most up-to-date information required to send your notifications. They also enable you to send notifications to non-user recipients.
You can use objects to:
- Send out-of-app notifications to non-user recipients (such as a [Slack channel](#slack-channel-notifications)).
- [Reference mutable data in your notification templates](/template-editor/referencing-data) (such as when a user edits a comment before a notification is sent).
We have Objects API support for in-app feed notifications on our roadmap.
If you have a use case for this functionality, please send a note
to support@knock.app or use the
feedback button at the top of this page to let us know.
}
/>
## Sending object data to Knock
All objects belong to a `collection`, which groups objects of the same type together. An object should be unique within a collection, identified by the `id` given. We use the `{collection, id}` pair to know when to create or update an object.
Objects follow the same rules as all other items in Knock in that they are unique and logically separated per Knock environment.
The way you manage object data in Knock is largely the same as [how you manage your user data](/concepts/users#sending-user-data-to-knock). As with users, we support three approaches for managing Knock objects: individual, bulk, and inline.
You can use the set object API to send us data for a single object.
[API reference →](/api-reference/objects/set)
You can use the bulk set objects API to send us data for many objects at once. This endpoint allows you to identify up to 1000 objects at a time.
[API reference →](/api-reference/objects/bulk/set)
You can also integrate object management into your workflow trigger calls. If you include additional object metadata (other than `id` and `collection`) in a workflow trigger call, Knock will perform an asynchronous action to upsert these objects as part of processing the workflow.
[API reference →](/api-reference/workflows/trigger)
## Guidelines for use
### Collection naming
Use plural collection names when possible. The collection name should describe the group of one or many objects within the collection. Good examples of collection names are `projects`, `teams`, `accounts`.
### The object identifier
The object `id` should be unique within the collection. It should also be a stable identifier, likely the primary key of the object in your system so it can be easily referenced later. Please note: object ids **cannot be changed once set**.
### Properties
Objects can contain any number of key-value property pairs that you can then reference in templates and trigger conditions. Properties will always be deeply merged between upserts, meaning that existing properties (including nested properties) will be updated with the newly provided values. Note that this means that existing properties cannot be explicitly removed, but you can overwrite them with a `null` value.
## Object subscribers
You can use [subscriptions](/concepts/subscriptions) to subscribe [recipients](/concepts/recipients) to objects as subscribers. When an object is passed to a workflow trigger, Knock will automatically fan out and run a workflow for every subscriber on that object. The object itself will also receive a workflow run, which is useful for sending notifications to shared resources like a Slack channel or a webhook endpoint.
One of the most powerful things about object subscriptions is that they
can contain other objects.
As an example, a workspace object may have a list of
projects
as subscribers, each of which has a list of
project follower
subscribers.
When you trigger a workflow with that workspace as a
recipient, Knock will fan out through the hierarchical relationship you've
created and notify all projects and{" "}
project followers under that workspace.
}
/>
## Object workflow runs
Knock accepts objects as recipients, so an object passed to a workflow trigger gets its own workflow run by default. This is useful when notifying shared resources such as [Slack channels](/integrations/chat/slack/overview#choosing-where-to-store-channel-data-users-vs-objects) or [customer-facing webhooks](/tutorials/customer-webhooks).
In the object's workflow run, Knock executes every applicable step. This may lead to unintended outcomes like object-driven fetch requests. To conditionally execute steps based on recipient type, use a [step condition](/designing-workflows/step-conditions) to evaluate the [recipient's](/template-editor/variables#recipient-user-or-object) `__typename` or `collection`.
## Referencing object data
You can reference object data in templates using the `object` filter to load object data into a template. You can reference an object by a static identifier, or by a dynamic identifier passed in via data in your workflow trigger.
For example, if we have a `projects` collection that contains an object under the identifier `proj_1`, we can load that object into a template via a static identifier like this:
```liquid title="Referencing an object by a static identifier"
{% assign project = "proj_1" | object: "projects" %}
```
Or, we can load an object by a dynamic identifier. For example, if we have a workflow trigger that contains a `project_id` property, we can load that object into a template like this:
```liquid title="Referencing an object by a dynamic identifier"
{% assign project = data.project_id | object: "projects" %}
```
Once an object is loaded into a template, you can reference any of the properties of that object using the dot notation.
You can read more about referencing data in templates in our [documentation on referencing data in templates](/template-editor/referencing-data).
## Examples
### Slack channel notifications
A common notification use case we see in SaaS applications is the ability for users to connect an object in the product they're using to a channel in their own Slack workspace. That way when something happens in that object (e.g. a comment is left) they receive a notification about it in their connected Slack channel.
Let's take a fictional example here where we have an audio collaboration service that allows its customers to connect a Project object to a Slack channel. Once the Project and Slack channel are connected, all Comments left within the Project will result in notifications sent to the customer's Slack channel.
Here's how we'd use Knock objects to solve this.
1. **Register our Project object to Knock**
Typically whenever the project is created or updated we'll want to send it through to Knock.
2. **Store the Slack connection information for the Project**
Once our customer chooses to connect their Slack channel to the Project, we have a callback that then adds the Slack information as Channel Data.
3. **Add Slack as a step to our workflow**
Inside of the Knock dashboard, we're going to add a new Slack step to our `new-comment` workflow that will send a notification displaying the comment that was left in our product.
4. **Send the Project as a recipient in your workflow trigger**
Now when we trigger our `new-comment` workflow, we also want to add our Project object as a recipient so that the newly added Slack step will be triggered.
Knock then executes the workflow for this Project object as it would for any user recipients sent in the workflow trigger, skipping over any steps that aren't relevant. (In this case, the Project object only has one piece of channel data mapped to it—the Slack channel—so it won't trigger notifications for any other channel steps in our `new-comment` workflow.) When the Slack step is reached, the connection information we stored earlier will be used as a means to know which channel to send a message to and how to authenticate to that channel.
## Subscriptions
Learn how to use subscriptions to notify a list of recipients associated with an object in your data model.
---
title: Subscriptions
description: Learn how to use subscriptions to notify a list of recipients associated with an object in your data model.
tags:
["subscriptions", "publish subscribe", "pub/sub", "lists", "alerts", "topics"]
section: Concepts
---
Subscriptions are an extension to [Objects](/concepts/objects) and express the relationship between a [Recipient](/concepts/recipients) (the subscriber) and an Object.
You can use subscriptions for:
- Creating notifications for a large number of recipients (e.g. all users of your product)
- Alerting use cases, where users can opt into and out of an alert
- Publish/subscribe models where you want to fan out to a set of users subscribed to a topic
Any Object within Knock can be subscribed to by one or more recipients, and the entire set of subscribers can be notified by triggering a workflow for the object, without you needing to keep the relationship data within your system of who is subscribed to what.
## How subscriptions work
1. Identify an object in a collection that represents the topic, or entity you wish to subscribe recipients to
2. Subscribe one or more recipients to the object by creating a subscription between the recipient and the object
3. Trigger a workflow for the object
On step #3, Knock will handle the fan-out of the workflow trigger **to the object itself and to all subscribed recipients**, automatically enqueuing a workflow run for each on your behalf.
## Integrating subscriptions
Note: for all of the examples below you will need to have an [object identified within Knock](/concepts/objects#sending-object-data-to-knock). In our examples below, we create an object under a `project_alerts` collection with an id `project-1`.
[Go to API documentation →](/api-reference/objects/add_subscriptions)
### Subscribing recipients to an object
Subscribing a recipient to an object creates an `ObjectSubscription` entity describing the relationship between the `Recipient` and the `Object`.
You can subscribe up to 100 recipients to an object at a time by passing one or more `RecipientIdentifiers`. There is no limit to the number of recipients you can subscribe to an object.
```javascript title="Subscribing multiple recipients to an object"
await knock.objects.addSubscriptions("project_alerts", "project-1", {
recipients: ["esattler", "dnedry"],
properties: {
// Optionally set other properties on the subscription for each recipient
},
});
```
Similar to workflow triggers, you can inline identify recipients while subscribing them to an object.
```javascript title="Identifying users while subscribing them to an object"
await knock.objects.addSubscriptions("project_alerts", "project-1", {
recipients: [
{
id: "esattler",
name: "Ellie Sattler",
email: "esattler@ingen.net",
},
{
id: "dnedry",
name: "Dennis Nedry",
email: "dnedry@ingen.net",
},
],
properties: {
// Optionally set other properties on the subscription for each recipient
},
});
```
### Unsubscribing recipients from an object
To remove one or more recipients (up to 100) from an object, you can pass a list of recipient identifiers.
```javascript title="Delete subscriptions for provided recipients"
await knock.objects.deleteSubscriptions("project_alerts", "project-1", {
recipients: ["esattler", "dnedry"],
});
```
### Triggering a workflow for object subscribers
By default when you trigger a workflow for an object that has subscriptions attached Knock will enqueue a new workflow run for the object itself **and** fan out to all of its subscribers, enqueuing a workflow run for each of them.
```javascript title="Triggering a workflow for an object and its subscribers"
await knock.workflows.trigger("alert-workflow", {
recipients: [{ collection: "project_alerts", id: "project-1" }],
data: {
// Data to be passed to all workflow runs
},
});
```
#### Deduplication by default
Knock always deduplicates recipients when executing a notification fan out, including for workflow triggers with subscriptions. Knock will ensure your notification workflow is executed only once for each unique recipient in the following cases:
- When the recipient appears both in the initial trigger and as a subscriber to one of your objects.
- When the recipient appears multiple times within a nested subscription hierarchy.
### Retrieving subscriptions for an object
You can retrieve a paginated list of subscriptions for an object, which will return the `recipient` subscribed as well.
```javascript title="Retrieving a paginated list of subscriptions for an object"
const { entries, page_info: pageInfo } = await knock.objects.listSubscriptions(
"project_alerts",
"project-1",
{ after: null },
);
```
### Retrieving subscriptions for a user
You can retrieve a paginated list of active subscriptions for a user, which will return the `object` that the user is subscribed to as well.
```javascript title="Retrieving a paginated list of subscriptions for a user"
const { entries, page_info: pageInfo } = await knock.users.getSubscriptions(
"user-1",
{ after: null },
);
```
## Accessing subscription properties in a workflow run
When triggering a workflow for a recipient from a subscription, the `properties` defined on the subscription are made available for use within the workflow run scope. You can access the properties under the `recipient.subscription` namespace.
As an example, if you have a property `role` under your subscription properties, you can access it as `recipient.subscription.role` in the workflow run scope.
Knock resolves these properties once, when it fans out the workflow trigger and enqueues the recipient workflow run. They stay fixed for the life of that run, even if the underlying subscription changes while the run is in flight. See [subscription properties on paused workflow runs](#faq-subscription-properties-on-paused-runs) for more detail.
If you're looking to reference the parent object that the recipient is
subscribed to, you can use the recipient.subscription.object{" "}
property.
}
/>
## Referencing subscriptions in templates
You can use the `subscriptions` Liquid filter to dynamically load up to 25 active subscriptions for a user in your notification templates. This is useful when you want to render content based on what a user is subscribed to without passing subscription data in the workflow trigger.
```liquid title="Rendering a user's subscriptions in a template"
{% assign subs = recipient.id | subscriptions %}
{% for sub in subs %}
{{ sub.object.id }} - {{ sub.properties.role }}
{% endfor %}
```
For more details, see [referencing data in templates](/template-editor/referencing-data#referencing-subscriptions-via-the-subscriptions-filter).
## Modeling nested subscription hierarchies
It's possible to model nested subscription hierarchies by associating child objects as subscribers of a parent object. This allows you to create structures like "organizations" having many "teams" which have many "team members" (users).
```javascript title="Adding child objects as subscribers of a parent object"
await knock.objects.addSubscriptions("organizations", "org-1", {
recipients: [
{ collection: "teams", id: "team-1", name: "Org 1, Team 1" },
{ collection: "teams", id: "team-2", name: "Org 1, Team 2" },
],
});
```
Once you've established a nested hierarchy like the above, it's also possible to notify **all child subscribers** from a parent object. In the example above, that means we could notify all team members of an organization by setting the recipient of the trigger to be the organization.
currently we only support subscriptions at a maximum depth of 2, meaning
you can model a hierarchy such as {"parent -> child -> user"}{" "}
but no deeper. If you need to support a deeper nesting, please{" "}
get in touch.
}
/>
## Frequently asked questions
There's no upper bound in the number of subscribers you can have against a
recipient, although you can only **manage** 100 recipients on an object at a
time using our API.
Yes! An object with subscribers _can also_ be subscribed to a parent object,
allowing you to create nested hierarchies of objects (like a Team has many
Projects, and each Project has many Members).
Right now, you can only **view** the subscribers of an object in the
dashboard. You can do so under **Objects** > **Subscriptions**.
Yes, you can pass a set of `properties`, which is a set of unstructured
key-value pairs that you set any arbitrary data about.
Right now the answer is no, but we're interested in hearing about your use
case here as we're considering adding this functionality in the future.
Yes, you can. Once you trigger a workflow for an object that has subscribers
attached, you will see a workflow run for each of the subscribers under the
"Workflow runs" page.
Yes. When you trigger a workflow for an object that has subscriptions
attached Knock will generate a workflow run for the object itself and for
all of the attached subscribers. See [object
subscribers](/concepts/objects#object-subscribers) for more details.
Yes. Add a [step condition](/designing-workflows/step-conditions) to
conditionally execute steps based on recipient type, or contact
[support](mailto:support@knock.app) to discuss disabling object runs across
your account.
No, currently Knock [deduplicates all recipients](#deduplication-by-default)
when fanning out to object subscribers. If this is blocking one of your use
cases or your adoption of Knock, please contact our [support
team](mailto:support@knock.app).
Yes. You can access the object that the recipient is subscribed to using the
`recipient.subscription.object` property.
No. Knock resolves the properties on a subscription at the point of fan-out, when it enqueues the recipient workflow run, and holds those values for the life of the run. If a workflow pauses on a [delay](/designing-workflows/delay-function), [batch](/designing-workflows/batch-function), or [wait for event](/designing-workflows/wait-for-event-function) step, an update you make to the subscription during the pause will not appear under `recipient.subscription` when the run resumes. This is expected behavior.
The parent object under `recipient.subscription.object` is an exception. Knock re-reads it from your environment each time a step executes, so updates to that object's properties during a pause are reflected.
If you need the current state of a subscription at send time, use the [`subscriptions` Liquid filter](/template-editor/referencing-data#referencing-subscriptions-via-the-subscriptions-filter), which queries your environment when the template renders. Iterate over the results and match on `recipient.subscription.object` to find the subscription for the object that the run fanned out from.
```liquid title="Reading current subscription properties for the object that fanned out the run"
{% assign subs = recipient.id | subscriptions %}
{% for sub in subs %}
{% if sub.object.id == recipient.subscription.object.id and sub.object.collection == recipient.subscription.object.collection %}
{% assign current_subscription = sub %}
{% break %}
{% endif %}
{% endfor %}
{% if current_subscription %}
Your role on this project is {{ current_subscription.properties.role }}.
{% else %}
Your role on this project is {{ recipient.subscription.role }}.
{% endif %}
```
Note that the filter returns the 25 oldest subscriptions for the recipient, so a recipient with more than 25 subscriptions may not have a match in the returned set. The example above falls back to `recipient.subscription` for that case.
No, currently the `actor` is **always** excluded from being a recipient in a
workflow trigger if they are a subscriber to an Object recipient.
No, currently we do not support [creating schedules](/concepts/schedules) to
notify subscribers of an object. Each individual subscriber will need to be
added as a recipient when creating the workflow schedule; a schedule for an
object recipient will only generate a workflow run for that object.
Yes, you can. [Workflow
cancellation](/send-notifications/canceling-workflows) requests can be
scoped to one or more specific recipients. You can target any recipient who
was notified via an object subscription, even if that recipient was not
explicitly included in the workflow trigger request.
## Audiences
Learn how to use Audiences to power your lifecycle and transactional messaging.
---
title: Audiences
description: Learn how to use Audiences to power your lifecycle and transactional messaging.
tags:
[
"dynamic audiences",
"static audiences",
"user segmentation",
"segmentation",
"segment",
"lifecycle",
"marketing",
"transactional",
"audience",
"groups",
"segments",
"cohorts",
"dynamic",
]
section: Concepts
---
An Audience is a user segment that you can use to target users for [workflows](/concepts/workflows), [guides](/in-app-ui/guides/overview), and [broadcasts](/concepts/broadcasts). Knock supports two types of audiences: static and dynamic. Dynamic audiences are maintained in real-time based on a set of defined conditions. Static audiences are mained via direct updates, either via a reverse ETL source such as Hightouch or Census, a CSV upload, the API, or manually in the Knock dashboard.
Use audiences to:
- [Trigger workflows](/send-notifications/triggering-workflows/audiences) for lifecycle messaging (such as new user signups) and transactional messaging (such as payment method updates).
- Orchestrate branch and conditional logic within your workflows using audience membership (e.g. if a user is in a `paid users` audience, opt them out of the workflow).
- Target users for an [in-app guide](/in-app-ui/guides/overview).
- Send a one-time message to a specific audience with a [broadcast](/concepts/broadcasts).
## Creating an audience
To create an audience, navigate to the **Audiences** page under the **Recipients** section on the Knock dashboard’s sidebar, then click “Create audience” in the top right corner. Determine whether the audience will be dynamic or static. Audience types cannot be changed after creation.
### Dynamic audiences
Dynamic audiences are built by creating a set of query rules on top of the [user data in Knock](/concepts/recipients), expressed as [conditions](/concepts/conditions). You can build dynamic audiences using the properties available on your user objects. For a full reference of supported condition types and operators, see the [conditions docs](/concepts/conditions).
Knock will automatically update the dynamic audience in real-time as the [user data](/managing-recipients/identifying-recipients) in Knock changes, moving users in and out of the audience as their properties change. These changes are known as "membership events" and are used to trigger workflows.
When building a dynamic audience, you will see a real-time preview of the audience members that match the query rules you’ve created on the right side of the screen. Remember, these are **users in the current environment** that match the query rules you’ve created.
Changes to dynamic audience are [versioned](/version-control/commits) and [promoted](/version-control/commits#promoting-commits) to environments. These changes must be made in your environment's `main` [branch](/version-control/branches).
Support for filtering by event data and tenant or object data is on the
roadmap. If you’re currently hitting a limitation with dynamic audiences,{" "}
send us your feedback
.
}
/>
### Static audiences
Static audiences are populated by adding users directly. You can populate a static audience in a variety of ways:
- **Workflows.** You can use the [update audience function](/designing-workflows/update-audience-function) in a workflow to add or remove users from a static audience.
- **Reverse ETL support.** Audiences can easily be synced from [Hightouch](/integrations/sources/hightouch#syncing-audiences-into-knock-from-hightouch) Models and [Census](/integrations/sources/census) Segments by configuring Knock as a sync destination. Click through to the integration-specific documentation for more information.
- **Audiences API.** The Knock API can be used to sync audiences from any data warehouse or reverse ETL system. Create the audience in the Knock dashboard, then use the add and remove API operations to power your sync. The API is designed for batch processing and accepts payloads of up to 1,000 members at a time. For more information see the [audiences API docs](/api-reference/audiences).
- **CSV upload.** You can upload a CSV of users to an audience. After uploading your CSV, you can map the CSV fields to the corresponding user fields in Knock. Knock will upsert the users as they are added to the audience and skip any users with malformed or missing IDs. The maximum size of a CSV upload is capped at 10MB.
- **Manually.** You can manually add existing users to an audience in the dashboard.
## Audiences and workflows
Audiences integrate with workflows in two key ways. You can configure a workflow to [trigger automatically whenever a user enters an audience](/send-notifications/triggering-workflows/audiences), enabling event-driven lifecycle messaging without additional API calls. You can also use audience membership as a condition in [branch](/designing-workflows/branch-function) and [step conditions](/designing-workflows/step-conditions) to gate logic based on which audiences a user belongs to at the time of execution.
## Audiences and tenants
Currently, tenant targeting is only supported for static audiences, but
support for dynamic audiences is coming soon.
}
/>
When adding users to static audience you can optionally include a tenant ID to power per-user, per-tenant notifications. When uploading an audience via CSV, the column that contains your tenant IDs should be mapped to the Knock field `tenant_id`.
A user can exist in an audience with multiple distinct tenants:
When a tenant is provided as part of a user's audience membership record, it will be passed as the `tenant` context on any broadcast or workflow runs that are triggered for that audience:
- For broadcasts, tenants that are mapped in your audience are included when the broadcast is sent. If a user is included in the audience with multiple distinct tenants, the broadcast will be sent once per tenant.
- For workflows that are triggered from an audience entry event, the tenant ID provided for the member will be passed along to the workflow trigger. If the same user is added with multiple distinct tenants, the workflow will trigger each time by default. To configure this behavior use [trigger frequency](/send-notifications/triggering-workflows#controlling-workflow-trigger-frequency) controls.
These runs will respect any tenant-specific [preferences](/multi-tenancy/per-tenant-preferences), [branding](/multi-tenancy/per-tenant-branding), and [translations](/multi-tenancy/per-tenant-translations) that have been configured for the tenant and recipient.
### Conditional evaluation
Tenancy is also taken into account when [audience membership conditions](/concepts/conditions#condition-types) are evaluated. For a recipient to be considered a member of an audience when a condition is evaluated, the `tenant` ID provided as context on the current broadcast or workflow run must match the user’s audience membership record. If no tenant ID was provided with the trigger, the user must have been added to the audience with no tenant ID.
For more information about how audience membership is evaluated for guides eligibility, see the [guides documentation](/in-app-ui/guides/overview#working-with-tenants).
## Frequently asked questions
If you add a user to an Audience who has not yet been identified to Knock, they will be indicated as a "missing user" in the audience. If you subsequently identify a user with the missing `user_id`, they will be a member of the audience and no longer "missing."
However, Knock will not retroactively trigger any audience-entry triggered workflows for users that are identified after being added to the audience.
Yes, you can create a dynamic audience by querying the user data in Knock. Learn more about [building a dynamic audience](/concepts/audiences#building-a-dynamic-audience).
No, currently you cannot use [source event data](/integrations/sources/overview) to build a dynamic audience. We will be adding this capability in the future. Please [get in touch](mailto:support@knock.app) if you have a specific use case for this functionality.
No, you can currently only build dynamic audiences using user data in Knock. We will be adding support for other object data in the future, including the ability to build a list of users based on their relationship to other objects in your system (like tenants). Please [get in touch](mailto:support@knock.app) if you have a specific use case for this functionality.
Dynamic audiences are updated in real-time. Any changes to the user data in Knock will be reflected in the dynamic audience immediately. That means if you have a property `plan_type` on the user object, and you build a dynamic audience for users on the `pro` plan, setting the `plan_type` to `pro` will immediately add the user to the dynamic audience.
While you can use an audience on a development [branch](/version-control/branches) to power workflows, broadcasts, and guides, you cannot make changes to an audience on a branch. You can only make changes to an audience on the main branch.
The reserved `created_at` and `updated_at` properties on user objects cannot be used in dynamic audience conditions. If you need to filter users by these values, store them as custom properties on your user objects in Knock.
Users can be removed from a static audience in the following ways:
- During a workflow run, using the [update audience function](/designing-workflows/update-audience-function)
- Individually via the Knock dashboard
- In bulk using [the Knock API](/api-reference/audiences/remove_members), which supports removing up to 1,000 users at a time
- Through [reverse ETL syncs](#supported-reverse-etl-vendors)
## Schedules
Learn how to use Schedules to run workflows at set times for your recipients in a recurring or one-off manner.
---
title: Schedules
description: Learn how to use Schedules to run workflows at set times for your recipients in a recurring or one-off manner.
tags:
[
"crons",
"schedules",
"digest",
"recurring",
"weekly",
"daily",
"monthly",
"schedule",
]
section: Concepts
---
A schedule allows you to automatically trigger a workflow at a given time for one or more recipients. You can think of a schedule as a managed, recipient-timezone-aware cron job that Knock will run on your behalf.
Some examples of where you might reach for a schedule:
- A digest notification where your users can select the frequency in which they wish to receive the digest (every day, every week, every month).
- A reminder notification for a specific event or deadline, sent only once at a given date and time.
## How schedules work
1. [Create a workflow](/designing-workflows) that you wish to run in the future.
2. Using the API, [set a repeating schedule](#scheduling-workflows-with-recurring-schedules-for-recipients) or a [non-recurring schedule](#scheduling-workflows-with-one-off-non-recurring-schedules-for-recipients) for one or more recipients for the workflow.
Knock will preemptively schedule workflow runs for the recipient(s) that you've provided, and execute those runs at the scheduled time. At the end of the workflow run (and in case of using a recurring schedule), a future scheduled workflow will be enqueued based on the recipient's next schedule.
Breaking changes to Schedules methods were introduced in the v1.0 release
of the Knock SDKs. Learn more about the new syntax in the{` `}
SDK migration manuals.
}
/>
## Scheduling workflows with recurring schedules for recipients
To schedule a workflow for a recipient using recurring schedules, you must first have a valid, committed workflow in your environment. We can then set a schedule with `repeats` for one or more recipients (up to 100 at a time).
```typescript title="Creating a recurring schedule for multiple recipients"
import Knock from "@knocklabs/node";
const client = new Knock({ apiKey: process.env["KNOCK_API_KEY"] });
const schedules = await client.schedules.create({
recipients: ["jhammond", "esattler", "dnedry"],
workflow: "park-alert",
data: { type: "dinosaurs-loose" },
repeats: [
{
days: ["mon", "tue", "wed", "thu", "fri", "sat", "sun"],
frequency: "daily",
hours: 9,
interval: 1,
minutes: 30,
},
],
ending_at: "2026-01-02T10:00:00Z", // Schedule will stop after this date
tenant: "jpark",
});
```
## Scheduling workflows with one-off, non-recurring schedules for recipients
To schedule a workflow for a recipient using a non-recurring schedule, you must also have a valid and committed workflow in your environment. We can then set a schedule with the `scheduled_at` property, specifying the moment when this workflow should be executed.
```typescript title="Creating a one-off schedule for a specific date and time"
import Knock from "@knocklabs/node";
const client = new Knock({ apiKey: process.env["KNOCK_API_KEY"] });
const schedules = await client.schedules.create({
recipients: ["jhammond", "esattler", "dnedry"],
scheduled_at: "2025-12-22T17:45:00Z",
workflow: "park-alert",
data: { type: "dinosaurs-loose" },
tenant: "jpark",
});
```
when using an Object as a recipient for a scheduled workflow, only the
object itself will receive the notification. Subscribers to that object
will not be included. If you want to schedule workflows for subscribers of
an object, you must add each subscriber individually as a recipient when
creating the workflow schedule.
}
/>
### Schedule properties
| Variable | Type | Description |
| -------------- | --------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `recipients` | RecipientIdentifier[] | One or more recipient identifiers, or complete recipients to be upserted. |
| `workflow` | string | The workflow to trigger. |
| `repeats` | ScheduleRepeat[] | A list of one or more repeats (see below). Required if you're creating a recurring schedule. |
| `data` | map | Custom data to pass to every workflow trigger. |
| `tenant` | string | A tenant to pass to the workflow trigger. |
| `actor` | RecipientIdentifier | An identifier of an actor, or a complete actor to be upserted. |
| `scheduled_at` | utc_datetime | A UTC datetime in ISO-8601 format representing the start moment for the recurring schedule, or the exact and only execution moment for the non-recurring schedule. |
| `ending_at` | utc_datetime | A UTC datetime in ISO-8601 format that indicates when the schedule should end. Once the current schedule time passes `ending_at`, no further occurrences will be scheduled. |
### ScheduleRepeat properties
| Variable | Type | Description |
| -------------- | ------------------------------------ | --------------------------------------------------------------------------------------------------------------------------------------------- |
| `frequency` | RepeatFrequency | The frequency in which this repeat schedule should run, one of monthly, weekly, daily, or hourly. |
| `interval` | number (optional) | The interval in which the rule repeats. Defaults to 1. Setting to 2 with a `weekly` frequency would mean running every other week. |
| `day_of_month` | number (optional) | The exact day of the month that this repeat should run. |
| `days` | DaysOfWeek[], "weekdays", "weekends" | The days of the week that this repeat rule should run. Can provide "weekdays" or "weekends" as a shorthand. |
| `hours` | number (optional) | The hour this schedule should run (in the recipient's timezone). Defaults to 00. |
| `minutes` | number (optional) | The minute this repeat should run (in the recipient's timezone). Must be one of: 0, 5, 10, 15, 20, 25, 30, 35, 40, 45, 50, 55. Defaults to 0. |
## Modeling repeat behavior
Every recurring schedule accepts one or more repeat rules, which allow you to express complex rules like:
- Every Monday at 9am.
- Every weekday at 10.30am.
- Every other Monday, Tuesday, and Friday at 6pm.
- Every year at midnight.
A schedule repeat has the following type structure:
```typescript title="ScheduleRepeat type definitions"
enum DaysOfWeek {
Mon = "mon",
Tue = "tue",
Wed = "wed",
Thu = "thu",
Fri = "fri",
Sat = "sat",
Sun = "sun",
}
enum RepeatFrequency {
Monthly = "monthly",
Weekly = "weekly",
Daily = "daily",
Hourly = "hourly",
}
type ScheduleRepeatProperties = {
frequency: RepeatFrequency;
interval?: number;
day_of_month?: number;
days?: DaysOfWeek[] | "weekdays" | "weekends";
hours?: number;
minutes?: number;
};
```
### Example repeat rules
To illustrate how to model a repeat rule, here are some common examples:
**Every Monday at 9am**
```json title="Schedule repeat for every Monday at 9am"
{
"frequency": "weekly",
"days": ["mon"],
"hours": 9
}
```
**Every weekday at 10.30am**
```json title="Schedule repeat for every weekday at 10:30am"
{
"frequency": "weekly",
"days": "weekdays",
"hours": 10,
"minutes": 30
}
```
**Every other Monday, Tuesday, and Friday at 6pm**
```json title="Schedule repeat for every other week on specific days"
{
"frequency": "weekly",
"interval": 2,
"days": ["mon", "tue", "fri"],
"hours": 18,
"minutes": 0
}
```
## Updating schedules
Up to 100 recipient schedules can be updated in a single call. Keep in mind that the properties passed in will be applied to all schedules.
```typescript title="Updating existing schedules"
import Knock from "@knocklabs/node";
const client = new Knock({ apiKey: process.env["KNOCK_API_KEY"] });
const schedules = await client.schedules.update({
schedule_ids: workflowScheduleIds,
ending_at: "2024-06-01T00:00:00Z", // Update when the schedule should end
data: { foo: "bar" },
});
```
## Removing schedules
Up to 100 schedules can be deleted at a time, causing any already enqueued schedules to be cancelled for a recipient.
```typescript title="Deleting schedules"
import Knock from "@knocklabs/node";
const client = new Knock({ apiKey: process.env["KNOCK_API_KEY"] });
const schedules = await client.schedules.delete({
schedule_ids: workflowScheduleIds,
});
```
## Listing scheduled workflows
Schedules can be listed per recipient (for a user or an object), or for an individual workflow:
```typescript title="Listing schedules for a user"
import Knock from "@knocklabs/node";
const client = new Knock({ apiKey: process.env["KNOCK_API_KEY"] });
// Automatically fetches more pages as needed.
for await (const schedule of client.users.listSchedules("user_id")) {
console.log(schedule.id);
}
```
```typescript title="Listing schedules for a specific workflow"
import Knock from "@knocklabs/node";
const client = new Knock({ apiKey: process.env["KNOCK_API_KEY"] });
// Automatically fetches more pages as needed.
for await (const schedule of client.schedules.list({
workflow: "workflow-key",
})) {
console.log(schedule.id);
}
```
Schedules include a `next_occurrence_at` property which computes the **next time that a schedule will be executed**.
Schedules also include a `last_occurrence_at` property which indicates when was the last time the schedule was executed.
## Workflow data in a scheduled workflow run
Workflows in Knock are triggered either via an API call or via a Source event, both of which will pass the `data` associated. In the case of a scheduled workflow, the workflow will be triggered with an empty data payload by default.
There are 2 ways in which to get data into each of your scheduled workflow runs:
1. **Define static data passed to every triggered workflow on a schedule.** We can include an optional `data` payload when we create our schedule. Any workflow runs triggered by that schedule will include the data payload within their workflow run scope.
2. **Fetch data from an HTTP endpoint to use in your workflow.** You can use an [fetch function step](/designing-workflows/fetch-function) to fetch data for a triggered scheduled workflow to "enrich" the data available with information from a remote server (via HTTP).
## Executing schedules in a recipient's timezone
Knock supports a `timezone` property on the recipient that automatically makes a scheduled workflow run timezone aware, meaning you can express recurring schedules like "every monday at 9am in the recipient's timezone." Recipient timezones must be a valid tz database time zone string, like `America/New_York`.
If a recipient does not have a timezone set, Knock falls back to the [account default timezone](/manage-your-account/account-timezone), or `Etc/UTC`.
[Read more about recipient timezone support](/concepts/recipients#recipient-timezones).
executing schedules in recipient timezones is currently only supported by{" "}
recurring schedules.
}
/>
## Frequently asked questions
No, currently we do not support creating schedules to notify subscribers of
an object. Each individual subscriber will need to be added as a recipient
when creating the workflow schedule; a schedule for an object recipient will
only generate a workflow run for that object.
You can use the `scheduled_at` attribute to start your schedule at a
particular time in the future.
You can use an HTTP fetch step to fetch data in your workflow as the first
step to execute to fetch dynamic template data used in your workflow.
When scheduling a workflow for one or more recipients, you can optionally
provide a static set of `data` which will be passed to the invoked workflow.
At any point before the scheduled workflow is invoked you can unschedule the
workflow for one or more recipients. If a workflow has already run, then
[normal workflow cancellation
rules](/send-notifications/canceling-workflows) take effect.
You'll see workflow runs that initiated from a scheduled workflow in the
list of workflow runs. From there you can select the debugger and debug a
given workflow.
Currently no, but we'll be looking to add this feature in the near future.
The `ending_at` parameter allows you to set an expiration time for both
recurring and one-off schedules. For recurring schedules, no new occurrences
will be scheduled after the `ending_at` time is reached. For one-off
schedules, the schedule will not execute if the `scheduled_at` time is after
the `ending_at` time. The `ending_at` time must be specified in UTC ISO-8601
format, for example: "2024-01-02T10:00:00Z".
Yes, you can update the schedule to change from recurring to non-recurring
(or vice versa). This can be done by removing the `repeats` property and
setting `scheduled_at` to the desired one-time execution time.
Scheduled workflow runs will always reference the workflow version that is
current when the scheduled run is executed. Any scheduled workflow runs that
are not already in flight when you commit your changes will use the updated
workflow version.
## Messages
Learn how Knock models per-recipient notifications with Messages.
---
title: Messages
description: Learn how Knock models per-recipient notifications with Messages.
tags: ["messages", "workflows"]
section: Concepts
---
## An overview
A Message in Knock represents a notification delivered to a [User](/concepts/users) or an [Object](/concepts/objects) on a particular channel. This is the core Knock data entity that your recipients will interact with when receiving notifications.
Knock exposes a set of [Message APIs](/api-reference/messages) via which you can query for notifications and update messages individually or in batches. The Knock [Feeds API](/api-reference/users/feeds) is a specialized view of messages delivered to an in-app feed channel.
The Knock dashboard makes available various message metadata to help you debug your notifications. This includes:
- Information about the request that triggered the delivery of the message.
- A preview of the message content as displayed for the recipient.
- Logs of requests between Knock and your channel provider as Knock works to deliver the message to the recipient.
- A timeline of message lifecycle events.
Message log data in the Dashboard and the public API are subject to
retention policy enforcement. In-app message data and the Feeds API are
not. See the{" "}
data retention docs for
more details on how Knock enforces this policy.
}
/>
## Statuses
Messages have two types of statuses. These are:
- **Delivery statuses** — The delivery state of a message as reported by your channel provider. Delivery statuses are mutually exclusive and implicitly managed by Knock as part of notification delivery.
- **Engagement statuses** — The way in which the recipient has interacted with the notification. A message can have multiple engagement statuses, and you can manage them yourself via the Knock API.
Knock captures changes in message status as events that can be sent to [outbound webhooks](/developer-tools/outbound-webhooks/overview).
To learn more, see our [message status documentation](/send-notifications/message-statuses).
## Link and open tracking
Knock provides opt-in, provider agnostic tracking capabilities for your notifications. With link tracking, Knock will capture link-click actions by your recipients as a message event. With open tracking, Knock will embed tracking pixels in email channel messages to help gauge when recipients are opening and reading your email notifications.
To learn more, see the [Knock tracking documentation](/send-notifications/tracking).
## Conditions
Learn how Knock's conditions model provides dynamic control flow to your workflow runs.
---
title: Conditions
description: Learn how Knock's conditions model provides dynamic control flow to your workflow runs.
tags:
[
"triggers",
"conditions",
"conditionals",
"steps",
"channels",
"workflows",
"preferences",
"conditional send",
"routing",
]
section: Concepts
---
Knock uses conditions to model checks that determine variations in your [workflow](/designing-workflows) runs. They provide a powerful way to create more advanced notification logic flows.
You can use conditions in three areas of the Knock model:
1. [**Step conditions**](/designing-workflows/step-conditions) — Used to determine if a single step in one of your workflows should execute during each workflow run. For example, only send an email if the preceding in-app notification has not yet been read or seen.
2. [**Channel conditions**](/integrations/overview#channel-conditions) — Used to determine if any step using the given channel should execute across all workflow runs. For example, only execute your Postmark email channel steps in your production environment.
3. [**Preference conditions**](/preferences/preference-conditions) — Used to determine the complete set of preferences available to the current workflow run. For example, allow a recipient to mute notifications for specific resources in your product.
Each of these three cases share the same underlying data model and UI editor, which we outline in detail here.
## Condition types
Knock's shared conditions model supports the following types of conditions:
- **Data** — Evaluates against a property in the [workflow trigger](/send-notifications/triggering-workflows) data payload.
- **Recipient** — Evaluates against a property on the workflow run [recipient](/concepts/recipients).
- **Actor** — Evaluates against a property on the workflow run [actor](/send-notifications/triggering-workflows/api#attributing-the-action-to-a-user-or-object).
- **Environment variable** — Evaluates against one of your [environment variables](/concepts/variables).
- **Audience membership** — Evaluates whether the workflow run recipient is a member of an [audience](/concepts/audiences).
- **Workflow** — Evaluates against a property of the currently executing workflow.
- **Workflow run state** — Evaluates against a property of the current workflow run.
- **Tenant** — Evaluates against a property on the [tenant](/concepts/tenants) associated with the current workflow run.
- **Message status** — Evaluates against the [delivery status](/send-notifications/message-statuses#delivery-status) or [engagement status](/send-notifications/message-statuses#engagement-status) of a message from a previous step in the current workflow run.
They are not available for use with channel-level or preference-level
conditions. You can learn more about how to work with message status
conditions in our{" "}
documentation on step-level conditions
.
}
/>
## Modeling conditions
Knock models each condition as a combination of three properties: a `variable`, an `operator`, and an `argument`. This will feel familiar to boolean logic with infix operators in many modern programming languages.
In our [JSON representation of a workflow](/mapi-reference/workflows/schemas/workflow) this will look something like:
```json title="A workflow run condition"
{
"variable": "run.total_activities",
"operator": "greater_than",
"argument": "5"
}
```
We also provide a [conditions editor](#the-conditions-editor) that provides some helpful UX abstractions on top of this model for building conditions in the Knock dashboard.
### Variables
A condition variable is always a string formatted like `"."`. Knock uses the variable `prefix` to determine the condition type and the variable `path` to determine where to look up the data for evaluation.
See the [conditions scope](#conditions-scope) for a list of available prefixes.
### Arguments
Knock uses the condition argument as the expected value in the condition evaluation. Arguments can be either static values or dynamic properties.
#### Static arguments
Static arguments can be any of the following JSON literals:
- Strings (`"foo"`, `"bar"`, `"baz"`)
- Numbers (`1.0`, `2`, `10000`)
- Booleans (`true`, `false`)
- `null`
Plus lists of any of the above.
#### Dynamic arguments
Dynamic arguments are nearly identical to variables. Knock will expect a string formatted like `"."` and use the information within to resolve a value from some runtime data property.
See the [conditions scope](#conditions-scope) for a list of available prefixes.
#### Timestamp arguments
The timestamp operators (`is_timestamp_before`, `is_timestamp_on_or_after`, and `is_timestamp_between`) accept timestamp arguments in three formats:
- **Relative.** A time relative to when the condition is evaluated. Relative timestamps include a value, a unit (`minutes`, `hours`, `days`, or `weeks`), and a modifier (`from now` or `ago`). For example, "7 days ago" or "3 days from now".
- **Absolute.** A fixed date and time. In JSON, this is represented in ISO 8601 format (e.g., `"2025-06-15T14:30:00Z"`).
- **Dynamic.** A Liquid template variable that resolves to a timestamp at runtime (e.g., `{{ recipient.subscription_ends_at }}`). Dynamic timestamp arguments are available in workflows, broadcasts, and guides.
Timestamp condition limitations:
Minimum duration. Relative timestamps must be at
least 15 minutes.
Precise calculations. Relative times are calculated
precisely from the current time. For example, "1 day from now" means
exactly 24 hours from the moment the condition is evaluated, not
"tomorrow".
Between operator. The{" "}
is_timestamp_between operator only supports absolute
dates or dynamic variables, not relative timestamps.
}
/>
### Operators
You can use any of the following operators in condition comparisons:
True if the variable equals the argument (`==`).
| Example condition | Evaluation |
| --- | --- |
| `plan is equal_to pro` where `plan` is `"pro"` | true |
| `plan is equal_to pro` where `plan` is `"free"` | false |
True if the variable does not equal the argument (`!=`).
| Example condition | Evaluation |
| --- | --- |
| `plan is not_equal_to pro` where `plan` is `"free"` | true |
| `plan is not_equal_to pro` where `plan` is `"pro"` | false |
True if the variable is greater than the argument (`>`).
| Example condition | Evaluation |
| --- | --- |
| `age is greater_than 18` where `age` is `21` | true |
| `age is greater_than 18` where `age` is `18` | false |
True if the variable is greater than or equal to the argument (`>=`).
| Example condition | Evaluation |
| --- | --- |
| `age is greater_than_or_equal_to 18` where `age` is `18` | true |
| `age is greater_than_or_equal_to 18` where `age` is `17` | false |
True if the variable is less than the argument (`<`).
| Example condition | Evaluation |
| --- | --- |
| `score is less_than 50` where `score` is `49` | true |
| `score is less_than 50` where `score` is `50` | false |
True if the variable is less than or equal to the argument (`<=`).
| Example condition | Evaluation |
| --- | --- |
| `score is less_than_or_equal_to 50` where `score` is `50` | true |
| `score is less_than_or_equal_to 50` where `score` is `51` | false |
True if the argument appears in the variable.
- When one value is text and one is a list, true if the text is an item in the list.
- When both values are text, true if the argument is a substring of the variable.
- When both values are lists, true if they share any items in common. To check whether one list fully contains the other, use `contains_all`.
| Example condition | Evaluation |
| ------------------------------------------------------------ | ---------- |
| `role contains engineer` where `role` is `"senior engineer"` | true |
| `role contains engineer` where `role` is `"designer"` | false |
| `tags contains vip` where `tags` is `["vip", "beta"]` | true |
| `tags contains vip` where `tags` is `["beta"]` | false |
True if the argument does not appear in the variable. For text, checks whether the argument is not a substring of the variable. For lists, checks whether the argument is not an item in the list. When both values are lists, true if they share no items in common.
| Example condition | Evaluation |
| --- | --- |
| `role not_contains engineer` where `role` is `"designer"` | true |
| `role not_contains engineer` where `role` is `"senior engineer"` | false |
| `tags not_contains vip` where `tags` is `["beta"]` | true |
| `tags not_contains vip` where `tags` is `["vip", "beta"]` | false |
True if all argument values are present in the variable. Lists only.
| Example condition | Evaluation |
| --- | --- |
| `roles contains_all ["admin", "editor"]` where `roles` is `["admin", "editor", "viewer"]` | true |
| `roles contains_all ["admin", "editor"]` where `roles` is `["admin"]` | false |
True if not all argument values are present in the variable. Lists only.
| Example condition | Evaluation |
| --- | --- |
| `roles not_contains_all ["admin", "editor"]` where `roles` is `["admin"]` | true |
| `roles not_contains_all ["admin", "editor"]` where `roles` is `["admin", "editor"]` | false |
True if the variable is `""`, `null`, `[]`, or not set. No argument needed.
| Example condition | Evaluation |
| --- | --- |
| `name is empty` where `name` is `""` | true |
| `name is empty` where `name` is `"alice"` | false |
True if the variable has a non-empty, non-null value. No argument needed.
| Example condition | Evaluation |
| --- | --- |
| `name is not_empty` where `name` is `"alice"` | true |
| `name is not_empty` where `name` is `""` | false |
True if the variable is set and not `null`. No argument needed. Note that a property set to an empty string or empty list is evaluated as existing. Use `not_empty` if you want to check for a meaningful value.
| Example condition | Evaluation |
| --- | --- |
| `plan exists` where `plan` is `"pro"` | true |
| `plan exists` where `plan` is `""` | true |
| `plan exists` where `plan` is `null` | false |
True if the variable is not set or is `null`. No argument needed. Note that a property set to an empty string or empty list is evaluated as existing. Use `empty` if you want to check for a missing or empty value.
| Example condition | Evaluation |
| --- | --- |
| `plan not_exists` where `plan` is `null` | true |
| `plan not_exists` where `plan` is `"pro"` | false |
| `plan not_exists` where `plan` is `""` | false |
True if the variable timestamp is before the argument.
| Example condition | Evaluation |
| --- | --- |
| `trial_ends_at is is_timestamp_before 7 days from now` where `trial_ends_at` is `5 days from now` | true |
| `trial_ends_at is is_timestamp_before 7 days from now` where `trial_ends_at` is `10 days from now` | false |
True if the variable timestamp is on or after the argument.
| Example condition | Evaluation |
| --- | --- |
| `activated_at is is_timestamp_on_or_after 30 days ago` where `activated_at` is `10 days ago` | true |
| `activated_at is is_timestamp_on_or_after 30 days ago` where `activated_at` is `60 days ago` | false |
True if the variable timestamp falls between the argument's start and end values. Does not support relative timestamps — use absolute dates or dynamic variables.
| Example condition | Evaluation |
| --- | --- |
| `created_at is is_timestamp_between ["2025-01-01", "2025-12-31"]` where `created_at` is `2025-06-15` | true |
| `created_at is is_timestamp_between ["2025-01-01", "2025-12-31"]` where `created_at` is `2024-12-31` | false |
True if the variable is a timestamp before the current server time. No argument needed.
| Example condition | Evaluation |
| --- | --- |
| `deleted_at is_timestamp_before_now` where `deleted_at` is a past timestamp | true |
| `deleted_at is_timestamp_before_now` where `deleted_at` is a future timestamp | false |
True if the variable is a timestamp on or after the current server time. No argument needed.
| Example condition | Evaluation |
| --- | --- |
| `expires_at is_timestamp_on_or_after_now` where `expires_at` is a future timestamp | true |
| `expires_at is_timestamp_on_or_after_now` where `expires_at` is a past timestamp | false |
### Conditions scope
Knock makes the following available to be used in a condition variable or dynamic argument:
| Property | Description |
| ------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `data.` | A data condition, where `` is used to select a property from the workflow trigger data payload. |
| `recipient.` | A recipient condition, where `` is used to select a property on the current recipient. [See full list of properties available](/template-editor/variables#recipient-user-or-object). |
| `actor.` | An actor condition, where `` is used to select a property on the current actor. [See full list of properties available](/template-editor/variables#recipient-user-or-object). |
| `vars.` | An environment variable condition, where `` is the name of one of your environment variables. |
| `workflow.{id,name,categories}` | A workflow condition. |
| `run.{total_activities,total_actors}` | A workflow run condition. |
| `tenant.` | A tenant condition, where `` is used to select a property on the current tenant. [See full list of properties available](/template-editor/variables#tenant). |
| `refs..delivery_status` | A [message status condition](/designing-workflows/step-conditions#message-status-conditions) that evaluates against a message's [delivery status](/send-notifications/message-statuses#delivery-status), where `` identifies the preceding workflow step that generated the message. |
| `refs..engagement_status` | A [message status condition](/designing-workflows/step-conditions#message-status-conditions) that evaluates against a message's [engagement status](/send-notifications/message-statuses#engagement-status), where `` identifies the preceding workflow step that generated the message. |
In cases where data is not found at the path given by the variable, Knock falls back to an empty string as the default value.
### Combining conditions
The following syntax does not apply to preference conditions. See the{" "}
preference conditions FAQs
{" "}
for more information on combining multiple conditions on a preference.
}
/>
You can combine multiple conditions together via either `AND` or `OR` operators.
- `AND` combined conditions require all conditions to be true for the evaluation to pass.
```json title="JSON representation of AND combined conditions"
"conditions": {
// the AND operator is represented by the "all" key
"all": [
{
"argument": "true",
"operator": "equal_to",
"variable": "recipient.is_active"
},
{
"argument": "true",
"operator": "equal_to",
"variable": "actor.is_active"
}
]
}
```
- `OR` combined conditions require at least one condition to be true for the evaluation to pass.
```json title="JSON representation of OR combined conditions"
"conditions": {
// the OR operator is represented by the "any" key
"any": [
{
"argument": "true",
"operator": "equal_to",
"variable": "recipient.is_active"
},
{
"argument": "true",
"operator": "equal_to",
"variable": "actor.is_active"
}
]
}
```
- You may also use a combination of `AND` and `OR` operators to create more complex conditions.
```json title="JSON representation of OR plus AND combined conditions"
"conditions": {
"any": [
{
"all": [
{
"argument": "true",
"operator": "equal_to",
"variable": "recipient.is_active"
},
{
"argument": "true",
"operator": "equal_to",
"variable": "actor.is_active"
}
]
},
{
"all": [
{
"argument": "true",
"operator": "equal_to",
"variable": "data.force_delivery"
}
]
}
]
}
```
## The conditions editor
The Knock Dashboard ships with a conditions editor that provides helpful abstractions on top of this data model. Rather than needing to remember how to format variables or name operators, Knock makes the appropriate options available to you.
When creating or modifying a condition, you'll see:
- A dropdown to select the condition type. Knock will use this option to determine the variable `` value.
- An input or dropdown to provide the variable data path.
- A dropdown to select the operator.
- An input or dropdown to provide the argument data path.
Working with the conditions editor to build a recipient data condition.
You can also use the conditions editor to combine multiple conditions together via either `AND` or `OR` operators.
Managing condition groups in the conditions editor.
The condition editor is available for use in the [workflow step editor](/designing-workflows#the-workflow-canvas) and the [channel environment settings editor](/integrations/overview#per-environment-configurations).
## Debugging conditions
Knock executes any step, channel, and preference conditions for each step within a workflow run. As part of execution, Knock captures detailed information about each condition evaluation for use in the [workflow debugger](/send-notifications/debugging-workflows).
### Debugging step and channel conditions
Knock will display step and channel conditions evaluation results together in the step detail panel in the debugger. The overall evaluation result will show whether the step was skipped. For each individual condition within the set, Knock will show either:
1. **The condition evaluation result.** This will include any dynamically resolved variable and argument data captured at workflow run time.
2. **A "not evaluated" state.** This will occur when a preceding condition or group has determined the result, meaning subsequent conditions did not require full evaluation.
Debugging step and channel conditions.
### Debugging preference conditions
Knock will display any preference conditions evaluations just below the step and channel conditions results. Knock will group each condition evaluation by location within the resolved preference set. The overall evaluation result will show whether the recipient opted-out for the given workflow, category, or channel type.
Debugging preference conditions.
## Variables
Learn more about using shared Variables in Knock.
---
title: "Variables"
description: "Learn more about using shared Variables in Knock."
tags: ["vars", "variables", "env vars", "secrets", "constants"]
section: Concepts
---
Variables within Knock let you set shared constants or secrets that you can use in all of the workflows and templates under your account. Variables can be overridden at the environment level to set per environment constants.
## Setting variables
You can create account-wide variables on the **Variables** page under the **Account** section of your account settings. Each variable has a `key` and a `value`. The key is how you'll reference the variable in your templates, conditions, and preference conditions when building your workflows.
## Setting secret variables
By default, any variables you set are created as public. Public variables are exposed via the [user feed endpoint](/api-reference/users/feeds/list_items) and are always visible within the dashboard by all team members. If you're working with variables that should not be exposed you can create them as secret variables by toggling the "Make variable secret" slider when creating a variable.
Secret variables are _never_ revealed in the dashboard (all values are obfuscated) and are _never_ exposed via the API.
## Accessing variables
Variables are available to be accessed under the `vars` namespace within your templates, step conditions, and preference conditions. For instance, if you set a variable with the key `base_url` you can access that variable under `vars.base_url`.
## Overriding variables per-environment
You can optionally set environment-specific values for your variables. To do so, go to the **Variables** page under the **Account** section of your account settings, click the three dots for a specific variable to select "Edit variable," and set the value for the environment you wish to override.
## Variable types and JSON parsing
Knock stores every variable value as text, but at send time we try to parse that text as JSON first. If the value is valid JSON, your variable takes on the resulting type. If it isn't, we fall back to using the value as a string.
This means a variable is not always a string. A value of `true` becomes a boolean, and a value of `123` becomes a number.
| Stored value | Parsed as |
| ------------------------------------ | --------------------------------------------------- |
| `true` / `false` | Boolean |
| `123` | Number |
| `12.5` | Number |
| `null` | `null` |
| `["a", "b"]` | Array |
| `{ "unit": "seconds", "value": 30 }` | Object |
| `https://example.com` | String |
| `007` | String (leading zeros aren't valid numbers in JSON) |
| `TRUE` | String (JSON is case-sensitive) |
### Comparing variables in conditions
Because parsing happens before your templates and conditions are evaluated, compare a variable against the type it parses into. A variable set to `true` is a boolean, so compare it as one:
```liquid title="Comparing a boolean variable"
{% if vars.feature_enabled == true %}
Welcome to the new experience.
{% endif %}
```
Comparing that same variable against the string `"true"` will never match.
### Using JSON objects in variables
Object and array values parse the same way, which makes variables useful for setting structured data under a single key. A `support` variable set to `{ "email": "help@example.com", "url": "https://example.com/help" }` gives your templates both `vars.support.email` and `vars.support.url`, and lets you override the pair for each environment in one place.
Some features in Knock can consume a JSON object directly. For example, if you want to set a [dynamic batch window](/designing-workflows/batch-function#set-a-dynamic-batch-window-using-a-variable), you can set a per-environment variable to contain `{ "unit": "seconds", "value": 30 }` and reference that variable from your batch step.
# Knock AI
Use AI in the dashboard, inside workflows, in your IDE, and in external clients.
## Overview
Use AI features across Knock — in the dashboard, inside workflows, in your IDE, and in external clients.
---
title: Knock AI overview
description: Use AI features across Knock — in the dashboard, inside workflows, in your IDE, and in external clients.
section: AI
---
Knock exposes AI functionality across several distinct primitives: a conversational assistant in the dashboard, an AI step inside workflows, a local CLI for IDE-based agents, a remote MCP server for external clients and your own apps, and a set of open-source skills that give agents procedural knowledge for working with Knock. Use this page to understand each one and which to reach for.
## Knock agent
The [Knock agent](/ai/agent) is a conversational assistant built into the Knock dashboard. It can do anything you'd normally do in the dashboard, with full context for the resource you're viewing and your active environment.
Use the Knock agent to:
- Build workflows, broadcasts, partials, email layouts, audiences, message types, and guides through conversation.
- Inspect existing resources and ask questions about how your messaging is configured.
- Ask analytics questions about your messaging performance and get charts and plain-language takeaways back.
- Pull in account-level company context and custom instructions so responses stay on-brand.
- Run bulk updates and refactors across resources — for example, update copy across multiple workflow templates, update a partial's content or options, or apply a formatting change across all your email layouts in a single plan.
The Knock agent does not consume AI credits and is configured under **Settings** > **AI settings**.
## Agent function
The [agent function](/ai/agent-function) is a workflow step that runs a prompt on an AI model of your choice and makes the response available in the rest of your workflow run. Use it to bring AI-powered context into the notifications you send.
Common use cases include:
- **Enrich recipient data.** Use user and tenant properties to infer market, persona, or use case.
- **Summarize batched activity.** Distill a batch of heterogeneous events into a concise digest summary.
- **Classify or route triggers.** Tag a sign-up, support ticket, or comment so downstream steps can branch on it.
The agent function consumes AI credits and is configured per workflow step. See the [full reference](/designing-workflows/ai-agent-function) for prompt and response format details.
## CLI
**Recommended when you're working in an IDE on a Knock-aware codebase.** The [Knock CLI](/ai/cli) gives a coding agent the local tools it needs to read and write Knock resources from your codebase. Reach for the CLI when you're editing code in Cursor, Claude, or Copilot and want the agent to manage workflows, templates, and other resources alongside your application code.
The CLI is the local-first surface and supports the full set of Knock resource operations, including local file scaffolding for new resources, local validation, and committing or promoting changes between environments.
## MCP server
**Recommended for external clients and your own apps.** The [MCP server](/ai/mcp-server) at `mcp.knock.app/mcp` exposes Knock primitives to LLMs and AI agents via the Model Context Protocol. Reach for the MCP server when you need Knock tools available inside Claude Desktop, ChatGPT, or any MCP-compatible client, or when you're building a product that needs Knock primitives behind an LLM.
The MCP server exposes a curated subset of Knock capabilities organized into tool groups (manage resources, commits, debug, manage data, documentation). It does not currently support local file scaffolding, local validation, or deletion — use the CLI for those.
The MCP server is built on top of the{" "}
Knock Agent Toolkit,
a lower-level SDK that lets you choose which tools to expose, configure
the auth model, and bring your own framework.
}
/>
## Skills
**Recommended alongside the CLI, the MCP server, or the dashboard agent.** [Skills](/ai/skills) are packaged procedural knowledge that an AI agent loads automatically when relevant. They sit alongside your tool surfaces and teach an agent _how_ to use those tools effectively.
Skills come from two places:
- **Knock's open-source package** at github.com/knocklabs/skills, installed into AI coding agents like Cursor or Claude. Includes `knock-cli` (pairs with the [CLI](/ai/cli)) and `notification-best-practices` (pairs with any surface).
- **Skills authored inside the [Knock agent](/ai/agent)** in the dashboard, which the dashboard agent invokes automatically during agent runs. Useful for codifying team-specific conventions and account-level context.
## Choosing between the CLI and MCP server
The CLI and MCP server are different tool for different environments. You can use this table to figure out which one fits your task.
| Question | Reach for |
| --------------------------------------------------------------- | ---------------------------- |
| Are you working in an IDE on a Knock-aware codebase? | [CLI](/ai/cli) |
| Do you need to scaffold, validate, or commit resources locally? | [CLI](/ai/cli) |
| Are you using an external GUI like Claude Desktop? | [MCP server](/ai/mcp-server) |
| Are you embedding Knock tools in your own product? | [MCP server](/ai/mcp-server) |
| Do you need ad-hoc natural-language operations? | [MCP server](/ai/mcp-server) |
## Related
- [Knock Agent Toolkit](/developer-tools/agent-toolkit/overview). The SDK behind the MCP server, for fully custom AI integrations.
- [Building with LLMs](/developer-tools/building-with-llms). Patterns and examples for putting Knock behind an LLM.
- **Settings > AI settings** in the dashboard. Configure company context and custom instructions used across Knock AI.
## Knock agent
Use the Knock agent in the dashboard to answer questions, inspect resources, and build customer messaging through conversation.
---
title: Knock agent
description: Use the Knock agent in the dashboard to answer questions, inspect resources, and build customer messaging through conversation.
tags: ["AI", "agent", "dashboard", "assistant"]
section: AI
---
The Knock agent is an AI-powered assistant built into the Knock dashboard.
You can use it to do anything you'd normally do in the dashboard, including create workflows, templates, guides, broadcasts, and partials. You can also use the Knock agent to learn about Knock concepts and inspect existing resources.
The Knock agent is separate from the{" "}
AI agent function, a
workflow step that runs inside a workflow to enrich data.
}
/>
## Get started with the agent
### Start from the Agents page
The Knock agent is available on the **Agents** page in the dashboard. This page lists all of your past conversations with the agent, and allows you to create a new conversation.
### Start from anywhere in the Knock dashboard
On any dashboard page where the agent is enabled, you can use the **agent prompt bar** at the bottom of the page to kick off a new conversation.
Once the agent is running, you can open the agent in a **sidebar** (anchored) or **floating** (overlay) layout to see it running. Use **Cmd+J** (Mac) or **Ctrl+J** (Windows/Linux), or the toggle in the main header to open/close the agent runner.
## Start from Slack
You can optionally use the Knock agent directly from your Slack workspace using the [Knock Slack extension](/integrations/extensions/slack). Doing so allows you to `@Knock` in any channel to kick off an agent session.
## What the Knock agent can do
### Read and inspect resources
The agent has full access to all of your Knock resources, including workflows, broadcasts, partials, email layouts, audiences, message types, and guides.
### Create and modify resources
The agent can create or update workflows, broadcasts, partials, email layouts, audiences, message types, and guides using dedicated tools. Each maps to a customer messaging primitive you manage in the dashboard.
### Bulk updates and refactors
Because the agent operates across all of your resources in a single plan, you can use it to make changes that span multiple workflows at once. For example:
- Update notification copy across every workflow template in a single instruction
- Update a partial's content or options and propagate the change across all templates that reference it
- Apply a formatting or structural change across all your email layouts
This makes the agent useful not just for building new resources, but for maintaining consistency across your messaging as your product evolves.
### Answer analytics questions
The agent can query your account's messaging data and return insights about your workflows, channels, and messages. Ask questions in plain language, such as:
- How many messages did a workflow send this month?
- What's the error rate for a workflow?
- Where are users dropping off in a workflow?
- Which messaging channel is driving the highest engagement?
- How has our delivery volume changed over time?
### Search the web
The agent can run a **web search** for structured results and **fetch** full page content when you need up-to-date or external reference material.
## What the agent cannot do
- Manage account settings such as billing, users, roles, or invites
- Delete resources
- Commit or promote changes to environments
- Run tests of your workflows or broadcasts
## Context awareness
The agent receives context for what you are viewing in the dashboard, including:
- **Active environment.** Are you in development, production, or another environment.
- **Active resource keys.** The workflow, broadcast, partial, so on that you're currently viewing.
- **System context.** You can configure account-level context and custom instructions in your account AI settings that are used in all prompts.
The agent is also fully aware of your partials, email layouts, and translations and so can use those to build or improve your messaging templates.
## Permissions and authorization
The agent respects the permissions you have in your account. If you don't have permission to manage a resource, the agent will not be able to create or update it either.
## Configuration
Workspace admins configure AI under **Settings** > **AI settings**:
- **Agent workflow function.** Lets builders add an AI agent step to workflows; **consumes** AI credits.
- **Knock agents.** Enables the conversational assistant for account members; **does not** consume AI credits.
- **Company context.** Free-text description of your product so answers stay on-brand (up to 5,000 characters.)
- **Custom instructions.** Free-text rules included in every agent conversation (up to 5,000 characters.)
## Related resources
- See how the agent fits alongside Knock's other AI primitives in the [Knock AI overview](/ai/overview)
- Connect external clients through the [MCP server](/ai/mcp-server)
- Set up coding agents with the [Knock CLI](/ai/cli) and [skills](/ai/skills)
## Frequently asked questions
No. The conversational Knock agent does not consume AI credits. The{" "}
AI agent function{" "}
inside workflows does.
Yes. See the MCP server docs for authentication
and tool groups.
## Agent workflow function
Learn how the agent workflow function brings AI-powered enrichment and personalization into your Knock workflows.
---
title: Agent function
description: Learn how the agent workflow function brings AI-powered enrichment and personalization into your Knock workflows.
tags: ["AI", "agent", "workflows", "functions", "personalization", "LLM"]
section: AI
---
The agent function is a workflow step that runs a prompt on an AI model of your choice and makes the response available in your workflow run. You can use it to enrich recipient data, personalize messaging, and bring AI-powered context into your notification flows.
Common use cases include:
- **Enriching recipient data.** Use user and tenant properties (such as domain) to understand a recipient's market, use cases, and target persona.
- **Personalizing messaging.** Bring that context into your [channel step templates](/template-editor/overview) to drive higher conversion rates.
- **Summarizing batch content.** Distill heterogeneous actions into a concise summary that reduces noise in digest notifications.
The agent function is a workflow step that runs inside a workflow run. It
is separate from the Knock agent, the
conversational assistant you use in the dashboard.
}
/>
## Learn more
The agent function lives alongside Knock's other workflow functions. To learn how it works, how to configure a prompt and response format, and how credits and billing work, see the [full reference](/designing-workflows/ai-agent-function) in the designing workflows docs.
For a tour of the other ways you can use AI across Knock, see the [Knock AI overview](/ai/overview).
## Knock CLI
Use the Knock CLI as the local-first surface for AI coding agents to read and write Knock resources from your codebase.
---
title: Knock CLI
description: Use the Knock CLI as the local-first surface for AI coding agents to read and write Knock resources from your codebase.
section: AI
---
The [Knock CLI](/developer-tools/knock-cli) is the local-first AI agent surface for Knock. It's fast, lightweight, and leans on tooling already available in your code editor. Reach for the CLI when you're working in Cursor, Claude, or another IDE on a Knock-aware codebase and you want the agent to manage workflows, templates, and other resources alongside your application code.
## What an agent can do with the CLI
When the Knock CLI is installed and authenticated, an AI coding agent can use it to:
- Pull workflows, templates, email layouts, partials, guides, and message types into your repo.
- Scaffold new resources locally, including new partials and guides.
- Edit resources as code, then validate them before pushing.
- Push changes back to Knock, commit them in an environment, and promote between environments.
- Wire Knock into your CI/CD pipeline.
The CLI exposes the full set of Knock resource operations. The [MCP server](/ai/mcp-server) exposes a curated subset focused on managing resources, manipulating data, and inspecting environments — it does not currently support local file scaffolding, local validation, or deletion. Use the CLI when you need any of those.
## Install the Knock CLI
Install the CLI with `npm`:
```bash title="Installing the Knock CLI"
npm install -g @knocklabs/cli
```
Then authenticate with `knock login`. See the [Knock CLI docs](/developer-tools/knock-cli) for full installation, authentication, and command reference.
## Pair with the `knock-cli` skill
The CLI gives an agent the tools to manage Knock resources. The [`knock-cli` skill](/ai/skills) gives the agent the procedural knowledge to use those tools well — which commands exist, when to reach for each one, and how to structure the resource files the CLI expects.
Install the skill alongside the CLI:
```bash title="Installing the knock-cli skill"
npx skills add knocklabs/skills --skill knock-cli
```
When you ask "add a comment-created workflow to this repo," the agent reads the skill, runs the right `knock` commands, and writes the resulting files into your project.
You can pair this setup with the [MCP server](/ai/mcp-server) when you also want the agent to perform live API operations against your Knock account from outside the IDE.
## See also
- [Knock AI overview](/ai/overview). See how the CLI fits alongside the dashboard agent, agent function, MCP server, and skills.
- [Knock CLI reference](/developer-tools/knock-cli). Full installation, authentication, and command reference.
- [Skills](/ai/skills). Procedural knowledge that complements the CLI and MCP server.
- [MCP server](/ai/mcp-server). Connect external clients and your own apps to Knock as tools.
## Knock MCP server
Use the Knock MCP server to make Knock accessible to LLMs and AI agents via tool calling.
---
title: Knock MCP server
description: Use the Knock MCP server to make Knock accessible to LLMs and AI agents via tool calling.
section: AI
---
Knock ships a remote MCP server at `mcp.knock.app/mcp` that exposes the primitives of Knock to LLMs and AI via the Model Context Protocol (MCP) so that your AI agents can discover and use Knock via tool calling. Reach for the MCP server when you need Knock tools available inside Claude, ChatGPT, Cursor, or any MCP-compatible client, or when you're building a product that needs Knock primitives behind an LLM.
Here are some examples of how you can use the MCP server in your workflow:
- **Create workflows using natural language.** "Create a welcome email workflow for my B2B SaaS app."
- **Trigger a specific workflow to test your integration.** "Trigger the comment-created workflow for Dennis Nedry."
- **Create a set of test user and tenant data in your account.** "Create a user called Dennis Nedry and a tenant called acme-corp."
## Get started
The Knock MCP server is a remote server—no local installation or Node.js setup is required. You connect to `https://mcp.knock.app/mcp` directly from your MCP client. Interactive clients authenticate with your Knock account via OAuth. For CI and other headless environments, you can authenticate with a [service token](#authenticate-with-a-service-token).
We've added setup instructions below for Claude, Claude Code, Cursor, and fx, but the same instructions apply to any other MCP client-compatible application.
### Claude
Knock is listed as a community connector in Anthropic's connectors directory. Use the connector in Claude Cowork and Claude Desktop.
### Claude Code
1. Run the following command to add the Knock MCP server:
```bash
claude mcp add --transport http knock https://mcp.knock.app/mcp
```
2. Start Claude Code and run `/mcp` to authenticate with your Knock account.
### Cursor
1. Go to **Settings** > **Cursor Settings** and find the "Tools & Integrations" section.
2. Click "New MCP server" under **MCP Tools**.
3. Inside your `mcp.json` file under the `mcpServers` key, add the following:
```json
{
"knock": {
"url": "https://mcp.knock.app/mcp",
"name": "Knock MCP Server"
}
}
```
4. When Cursor prompts you to authenticate, sign in with your Knock account.
### fx
1. Start an interactive fx session, then run the following command to add the Knock MCP server:
```bash
/mcp add --transport http knock https://mcp.knock.app/mcp
```
2. Run the following command to authenticate with your Knock account:
```bash
/mcp auth knock --open
```
See the fx MCP docs for more configuration options.
## Authenticate with a service token
For environments that cannot complete a browser OAuth flow, such as CI pipelines or unattended agents, pass a Knock [service token](/developer-tools/service-tokens) (`knock_st_…`) as a bearer credential. MCP clients that set an `Authorization` header skip OAuth.
This is token passthrough: the same Management API credential authenticates the MCP session and outbound Knock calls. Prefer OAuth for interactive use. Treat the service token as a secret.
Generate a service token from the dashboard under **Settings > Service tokens**, then add it to your MCP client config:
```json title="mcp.json"
{
"mcpServers": {
"knock": {
"url": "https://mcp.knock.app/mcp",
"headers": {
"Authorization": "Bearer ${KNOCK_SERVICE_TOKEN}"
}
}
}
}
```
Replace `${KNOCK_SERVICE_TOKEN}` with your token, or keep the environment variable if your client interpolates it.
Service-token sessions skip the consent screen and enable all MCP capabilities. Restrict access with the service token rather than MCP capability checkboxes.
## Capabilities
When connecting to the Knock MCP server with OAuth, you can choose exactly which capabilities to enable. The MCP server exposes a curated subset of Knock functionality — focused on reading and managing resources, running the Knock agent, inspecting environments, and searching documentation. Limiting the active capabilities to only what you need keeps the tool list manageable and reduces the risk of unintended changes.
When you authenticate with a [service token](#authenticate-with-a-service-token), the consent screen is skipped and all capabilities are enabled.
| Capability | Description | Enabled by default |
| -------------------- | ------------------------------------------------------------------------------------------- | ------------------ |
| **Read resources** | Inspect Knock configuration via the Management API (GET requests) | Yes |
| **Manage resources** | Create and update Knock configuration via the Management API (write requests) | Yes |
| **Knock agent** | Use the Knock agent to create and manage workflows, broadcasts, guides, and other resources | Yes |
| **Debug** | Inspect environments and view sent message logs | No |
| **Manage data** | Manage users, tenants, and object data | No |
| **Documentation** | Search Knock documentation | No |
### Knock agent capability
The **Knock agent** capability enables tools that invoke the same [Knock agent](/ai/agent) available in the dashboard. When enabled, your MCP client can start agent sessions to create and manage workflows, broadcasts, guides, and other resources through a conversational interface.
This capability is useful when you want the agent to handle complex, multi-step tasks that benefit from its built-in knowledge of Knock best practices and resource relationships. For simpler, direct operations, the **Read resources** and **Manage resources** capabilities provide lower-level access through the Management API.
If you need capabilities the MCP server doesn't expose — such as local file scaffolding for new resources, validating them before push, or working entirely offline against a checked-in repo — reach for the [Knock CLI](/ai/cli) instead.
## What tools are available?
The MCP server ships with tools to interact with all Knock resources. You can find the full list of available tools in the [tools reference](/developer-tools/agent-toolkit/tools-reference) of the Knock Agent Toolkit, which the MCP server is built on top of.
Please note that at this time, the MCP server **does not** ship with any tools to delete resources. This is intentional to prevent the accidental deletion of resources in your Knock account.
### Workflow-specific tools
The Knock MCP server exposes a full suite of tools for creating and managing workflows. Using the MCP server you can:
- Create a workflow with natural language: "create a workflow that sends a welcome email to new users"
- Create a delay or batch step within your workflow: "delay for 3 days" or "batch for 10 minutes"
- Create an email step within your workflow: "create a credit card expiring email with a link back to the dashboard"
- Create an SMS, push, or in-app feed step within your workflow
Using these tools you can create a complex prompt that describes one or more workflows that you'd like to create with natural language.
## Workflows-as-tools
The Knock MCP server also supports exposing your workflows as individual tools. This gives the LLM a specific and precise interface for invoking workflow triggers, including describing the data trigger requirements for your workflows.
By default, the MCP server will **not** expose any workflows as tools. To opt into this behavior, contact us or refer to your MCP client's tool configuration options.
## Pair with skills
The MCP server gives an agent the tools to operate on Knock. [Skills](/ai/skills) give the agent the procedural knowledge to operate on Knock _well_. The two are complementary, and most teams using MCP install at least one skill alongside it.
Knock's [`notification-best-practices`](/ai/skills) skill pairs naturally with the MCP server. It teaches an agent how to write effective notification copy across email, SMS, push, and in-app channels — guidance that applies regardless of whether the agent reaches Knock through MCP, the CLI, or the dashboard agent.
Install it with:
```bash
npx skills add knocklabs/skills --skill notification-best-practices
```
See the [skills page](/ai/skills) for the full catalog of available skills and which surface each one complements.
## Related links
- [Knock AI overview](/ai/overview)
- [Knock agent](/ai/agent)
- [CLI](/ai/cli)
- [Skills](/ai/skills)
- [Service tokens](/developer-tools/service-tokens)
- [Building with LLMs](/developer-tools/building-with-llms)
- [Knock Agent Toolkit](/developer-tools/agent-toolkit/overview)
## Frequently asked questions
Some MCP clients will warn you about having more than 50 tools. To address
this, enable only the capabilities you need for the task at hand. For
example, if you're only managing user data, enable the **Manage data**
capability and leave the others disabled. Service-token sessions enable all
capabilities, so you may see this warning in headless clients.
If you see an error like _"The model returned an error. Try disabling MCP
servers, or switch models,"_ check which model is selected for the Cursor
agent. Make sure it's explicitly set to a supported model like
`claude-sonnet-4` rather than relying on automatic model selection.
Yes. For CI and other headless environments, pass a service token as a
bearer credential in your MCP client config. See [authenticate with a
service token](#authenticate-with-a-service-token). Interactive clients
should keep using OAuth.
## Skills
Use skills to give AI agents the procedural knowledge they need to work with Knock effectively, whether they run in your IDE, an external client, or the Knock dashboard.
---
title: Skills
description: Use skills to give AI agents the procedural knowledge they need to work with Knock effectively, whether they run in your IDE, an external client, or the Knock dashboard.
section: AI
---
Skills are packaged instructions and rules that extend an AI agent's capabilities with Knock-specific procedural knowledge. They sit alongside your tool surfaces — the [Knock CLI](/ai/cli), the [MCP server](/ai/mcp-server), and the [Knock agent](/ai/agent) in the dashboard — and teach the agent _how_ to use those tools to accomplish real work.
Once a skill is available to an agent, it auto-activates when you ask the agent to work on a related task. There's no manual prompting required.
Skills come from two places at Knock:
- **The open-source `knocklabs/skills` package** that you install into an AI coding agent (Cursor, Claude, and similar). These are the skills covered in [Available skills](#available-skills) below.
- **Your own skills authored inside the [Knock agent](/ai/agent)** in the dashboard. The dashboard agent supports creating skills directly in your account and invokes them automatically during agent runs, which is useful for codifying team-specific conventions that aren't captured in the open-source package.
## Install Knock's open-source skills in a coding agent
Knock publishes an open-source skills package on GitHub at github.com/knocklabs/skills. Install it into any compatible AI coding agent (Cursor, Claude, and similar) so the agent can use Knock's skills when working on your codebase.
Install the entire package with a single command:
```bash title="Installing the Knock skills package"
npx skills add knocklabs/skills
```
Or install specific skills by passing a flag:
```bash title="Installing individual Knock skills"
npx skills add knocklabs/skills --skill knock-cli
npx skills add knocklabs/skills --skill notification-best-practices
```
## Author skills in the Knock dashboard agent
The [Knock agent](/ai/agent) in the dashboard also supports skills. You can create skills directly in your Knock account and the dashboard agent invokes them automatically during agent runs.
Use dashboard skills to:
- Codify team-specific conventions that aren't captured in the open-source package (for example, your internal naming standards, copy guidelines, or workflow patterns).
- Standardize how the agent handles common requests across your account.
- Layer organizational context on top of Knock's built-in agent behavior.
The open-source package and dashboard-authored skills are complementary. A team might install `notification-best-practices` from the open-source package and also author an internal "transactional email tone of voice" skill in the dashboard.
## Available skills
### `knock-setup`
The `knock-setup` skill connects Knock to a coding agent, discovers high-value workflows from a product, and helps wire triggers into the application.
**Complements.** The [MCP server](/ai/mcp-server) and [Knock CLI](/ai/cli).
### `knock-cli`
The `knock-cli` skill teaches AI agents how to use the [Knock CLI](/developer-tools/knock-cli) to manage your Knock resources from your codebase.
**Complements.** The [Knock CLI](/ai/cli).
Use it when you want an agent to:
- Pull workflows, templates, guides, and partials to your local machine.
- Push local changes back to Knock.
- Manage Knock resources as part of a development or CI/CD workflow.
### `knock-notification-best-practices`
The `knock-notification-best-practices` skill gives AI agents comprehensive guidelines for notification design and implementation.
**Complements.** Any surface — the [Knock CLI](/ai/cli), the [MCP server](/ai/mcp-server), and the [Knock agent](/ai/agent) in the dashboard. Because this skill is about content and UX rather than how the agent reaches Knock, it applies regardless of which surface the agent uses.
Use it when you want an agent to:
- Write notification copy across channels (email, SMS, push, in-app).
- Apply best practices for transactional and welcome email templates.
- Follow channel-specific formatting and content guidelines.
### `knock-in-app-ui`
The `knock-in-app-ui` skill helps agents set up, render, and debug Knock guides in React.
**Complements.** The [Knock CLI](/ai/cli) and in-app UI SDKs.
### `knock-product-messaging-strategy`
The `knock-product-messaging-strategy` skill helps agents design a cross-channel messaging system for activation, engagement, and retention — including triggers, ownership, channel progression, preferences, and measurement — then map that plan onto Knock workflows and guides.
**Complements.** Any surface. Pairs with Knock manuals such as the [product leader's guide to effective messaging](https://knock.app/manuals/product-leaders-guide-to-effective-notifications/the-product-leaders-guide-to-effective-notifications).
Use it when you want an agent to:
- Plan lifecycle and retention messaging for a product.
- Audit an existing notification program for gaps and fatigue.
- Prioritize workflows and guides before building them in Knock.
### `knock-lifecycle-opportunities`
The `knock-lifecycle-opportunities` skill scans a product codebase for activation, engagement, expansion, and churn signals, then recommends precise lifecycle messaging opportunities.
**Complements.** Pairs with `knock-product-messaging-strategy` for deeper design, and `knock-setup` when you're ready to build.
### `knock-migrate-to-knock`
The `knock-migrate-to-knock` skill investigates existing messaging infrastructure (Braze, Courier, Customer.io, ESP-direct, or custom code) and recommends how it maps onto Knock.
**Complements.** The [Braze](/tutorials/migrate-from-braze) and [Courier](/tutorials/migrate-from-courier) migration tutorials, plus `knock-setup` when you're ready to cut over.
## How skills fit with the CLI, MCP server, and dashboard agent
Skills are not tied to a single tool surface. Different skills complement different surfaces, and many teams install or author more than one:
| Skill | Pairs with | What it adds |
| ----------------------------------- | -------------------------------------------------------- | --------------------------------------------------------------------------- |
| `knock-setup` | The [MCP server](/ai/mcp-server) and [CLI](/ai/cli) | Connect tooling, discover workflows, and wire triggers. |
| `knock-cli` | The [Knock CLI](/ai/cli) | How to scaffold, edit, and push resource files from your codebase. |
| `knock-notification-best-practices` | Any surface (CLI, MCP, dashboard agent) | How to write effective notifications across channels. |
| `knock-in-app-ui` | In-app SDKs and the [CLI](/ai/cli) | How to implement and debug Knock guides. |
| `knock-product-messaging-strategy` | Any surface | How to design a growth-oriented messaging system before you build. |
| `knock-lifecycle-opportunities` | Any surface | How to find activation and retention messaging opportunities in a codebase. |
| `knock-migrate-to-knock` | Migration tutorials and the [MCP server](/ai/mcp-server) | How to inventory an existing stack and map it to Knock. |
| Dashboard-authored skills | The [Knock agent](/ai/agent) in the dashboard | Team-specific conventions and account-level context. |
When an agent has both a tool surface and the right skill available, it can do more with fewer prompts: the tools give it reach into Knock, and the skill gives it the patterns to use those tools well.
## See also
- [Knock AI overview](/ai/overview). See how skills fit alongside the dashboard agent, agent function, CLI, and MCP server.
- [Knock agent](/ai/agent). The in-dashboard assistant where you can author and invoke skills directly.
- [Knock CLI](/ai/cli). The local-first agent surface that pairs with the `knock-cli` skill.
- [MCP server](/ai/mcp-server). Connect external clients and your own apps to Knock as tools.
# Workflows
Learn how to design notifications using Knock's workflow builder, then explore advanced features such as batching, delays, and more.
## Overview
Learn more about how to design and create powerful cross-channel notification workflows in Knock.
---
title: Designing workflows
description: Learn more about how to design and create powerful cross-channel notification workflows in Knock.
tags: ["steps", "workflows", "functions"]
section: Designing workflows
---
The Knock workflow builder enables you to craft notification workflows that combine functions, channels, and conditional logic to determine which of your users to notify across which channels when a given event takes place in your product.
## How the Knock notification engine works
As you start to dig into workflows, it's helpful to understand the basics of what happens in Knock when you [trigger a workflow](/send-notifications/triggering-workflows).
When Knock receives a workflow trigger (like the one below) for one of your workflows, it will produce a **workflow run** for **each recipient** you send in your workflow trigger.
```js title="A workflow trigger for three recipients"
await knock.workflows.trigger("comment-created", {
// The user who performed the action (optional)
actor: "user_0",
// The list of recipients
recipients: ["user_1", "user_2", "user_3"],
// Data to be passed to the template
data: {
page_name: "Marketing brief",
comment_body: "Hey team — can we take another look at this?",
},
});
```
In the example above we've included three recipients, so our workflow trigger will produce three separate workflow runs.
## The workflow canvas
All Knock workflows consist of three basic parts:
- A **trigger step** that starts the workflow
- **Channel steps** that send notifications to your configured channels
- **Function steps** that control the flow of the workflow and produce state for use in templates
### The trigger step
Every workflow starts with a trigger step. When you want to run a workflow, you send a trigger call to the Knock API with an `actor`, a list of `recipients`, and a `data` payload with any information you want to use in the notification templates of the workflow. (More on this in [triggering workflows](/send-notifications/triggering-workflows).) When the workflow is triggered, it creates a workflow run for each of the `recipients` passed in the trigger call.
A trigger step can optionally have [conditions](/designing-workflows/step-conditions), which determine if the workflow should execute. When the conditions on the trigger step are not met, the workflow will terminate.
### Channel steps
A channel step sends a notification to a recipient. When the workflow engine reaches a channel step, it looks for relevant channel data on the recipient. As an example, an email channel step will look for the `email` property on the recipient. If no relevant channel data for that recipient is found, the step is skipped. If channel data is found, then the step will send a notification.
Each channel has a notification template (designed by you in the Knock dashboard) which inserts the `data` from your trigger call into a [styled template](/template-editor/overview) for that step's given channel.
You can add any of the major [channel types supported by Knock](/integrations/overview#supported-providers) into your workflow. By default, we show all of our supported channel types, but you'll need to configure a provider with each channel before you can actually use them in a workflow. For more information on how to configure channels in your Knock account, see our [integration overview](/integrations/overview).
You can customize the channels displayed in the workflow builder by
configuring channel visibility
.
}
/>
### Function steps
A function is a step in a workflow that does something to the data being passed in your trigger call. You can use functions by entering the workflow builder and adding function steps onto the canvas. In the workflow builder, functions are grouped in tabs. The **Data functions** tab includes steps that update data in Knock during a workflow run.
We currently support the following functions:
- [Batch](/send-notifications/designing-workflows/batch-function) (aggregate trigger calls that have the same value for a specified batch key)
- [Branch](/send-notifications/designing-workflows/branch-function) (evaluate conditions to determine which path a workflow should take)
- [Experiment](/send-notifications/designing-workflows/experiment-function) (randomly assign recipients to percentage-based cohorts for A/B testing and experimentation)
- [Delay](/send-notifications/designing-workflows/delay-function) (wait an amount of time before proceeding to the next workflow step)
- [Wait for event](/send-notifications/designing-workflows/wait-for-event-function) (pause a workflow until a matching event is received or the wait time expires)
- [Fetch](/send-notifications/designing-workflows/fetch-function) (execute an HTTP request to fetch additional data for a workflow)
- [AI agent](/send-notifications/designing-workflows/ai-agent-function) (run a prompt on an AI model and merge the response into workflow state)
- [Throttle](/send-notifications/designing-workflows/throttle-function) (limits the number of executions of the workflow for the recipient over a window of time)
- [Trigger workflow](/send-notifications/designing-workflows/trigger-workflow-function) (execute a nested workflow with trigger data derived from parent workflow data and environment variables)
**Data functions**
- [Update user](/send-notifications/designing-workflows/update-user-function) (update a user's properties in Knock during a workflow run)
- [Update tenant](/send-notifications/designing-workflows/update-tenant-function) (update a tenant's properties in Knock during a workflow run)
- [Update object](/send-notifications/designing-workflows/update-object-function) (update an object's properties in Knock during a workflow run)
- [Update data](/send-notifications/designing-workflows/update-data-function) (update workflow data state with computed or static values)
- [Update audience](/send-notifications/designing-workflows/update-audience-function) (add or remove the current recipient from a static audience)
## Step conditions
Each workflow step can have one or more conditions that determine, at workflow execution time, if the step should execute. Conditions are one way you can add control flow logic to your notification workflows.
[Read more about step conditions](/send-notifications/designing-workflows/step-conditions).
## Function steps
## Delay function
Learn more about the delay workflow function within Knock's notification engine.
---
title: Delay function
description: Learn more about the delay workflow function within Knock's notification engine.
tags: ["steps", "delays", "wait", "functions"]
section: Designing workflows
---
A delay function does just what it sounds like: it delays the execution of the workflow for some amount of time, then proceeds to the next step. There are three types of delays we support in Knock today: "wait for fixed interval", "wait for a dynamic period", and "wait until a relative timestamp."
## Wait for a fixed interval
The "wait for fixed interval" delay type waits for an interval of time (provided by you in the workflow editor) and then proceeds to the next step.
Fixed interval delay functions are helpful for the following use cases:
- Check to see if a user's seen or read an in-app message before sending an email
- Remind a user about a pending invite they haven't accepted
## Wait for a dynamic period
You can also set the length of your delay dynamically using a variable. You can use any of the data, recipient, actor, or environment variables associated with the workflow run to set your duration.
When specifying a dynamic delay period you must provide one of the following:
- An ISO-8601 timestamp (e.g. `2022-05-04T20:34:07Z`) which must be a datetime in the future
- A duration unit (e.g `{ "unit": "seconds", "value": 30 }`)
- A window rule (e.g `{ "frequency": "daily", "hours": 9, "minutes": 30 }`)
A dynamic delay must be available to be resolved via the `key` you specify on the given schema, meaning that if you specify a key of `delayUntil` in your `data` schema, your workflow trigger data must contain either an ISO-8601 timestamp, a valid duration unit, or a valid window rule.
When the key specified is missing or resolves to an invalid value, a corresponding error will be logged on the workflow run, and the delay will be **skipped**.
Timestamp-based delays are helpful for reminders about resources in your product that need to be completed or addressed by a specific point in time. As an example, if a user has a task that's due three days from now and you want to remind them 24 hours before it's due, you can set a timestamp delay for the task's due date minus 24 hours.
#### An example timestamp
```json title="Setting a delay until timestamp"
{
"delayUntil": "2024-01-05T14:00:00Z"
}
```
You can then reference that in your delay step settings as `data.delayUntil`.
A duration will take the current time that the delay step is executing and add the duration to it to produce the delay until time. A duration object is an entity that you can set on recipients, tenants, environment variables, or in your data payload and reference on your delay step.
#### Duration properties
| Variable | Type | Description |
| -------------- | ------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------- |
| `unit` | "seconds" \| "minutes" \| "hours" \| "days" \| "weeks" | Unit of duration. |
| `value` | number | Number of seconds, minutes, hours, days, or weeks to delay the workflow. |
#### An example duration
Let's say you want to express a duration that delays for 15 minutes, here's how you structure that:
```json title="Setting a duration"
{
"delayDuration": {
"unit": "minutes",
"value": 15
}
}
```
You then reference that as `data.delayDuration` in the delay step configuration.
A window rule determines a dynamic interval for when the delay should close. It allows you to express rules like "delay until Monday at 9am".
The window rule will always be evaluated in the [recipient's timezone](/concepts/recipients#recipient-timezones) (when set) and will fall back to the account default timezone, or "Etc/UTC".
#### Window rule properties
| Variable | Type | Description |
| -------------- | ------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------- |
| `frequency` | "hourly" \| "daily" \| "weekly" \| "monthly" | The frequency at which the window rule should evaluate. |
| `days` | DaysOfWeek[], "weekdays", "weekends" (optional) | The specific days the rule is valid on. |
| `hours` | number (optional) | The hour at which the rule should evaluate. Defaults to 0. |
| `minutes` | number (optional) | The minute at which the rule should evaluate. Must be one of: 0, 5, 10, 15, 20, 25, 30, 35, 40, 45, 50, 55. Defaults to 0. |
| `day_of_month` | number (optional) | When frequency is "monthly", set this value to specify the day of the month when the rule executes. If omitted, the rule uses the day of the month on which the delay window opened and executes at the next occurrence of the configured time. |
#### Example window rule
Let's say you want to express setting a window rule for delaying until Monday at 9am, here's how you might structure that on your recipient:
```json title="Recipient delay window"
{
"delayUntil": {
"frequency": "weekly",
"days": ["mon"],
"hours": 9
}
}
```
Now you can set the delay window key to `recipient.delayUntil` to reference this window rule.
## Wait until a relative timestamp
You can use our relative delay to wait some time before or after a timestamp that you provide in your workflow payload. This computes a delay time for a fixed interval relative to a dynamic timestamp.
Relative delay functions are helpful for various scenarios, including:
- Appointment reminders: send a notification one day before an appointment time
- Follow-up reminders: send a follow-up message two hours after an event
When configuring a relative delay, you'll specify:
- A fixed delay interval (provided by you in the workflow editor)
- Whether the delay should occur before or after the dynamic timestamp
- The `key` for the dynamic timestamp (which can come from your trigger data, recipient data, or other sources)
As in the dynamic delay section above, the key specified must be available to be resolved. If the key is missing or resolves to an invalid value, a corresponding error will be logged on the workflow run, and the delay will be skipped.
## Using workflow cancellation with delays
In cases where you're waiting to see if a user will complete an action before sending a notification, you can use our [workflow cancellation API](/send-notifications/canceling-workflows) to ensure a user doesn't receive an unnecessary reminder.
If the user completes the action you were going to remind them about, cancel the workflow to keep any additional notifications from being sent.
## Frequently asked questions
Often when you're testing your Knock workflows, you'll want your delay durations to be shorter in non-production environments to aid with testing. To set per-environment delay duration you can:
- Create a new variable on the **Variables** page under the **Account** section of your account settings with a relative duration as JSON (`{ "unit": "seconds", "value": 30 }`) and a name of `delayDuration`. You can set per-environment values to specify a shorter or longer window as needed
- Set your delay duration to "Wait until a dynamic interval"
- Specify that your delay duration will come from an environment variable
- Set the key to `delayDuration`, which will resolve the delay duration from the variable you created
You can use the [workflow cancellation API](/send-notifications/canceling-workflows) to cancel a delayed workflow. You must use a unique cancellation key to cancel a previously triggered workflow run.
A workflow can be delayed for a maximum of 365 days (1 year).
Knock will ensure that your delayed workflow run will execute within ~1 - 5s of the delayed time.
We currently don't have a way to view all delayed workflow runs with pending messages. If this is a feature you need, please reach out as we'd love to hear your use case.
Yes. Recipient properties and preferences are re-read from your Knock environment each time a step executes, so a delayed run renders with the recipient data that's current when the delay ends.
[Subscription](/concepts/subscriptions) properties behave differently. Knock resolves the properties on a subscription at the point of fan-out and holds them for the life of the run, so an update you make to a subscription during a delay will not appear under `recipient.subscription` when the run resumes. See the FAQ about [subscription properties on paused workflow runs](/concepts/subscriptions#faq-subscription-properties-on-paused-runs) for more detail.
Workflow recipient runs will always reference the workflow version that was current when the run was triggered, so your changes will not be reflected in workflow runs that are already in flight. If you need to stop a delayed workflow run because you've updated your workflow, you can use the [workflow cancellation API](/send-notifications/canceling-workflows).
## Wait for event function
Learn more about the wait for event workflow function within Knock's notification engine.
---
title: Wait for event function
description: Learn more about the wait for event workflow function within Knock's notification engine.
tags:
[
"steps",
"wait",
"events",
"sources",
"messages",
"audiences",
"recipients",
"functions",
]
section: Designing workflows
---
A wait for event function pauses a workflow or broadcast until a matching event is received, or until a configured wait time expires. Use it when the next step in your workflow or broadcast should depend on something that happens after the run starts — such as a payment completing in an external system, a message being delivered, another workflow finishing for the same recipient, an audience membership change, or a recipient property update.
## How it works
When a workflow run reaches a wait for event step, Knock pauses execution and registers a durable wait for the configured event. The workflow stays paused until one of the following happens:
1. **A matching event is received.** Knock evaluates the event against your match conditions (when configured). If the event passes, Knock applies your **On match** action and resumes the workflow (or halts it, depending on your configuration).
2. **The wait time expires.** If no matching event arrives before the wait time ends, Knock applies your **After wait time** action.
While the workflow is paused, no downstream steps execute. This makes the wait for event function useful for coordinating notifications with product activity without building polling or state management in your application.
## Event types
Select an **event type** in the step settings, then configure the fields for that type.
### Integration source
Wait for an event from a connected [integration source](/integrations/sources/overview), such as Segment, Stripe, or a custom webhook source.
Configure:
- **Event.** The source event to wait for. Knock identifies the event by its event key and integration source key, which remain stable when you promote workflows between environments.
Your Knock environment must have at least one configured source that has received the event you want to wait for.
When a source event includes a `user_id`, Knock scopes matching to the workflow recipient for that run. Events without a recipient association can still match waits that are registered without recipient scoping.
Source event payload fields are available under `event.data.*`. Envelope fields such as `user_id`, `inserted_at`, and `preprocess_output` are available at the top level of `event.*`.
### Message
Wait for a [message lifecycle event](/send-notifications/message-statuses) produced by a specific [workflow](/concepts/workflows), [broadcast](/concepts/broadcasts), or [guide](/concepts/guides) for the same recipient.
Configure:
- **Source type.** The kind of message source to observe: workflow, broadcast, or guide.
- **Source.** The specific workflow, broadcast, or guide whose messages should match this wait.
- **Message event.** The lifecycle event to wait for, such as delivered, bounced, seen, read, or link clicked.
- **Channel steps.** Optional. For workflow and broadcast sources, filter to messages produced by specific channel steps. Selecting a channel step writes an `event.step_ref` match condition and satisfies the match conditions requirement. Defaults to any step. For guide sources, filter by `event.step_ref` in match conditions instead.
Available message events include: created, queued, sent, not sent, delivered, delivery attempted, undelivered, bounced, read, unread, seen, unseen, archived, unarchived, interacted, and link clicked.
Message event waits are scoped to the workflow recipient and the selected message source. Match conditions are **required** for message events.
### Workflow
Wait for a workflow lifecycle event from another workflow run for the same recipient.
Configure:
- **Workflow.** The workflow whose lifecycle events this wait should observe.
- **Workflow event.** Either **Started** or **Completed**.
Workflow event waits are scoped to the workflow recipient and the selected workflow. Match conditions are **required** for workflow events.
### Audience
Wait for a [dynamic audience](/concepts/audiences) membership change for the workflow recipient.
Configure:
- **Audience.** The dynamic audience to watch. Static audiences are not supported for wait for event steps.
- **Membership event.** Either **Enter** or **Exit**.
### Recipient
Wait for the current workflow recipient to be updated in Knock. Today, recipient waits listen for the **updated** event for that recipient (not updates for other recipients).
Recipient waits have no additional configuration fields beyond the event type. Use match conditions when you only want to resume on specific property, preference, or channel data changes.
## Configuring a wait for event step
Beyond selecting the event type and its event-specific fields, you configure the following settings for every wait for event step.
### Match conditions
Match conditions filter candidate events before the workflow resumes. Knock evaluates each candidate event against these conditions. If an event does not pass, the workflow keeps waiting until a matching event arrives or the wait time expires.
Knock already scopes waits to the workflow recipient for the run, so you do not need a recipient ID condition to match events to the current user.
| Event type | Match conditions |
| ------------------ | ---------------- |
| Integration source | Optional |
| Message | Required |
| Workflow | Required |
| Audience | Optional |
| Recipient | Optional |
You can build match conditions using the same [conditions builder](/concepts/conditions) used elsewhere in Knock. The following variable namespaces are available:
| Namespace | Description |
| ------------------- | ------------------------------------------------------------------------------- |
| `event.*` | The awaited event payload. Use this namespace for fields on the incoming event. |
| `recipient.*` | The workflow recipient. |
| `data.*` | The original workflow trigger payload. |
| `vars.*` | Environment variables. |
| `tenant.*` | The tenant associated with the workflow run. |
| Audience membership | Check whether the recipient belongs to an audience. |
| `refs.*` | Message status from preceding channel steps in the workflow run. |
The shape of `event.*` depends on the event type:
| Event type | Example `event.*` fields |
| ------------------ | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Integration source | `data.*` (source event payload, such as properties from a Segment track event), `user_id`, `inserted_at`, `preprocess_output`, `event_gid` |
| Message | `message_id`, `event_type`, `channel_id`, `channel_type`, `channel_provider`, `tenant_id`, `exec_mode`, `step_ref`, `recipient`, `inserted_at`, `source.type`, `source.key`, and event-specific `data.*` |
| Workflow | `workflow_key`, `workflow_run_id`, `recipient`, `status`, `tenant_id`, `notify_data`, `exec_mode`, `inserted_at` |
| Audience | `audience_id`, `recipient`, `transition`, `happened_at` |
| Recipient | `recipient`, `event_type`, `timestamp`, `properties`, `preferences`, `knock_traits`, `channel_data` |
### On match
Controls what happens when a matching event is received before the wait time expires:
- **Continue workflow.** Resume execution and proceed to the next step. This is the default.
- **Halt workflow.** Cancel the workflow run. Use this when the awaited event means later steps should not execute — for example, canceling a reminder workflow when a user completes the action you were going to remind them about.
### Wait time
How long Knock waits for a matching event before timing out. The dashboard default is 15 minutes. You can configure the duration in seconds, minutes, hours, days, or weeks.
A wait for event step can wait for a maximum of 30 days.
### After wait time
Controls what happens when the wait time expires before a matching event arrives:
- **Halt workflow.** Cancel the workflow run. This is the default.
- **Continue workflow.** Resume execution and proceed to the next step.
### Step conditions
Like other workflow steps, a wait for event step supports [step conditions](/designing-workflows/step-conditions) that determine whether the step executes at all when the workflow run reaches it. Step conditions are evaluated when the step runs, not when an awaited event arrives.
## Downstream step output
When a wait for event step resumes on a **Continue workflow** path, it writes output under `refs.` that downstream steps can reference:
| Property | Type | Description |
| ------------------ | ------- | ------------------------------------------------------------------------------- |
| `matched` | boolean | `true` when a matching event claimed the wait; `false` when the wait timed out. |
| `signal_variables` | object | The payload from the matched event. An empty object on timeout. |
Use `refs..matched` in a downstream [branch function](/designing-workflows/branch-function) to run different logic depending on whether the event arrived in time. Use `refs..signal_variables` to access fields from the matched event payload in conditions or templates.
```json title="Example downstream condition"
// Branch on whether the event matched before timeout
refs.wait_for_payment.matched == true
// Branch on a field from the matched integration source event payload
refs.wait_for_payment.signal_variables.data.status == "paid"
```
## Common patterns
### Wait for an external action before sending a follow-up
Trigger a workflow when a user starts a flow, add a wait for event step that listens for a completion event from an integration source (such as Segment), then send a follow-up notification only if the user does not complete the action within your wait window.
Pair this with **On match: Halt workflow** and **After wait time: Continue workflow** so the workflow proceeds to your reminder step only when the completion event does not arrive in time.
### Escalate when a message is not engaged
Send an in-app notification, then wait for a message **seen** or **read** event from that workflow. Optionally select the channel step that sent the in-app message so the wait only resumes for that step's messages. If the wait times out, continue to an email channel step. Use match conditions on `event.*` as needed to narrow which message events resume the workflow.
### Wait for a nested workflow to finish
Trigger a child workflow with a [trigger workflow function](/designing-workflows/trigger-workflow-function), then wait for that workflow's **Completed** event for the same recipient before continuing in the parent workflow.
### React to audience membership changes
Wait for a recipient to enter or exit a dynamic audience before sending a campaign or changing notification volume. Use audience event waits when membership is driven by properties rather than an explicit API action.
### Branch on event payload
After the wait resolves, use a branch step with conditions on `refs..signal_variables` to send different notifications based on data in the matched event.
## Wait for event vs. delay
Both wait for event and [delay](/designing-workflows/delay-function) functions pause a workflow, but they differ in what resumes execution:
| | Wait for event | Delay |
| ------------------------------------- | -------------------------------------------------- | -------------------------------------------- |
| Resumes when | A matching event arrives, or the wait time expires | The configured interval or timestamp elapses |
| Depends on external or Knock activity | Yes | No |
| Match conditions | Yes | No |
Use a delay when you need to wait a fixed amount of time. Use wait for event when the workflow should react to a specific event.
## Using workflow cancellation with wait for event steps
Workflow runs paused at a wait for event step can be canceled using the [workflow cancellation API](/send-notifications/canceling-workflows), the same as runs paused at a delay, batch, or fetch step. Provide a `cancellation_key` when you trigger the workflow, then call the cancel endpoint with the same key.
Canceling a paused workflow deletes the scheduled resume job and marks the durable wait as canceled. No downstream steps execute after cancellation.
## Debugging wait for event steps
You can inspect wait for event execution in the [workflow debugger](/send-notifications/debugging-workflows). For each workflow run, the debugger shows:
- Whether the workflow is still waiting for an event, or which event was received
- When the wait expires or expired
- Match condition evaluations for candidate events, including the result of each evaluation
When match conditions reject an incoming event, Knock logs a `wait_conditions_evaluated` event on the workflow run so you can see why the event did not resume the workflow.
## Frequently asked questions
Knock claims the wait for the first event that passes your match conditions.
Subsequent events for the same wait are ignored because the wait has already
been claimed.
Knock ignores events whose timestamp falls outside the wait window. If the
wait has already timed out and the workflow resumed or halted, late-arriving
events do not affect the run.
Only when waiting for an integration source event. Message, workflow,
audience, and recipient event waits use events generated inside Knock and do
not require a connected source.
When the event type is message or workflow, Knock requires at least one
match condition so the wait can narrow which events resume the run. For
message events from a workflow or broadcast source, selecting a channel step
satisfies this requirement by adding an `event.step_ref` condition.
Integration source, audience, and recipient waits can omit match conditions.
Yes. The workflow trigger type does not affect the wait for event step. The
step listens for the configured event type independently of how the workflow
was triggered.
Yes. Wait for event functions are supported in broadcasts as well as
workflows.
Yes. Select message as the event type, set the source type to workflow, and
choose the current workflow as the source. The wait matches message events
for the same recipient from that workflow.
Workflow recipient runs reference the workflow version that was current when
the run was triggered. Changes to the workflow do not affect runs that are
already in flight. Use the [workflow cancellation
API](/send-notifications/canceling-workflows) to stop a paused run after you
update the workflow.
A wait for event step can wait for a maximum of 30 days.
## Batch function
Learn more about the batch workflow function within Knock's notification engine.
---
title: Batch function
description: Learn more about the batch workflow function within Knock's notification engine.
tags: ["steps", "batch", "batched messages", "batching", "digests", "functions"]
section: Designing workflows
---
A batch function collects notifications that have to do with the same subject, so you can send fewer notifications to your users.
Batch functions are helpful when a recipient needs to be notified about a lot of activity happening at once, but doesn't need a notification for every single activity within the batch.
Commenting is a common use case. If a user leaves ten comments in a page in fifteen minutes, you don't want to send the user ten separate notifications. You want to send them one notification about the ten comments they just received.
## How batching works
Here's a step-by-step breakdown of how a batch function works:
- When a given recipient's workflow run hits a batch step, a batch is opened for an interval of time which you define (the [batch window](#setting-the-batch-window)).
- While that interval is open, the batch function aggregates any additional incoming triggers for that recipient as `activities`. If a [batch key](#selecting-a-batch-key) is provided in your batch step, the incoming triggers for that recipient will be grouped into separate batches based on the batch key.
- As subsequent workflow triggers are added to an open batch as `activities`, their underlying workflow runs are terminated.
- When the batch window interval closes, the workflow continues to the next step, with the data collected in the batch available as [variables](#using-batch-variables) in the workflow run scope. By default, that continuation uses the [latest published version](#setting-the-workflow-version-mode) of the workflow.
A batch function always captures events per `recipient`. By default, an open batch stays open across workflow versions. For more information on how updates to your workflow affect existing open batches, see [setting the workflow version mode](#setting-the-workflow-version-mode) and [updating workflows with batch steps](#updating-workflows-with-batch-steps).
As new activities are added to an open batch, their
underlying workflow runs terminate. See{" "}
debugging workflows with a batch step
{" "}
to learn how the workflow debugger links those runs together.
}
/>
## Selecting a batch key
When you configure an optional batch key, batched events are further grouped by that key. The batch key resolves to a value in your `data` payload; a configured batch key of `event_type` points to `data.event_type`. You can also use Liquid to reference [variables](/template-editor/variables) from the workflow run scope (such as the `recipient.*`, `actor.*`, or `tenant.*` namespaces) to construct a key.
You can use multiple variables when constructing a batch key. For example, setting the batch key to `{{data.eventType}}-{{actor.id}}` would batch separately per event type and actor.
Here's a helpful way to think about batching. By default the batch
function batches on a key of recipient_id. When a batch key
is provided, it batches events on a key of{" "}
concat(recipient_id, batch_key). In{" "}
pinned mode, the workflow
version is also included in the key so each published version gets its own
batch.
}
/>
As an example, in a document editing app where a recipient is receiving notifications about activity across different pages, you can provide a batch key of `page_id` and the user will receive different batched notifications about each individual page.
Using the batch function to batch new comment notifications by page.
Here's a detailed walkthrough of how this example might work in practice:
- You have a `new-comment` workflow that includes a batch step.
- You send six trigger calls to that workflow: three about `page A` and three about `page B`. The trigger calls are all for the same recipient Elmo.
- If your batch step does not have a batch key, Elmo will receive a batched notification about six activities.
- If your batch step includes a batch key of `page_id`, Elmo will receive two notifications: one for the three activities about `page A` and one for the three activities about `page B`.
## Setting the batch window
The batch window determines the length of time that the batch will be open, with the window opening from the **first** time the batch is triggered.
### Set a fixed batch window
You can set a fixed duration batch window using the "Fixed" window option in the batch step. The window accepts a duration which can be specified in seconds, minutes, hours, or days.
The batch is opened when it is first triggered for a given recipient. The batch is closed after the fixed duration of time has elapsed.
### Set a dynamic batch window using a variable
You can also set the length of your batch windows dynamically using a variable. You can use any of the data, recipient, actor, or environment variables associated with the workflow run to retrieve your dynamic batch window.
When specifying a dynamic batch window you must provide one of the following:
- An ISO-8601 timestamp (e.g. `2022-05-04T20:34:07Z`) which must be a datetime in the future
- A relative duration (e.g `{ "unit": "seconds", "value": 30 }`)
- A window rule (e.g `{ "frequency": "daily", "hours": 9, "minutes": 30 }`)
A dynamic window must be available to be resolved via the `key` you specify on the given schema, meaning that if you specify a key of `batchWindow` in your `data` schema, your workflow trigger data must contain either an ISO-8601 timestamp, a valid duration unit, or a valid window rule.
When the key specified is missing or resolves to an invalid value, a corresponding error will be logged on the workflow run, and the batch will be **skipped**.
A fixed timestamp will tell Knock to close the batch window at the exact date time you provide. It must be a valid ISO-8601 timestamp in the future.
#### An example timestamp
```json title="Setting a batch until timestamp"
{
"batchUntil": "2024-01-05T14:00:00Z"
}
```
You can then reference that in your batch step settings as `data.batchUntil`.
A duration will take the current time that the batch step is executing and add the duration to it to produce the batch window closing time. A duration object is an entity that you can set on recipients, tenants, environment variables, or in your data payload and reference on your batch window.
#### Duration properties
| Variable | Type | Description |
| -------------- | ------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------- |
| `unit` | "seconds" \| "minutes" \| "hours" \| "days" \| "weeks" | Unit of duration. |
| `value` | number | Number of seconds, minutes, hours, days, or weeks that the batch remains open. |
#### An example duration
Let's say you want to express a duration that will always close a batch window 1 day after the batch is started, here's how you structure that:
```json title="Setting a duration"
{
"batchDuration": {
"unit": "days",
"value": 1
}
}
```
You then reference that as `data.batchDuration` in the batch step configuration.
A window rule determines when the next occurrence of the batch window should be executed. It allows you to express rules like "batch until Monday at 9am", or "keep the batch window open for 2 weeks until the next Friday."
The window rule will always be evaluated in the [recipient's timezone](/concepts/recipients#recipient-timezones) (when set) and will fall back to the account default timezone, or "Etc/UTC".
#### Window rule properties
| Variable | Type | Description |
| -------------- | ------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------- |
| `frequency` | "hourly" \| "daily" \| "weekly" \| "monthly" | The frequency at which the window rule should evaluate. |
| `days` | DaysOfWeek[], "weekdays", "weekends" (optional) | The specific days the rule is valid on. |
| `hours` | number (optional) | The hour at which the rule should evaluate. Defaults to 0. |
| `minutes` | number (optional) | The minute at which the rule should evaluate. Must be one of: 0, 5, 10, 15, 20, 25, 30, 35, 40, 45, 50, 55. Defaults to 0. |
| `day_of_month` | number (optional) | When frequency is "monthly", set this value to specify the day of the month when the rule executes. If omitted, the rule uses the day of the month on which the batch window opened and executes at the next occurrence of the configured time. |
#### Example window rule
Let's say you want to express setting a window rule for batching weekly on a Monday at 9am, here's how you might structure that on your recipient:
```json title="Recipient batch window"
{
"batchWindow": {
"frequency": "weekly",
"days": ["mon"],
"hours": 9
}
}
```
And now you can set the batch window key to `recipient.batchWindow` to reference this window rule.
**Please note**: an open batch window will never be extended by a subsequent workflow trigger with a different dynamic batch window specified. Once a given batch has been opened by a workflow trigger, its window interval is immutable.
### Set a relative batch window
You can also set a batch window that will close with an offset relative to your dynamic batch window. For example, you might want to batch events up until one hour before or after an appointment.
Relative batch windows support all of the same configuration options as dynamic batch windows, but are calculated according to the additionally-configured relative offset. When the window property specified is missing or resolves to an invalid value, a corresponding error will be logged on the workflow run and the batch will be **skipped**.
### Using a sliding batch window
By default, all batch windows are fixed, where the closing of the batch window is determined by the first trigger that starts the batch. In some situations, you may wish to "extend" the batch window when a new trigger is received to recompute the closing time of the batch. This option is supported in the batch step as a "sliding window."
When a sliding window is enabled on a batch function, subsequent workflow triggers that are detected by the already-open batch window will add the configured default window duration onto the already-open batch window. Let's walk through an example:
- 🎛️ [Initial batch window: 1 minute]
- Trigger: the batch opens with a closing window of `now() + 1 min`
- ⏲️ [30 seconds pass]
- Trigger: new item added to the batch, the closing window is recomputed to be `now() + 1 min`, a total of 1 minute and 30 seconds from when the batch was opened
- ⏲️ [1 minute passes]
- The batch closes after 1 minute and 30 seconds
#### Setting a maximum batch window duration
When using a sliding batch window, you must set an extension limit for the batch. This value represents the maximum amount of time that a batch window can remain open if it is extended by subsequent workflow triggers.
This "Max window limit" option is displayed once you enable a sliding window by selecting "Extend window when new activities are received," and can be set as any duration unit.
Once configured, Knock will compute the maximum extended batch window for subsequent triggers as the time your batch was initially opened plus the maximum window duration. For example:
- 🎛️ [Initial batch window: 12 hours]
- 🎛️ [Max extension limit: 24 hours]
- Trigger: the batch opens with a closing window of `now() + 12 hrs`
- ⏲️ [6 hours pass]
- Trigger: new item added to the batch, the closing window is recomputed to be `now() + 12 hrs`, a total of 18 hours from when the batch was opened
- ⏲️ [Another 7 hours pass]
- Trigger: new item added to the batch, the closing window is recomputed to be `now() + 12 hrs`, which would be a total of 25 hours. Because this exceeds the maximum extension limit, the window is set to close 24 hours after it was opened
- ⏲️ [Another 3 hours pass]
- Trigger: new item added to the batch. The closing window is not recomputed because the maximum extension has already been reached
- ⏲️ [Another 8 hours pass]
- The batch closes after 24 hours
If you configure your maximum window with a value that is _less_ than the initial window duration, subsequent batched triggers will shorten the overall window. If this new maximum duration has already elapsed, the batch window will immediately close and the workflow run will proceed.
- 🎛️ [Initial batch window: 24 hours]
- 🎛️ [Max extension limit: 12 hours]
- Trigger: the batch opens with a closing window of `now() + 24 hrs`
- ⏲️ [23 hours pass]
- Trigger: new item added to the batch, the closing window is recomputed to be `now() + 24 hrs`, a total of 47 hours from when the batch was opened. This exceeds the configured maximum of 12 hours, so the window is set to close 12 hours after it was opened
- Because 12 hours have already elapsed, the batch window closes immediately (after 23 hours have elapsed)
To avoid confusion, we recommend always choosing a max extension limit duration that is greater than your initial batch window duration.
## Setting the maximum activity limit
Optionally, you can also set a maximum limit for the number of activities allowed to be accumulated in a given batch, at anywhere between 2 and 1000 activities.
When this option is set, your batch window will close as soon as the number of activities accumulated in the batch reaches the maximum limit set, regardless of the amount of time remaining in its fixed or sliding batch window.
## Setting the batch order
Although batches will accumulate every activity added to the batch, only ten items will be returned in `activities` once the batch step window closes. There are two options for which ten activity objects will be returned when the batch step closes:
- **The first ten (default):** The ten oldest activity objects added to the batch step will be returned.
- **The last ten:** The ten newest activity objects added to the batch will be returned.
Note that for both settings, the `activities` variable will always be sorted in chronological order (oldest to most recent).
## Immediately flushing the first item in a batch
Batch steps optionally support a mode to immediately flush the first item in a batch. This mode is useful when you want to immediately notify a user about the first item in a batch, and then accumulate additional items over a window of time.
To enable this mode, you can toggle on "Immediately flush leading item" in the "Advanced settings" section of the batch step.
When this mode is enabled, the first item for an unopened batch will "open" the batch and the usual batching rules will apply. However, unlike a normal batch, the first item will **not be included in the `activities` of the batch** and will instead continue execution past the batch step. This means that when the batch window closes later on, the workflow will proceed on the "second" item's workflow run, rather than the first run that opened the batch.
If you want to branch on whether the first item in a batch was flushed or not, you can use the `total_activities` variable to do so. When it is set to 1, you know that you're working with the first item in a batch.
if there is never a second item added to the batch, the batch will noop on
closing as there is nothing in it to execute.
}
/>
## Setting the workflow version mode
A batch step can continue on the **latest** workflow version or stay **pinned** to the version that opened the batch. New batch steps default to latest mode.
Set this in the "Advanced settings" section of the batch step with the "Continue on latest version" toggle. You can also set `workflow_version_mode` to `latest` or `pinned` when you manage the workflow through the [Management API](/developer-tools/management-api) or [CLI](/developer-tools/knock-cli).
Legacy behavior for batch steps added prior to August 20, 2026 was to
default to pinned mode. Please review{" "}
updating workflows with batch steps
{" "}
for more information on expected behavior and how to update existing batch
steps to use latest mode.
}
/>
### Latest (default)
In latest mode, an open batch stays open across [commits](/concepts/commits) and promotions. Subsequent triggers for the same recipient (and [batch key](#selecting-a-batch-key), if you set one) join that batch, even after you promote a new version of the workflow.
When the window closes, Knock continues the workflow on the latest published version that still includes this batch step with latest mode enabled. Template and step changes you committed while the batch was open are used for that continuation.
Use latest mode for digest-style batches so a new workflow version does not open a second batch or send a duplicate notification.
### Pinned
Pinned mode ties the batch to the workflow version that opened it. Committing a new version of the workflow opens a new batch for the same recipient. When a window closes, that batch continues on the version that opened it.
Pinned is an advanced option. Use it only when you need a separate batch for each workflow version. For long-running batches, a new workflow version can close two batches around the same time and send two notifications.
## Working with batches in your templates
Another important aspect of batch functions is that they generate state that can be used in your templates. Let's continue the commenting example we used above.
In this scenario, we'll want different copy in our notification for when a batch includes one item ("Jane left a comment") v. when a batch includes more than one item ("Jane left _n_ comments").
We can address use cases like this by referencing the `total_activities` variable within our workflow.
Here's an example of a message template that uses this variable to determine what type of copy to use:
```markdown
{% if total_activities > 1 %}
{{ actor.name}} left {{ total_activities }} comments on {{ page_name }}
{% else %}
{{ actor.name}} left a comment on {{ page_name }}.
{% endif %}
```
Here's a list of the variables that you can use to work with batch-related state.
- `total_activities`. The number of activities included within the batch. (An example: In the notification "Dennis Nedry left 8 comments for you", the `total_activities` count equals eight).
- `total_actors`. The number of unique actors that triggered activities included within the batch. (An example: In the notification "Dennis Nedry and two others left comments for you", the `total_actors` count equals three, Dennis plus the two others you mentioned in the notification).
- `activities`. A list of up to ten of the activity objects included within the batch, where each activity equals the state sent across in your trigger call. The `activities` variable lists the _first_ or _last_ ten activity objects added to the batch (configurable by setting the [batch order](#setting-the-batch-order)). Each activity includes any `data` properties you sent along in the trigger call, as well as any user properties for your actor and recipient(s). You can use the activities variable to create templates like this:
```
{% for activity in activities %}
{{ activity.actor.name }} commented on {{ activity.pageName }} with:
{{ activity.content }}
{% endfor %}
```
- `actors`. A list of up to ten of the unique actors included within the batch, where each actor is a user object with the properties available on your Knock user schema. The `actors` variable lists the _first_ or _last_ ten actors added to the batch.
### Setting the batch render limit (beyond 10)
The render limit setting for batch activities and actors is only available
on our{" "}
Enterprise plan.
}
/>
By default, up to ten items will be returned in `activities` and `actors` variables inside your templates after the batch window closes.
On the Enterprise plan, you can configure the maximum number of `activities` and `actors` to be rendered in your templates beyond the default limit of 10, to any number between 2 and 100.
### The `data` payload
When a workflow includes a batch step, the `data` payload that is available to your message templates after the batch window closes (and via the API, wherever trigger data is returned alongside a message or used as a [filter](/api-reference/overview/trigger-data-filtering)) will be combined and truncated according to the following rules:
- Nested data structures (objects and arrays) are removed. The available `data` will be a JSON object with a single level of key-value pairs.
- Supported values are the JSON scalars string, number, boolean, and `null`.
- String values are limited to 256 characters in length. Strings that exceed this limit are truncated to the maximum.
- When payloads are combined, they are merged in the order in which they are received. Any keys that are used in multiple trigger calls will have the value of the most-recent trigger's `data` payload.
For this reason, we recommend referencing the `activities` array to access data from a specific trigger event when your workflow includes a batch step.
## Updating workflows with batch steps
What happens when you [commit](/concepts/commits) and promote a new version of a workflow with an open batch depends on the [workflow version mode](#setting-the-workflow-version-mode) of your batch step.
In **latest** mode (the default for new batch steps), the open batch stays open. Subsequent triggers join it, and when the window closes Knock continues the workflow on the latest published version. Template and step changes you committed while the batch was open are used for that continuation.
In **pinned** mode, the batch stays tied to the workflow version that opened it. Promoting an updated version (including a change to update a batch step's workflow version mode from pinned to latest) opens a new batch the next time the workflow is triggered. Existing batches remain open until their duration elapses, even though they will not accumulate additional events from the new version. For long-running batches that always close at a specific interval (like "every Monday at 9:00 a.m."), that can send two notifications in close succession.
To prevent a workflow from sending notifications or accumulating additional events while you work on an update, you can set the workflow's [status](/concepts/workflows#workflow-status) to `Inactive`. While a workflow remains in the inactive state, new events will not be batched and any currently-open batch windows that close will not proceed to the next workflow step; their runs will instead be terminated and no additional messages will be generated.
- A workflow's status is an environment-specific setting. Be sure to target your production environment if you decide to use this control.
- Toggling a workflow's status does not automatically cancel any currently-open batch windows. Your workflow should remain in the `Inactive` state until all open batch windows have closed, otherwise your batches will proceed as normal once their window durations have elapsed.
- While the workflow is `Inactive` in Production, promote your changes. After your open batch windows close and outstanding workflows have terminated, setting the workflow back to `Active` will begin batching incoming events again and these workflow runs will proceed with the newly-published workflow version.
## Using workflow cancellation with batches
If you want to remove an item from a batch (example: a user deletes a comment), you can use our [workflow cancellation API](/send-notifications/canceling-workflows) to cancel a batched item, thereby removing it from the batch.
If a batch is empty when its window closes because all of its `activities` were canceled, no subsequent channel steps in the workflow will generate messages.
Once a batch window has been opened, it will remain open until its full
duration has elapsed. Any workflow cancellation will remove the specific
individual workflow run that it references from the batch.
Because of this behavior, it's important to remember that
canceling a workflow run that opened a batch window will never close the
batch window itself.
Any subsequent triggers to that recipient/workflow key combination
will add activities to the open batch, and those activities will proceed when
the batch window closes if their respective workflow runs are not also canceled.
See the FAQs below for a workaround to close an open batch window.
}
/>
### Canceling runs after a batch closes
If you need to cancel an in-flight workflow run after its batch window has closed and it has proceeded to the next workflow step, you must use the `cancellation_key` from the workflow trigger which originally opened the batch window. The original key can be used to cancel the run even if it was previously used to remove the initial `activity` from the batch while it was still open.
After a batch window has closed, specific `activities` are no longer eligible to be removed from a batch or otherwise canceled. Because each activity's individual workflow run is terminated when it is added to an open batch, any `cancellation_key` which is not associated with the original workflow run will have no effect.
Keep this behavior in mind when deciding whether to include delay steps after a batch step in your workflows.
## Frequently asked questions
Often when you're testing your Knock workflows, you'll want your batch windows to be shorter in non-production environments to aid with testing. To set per-environment batch windows you can:
- Create a new variable on the **Variables** page under the **Account** section of your account settings with a relative duration as JSON (`{ "unit": "seconds", "value": 30 }`) and a name of `batchWindow`. You can set per-environment values to specify a shorter or longer window as needed
- Set your batch window to "Batch for a dynamic interval"
- Specify that your batch window will come from an environment variable
- Set the key to be `batchWindow`, which will resolve the batch window from the variable you created
If the batch step uses latest mode (the default for new steps), the open batch stays open. New triggers join it, and when the window closes the workflow continues on the latest published version.
If the batch step uses pinned mode, committing a new workflow version opens a new batch. The original batch still closes on its own window and continues on the version that opened it.
Pinned mode is an advanced option. Use it only when you want a batch that is tied to a specific published workflow version, so later commits open a separate batch instead of joining an open batch.
For digest and aggregation use cases, keep latest mode enabled.
Right now we don't offer a way to close a batch from a workflow trigger. One workaround is to use a [sliding batch window](/designing-workflows/batch-function#using-a-sliding-batch-window) and then set the max extension window to be a very small duration (i.e. 1 second), meaning that the batch will immediately close when a subsequent trigger occurs.
You can use the [workflow cancellation API](/send-notifications/canceling-workflows) to remove an item that has been accumulated into an active batch. If all items have been removed from the batch when its window closes, any channel steps proceeding will be skipped.
A batch can support an unbounded number of items per recipient, although we will only ever return either the first 10 or last 10 items to be rendered in your template. On Enterprise plan, you can configure to include up to 100 via the [render limit setting](/designing-workflows/batch-function#setting-the-batch-render-limit-beyond-10).
We will by default expose at most 10 activities to your template rendered in your batch (available under the `activities` variable). The `total_activities` will always include the total amount of bundled
activities in the batch. On Enterprise plan, you can configure to include up to 100 via the [render limit setting](/designing-workflows/batch-function#setting-the-batch-render-limit-beyond-10).
You can use the "Batch order" setting on the batch step to set if you want the first 10 items (the default) or the last 10 items added to the batch.
You can use the `activities` property in your template to access the items included in the batch. Each `activity` will include any `data` sent along with the workflow trigger that was batched.
Yes, but keep the following in mind:
- Batch steps should never be used in sequence. Because the workflow runs underlying individual `activities` are terminated when they are added to a batch, subsequent batch steps will only ever collect a single `activity` and will not serve a useful purpose.
- While you can use multiple batch steps in parallel (for example, in separate workflow branches), events that take different branch paths can still be batched together unless each step is uniquely identified. The default behavior differs depending on your batch step's [workflow version mode](#setting-the-workflow-version-mode): in latest mode, Knock includes the batch step in the batch key, so parallel batch steps open separate batches. In pinned mode, the default key is `concat(recipient_id, workflow_version_id)`, which is not unique per batch step. To open separate batches for each parallel pinned batch step, configure a unique [batch key](#selecting-a-batch-key) for each step.
Not exactly. The batch function is a powerful tool for aggregating multiple similar events into a single notification. However, you may find that its inherent characteristics (such as [render limits](#setting-the-batch-render-limit-beyond-10), needing to manage [cancellation](#using-workflow-cancellation-with-batches) of batched items that should no longer be included, etc.) mean that it isn't well-suited for powering regular daily or weekly digests that summarize a user's account activity, where notifications should always send at specific intervals and you need to have granular control over the events that are included in those messages. In those cases, referencing your system as the source of truth for the events that should be included in the digest at send time is often a better approach.
See our tutorial on [powering recurring digests with Knock](/tutorials/building-recurring-digests) for more guidance on the pattern that we recommend. If you aren't sure about the best approach for your use case, please [reach out to our support team](mailto:support@knock.app?subject=Building%20recurring%20digests%20with%20Knock) and we'll be happy to help.
No, this is not currently supported. If this is a blocker for your use case, please [get in touch with us](mailto:support@knock.app?subject=Per%20recipient%20batch%20windows).
When messages are generated from a batch step, the workflow trigger call data for the first (or last) 10 activities of the batch will be combined into one single entity at batch closing time.
You will be able to filter messages or feed items using the `trigger_data` parameter of our API, which will filter the results to only the items whose workflow trigger call's data
contain the given `trigger_data` value.
This means that using the `trigger_data` parameter will only return items for which the combined workflow trigger call data of the
first (or last) 10 activities contain the value used on the `trigger_data` parameter. If you are using a value for the `trigger_data` parameter which is not included in the
first (or last) 10 activities of an item, then the item will be returned.
To understand how the combined trigger call data will look like, let's take a look at the following example:
Let's consider the case where a message was generated after a batch step with 2 batched activities closes.
The first activity was generated by workflow trigger call with the following trigger data: `{page: "A"}`.
The second activity was generated by a workflow trigger with the following trigger data: `{page: "B"}`.
When the batch closes, the trigger data of both activities will be merged into a single object that will contain the `{page: "B"}`.
If we try to filter messages or feed items using the `trigger_data` filter with value`{page: "A"}`, the message in the example won't be returned.
Yes, if you use the [sliding batch window](#using-a-sliding-batch-window) option then the batch window can always be extended past its original setting. When combined with a dynamic batch window from a variable, this allows you to control exactly when a specific batch window should close.
Yes, you can optionally set the [maximum activity limit](#setting-the-maximum-activity-limit) to conditionally close the batch window based on the number of items contained in the batch.
When a workflow includes a batch step, only the attachment(s) from the activity that opened the batch window are sent with subsquent email messages. Attachments from later `activities` in the batch are not included. To send a single email that includes an attachment for every batched `activity`, use a [fetch step](/designing-workflows/fetch-function) after your batch step to collect them. See [sending attachments with batched workflows](/integrations/email/attachments#sending-attachments-with-batched-workflows) for the full workaround.
We cannot guarantee the order of requests made within quick succession (< 2s) and the order they appear in the batch. If you need a guaranteed order, then you will need to enqueue requests with latency in your system.
## Branch function
Learn more about the branch workflow function within Knock's notification engine.
---
title: Branch function
description: Learn more about the branch workflow function within Knock's notification engine.
tags:
[
"steps",
"branch",
"switch",
"conditions",
"conditional",
"if else",
"branching",
]
section: Designing workflows
---
The branch function allows you to execute discrete branches of logic within your workflows using our powerful [conditions builder](/concepts/conditions) to specify the criteria for when a branch should execute.
You can think about the branch function in Knock as an `if/else` step, with the ability to add multiple `else if` clauses. Each branch has access to the full [workflow run scope](/concepts/conditions#condition-types) to evaluate conditions. Knock will execute the first branch whose conditions evaluate to `true`.
## Adding conditions to branches
Each non-default branch must have at least one condition for the branch function to be valid. Conditions are added through the conditions builder, which allows you to compose conditions via `and` or `or` boolean operators. You can build conditions for branches that contain any of the types called out in the [conditions documentation](/concepts/conditions#condition-types), including access to any messages previously generated within the workflow run.
## The default branch
For each branch step, a default branch must always exist, although the default branch does not need to contain any steps. When none of the preceding branches evaluate to `true`, the default branch is executed.
## Terminating branches
Each branch in a branch function can optionally terminate the workflow. This can be useful to ensure that for certain cases you don't want the workflow to continue executing.
You can toggle the ability to terminate the branch by checking the "Exit the workflow at the end of the branch" under the conditions section.
## Managing branches
Branches within your branch function can be:
- Renamed for clarity to give a visual indicator of when the branch executes
- Re-ordered to change the execution order
- Deleted, removing all steps inside of the branch
the default branch cannot be deleted or re-ordered.}
/>
## Debugging branches
You can debug branch execution in the [workflow debugger](/send-notifications/debugging-workflows). During a workflow run for a workflow with branches, we'll highlight the specific branch paths that were executed to help you debug. We'll also highlight the conditions that led to why a particular branch was executed.
## Frequently asked questions
Yes, absolutely. You can nest delays, throttles, batches, and other branch
steps inside of branches as well.
The maximum depth for branches is set at 5. If you have needs that go beyond
this, please reach out to discuss.
The maximum number is currently 10 branches, including the default,
per-branch function.
No, you cannot have step conditions on the branch step.
## Experiment function
Learn more about the experiment workflow function within Knock's notification engine.
---
title: Experiment function
description: Learn more about the experiment workflow function within Knock's notification engine.
metaDescription: Learn how you can use the experiment workflow function to create randomized cohorts for A/B testing and general experimentation.
tags:
[
"steps",
"random cohort",
"cohort",
"branch",
"A/B test",
"split test",
"experiment",
"percentage",
"functions",
]
section: Designing workflows
---
The experiment function enables you to split recipients into randomized cohorts within your workflows, routing each recipient down a specific branch based on a percentage-based distribution. This is useful for A/B testing notification content, gradually rolling out new notification strategies, or running experiments across your recipient base.
## How it works
Each cohort in an experiment has a percentage weight, and those weights divide a scale from 0 to 100 into ranges. When a workflow run reaches an experiment step, Knock assigns the recipient to a cohort using the following process:
1. **Cohort key.** Knock hashes the value of the cohort key to assign the recipient a spot on the 0 to 100 scale. The assigned spot is specific to each experiment step, so a recipient's cohort assignment in one experiment has no bearing on their assignment in another.
2. **Percentage distribution.** Knock reads the recipient's assigned spot on the scale against the experiment's configured cohort ranges to identify the recipient's cohort. For example, in a 30/70 split, recipients assigned a spot below 30 belong to the first cohort and everyone else goes to the second. Hashing the same cohort key always produces the same result, so a recipient is assigned to the same cohort every time the workflow runs.
3. **Branch execution.** Once assigned to a cohort, the recipient proceeds through the steps defined in their cohort's branch.
## Configuring experiments
A new experiment step starts with two evenly-distributed cohorts. You can add additional cohorts, adjust the percentage distribution between them, and set a cohort key to group similar recipients together.
- **Cohort key.** A cohort key is used to determine a recipient's cohort assignment when your experiment step runs. Configuring one is optional; by default, Knock uses `recipient.id` as the cohort key. Map it to a custom value using the [variables](/template-editor/variables) available to a workflow run.
- **Percentage weights.** Set the percentage for each cohort to control the distribution of recipients. The total across all cohorts must equal 100%.
When a custom cohort key is configured, it must be available to every
workflow run. If the configured key has no value when a workflow run is
processed, the experiment step does not fall back to using the default{" "}
recipient.id key. Instead, the step errors with{" "}
cohort_key_missing and the workflow run terminates, so none
of the steps that follow it will run. If your cohort key comes from your
trigger data or recipient properties, ensure that every run of the
workflow has access to that property. Read more about{" "}
selecting a cohort key below.
}
/>
### Grouping your recipients
The experiment function randomly assigns recipients to cohorts person-by-person. If you'd like to group recipients together by a shared property to ensure that similar users receive the same messaging, you can configure a custom cohort key.
For example, a key of `tenant.id` groups recipients by [tenant](/multi-tenancy/overview). This guarantees that recipients under a given account receive the same messaging as their teammates. A property such as `recipient.role` means that everyone with the same role will receive the same messaging.
### Selecting a cohort key
A cohort key can be configured as one of the following:
- **A path that references a workflow variable.** A key of `data.account_id` uses the `account_id` property you send in the `data` payload of your workflow trigger. You can also reference other properties like `tenant.id`, `actor.id`, or an [environment variable](/concepts/variables) under the `vars.*` namespace.
- **A Liquid expression.** A key such as `{{ tenant.id }}-{{ data.order_id }}` combines several variables into one key. Knock uses the expression's resolved value as the cohort key.
Keep in mind that when a Liquid expression references data that isn't available, it evaluates as an empty string (`""`) instead of a missing value, so the workflow run continues. Every recipient with missing data will end up with the same empty value for their cohort key, which assigns all of them to the same cohort and skews your results. If you use a Liquid expression for your cohort key, confirm that the data behind it is always present.
## Use cases
The experiment function is well-suited for:
### A/B testing
Test different notification templates, copy, or channels to see which performs better. For example, split recipients 50/50 between two email templates to measure engagement.
### Gradual rollouts
Roll out a new notification strategy to a small percentage of recipients before expanding to all users.
### Random cohort experimentation
Run multi-variant experiments by splitting recipients across three or more cohorts with different notification flows.
### Holdout testing
Test whether or not a particular message adds lift to your conversion goals. This type of test is a variation of A/B testing where one cohort receives a message and the other cohort does not. It's helpful in determining if a message is useful.
## Nesting experiment steps
Experiment steps can be nested inside other experiment steps, regular branches, or any other workflow function. This enables you to create more complex experimental setups, such as splitting recipients into cohorts and then further splitting within each cohort.
## Analytics
We're making changes to the analytics page to provide better insight into
experiment step performance. Stay tuned for updates.
}
/>
## Debugging experiment steps
You can debug experiment step execution in the [workflow debugger](/send-notifications/debugging-workflows). During a workflow run, the debugger shows which cohort was chosen for each recipient, including the cohort key value used for assignment and the percentage distribution across cohorts.
A `cohort_key_missing` error in the debugger indicates that the cohort key had no value for the current workflow run, so the experiment step terminated and the workflow run stopped. When this occurs, check to make sure that the cohort key maps to a variable that is always present for the recipients of your workflow.
## Frequently asked questions
Yes. The same cohort key value will always be assigned to the same cohort
for a given step, so a recipient will consistently land in the same branch
across multiple workflow runs.
No. The experiment step assigns recipients to cohorts based on the cohort
key and percentage distribution. This means that recipients with a shared
cohort key value will always be grouped together in the same cohort, but you
can't guarantee which specific cohort that will be. For use cases where you
need to route a recipient on a specific path through a workflow based on
conditions that you define, you can use the [branch
function](/designing-workflows/branch-function) instead.
Yes, you can update the percentage distribution at any time. Note that
changing the distribution may cause some recipients to shift to a different
cohort on subsequent workflow runs.
A cohort set to 0% will not receive any recipients. This can be useful when
you want to temporarily disable a branch without removing it from the
workflow.
No. Each experiment step splits its recipients on its own, so a recipient
who lands in a given cohort for one step is not guaranteed to land in the
same cohort for a different step.
Yes. You can nest delays, throttles, batches, branch steps, and other
functions inside of experiment steps.
The maximum number of cohorts per experiment step is 10.
The maximum depth for experiment steps is set at 5. If you have needs that
go beyond this, please reach out to discuss.
Yes, experiment steps can be used in both workflows and broadcasts.
## Fetch function
Learn more about the fetch workflow function within Knock's notification engine.
---
title: Fetch function
description: Learn more about the fetch workflow function within Knock's notification engine.
tags: ["steps", "fetch", "request", "http", "functions"]
section: Designing workflows
---
A fetch function executes an HTTP request as a step in a workflow. Any data returned to a fetch function is merged into the original trigger `data` provided on workflow trigger and made available to all subsequent steps in the workflow.
With the fetch function, you can acquire additional data for your channel step templates that may not be immediately available when you first trigger a workflow. A common case is combining a fetch function with a [batch function](/send-notifications/designing-workflows/batch-function) to retrieve trigger data for a group of activities after a batch window has closed. You can also use the fetch function to trigger side effects in your systems as Knock processes your workflow.
## Building a request
As with channel steps, you use the Knock template editor to configure the shape of your request. For each fetch step, you can edit the following attributes:
- **Request method** - You can select one of GET (default), POST, PUT, DELETE, or PATCH.
- **URL** - A valid HTTP URL.
- **Headers** - Any headers Knock should include in the request. You manage these via a key-value editor, with the key being the header name and the value being the header value.
- **Query parameters** - Any query parameters to encode into the URL. You also manage these via a key-value editor.
- **Request body** - When building a POST or PUT request, you can build a request body to include in the request. Knock will always encode the request body as JSON.
Using the request template editor to configure a fetch function.
Aside from the request method selector, each of the above fields is a Liquid-compatible input. This means you can use Liquid variables and control flow to inject variable data, access Knock-controlled workflow state attributes (e.g., `recipient`), and dynamically shape the request per workflow run.
See the [Knock template editor reference](/template-editor/overview) for detailed information on working with Liquid templates in Knock.
## Request execution
When executing the request for a fetch function, Knock expects the following from your service:
- The response to the request is one of: `200 OK`, `201 Created`, or `204 No Content`.
- If the request response contains data, it's encoded as JSON and can be decoded into a map/dictionary/hash.
- The response to the request takes no longer than 15 seconds for Knock to receive.
### Merging data
When the response sent to Knock for a fetch function request contains JSON data, Knock will merge the decoded result into the `data` you originally passed to [the workflow trigger call](/send-notifications/triggering-workflows). Knock uses a shallow-merge strategy here where:
- Data from the request overwrites the original workflow run data.
- Top-level attributes are merged, and nested attributes are completely overwritten.
_The merged data result from a fetch function step then becomes the global trigger data for all subsequent steps in the workflow run._
The example below illustrates how this could look in practice.
```json title="Example response data merge for fetch function steps"
// Original trigger data
{
"foo": "bar",
"metadata": {
"count": 1
}
}
// Fetch function response data
{
"biz": "baz",
"metadata": {
"query_count": 1
}
}
// Merge result
{
"foo": "bar",
"biz": "baz",
"metadata": {
"query_count": 1
}
}
```
### Specifying the Response Path
You can specify where in the trigger data the response from the fetch step should be placed. To do so, click on "Manage Settings" from the fetch step within your workflow template editor. From there, you can specify the response path.
The response path can be any string. To create nested keys within the trigger data, use dot (`.`) notation. For example, specifying `foo.bar` will place the response under the `bar` key within the `foo` object.
### Error handling
Knock will automatically retry request execution for a fetch function following certain types of errors. The first retry will be delayed by 30 seconds, and the second by 60 seconds. These retryable errors are:
- **Server errors** - Any `5xx` level HTTP error code.
- **Rate limiting** - Any `429` HTTP error code.
- **Request timeouts** - This is any fetch function request from Knock that does not receive a completed response within the 15 second limit.
All other errors or unexpected responses are immediately fatal. These include:
- Any other HTTP response code.
- Some issue with the structure of the request, such as an invalid URL.
- Any issue JSON-encoding a request body.
- Response data that cannot be JSON-decoded as expected.
After two failed retries for a retryable error or any non-retryable error, Knock will mark the fetch function step as a failure and halt your workflow run.
## Testing fetch functions
As you develop, you can execute test runs of your fetch step from right within the template editor. This should look and feel similar to executing test runs of your workflows, but here Knock will execute just your fetch step, ignoring any other steps that may exist before or after.
To run a fetch step test:
1. Click the button that sits to the right of the URL field in the template editor. This should open the Knock test runner modal.
2. Specify the appropriate trigger parameters (actor, recipient, trigger data, and tenant) for the test run. **NOTE:** If your fetch step expects data from a preceding batch step or fetch step, you'll need to explicitly include it here in the "Data" field. Since Knock will test this step in isolation, it cannot know what preceding data may be present when the full workflow runs.
3. Click the "Run test" button in the modal. The modal will close and the test console should display a loading state as Knock executes the test.
4. When the test run has completed, Knock will load the result into the test console for your review. You can then use use the "Request" and "Response" buttons to toggle between the two views in the test console. The "Response" section will show any data returned by the request that would be made accessible to subsequent steps in your workflow.
**When running fetch step tests, Knock will not retry a failed request on any error.** For the retryable errors [outlined above](#error-handling), Knock will indicate in the test console result that they would be retried during a full workflow run.
## Debugging fetch functions
You can use the [workflow run logs](/send-notifications/debugging-workflows) to debug your fetch function steps. For each fetch function, you can expect to see in the logs:
- The request URL (with encoded query parameters), headers, and body as sent by Knock.
- The duration of the request (in milliseconds).
- The response headers and body data.
In the workflow run overview, you'll also see any data that Knock successfully received from your fetch function steps and merged into your workflow run state.
Viewing log details for a successful fetch function step.
If the request encounters an error, you can also expect to see details about the error in the logs. And finally, if the fetch function retries the request on a retryable error, you can expect to see details enumerated for each request attempt.
Viewing log details for an unsuccessful fetch function step.
See the [documentation on debugging workflows](/send-notifications/debugging-workflows) for more details about workflow debugging and run logs.
## Securing fetch requests
Adding security to your fetch requests guards your endpoint from the outside world. There are currently two options to do this within Knock: using authentication headers, or adding request signing.
### Adding authentication via headers
One option for adding authentication is to use a **shared secret** between Knock and your service's endpoint that you inject into the headers of the request. You can use our [secret variables](/concepts/variables#setting-secret-variables) to create and store this secret within Knock, ensuring that it can be unique per environment and also obfuscated within the dashboard across all usage.
Variables can be accessed under the `vars` namespace in liquid. To add a secret into a header you use the syntax `{{ vars.your_variable_name }}` in the header value field.
### Adding request signing
Another option is to enable **request signing**, which will sign the request against a signing key that Knock generates and that can be used to guarantee that the request is coming from Knock.
You can enable request signing for the fetch function by going to the "Manage settings" modal in the top right corner when editing the request template. Once you enable request signing, Knock will generate a signing key that will be used to sign the request. This same key can then be used within your application to verify the request came from Knock via a signature added to the request as a `x-knock-signature` header.
**Verifying the signature**
The signature is generated with an HMAC using the SHA256 algorithm and, before being encoded, is comprised of the timestamp and the stringified JSON payload of the request. We encode `"timestamp in numerical form"."stringified payload"` as the signature of the request.
The `x-knock-signature` header is a string comprised of the timestamp used in the encoding and the encoded value above. It will look like this: `t=timestamp,s=encoded-signature`
To test that the payload sent has not been compromised, you can recreate the signature using the shared secret key and compare to the one sent in the header.
1. Split the `x-knock-signature` on the comma (",") and extract the values of timestamp and signature.
2. Construct the value of the signature by concatenating:
- The timestamp (as a string)
- The character `.`
- The stringified JSON payload
3. Generate the signature with an HMAC and SHA256 algorithm using the signing key from the fetch function.
4. Compare your generated signature with the one extracted in step one; they should match exactly. If the timestamp is more than five minutes old compared to the current time, you may decide you want to reject the payload for additional security.
## Reusable fetch functions
### An overview
Knock allows you to create and save request configurations so that your team can reuse them as instances across multiple workflows. Updates to these requests cascade down to their instances, making it possible to centrally manage configurations. Reusable requests are [a versionable resource](/concepts/commits) in Knock.
### Creating a reusable request
To create a reusable request, navigate to the **Reusable requests** page in the Knock dashboard from the main sidebar. Then, click the "Create reusable request" button. After creation, this will take you to the function editor where you can specify the details of your function.
Once the request is created, save and commit the configuration.
Optionally, you can define **request inputs** for the reusable request so each workflow instance can supply its own structured values while sharing the same HTTP configuration. See [Define inputs](#define-inputs) later on this page.
Creating a reusable request in the dashboard editor.
### Using a reusable request
To use a reusable request in a workflow, first navigate to the workflow where you'd like to use it. Then, create a fetch step by selecting it in the step selection menu.
Within the step panel, you can select the "Apply template" button to select which reusable request to inherit the details of.
Once selected, **the workflow's fetch step will be in an uneditable state** with the details of the reusable request applied.
Reusable request applied to a fetch step.
### Define inputs
Reusable requests can declare an **input schema** so team members know what parameters are available to them when using the request in a workflow.
#### Input schema
On the reusable request, **input schema** is a JSON Schema object that describes the allowed input properties (types, required fields, default values, and so on).
To define a schema, navigate to the reusable request editor and click "Define schema" on the left side.
#### Workflow usage
When a schema is present, the dashboard will render structured input fields on linked fetch steps inside the workflow editor. These input fields support Liquid syntax and are unique per workflow run, so they can target all available variable fields like `recipient`, `data`, `actor`, and `vars`.
#### Preview inputs on the reusable request
On the reusable request itself you can set **preview inputs**. These values are used when you preview or test the reusable request in isolation from a workflow.
#### Using values in the request template
Knock resolves values for the fetch step and merges them into the Liquid scope for that step under **`inputs`**. Reference them in the URL, headers, query parameters, or body like any other variable—for example `{{ inputs.order_id }}` alongside `{{ recipient.id }}` or fields from trigger `data`.
### Making changes to a reusable request
If you need to make changes to the request, it's recommended to edit the underlying request itself via the "Reusable requests" page, that way changes will apply to all instances of the request.
However, if you need to make changes to a single fetch step request, you can click the "Detach instance" button from the dropdown to remove the reusable request usage, and enable an editable state.
### Versioning
Reusable requests are environment-specific, so you can safely edit a request in one environment without affecting production workflows. To use a request in a different environment, make sure the request is committed and promoted to the environment you want to use it in.
Read more about [versioning in Knock here](/concepts/commits).
## Agent function
Learn how to use the agent workflow function to enrich data and personalize messaging in Knock workflows.
---
title: Agent function
description: Learn how to use the agent workflow function to enrich data and personalize messaging in Knock workflows.
tags: ["steps", "AI", "agent", "LLM", "functions", "personalization"]
section: Designing workflows
---
The agent function runs a prompt on an AI model of your choice and makes the response available in your workflow state. You can use it to enrich recipient data, personalize messaging, and bring AI-powered context into your messaging flows.
Common use cases include:
- **Enriching recipient data.** Use user and tenant properties (such as domain) to understand a recipient's market, use cases, and target persona.
- **Personalizing messaging.** Bring that context into your [channel step templates](/template-editor/overview) to drive higher conversion rates.
- **Summarizing batch content.** Distill heterogeneous actions into a concise summary that reduces noise in digest notifications.
## How it works
When a workflow run reaches an agent step, Knock:
1. Renders your prompt with the current [workflow run scope](/concepts/conditions#condition-types) (recipient, actor, tenant, data, etc.).
2. Sends the prompt to the AI model you've selected.
3. Adds the response to the workflow run data.
The response is stored as `data.`. You can reference this data in subsequent steps and templates.
## Configuring an agent step
### Selecting a model
Choose the AI model from the dropdown in the step configuration. The model you select affects both the quality of responses and the [credit cost](#credits-and-billing) per step execution.
Generally we recommend using a faster, lightweight model for quick tasks (e.g. Haiku 4.5) and a more powerful model (e.g. Sonnet 4.5) for complex tasks.
### Writing the prompt
The prompt field accepts [Liquid](/template-editor/reference-liquid-helpers) syntax, so you can inject variable data from the workflow run scope. For example:
```liquid title="Example prompt with context"
## Goal
Determine a single company’s customer segments and ideal customer profile.
Use the company’s official website and the official LinkedIn company page.
Cross-validate claims and prefer primary sources.
The actual variables to be used are defined in the Inputs section below.
## Inputs
Company domain: {{ tenant.companyDomain }}
Company name: {{ tenant.companyName }}
## Process
Use the company domain and name to find the company’s official website and LinkedIn company page.
```
You can reference:
- `recipient` — The workflow run recipient.
- `tenant` — The tenant (i.e. company, organization, workspace) associated with the workflow run.
- `data` — The trigger payload passed to the workflow.
- `actor` — The user or system that triggered the workflow.
- `vars` — Your [environment variables](/concepts/variables).
See the [Knock template editor reference](/template-editor/overview) for more on working with Liquid in Knock.
### Response format
By default, the agent returns a single string response available as `data..text`.
You can set the response format to **JSON** when you need structured output for use in templates or [branch steps](/designing-workflows/branch-function). When using JSON format, you must supply a JSON schema for the shape of the data that you'd like the agent to fill in.
```json title="Example JSON schema"
{
"type": "object",
"properties": {
"customer_segments": {
"type": "array",
"description": "The customer segments the company belongs to. Specify up to 3 segments."
},
"industry": {
"type": "string",
"description": "The industry the company operates in"
}
},
"required": ["customer_segments", "ideal_customer_profile"]
}
```
### Web search
Web search is currently only supported for Anthropic models.}
/>
When **web search** is enabled, the agent can use a browser to crawl pages and gather information. This is useful for enriching data based on a recipient's domain or website amongst other research tasks.
Web search increases the credit cost of each step execution.
## Testing agent steps
You can run test executions of your agent step from the workflow editor. Test runs **do not consume credits**.
1. Open the agent step in the workflow editor.
2. Click the test button next to the prompt field.
3. Specify the trigger parameters (actor, recipient, trigger data, tenant) for the test run.
4. Click **Run test**.
The test runner executes only the agent step in isolation. If your step expects data from a preceding step (such as a batch or fetch), include that data in the **Data** field when running the test.
## Credits and billing
Agent function executions consume **agent credits**. Credits are used when the step successfully runs in a workflow. Test runs do not consume credits.
The credit cost per execution depends on:
- **Model.** Each model has a different credit cost per run.
- **Web search.** Adds credits per execution.
- **Input/output tokens.** The number of tokens in the prompt and response.
The credit cost you're charged will either be the minimum cost of the model (and web search, if enabled) or the actual cost of the input/output tokens, whichever is greater.
### Managing credits
- **Included credits.** Your plan includes a set amount of credits per billing period. Credits do not roll over.
- **Purchasing credits.** When you need more, go to the **Billing** page in your account settings to purchase additional credits.
- **Auto-purchase.** You can configure a threshold and amount for automatic credit top-ups when your balance falls below a certain level.
- **Running out of credits.** When you run out of credits, agent steps halt. You can configure behavior when this happens (e.g. continue the workflow or stop the workflow).
### Credit reference
When web search is enabled, the minimum credit cost is increased by 3 credits per execution.
### Understanding credit use
You can see the minimum credit costs for a selected model in the agent function in the workflow editor.
When you run a test execution of the agent step, you can see the **actual credit cost** for the execution that your account would have been charged.
In the workflow debugger, you can see the actual credit cost for each step execution under the **credits** column.
## Error handling
When an agent step fails (e.g. model error, timeout, or invalid response), Knock marks the step as failed. You can configure whether the workflow should halt or continue to the next step when an agent step fails using the "Halt on error" setting.
The agent step will retry up to 3 times for certain types of errors:
- **Model errors.** The model returns an error response.
- **Timeout errors.** The request takes longer than the model's timeout.
- **Unexpected errors.** The model returns an unexpected response.
Note: we will **not** retry when the model returns an error response or indicates that they could not fulfill the request.
## Debugging agent steps
You can use the [workflow run logs](/send-notifications/debugging-workflows) to debug agent steps. For each agent step, the logs include:
- The rendered prompt sent to the model.
- The model response.
- The duration of the request.
- Any errors encountered.
## Frequently asked questions
Yes. The output from an agent step is available in the workflow run scope, so you can use it in [step conditions](/designing-workflows/step-conditions) on subsequent steps.
For example, you could branch based on whether the agent returned a specific persona type or a non-empty enrichment result.
Yes. You can place an agent step after a [batch function](/designing-workflows/batch-function) to summarize or enrich the batched activities. The agent has access to the batch data in the workflow run scope.
If the prompt fails to render due to a Liquid error, the step will fail and the workflow will halt (or continue, depending on your error handling configuration). Use the [workflow debugger](/send-notifications/debugging-workflows) to inspect the error.
## Throttle function
Learn more about the throttle workflow function within Knock's notification engine.
---
title: Throttle function
description: Learn more about the throttle workflow function within Knock's notification engine.
tags: ["steps", "functions"]
section: Designing workflows
---
A throttle function allows you to limit the number of times a workflow is executed for a recipient within a given window. For example, in an alerting system, your recipients might only want to receive a single email _per hour_ for a given alert. A throttle lets you express this logic within Knock.
Throttle functions are helpful when you want to control how often a workflow is executed for a recipient without needing to implement the logic within your own application layer.
## How throttling works
Throttling works like a gate. When the throttle step is executed, the gate is checked; if the threshold over the window has been exceeded, then the workflow stops execution. If the threshold has not been met, then the workflow will proceed.
Throttle functions have 3 pieces of configuration:
1. **A throttle window**: the length of the throttle period.
2. **A throttle threshold**: the number of invocations allowed within the window. Defaults to 1 if none provided.
3. **A throttle key** (optional): An optional value to specify as the throttle key for the workflow run.
## Setting a throttle window
The throttle window determines how long a throttle is active for the recipient. The window opens the first time the throttle function is executed in a workflow run for a recipient.
### Set a fixed throttle window
You can set a fixed duration throttle window using the "Throttle for a fixed window" option in the throttle step. The window accepts a relative duration, which can be specified in seconds, minutes, hours, or days.
### Set a dynamic throttle window
You can also set the length of your throttle windows dynamically using a variable. You can use any of the data, recipient, actor, or environment variables associated with the workflow run to set your dynamic throttle window.
When specifying a dynamic window you must provide one of the following:
- An ISO-8601 timestamp (e.g. `2022-05-04T20:34:07Z`) which must be a datetime in the future
- A relative duration unit (e.g `{ "unit": "seconds", "value": 30 }`)
- A window rule (e.g `{ "frequency": "daily", "hours": 9, "minutes": 30 }`)
A dynamic interval must be available to be resolved via the `key` you specify on the given schema, meaning that if you specify a key of `throttleWindow` in your `data` schema, your workflow trigger data must contain either an ISO-8601 timestamp, a valid duration unit, or a valid window rule.
When the key specified is missing or resolves to an invalid value, a corresponding error will be logged on the workflow run, and the throttle will be **skipped**.
A fixed timestamp will tell Knock to close the throttle window at the exact datetime you provide. It must be a valid ISO-8601 timestamp in the future.
#### An example timestamp
```json title="Setting a throttle until timestamp"
{
"throttleUntil": "2024-01-05T14:00:00Z"
}
```
You can then reference that in your throttle step settings as `data.throttleUntil`.
A duration will take the current time that the step is executing and add the duration to it to produce the throttle window close time. A duration object is an entity that you can set on recipients, tenants, environment variables, or in your data payload and reference on your throttle step.
#### Duration properties
| Variable | Type | Description |
| -------------- | ------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------- |
| `unit` | "seconds" \| "minutes" \| "hours" \| "days" \| "weeks" | Unit of duration. |
| `value` | number | Number of seconds, minutes, hours, days, or weeks for the throttle to be applied. |
#### An example duration
Let's say you want to express a duration that throttles for 15 minutes, here's how you structure that:
```json title="Setting a duration"
{
"throttleDuration": {
"unit": "minutes",
"value": 15
}
}
```
You then reference that as `data.throttleDuration` in the throttle step configuration.
A window rule determines a dynamic interval for when the throttle should close. It allows you to express rules like "throttle until Monday at 9am."
The window rule will always be evaluated in the [recipient's timezone](/concepts/recipients#recipient-timezones) (when set) and will fall back to the account default timezone, or "Etc/UTC".
#### Window rule properties
| Variable | Type | Description |
| -------------- | ------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------- |
| `frequency` | "hourly" \| "daily" \| "weekly" \| "monthly" | The frequency at which the window rule should evaluate. |
| `days` | DaysOfWeek[], "weekdays", "weekends" (optional) | The specific days the rule is valid on. |
| `hours` | number (optional) | The hour at which the rule should evaluate. Defaults to 0. |
| `minutes` | number (optional) | The minute at which the rule should evaluate. Must be one of: 0, 5, 10, 15, 20, 25, 30, 35, 40, 45, 50, 55. Defaults to 0. |
| `day_of_month` | number (optional) | When frequency is "monthly", set this value to specify the day of the month when the rule executes. If omitted, the rule uses the day of the month on which the throttle window opened and executes at the next occurrence of the configured time. |
#### Example window rule
Let's say you want to express setting a window rule for throttling until Monday at 9am, here's how you might structure that on your recipient:
```json title="Recipient throttle window"
{
"throttleWindow": {
"frequency": "weekly",
"days": ["mon"],
"hours": 9
}
}
```
Now you can set the throttle window key to `recipient.throttleWindow` to reference this window rule.
## Setting a throttle threshold
The throttle threshold determines how many invocations are allowed in the window before the threshold takes effect. By default, this value is set to 1, but you can change it as needed.
For example, if you want to say that you want to allow 5 invocations over a 1-minute window, then you would set the throttle threshold to 5.
## Selecting a throttle key
A throttle function always throttle events per `recipient`. When you provide a throttle key, throttled events are further grouped by that key. The throttle key resolves to a value in your `data` payload. You can also use Liquid to [reference variables](/template-editor/variables) from the workflow run scope (such as the `recipient.*`, `actor.*`, or `tenant.*` namespaces) to construct a key.
You can use multiple variables when constructing a throttle key. For example, setting the throttle key to `{{data.eventType}}-{{actor.id}}` would throttle separately per event type and actor.
When the key specified is missing or resolves to an invalid value, a corresponding error will be logged on the workflow run, and the throttle will be **skipped**.
Here's a helpful way to think about throttling. By default, the throttle
function throttles on a key of recipient_id. When a throttle
key is provided, it throttles on a key of{" "}
concat(recipient_id, throttle_key).
}
/>
Custom throttle keys must be shorter than 64 characters long after being JSON and URL encoded.
## Frequently asked questions
Yes! A dynamic throttle window can come from a variety of dynamic sources
like the recipient, the environment, or within the data payload.
When a throttle is hit, the workflow will stop execution. You will be able
to see this in your workflow run logs.
We haven’t added this ability, but if this is something you’re looking to
do, please reach out to us to discuss your use case. We’d love to hear more.
A throttle is allowed to be opened for a maximum of 31 days. If you have a
use case for a longer throttle window, please [get in
touch](mailto:support@knock.app).
Absolutely, each throttle step is executed independently in a workflow, so
you can have as many as you need.
Currently, you cannot throttle across Knock workflows. In the future, we
will be exploring adding the ability to rate-limit the number of
notifications a recipient can receive in a given window of time, which will
work across workflows.
Currently, you cannot extend the throttle window past 31 days. If you need
to throttle a workflow to run at most once per recipient, you can consider
using [workflow trigger
frequency](/send-notifications/triggering-workflows#controlling-workflow-trigger-frequency)
instead.
## Trigger workflow function
Learn more about the trigger workflow function within Knock's notification engine.
---
title: Trigger workflow function
description: Learn more about the trigger workflow function within Knock's notification engine.
tags: ["steps", "functions"]
section: Designing workflows
---
A trigger workflow function enables you to invoke a workflow from within another workflow. This function allows you to compose complex notifications by reusing logic across multiple workflows, improving maintainability and reducing duplication.
When using the trigger workflow function, you can utilize the data passed directly from the parent workflow or specify custom data for use when triggering the nested workflow.
## How trigger functions work
The trigger workflow step functions similarly to a standard workflow trigger, executing a specified workflow with a specified payload. The payload is constructed based on the configuration settings defined in the step.
Like other functions, the trigger workflow function runs independently for each recipient in the parent workflow. This means that if your parent workflow has three recipients, the trigger function will execute three times, creating distinct workflow runs each time. This behavior ensures that each recipient's context and data is properly isolated in the nested workflow.
## Configuring a trigger function
Choose from any currently *active* workflows in your system
Recipients
Actor (optional)
Tenant (optional)
Data (optional)
Cancellation key (optional)
### Selecting the workflow
You can select any active workflow for use in the trigger workflow step. The trigger function will always use the most recently committed version of the selected workflow. To ensure that the correct workflow version is triggered, you must [commit](/concepts/commits) any intended changes to the selected workflow. Any uncommitted changes to the selected workflow will not be reflected when the step is executed.
If the selected workflow is later set to inactive or is archived, the trigger workflow step will be in an invalid state and the step will be skipped.
### Setting the trigger data
The trigger workflow function uses strings or [Liquid](/template-editor/reference-liquid-helpers) variables to define the trigger data for the nested workflow. You can reference any variables and data available in the parent workflow run.
| Field | Type | Default Value | Description |
| ------------------ | ------ | --------------------------------- | ------------------------------------------------------ |
| `recipients` | string | `{{ recipient.id }}` | The recipient(s) who will receive the nested workflow. |
| `actor` | string | `{{ actor.id }}` | The user or system initiating the nested workflow. |
| `tenant` | string | `{{ tenant.id }}` | The tenant context for the nested workflow. |
| `data` | string | `{{ data \| json }}` | Data payload passed to the nested workflow. |
| `cancellation_key` | string | `{{ workflow.cancellation_key }}` | Unique identifier used to cancel nested workflow runs. |
### Handling Errors
When configuring the trigger workflow function, you may encounter the following errors:
- **Liquid Rendering Error**: This occurs when there is a syntax error in the Liquid template used for defining trigger data. Ensure that all variables and expressions are correctly formatted and available in the parent workflow context.
- **Invalid Trigger Data**: If the resolved trigger data for the nested workflow is invalid, the workflow execution will fail. This can happen if required fields are missing or contain incorrect values. Double-check the data being passed to ensure it meets the expected format and requirements of the nested workflow.
## Workflow cancellation
When using trigger workflow functions, both parent and nested workflows can be canceled if they contain cancelable steps (batch, delay, or fetch functions) and are configured with cancellation keys.
If the parent workflow is canceled before the trigger workflow step executes, the nested workflow will not be triggered, so no separate cancellation is needed.
If you need to cancel a nested workflow that has already been triggered, you can do so by making a separate cancellation request using the cancellation key configured in the trigger workflow step. Canceling the parent workflow after the trigger workflow step has executed will not automatically cancel the nested workflow - you'll need to cancel each workflow separately.
## Data steps
## Update user function
Learn how to update a user in Knock during a workflow run.
---
title: Update user function
description: Learn how to update a user in Knock during a workflow run.
tags: ["steps", "users", "data", "functions"]
section: Designing workflows
---
An update user function updates a [user](/concepts/users) stored in Knock as a step in your workflow. Use it when you need to change a user's properties or [preferences](/preferences/overview) based on workflow context to enable downstream steps, [audiences](/concepts/audiences), or other workflows to use the updated data.
Common use cases include syncing state from your trigger (for example, "last notified at"), making a user eligible for a [dynamic audience](/concepts/audiences) so they'll receive a [guide](/concepts/guides), or updating notification preferences from within a workflow.
## Selecting the user
By default, Knock updates the current workflow [recipient](/concepts/recipients) (the user this run is for). Alternatively, you can select a property that resolves to a user ID (or use a literal user ID) to update a different user (for example, the `actor` or a user ID from your trigger `data`).
The update user step supports upserting. If you specify a user ID that does not yet exist in Knock, a new user will be created with the properties you set.
Update user function step in the workflow builder.Configuring a user ID for the update user step.
## Updating preferences
The update user step can update the user's notification [preferences](/preferences/overview). This enables you to create workflow logic that updates which channels or workflows a user is opted into.
Set preferences using the `preferences` key on the user. The value should follow the structure of a [`PreferenceSet`](/api-reference/recipients/preferences/schemas/preference_set).
Preferences are deep-merged into the user's existing preference set. This means you can set individual preference keys across multiple update user steps without overwriting previously set values. For example, two sequential update user steps can each target a different part of the preference set and the results will be combined:
```json title="Preference deep merge across two update user steps"
// Update user step 1
{
"preferences": { "default": { "categories": { "admin": false } } }
}
// Update user step 2
{
"preferences": { "default": { "channel_types": { "email": false } } }
}
// Resulting preferences on the user
{
"default": {
"categories": { "admin": false },
"channel_types": { "email": false }
}
}
```
## Configuring properties
You can set any number of properties on the user. Each property has a **key** and a **value**. Properties can be configured as a JSON blob or as key-value pairs.
- **Key.** The property name. You can use an existing user property or define a new property.
- **Value.** The value to set. You can use [Liquid](/template-editor/overview) (for example, `{{ data.foo }}` or `{{ recipient.email }}`) to resolve a dynamic value from workflow data, the recipient, the actor, or [variables](/concepts/variables). You can also use a static value (for example, `"bar"` or `true`).
## Merging properties
When an update user step executes, Knock deep-merges the configured properties into the existing user. This means:
- Top-level keys are merged into the existing user, adding new keys and replacing existing ones.
- Nested objects are recursively merged rather than replaced. If the existing user has a nested object and the update step sets a key inside it, only that key is updated — the rest of the nested object is preserved.
This is the same deep-merge behavior used by the [identify API](/api-reference/users/identify).
```json title="Property deep merge across two update user steps"
// Update user step 1
{
"meta": { "first": "hello", "last": "world" }
}
// Update user step 2
{
"meta": { "last": "knock" }
}
// Resulting properties on the user
{
"meta": {
"first": "hello",
"last": "knock"
}
}
```
## Limitations
Update user steps do not support updating [channel data](/managing-recipients/setting-channel-data). You cannot set or change channel data (for example, push tokens) via this step.
In addition, `channel_data` is not rendered in the workflow event success or error logging for these recipients, even when channel data is present on the user.
## Debugging
You can use the [workflow run logs](/send-notifications/debugging-workflows) to debug update user steps. The logs render the full before/after diff view of the user so that you can verify the pre-state, the properties that were set, and the post-state.
Before/after diff for an update user step in the workflow run logs.
Update user steps are also available in the [management API](/mapi-reference/overview) and can be included when you show or upsert a workflow.
## Update tenant function
Learn how to update a tenant's properties in Knock during a workflow run.
---
title: Update tenant function
description: Learn how to update a tenant's properties in Knock during a workflow run.
tags: ["steps", "tenants", "data", "functions"]
section: Designing workflows
---
An update tenant function updates a [tenant](/concepts/tenants) stored in Knock as a step in your workflow. Use it when you need to change a tenant's properties based on workflow context to enable downstream steps or other workflows to use the updated data.
Common use cases include syncing tenant state from your trigger (for example, approval status or feature flags), updating [tenant-level preference defaults](/multi-tenancy/per-tenant-preferences), or storing data on the tenant that you reference later in the same workflow or in another workflow.
## Selecting the tenant
By default, Knock updates the tenant associated with the current workflow run (the `tenant` you passed in the [trigger](/send-notifications/triggering-workflows)). You can leave this default, or select a property that resolves to a tenant ID (or use a literal tenant ID) to update a different tenant.
The update tenant step supports upserting. If you specify a tenant ID that does not yet exist in Knock, the tenant will be created with the properties you set.
Update tenant function step in the workflow builder.Configuring a tenant ID for the update tenant step.
## Updating preferences
You can update a tenant's default [preferences](/preferences/overview) from within a workflow. Use the `preference_set` key nested under `settings` (not `preferences`) when setting tenant preferences. The value should follow the structure of a [`PreferenceSet`](/api-reference/recipients/preferences/schemas/preference_set). For more information on how tenant preferences work and how to structure them, see [per-tenant preferences](/multi-tenancy/per-tenant-preferences).
```json title="Setting tenant preferences via the update tenant step"
{
"settings": { "preference_set": { "categories": { "admin": false } } }
}
```
Tenant preference defaults are deep-merged into the tenant's existing preference set. This means you can set individual preference keys across multiple update tenant steps without overwriting previously set values. For example, two sequential update tenant steps can each target a different part of the preference set and the results will be combined:
```json title="Preference deep merge across two update tenant steps"
// Update tenant step 1
{
"settings": { "preference_set": { "categories": { "admin": false } } }
}
// Update tenant step 2
{
"settings": { "preference_set": { "channel_types": { "email": false } } }
}
// Resulting tenant preference defaults
{
"categories": { "admin": false },
"channel_types": { "email": false }
}
```
For more details on updating tenant default preferences and how to modify the merge behavior, see the [per-tenant preferences FAQ](/multi-tenancy/per-tenant-preferences#frequently-asked-questions).
## Configuring properties
You can set any number of properties on the tenant. Each property has a **key** and a **value**. Properties can be configured as a JSON blob or as key-value pairs.
- **Key.** The property name. You can use an existing tenant property or define a new property.
- **Value.** The value to set. You can use [Liquid](/template-editor/overview) (for example, `{{ data.tenant_name }}` or `{{ tenant.id }}`) to resolve a dynamic value from workflow data, the recipient, the actor, or [variables](/concepts/variables). You can also use a static value (for example, `"Acme Corp"` or `true`).
## Merging properties
When an update tenant step executes, Knock deep-merges the configured properties into the existing tenant. This means:
- Top-level keys are merged into the existing tenant, adding new keys and replacing existing ones.
- Nested objects are recursively merged rather than replaced. If the existing tenant has a nested object and the update step sets a key inside it, only that key is updated — the rest of the nested object is preserved.
```json title="Property deep merge across two update tenant steps"
// Update tenant step 1
{
"meta": { "first": "hello", "last": "world" }
}
// Update tenant step 2
{
"meta": { "last": "knock" }
}
// Resulting properties on the tenant
{
"meta": {
"first": "hello",
"last": "knock"
}
}
```
## Limitations
Update tenant steps do not support updating [channel data](/managing-recipients/setting-channel-data). You cannot set or change channel data on a tenant via this step.
In addition, `channel_data` is not rendered in the workflow event success or error logging for these recipients, even when channel data is present on the tenant.
## Debugging
You can use the [workflow run logs](/send-notifications/debugging-workflows) to debug update tenant steps. The logs render the full before/after diff view of the tenant so that you can verify the pre-state, the properties that were set, and the post-state.
Before/after diff for an update tenant step in the workflow run logs.
Update tenant steps are also available in the [management API](/mapi-reference/overview).
## Update object function
Learn how to update an object's properties in Knock during a workflow run.
---
title: Update object function
description: Learn how to update an object's properties in Knock during a workflow run.
tags: ["steps", "objects", "data", "functions"]
section: Designing workflows
---
An update object function updates an [object](/concepts/objects) in a collection stored in Knock as a step in your workflow. Use it when you need to change an object's properties based on workflow context to enable downstream steps or other workflows to use the updated data.
Common use cases include syncing object state from your trigger (for example, status or last activity), or storing data on the object that you reference later when the object is used as a recipient in another workflow.
## Selecting the collection and object
The update object step does **not** support a "current object" mode. You must specify which object to update.
- **Collection.** Choose from all [object collections](/concepts/objects) in your environment (for example, "Projects" or "Repositories").
- **Object ID.** Select a property that resolves to the object ID within that collection, or use a literal object ID. This can come from your trigger data (for example, `data.project_id`), from the recipient when the recipient is an object (`recipient.id`), or from another source in the workflow run.
The update object step supports upserting. If you specify an object ID that does not yet exist in that collection in Knock, the object will be created with the properties you set.
Update object function step in the workflow builder.
Configuring collection and object ID for the update object step.
## Updating preferences
You can update an object's [preferences](/preferences/overview) from within a workflow. Set them using the `preferences` key. The value should follow the structure of a [`PreferenceSet`](/api-reference/recipients/preferences/schemas/preference_set).
Preferences are deep-merged into the object's existing preference set. This means you can set individual preference keys across multiple update object steps without overwriting previously set values. For example, two sequential update object steps can each target a different part of the preference set and the results will be combined:
```json title="Preference deep merge across two update object steps"
// Update object step 1
{
"preferences": { "default": { "categories": { "admin": false } } }
}
// Update object step 2
{
"preferences": { "default": { "channel_types": { "email": false } } }
}
// Resulting preferences on the object
{
"default": {
"categories": { "admin": false },
"channel_types": { "email": false }
}
}
```
## Configuring properties
You can set any number of properties on the object. Each property has a **key** and a **value**.
- **Key.** The property name. You can use an existing object property or define a new property.
- **Value.** The value to set. You can use [Liquid](/template-editor/overview) (for example, `{{ data.status }}` or `{{ recipient.name }}`) to resolve a dynamic value from workflow data, the recipient, the actor, or [variables](/concepts/variables). You can also use a static value (for example, `"active"` or `true`).
Properties can be configured as a JSON blob or as key-value pairs.
## Merging properties
When an update object step executes, Knock deep-merges the configured properties into the existing object. This means:
- Top-level keys are merged into the existing object, adding new keys and replacing existing ones.
- Nested objects are recursively merged rather than replaced. If the existing object has a nested object and the update step sets a key inside it, only that key is updated — the rest of the nested object is preserved.
This is the same deep-merge behavior used by the [objects API](/api-reference/objects/set).
```json title="Property deep merge across two update object steps"
// Update object step 1
{
"meta": { "first": "hello", "last": "world" }
}
// Update object step 2
{
"meta": { "last": "knock" }
}
// Resulting properties on the object
{
"meta": {
"first": "hello",
"last": "knock"
}
}
```
## Limitations
Update object steps do not support updating [channel data](/managing-recipients/setting-channel-data). You cannot set or change channel data on an object via this step.
In addition, `channel_data` is not rendered in the workflow event success or error logging for these recipients, even when channel data is present on the object.
## Debugging
You can use the [workflow run logs](/send-notifications/debugging-workflows) to debug update object steps. The logs render the full before/after diff view of the object so that you can verify the pre-state, the properties that were set, and the post-state.
Before/after diff for an update object step in the workflow run logs. This
workflow run upserted a new object, so the diff shows only the new version.
Update object steps are also available in the [management API](/mapi-reference/overview).
## Update data function
Learn more about the update data function within Knock's notification engine.
---
title: Update data function
description: Learn more about the update data function within Knock's notification engine.
tags: ["steps", "data", "workflow state", "functions", "liquid"]
section: Designing workflows
---
An update data function updates properties on the workflow `data` state as a step in a workflow. Any data set by an update data function is merged into the original trigger `data` provided on the workflow trigger and made immediately available to all subsequent steps in the workflow.
## Configuring data properties
To configure an update data function, you can add key-value pairs in the step editor or use the code editor to input a JSON object directly. Each key represents a property name that will be set on the workflow data, and each value can be either a static value or a Liquid expression.
Each value field is a Liquid-compatible input. This means you can use Liquid variables and control flow to inject variable data, access Knock-controlled workflow state attributes (e.g., `recipient`), and dynamically compute values per workflow run.
Update data function step in the workflow builder.
Code editor mode for configuring an update data function.
Here are some example configurations:
| Key | Value | Description |
| ---------------- | -------------------------------------------- | --------------------------------------------------- |
| `full_name` | `{{ data.first_name }} {{ data.last_name }}` | Combines first and last name into a single property |
| `greeting` | `Hello` | Sets a static greeting value |
| `item_count` | `{{ data.items \| size }}` | Computes the count of items in an array |
| `is_premium` | `{{ recipient.plan \| equals: "premium" }}` | Sets a boolean flag based on recipient data |
| `formatted_date` | `{{ "now" \| date: "%B %d, %Y" }}` | Adds the current date in a specific format |
See the [Knock template editor reference](/template-editor/overview) for detailed information on working with Liquid in your Knock message templates.
## Merging data
When an update data function executes, Knock will merge the configured properties into the `data` you originally passed to [the workflow trigger call](/send-notifications/triggering-workflows). Knock uses a shallow-merge strategy where:
- Top-level keys from the update data step are merged into the existing workflow run data, adding new keys and replacing existing ones.
- Nested objects are replaced entirely rather than deep-merged. If the original data has a nested object and the update data step sets the same key, the entire nested object is overwritten.
_The merged data result from an update data function step then becomes the global trigger data for all subsequent steps in the workflow run._
The example below illustrates how this could look in practice.
```json title="Example data merge for update data function steps"
// Original trigger data
{
"first_name": "Jane",
"last_name": "Doe",
"metadata": {
"source": "web"
}
}
// Update data function configuration
// full_name: {{ data.first_name }} {{ data.last_name }}
// metadata: { "computed": true }
// Merge result
{
"first_name": "Jane",
"last_name": "Doe",
"full_name": "Jane Doe",
"metadata": {
"computed": true
}
}
```
## Debugging update data functions
You can use the [workflow debugger](/send-notifications/debugging-workflows) to debug your update data function steps. When viewing a workflow run for a specific recipient, you can select the workflow data function step to see the computed data that was merged into your workflow run state.
Viewing update data function step in the workflow run logs.
## Frequently asked questions
Use an **update data function** when you need to transform, compute, or restructure data that is already available in your workflow run. This is ideal for operations like combining fields, setting defaults, or pre-computing Liquid expressions.
Use a **[fetch function](/send-notifications/designing-workflows/fetch-function)** when you need to retrieve additional data from an external service that isn't available in your trigger data. The fetch function makes an HTTP request to your service and merges the response into your workflow data.
In some cases, you might use both: a fetch function to retrieve additional data, followed by an update data function to transform or restructure the combined data for your templates.
You can set a top-level property to an object value, but you cannot directly
set deeply nested properties (e.g., `metadata.nested.value`). If you need to
update a nested property, you'll need to set a new value for the entire parent object (`metadata`), which
will replace any existing nested data due to the shallow-merge behavior. See the section on [merging data](#merging-data) above for an example.
If a Liquid expression in your update data function encounters an error (such as referencing a property that doesn't exist), **the step will fail and halt your workflow run.** You can use Liquid's default filter (e.g., `{{ data.optional_field | default: "fallback" }}`) to provide fallback values and avoid errors when data may be missing.
Yes. Since each update data function merges its computed data into the workflow's global data state, subsequent steps (including other update data functions) can reference that data using the `data` namespace. For example, if a previous step set `data.full_name`, a later step can reference it as `{{ data.full_name }}`.
## Update audience function
Learn how to add or remove users from a static audience during a workflow run.
---
title: Update audience function
description: Learn how to add or remove users from a static audience during a workflow run.
tags: ["steps", "audiences", "data", "functions"]
section: Designing workflows
---
An update audience function adds or removes a user from a [static audience](/concepts/audiences).
You can add or remove users from a static audience to trigger other workflows, send [broadcasts](/concepts/broadcasts), and make the recipient eligible to see [guides](/concepts/guides).
Common use cases include making a user eligible for a guide after they complete an onboarding step, removing a user from a promotional audience after they convert, or syncing audience membership based on data available in your workflow trigger.
## Choosing the action
The update audience step supports two actions:
- **Add to.** Adds the current recipient to the selected static audience. If the recipient is already a member, the step succeeds with no change.
- **Remove from.** Removes the current recipient from the selected static audience. If the recipient is not a member, the step succeeds with no change.
Update audience function step in the workflow builder.
## Selecting the audience
Choose a static audience from the audiences available in your environment. The dropdown lists all static audiences that have been created and committed in the current environment.
Once you select an audience, the step shows usages of the selected audience, including workflows, broadcasts, and guides.
## Limitations
The update audience step only works with [static audiences](/concepts/audiences).
The step always operates on the current workflow user.
An update audience step cannot Add to the same audience that triggers the workflow. If your workflow uses an [audience change trigger](/send-notifications/triggering-workflows/audiences), the trigger audience is not available in any update audience steps within that workflow. Likewise, if a workflow already contains an update audience step Adding to a given audience, that audience cannot be selected as the trigger audience.
## Debugging
You can use the [workflow run logs](/send-notifications/debugging-workflows) to debug update audience steps. When viewing a workflow run for a specific recipient, select the update audience step to see whether the recipient was added to or removed from the audience, and the audience that was targeted.
Viewing an update audience step in the workflow run logs. The recipient was
added to the audience.
Viewing an update audience step in the workflow run logs. The recipient was
not removed from the audience because they were not a member.
## Frequently asked questions
Use an **update audience step** when audience membership should change as part of a workflow run, for example adding a user to a "completed onboarding" audience after they finish a setup flow. The step runs inline with your workflow so subsequent steps immediately see the updated membership.
Use the [audiences API](/api-reference/audiences) when you need to sync audience membership in bulk from an external source (such as a data warehouse or reverse ETL tool), or when the membership change is not tied to a specific workflow run.
No. Dynamic audience membership is computed automatically from user properties. To make a user eligible for a dynamic audience during a workflow, use an [update user step](/send-notifications/designing-workflows/update-user-function) to set a property that matches the audience's query rules.
No. The update audience step always operates on the current workflow recipient. If you need to modify audience membership for a different user, use the [audiences API](/api-reference/audiences) instead.
## Step conditions
Learn more about how to use step conditions within the Knock workflow builder.
---
title: Step conditions
description: Learn more about how to use step conditions within the Knock workflow builder.
tags:
[
"triggers",
"conditions",
"conditionals",
"steps",
"routing",
"conditional send",
]
section: Designing workflows
---
Step conditions allow you to apply control flow to your workflow runs on a per-step basis. You can use the [Knock conditions editor](/concepts/conditions#the-conditions-editor) to associate one or more conditions with any step in your workflow. Then, for each workflow run, Knock will evaluate these conditions to determine if the step should execute.
Some examples of the kinds of step conditions you can design include:
- Only execute a workflow if `shouldExecute == true`.
- Only send an email if an in-app notification was not previously read or seen.
- Only send an in-app notification if the `recipient.plan == "pro"`.
- Only execute a delay step if `delay == true` in the workflow trigger.
- Only send an email in your development environment if the recipient's email matches a particular domain.
See our [documentation on the Knock conditions model](/concepts/conditions) for more information about how conditions work across Knock and how to [debug your conditions within your workflow runs](/concepts/conditions#debugging-conditions).
This page covers features specific to step conditions, most importantly message status conditions.
## Types of step conditions
### Trigger step conditions
A [trigger step](/designing-workflows/overview#the-trigger-step) can have one or more step conditions, which will be evaluated on the trigger of the workflow for the recipient. When the conditions evaluate to false then the workflow **will be halted** and no other steps will be executed.
### Other step conditions
For all function and channel steps, step conditions will be evaluated when the step is executed. If the conditions on the step evaluate to false, then the step will be **skipped** and the subsequent step will be invoked, or the workflow will terminate if there are no other steps to execute.
## Message status conditions
Message status conditions allow you to build a check for one workflow step that evaluates against the [delivery or engagement status](/send-notifications/message-statuses) of a message sent from a preceding step.
This means that message status conditions are most effective when used in
combination with workflow steps (like a{" "}
delay function) that
pause workflow execution. See the section on{" "}
evaluation timing below for more
information.
}
/>
When building a step message status condition, you'll use the conditions editor to select:
- Any preceding channel step that may produce a message, using it's `ref`.
- An asserting (`"has"`) or negating (`"has not"`) condition operator.
- The expected delivery or engagement status case.
Message state used to evaluate status conditions is subject to the Knock data retention policy. If you attempt to evaluate a status condition against a message that has expired out of your account's retention window, the condition will always evaluate to a false result. For more information, see our [data retention docs](/manage-your-account/data-retention).
### Status cases
While you can reference any preceding channel step in a message status
condition, you will be presented with a different set of options depending
on the case (asserting or negating) and the target step's channel type.
In-app feed channel steps support certain engagement status options ("seen
but not read") that others do not. The "read" and "link clicked" status
conditions often require that{" "}
Knock tracking has been
enabled.
}
/>
| Case | Limits | Description |
| ------------------------ | ------------------------------------------------ | -------------------------------------------------------------------------------------------------------------------- |
| **skipped** | - | The target step was skipped and did not generate a message. |
| **failed delivery** | - | The message failed to deliver and Knock has exhausted all retries. |
| **bounced** | - | The message was successfully sent to the delivery provider but failed to send due to a bounce. |
| **sent** | - | The message has been successfully sent to the delivery provider. |
| **delivered** | - | The message has been successfully sent to the delivery provider, and Knock has confirmed delivery to your recipient. |
| **seen** | _In-app channels only_ | The message has been rendered in the feed. |
| **seen but not read** | _In-app channels only_ | The message has been rendered in the feed, but not yet marked as read by your recipient. |
| **read** | _In-app channel or Knock open tracking required_ | The message has been marked as read. |
| **read but not clicked** | _Knock link tracking required_ | The message has been marked as read but no links have been clicked. |
| **interacted with** | _In-app channels only_ | The recipient has clicked on the message. |
| **link clicked** | - | The recipient has clicked at least one link in the message. |
| **archived** | - | The message has been archived. |
### Evaluation timing
A workflow [channel step](/designing-workflows/channel-step) that produces a `Message` will enqueue an asynchronous downstream message send to the recipient and proceed directly to the next workflow step. Knock evaluates message status conditions (like all other step conditions) immediately when executing a workflow step.
This means that you will need to account for time between workflow steps when building message status conditions, especially for messages that require delivery confirmation, recipient engagement, or which utilize [send windows](/designing-workflows/send-windows) that can delay the sending of the message. For example, if you want to send an SMS message as a fallback for a `bounced` push notification, you will need to leave time for Knock to send the push notification and receive the bounced response from the downstream provider prior to the SMS channel step.
[See below](#example-conditionally-sending-an-email-if-an-in-app-notification-was-not-seen) for an example of using a delay step in combination with a message status condition.
### Multiple messages
In certain cases, such as when using a [channel group](/integrations/overview#channel-groups), a single channel step can produce multiple messages. In these cases, Knock uses the message with the **highest** status for the condition evaluation.
To determine each message's highest status, Knock looks at both its [delivery status](/send-notifications/message-statuses#delivery-status) plus each of its [engagement statuses](/send-notifications/message-statuses#engagement-status), choosing the highest value status from the group. Knock uses the following combined delivery and engagement status hierarchy (ordered from lowest to highest):
1. `undelivered`
2. `bounced`
3. `delivery_attempted`
4. `queued`
5. `not_sent`
6. `sent`
7. `delivered`
8. `seen`
9. `read`
10. `interacted` + `link_clicked`
11. `archived`
## Example: conditionally sending an email if an in-app notification was not seen
One common use-case for step conditions is conditionally sending a notification based on whether the recipient has seen a preceding notification delivered on another channel. You can think of this concept as channel escalation, or intelligent routing.
In order to implement this, your workflow will need:
- An in-app notification channel step to send the initial message
- A delay step so that we wait a period of time before executing the email step
- An email channel step to send the escalated message
Next, we'll add a condition to our email channel step that will tell Knock to only send the email if the in-app notification has not yet been seen. To do this you will:
1. Select a "Step message status" condition type.
2. Select the `ref` of the in-app step (by default named `in_app_feed_1`).
3. Select the negating "has not" operator.
4. And finally, select the "been seen" status case option.
Setting a condition on an email step that passes when the message produced
by the preceding in-app step has not been seen after a 5-minute delay.
That's all it takes to build intelligent message routing in Knock!
## Advanced: How Knock models status conditions
The message status condition editor provides some useful abstractions on top of Knock's [conditions model](/concepts/conditions#modeling-conditions). Under the hood, Knock stores each status condition using our standard `variable`, `operator`, and `argument` trio, with some special caveats:
- The `variable` will always be either `refs..delivery_status` or `refs..engagement_status`.
- The `operator` will be a hierarchical comparison operator for a delivery status condition or an inclusionary operator for an engagement status condition.
- The `argument` will be a reserved status case string.
Below we provide example models for each of the status conditions made available in the editor.
#### Skipped cases
```json title="'has been skipped' case"
{
"variable": "refs.email_1.delivery_status",
"operator": "equal_to",
"argument": "$message.skipped"
}
```
```json title="'has not been skipped' case"
{
"variable": "refs.email_1.delivery_status",
"operator": "not_equal_to",
"argument": "$message.skipped"
}
```
#### Failed delivery cases
```json title="'has failed delivery' case"
{
"variable": "refs.email_1.delivery_status",
"operator": "equal_to",
"argument": "$message.undelivered"
}
```
#### Bounced cases
```json title="'has bounced' case"
{
"variable": "refs.email_1.delivery_status",
"operator": "equal_to",
"argument": "$message.bounced"
}
```
#### Sent cases
```json title="'has been sent' case"
{
"variable": "refs.email_1.delivery_status",
"operator": "greater_than_or_equal_to",
"argument": "$message.sent"
}
```
```json title="'has not been sent' case"
{
"variable": "refs.email_1.delivery_status",
"operator": "less_than",
"argument": "$message.sent"
}
```
#### Delivered cases
```json title="'has been delivered' case"
{
"variable": "refs.email_1.delivery_status",
"operator": "greater_than_or_equal_to",
"argument": "$message.delivered"
}
```
```json title="'has not been delivered' case"
{
"variable": "refs.email_1.delivery_status",
"operator": "less_than",
"argument": "$message.delivered"
}
```
#### Seen cases
```json title="'has been seen' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "contains",
"argument": "$message.seen"
}
```
```json title="'has been seen but not read' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "contains",
"argument": "$message.seen_not_read"
}
```
```json title="'has not been seen' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "not_contains",
"argument": "$message.seen"
}
```
#### Read cases
```json title="'has been read' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "contains",
"argument": "$message.read"
}
```
```json title="'has been read but not clicked' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "contains",
"argument": "$message.read_not_link_clicked"
}
```
```json title="'has not been read' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "not_contains",
"argument": "$message.read"
}
```
#### Interacted cases
```json title="'has been interacted with' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "contains",
"argument": "$message.interacted"
}
```
```json title="'has not been interacted with' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "not_contains",
"argument": "$message.interacted"
}
```
#### Link clicked cases
```json title="'has had a link clicked' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "contains",
"argument": "$message.link_clicked"
}
```
```json title="'has not had a link clicked' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "not_contains",
"argument": "$message.link_clicked"
}
```
#### Archived cases
```json title="'has been archived' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "contains",
"argument": "$message.archived"
}
```
```json title="'has not been archived' case"
{
"variable": "refs.email_1.engagement_status",
"operator": "not_contains",
"argument": "$message.archived"
}
```
## Channel steps
Learn more about channel steps within Knock's notification engine.
---
title: Channel steps
description: Learn more about channel steps within Knock's notification engine.
tags: ["steps", "channels", "functions"]
section: Designing workflows
---
A channel step within a workflow is the building block to produce a notification for a recipient. Channel steps house your notification templates and represent a notification to be delivered on a single channel type (e.g. email, push, SMS, in-app, etc).
For a channel step to be valid it must have a [channel or channel group](/integrations/overview#channel-groups) associated with it.
## Channel step execution
When a channel step is executed Knock does the following:
1. Runs through any [step conditions](/designing-workflows/step-conditions) to see if the step should be executed.
2. Checks the recipient has the information required to send notifications via this channel. (e.g. for an email channel, do they have an `email` address set? For a push channel do they have the [required channel data](/send-notifications/setting-channel-data) configured?)
3. Checks the [recipient's preferences](/preferences/overview) to see if they have opted out from receiving notifications on this channel or from this workflow.
4. Checks the channel's [send windows](/designing-workflows/send-windows) to see if the notification should be sent now or at a later time.
If the step continues, Knock will render [the template](/template-editor) associated with the step and enqueue a message to [deliver to the provider](/send-notifications/delivering-notifications) via the configured credentials on the channel.
See our [debugging workflows documentation](/send-notifications/debugging-workflows#understanding-workflow-execution-behavior) for more details on how workflow steps are executed and what happens when they encounter errors.
## Channel support
You can read more about configuring channels in our [integrations overview](/integrations/overview).
### In-app notifications
The Knock [Feed API](/api-reference/users/feeds) gives developers a way to deliver in-app notifications to feeds, inboxes, and other notification-based experiences.
There are a few ways to power in-app notifications in your product using Knock:
- **Use our [React SDK](https://github.com/knocklabs/javascript/tree/main/packages/react).** The Knock notification feed component provides real-time updates, pagination, badge behavior, filtering, and more. It's a great way to quickly add an in-app feed to your product if you use React.
- **Leverage our [client-side JS SDK](https://github.com/knocklabs/javascript/tree/main/packages/client).** This is a good approach if you need to use a component library outside of React JS but are still in the JS ecosystem.
- **Integrate with our [API directly](/api-reference/users/feeds).** If you're not working within the JS ecosystem in your client, you can integrate directly with the Knock Feed API to power your in-app notifications.
### Out-of-app channels
We support notification delivery to the following out-of-app channel types: [email](/integrations/email/overview), [push](/integrations/push/overview), [SMS](/integrations/sms/overview), and 3rd-party [chat apps](/integrations/chat/overview) (such as Slack). Click through to see a full list of the providers we support within each channel type.
Slack and Discord channel steps can also [reply to a message from a previous workflow step or in an existing thread](/integrations/chat/replying-to-chat-messages).
## Configuring displayed channels
By default, the workflow builder will display a single card for each channel type that is configured in your account. You can customize the channels displayed in the workflow builder by [configuring channel visibility](/concepts/channels#channel-visibility) per-channel. This allows you to keep your step panel focused on the channels that are relevant.
## In-app guide step
Learn how to make a recipient eligible for a guide directly from a workflow or broadcast step.
---
title: In-app guide step
description: Learn how to make a recipient eligible for a guide directly from a workflow or broadcast step.
tags: ["steps", "guides", "audiences", "in-app", "channels"]
section: Designing workflows
---
Use an in-app guide step to update a user's [guide](/concepts/guides) eligibility within a workflow or broadcast run. This is useful when eligibility is driven by the context of the workflow or broadcast. For example, recipients may become eligible for an onboarding modal after completing a certain action in a cross-channel onboarding campaign.
## How it works
An in-app guide step references a guide by its key. When you add the step to a workflow or broadcast, Knock creates a managed [static audience](/concepts/audiences) behind the scenes and links it to the guide's targeting rules. When the step executes for a recipient, Knock adds that recipient to the managed audience to make them [eligible for the selected guide](/in-app-ui/guides/create-guides#targeting).
If the workflow or broadcast run includes a tenant ID, Knock adds the recipient to the audience as a user-tenant pair. Learn more about [audiences and tenants](/concepts/audiences#audiences-and-tenants).
To receive the rendered guide in your application, eligible audience members must also meet any guide targeting criteria set directly on the guide. This includes [property-based targeting](/in-app-ui/guides/create-guides#targeting) and [activation rules](/in-app-ui/guides/create-guides#activation). Guides may also be subject to [throttling](/in-app-ui/guides/order-guides) depending on how they've been prioritized against other guides your user is eligible for.
## Adding an in-app guide step
In the workflow or broadcast builder, drag the **In-app guide** step onto
your canvas. It's listed alongside your channel steps in the step panel.
Select the guide you want to make recipients eligible for. Only guides
that have been created and [committed](/version-control/commits) in the
current environment are available for selection.
Add [step conditions](/designing-workflows/step-conditions) to control
when the step should run.
## Promoting the guide with the workflow
The in-app guide step references a [guide](/in-app-ui/guides/create-guides) by
key. That guide must already exist in the destination
[environment](/version-control/environments). If you
[promote](/version-control/commits#promoting-commits) the workflow or
broadcast first, the `guide_key` cannot resolve and the step is invalid there.
Promote the guide first so the dependency exists before Knock evaluates the
workflow:
1. Create and configure the guide in your development environment, then
[commit](/version-control/commits) and promote it.
2. Create or update the workflow or broadcast with the in-app guide step,
commit it, and promote it to the same environment.
3. After the workflow or broadcast is promoted, update the guide's
[audience targeting](/in-app-ui/guides/create-guides#targeting) if needed.
To only target recipients through the step, leave the guide's audience
empty, then commit and promote the guide again.
4. Repeat this order for each environment on the way to production.
## Guide targeting and the managed audience
When a guide is referenced by an in-app guide step, its **Audience** settings reflect that it's targeted by a workflow or broadcast step rather than, or in addition to, a manually selected audience. You can see which workflows and broadcasts trigger a given guide in the **Triggered by** section of the guide's details page in the dashboard.
### Tenant context
When a workflow trigger includes a tenant ID, Knock includes that tenant ID in
the recipient's audience membership context. This means the in-app guide step
enrolls the recipient as a user-tenant pair, rather than as a user alone. The
same applies when a broadcast run includes tenant context.
This context can affect guide eligibility when [tenancy strict
mode](/in-app-ui/guides/create-guides#tenancy-strict-mode) is enabled. See the
tenancy strict mode documentation for details.
## Frequently asked questions
Yes. In-app guide steps are supported in both workflows and broadcasts.
Not necessarily. As described in [How it works](#how-it-works), enrollment
makes the guide eligible, but your application still needs to fetch (or
refetch) guides for that recipient before the guide can render. See
[rendering guides](/in-app-ui/guides/render-guides) for how to do this in
your application.
Not through the in-app guide step itself, since it only adds recipients to
the managed audience. If you need to revoke eligibility, use [property-based
targeting](/in-app-ui/guides/create-guides#targeting) or [activation
rules](/in-app-ui/guides/create-guides#activation) on the guide to control
when it's actually shown, rather than relying solely on audience membership.
The in-app guide step becomes invalid. Workflow or broadcast runs skip the
invalid step and continue to the next step until the guide reference becomes
valid again. Knock records the skipped step and error in the run log, but
the run does not exit with an error state. Update the step to reference a
different committed guide, or restore the guide's committed state.
## Send windows
Learn how to control when notifications are delivered using send windows.
---
title: Send windows
description: Learn how to control when notifications are delivered using send windows.
tags: ["send windows", "steps", "channels", "workflows"]
section: Designing workflows
---
You can use send windows to specify when a channel step should send a message. For example, if you want to ensure your customers don’t receive a given transactional email from your product outside of working hours, you can set send windows for Monday - Friday, between 9:00 a.m. and 6:00 p.m. local user time.
Messages generated outside of this window will be [queued](https://docs.knock.app/send-notifications/message-statuses#3-queued) until the next open window, at which time Knock will resume delivery to the downstream provider.
Send windows are evaluated in the recipient's timezone (when set), specified by the user `timezone` [property](/concepts/users#optional-attributes). If the recipient's timezone is not set, Knock falls back to the [account default timezone](/manage-your-account/account-timezone), or `Etc/UTC`.
For push channels, a [device-level timezone](/integrations/push/device-metadata) takes precedence over the recipient's timezone when evaluating send windows.
## Modeling send windows
Knock models send windows as a list of send window objects. Each day must have 1 send window specified.
The send window object has the following properties:
| Property | Description |
| -------- | ------------------------------------------------------------------------------------------------------------------------------------------------ |
| `day` | Day of the week. One of: ”monday”, ”tuesday”, ”wednesday”, ”thursday”, ”friday”, ”saturday”, ”sunday”. |
| `type` | Whether notifications should be sent or not sent for this send window. One of: ”send”, ”do_not_send”. |
| `from` | An optional ISO-8601 time-only format string specifying the start of the window (defaults to 00:00:00). Only supported if type is set to ”send”. |
| `until` | An optional ISO-8601 time-only format string specifying the end of the window (defaults to end of day). Only supported if type is set to ”send”. |
In our JSON representation this will look something like:
```json title="Example send window"
{
"day": "monday",
"type": "send",
"from": "09:00:00",
"until": "17:00:00"
}
```
## The send windows editor
When creating or modifying a channel step, you can use the send window editor to configure send windows. If notifications are enabled for a given day of the week, you can also specify the time range during which messages will be sent on that day.
Send windows editor
## Validating trigger data
Learn how to validate the data passed to your Knock workflows using JSON schemas to ensure accuracy and prevent errors in your notifications.
---
title: Validating workflow trigger data
description: Learn how to validate the data passed to your Knock workflows using JSON schemas to ensure accuracy and prevent errors in your notifications.
section: Developer tools
---
Workflow trigger data is critical for ensuring your notifications have the right content and context. To help prevent errors and maintain data integrity, Knock offers a trigger data validation feature that allows you to specify the expected structure of the data passed to your workflows.
Trigger data validation lets you define a JSON schema that describes the expected shape and types of data passed to your workflow. If the incoming data doesn't match the specified schema, the trigger endpoint will return a `422 Unprocessable Entity` error with details about where the validation failed.
## How to set up trigger data validation
You can enable and configure trigger data validation in two ways:
1. **Via the Workflow Builder:**
- Navigate to the "Trigger step" in the workflow builder
- Under the "API params" section, click "Edit schema"
- Supply a valid JSON schema
- Commit your changes for the schema to take effect
2. **Via the Management API or CLI:**
- Use the `trigger_data_json_schema` field to provide your schema
## Example schema
Here's an example of a simple schema that expects a `name` property in the trigger data:
```json title="Trigger data validation schema"
{
"type": "object",
"properties": {
"name": { "type": "string" }
},
"required": ["name"]
}
```
With this schema in place, if the `name` property is missing or not a string, the trigger endpoint will return a `422` error.
## Error handling
When the incoming data fails validation, the API will respond with:
- Status code: `422 Unprocessable Entity`
- Response body: A list of validation errors, indicating where the data failed to meet the schema requirements
This ensures that your workflows are not executed with incorrect or incomplete data, helping to maintain the integrity of your notification system.
## Availability
Trigger data validation is available to all Knock customers. We recommend implementing it for all critical workflows to ensure data consistency and prevent potential issues in your notification pipeline.
## Type safety
Optionally, you can use the **[Knock CLI](/cli/overview)** to generate type definitions for TypeScript, Python, Ruby, and Go from your trigger data schemas. This will help you catch integration errors at compile time and ensure your workflow triggers always include the correct data.
Learn more about [type safety with workflows](/developer-tools/type-safety).
# Templates
Learn how to work with templates in Knock.
## Overview
Learn how to use the Knock template editor to design personalized cross-channel messages for your product.
---
title: Working with templates
description: Learn how to use the Knock template editor to design personalized cross-channel messages for your product.
tags:
[
"template",
"liquid",
"steps",
"variants",
"localization",
"internationalization",
"languages",
]
section: Working with templates
---
Knock has a full suite of tools for building and managing your cross-channel message templates including:
- Rich personalization and control flow with [Liquid](/template-editor/reference-liquid-helpers).
- Reusable content blocks with [partials](/template-editor/partials/overview).
- A [rich, visual editor](/template-editor/email-templates) for building emails with pre-built and custom components.
- The ability to drill down into code for complex templating use cases.
- A live-preview pane for seeing how your template will look when sent to a recipient.
- A test runner for sending test messages.
- Localization and translation support with [translations](/template-editor/translations).
- Local or remote programmatic management through our [CLI](/developer-tools/knock-cli) or [Management API](/mapi-reference).
## Overview
Each [channel step](/designing-workflows/channel-step) you add to a workflow or broadcast has its own message template. This template renders the message sent to your users on a given channel.
You can manage templates for each channel step via the Knock dashboard, or programmatically via the [Management API](/mapi-reference).
There is no concept of a standalone template in Knock. All templates must
belong to a single channel step within a workflow or broadcast.
}
/>
## Working with the template editor
You can access a channel step's template by clicking the "Edit content" button.
Within the template editor you will always see:
- A state pane for setting the properties used to preview your template.
- The template editor itself, which will vary depending on the channel type.
- A preview pane for seeing how your template will look when sent to a recipient.
## Version control
All changes to templates are versioned through Knock's [commit](/version-control/commits) and [environment](/version-control/environments) model. Saved changes are not made "live" until they are committed and/or promoted to a higher environment.
You can view a text diff of any changes to template through the "View changes" button in the **Changes** tab as well as seeing who made the change and on what date.
## Personalize messages with template variables
To inject a variable into your template, enclose it with double curly braces: `{{ a_variable }}`.
You can use curly braces to reference a number of different variable types in your templates. We've included a few common types below.
You can find the [full list of supported variables here](/template-editor/variables).
### Data payload variables
All variables sent in the `data` payload of your workflow trigger call. If you send through `{ "a_variable": "something" }` in your data payload you can reference this as `{{ data.a_variable }}` in your template.
if you want to reference all of the data passed to the workflow, you can
use the data variable.
}
/>
### User properties
To reference a user property (such as `name`), use the `recipient` namespace. This looks up the recipient of a given notification, and then finds the specified property for that user. Here's a code example where a recipient's name and plan are injected into a notification template:
```
Hey there {{ recipient.name }},
You just upgraded to the {{ recipient.plan }} plan.
Thanks,
The team @ Knock
```
You can also use the actor namespace to reference properties
of the actor who triggered the notification.
}
/>
[Full list of Knock variables available →](/template-editor/variables)
## Adding control flow and iteration to your template
The Knock template editor uses Liquid tags to create the logic and control flow for notification templates. To learn more about Liquid, you can check out their documentation.
Here are a few Liquid tag types that are commonly used in Knock notification templates.
**If and else-if statements.** For when you want to show different copy depending on a user property or a data variable from your trigger call. In the example below, we show different copy depending on whether a batch of comments includes one or many comments.
```liquid
{% if total_activities > 1 %}
{{ actor.name }} left {{ total_activities }} comments on {{ page_name }}
{% else %}
{{ actor.name}} left a comment on {{ page_name }}.
> {{ comment_body }}
{% endif %}
```
**For loops.** You can use Liquid's `for...in...` tag to iterate over a list of items. We can add this to our example from above to iterate over the comments in a batch and add each one to our notification.
```liquid
{% if total_activities > 1 %}
{{ actor.name}} left {{ total_activities }} comments on {{ data.page_name }}
{% for activity in activities %}
> {{ activity.data.comment_body }}
{% endfor %}
{% else %}
{{ actor.name}} left a comment on {{ data.page_name }}.
> {{ data.comment_body }}
{% endif %}
```
There are also a number of [Liquid filters](/template-editor/reference-liquid-helpers) you can use to mutate the variables you pass into a notification template. Here's an example that uses the `split` and `first` filters to pull the first name for a given user.
```liquid
You've been invited by {{ actor.name | split: " " | first }} to
join {{ data.account_name }} on Knock.
```
To learn more about the variables, Liquid keywords, and other helper functions available to you in the Knock template editor, check out our [Liquid helper reference](/template-editor/reference-liquid-helpers).
## Sharing templates across channels
You can use [partials](/template-editor/partials/overview) to share content across your templates, whether they belong to workflows, broadcasts, or guides.
Partials are reusable pieces of content that can include Liquid for rich templating. HTML partials can also be used as blocks within the visual email editor.
[Learn more about working with partials](/template-editor/partials/overview).
## Localization and translations
Knock supports localization and translation of your message templates. You can use the `t` tag to wrap content you want to translate in your default language, and Knock will automatically generate translation files for you behind the scenes.
[Learn more about working with translations](/template-editor/translations).
## Frequently asked questions
This is a common question that we hear from our customers, particularly those who currently maintain templates for their notifications in other third-party tools (often more than one!).
While [planning a migration](/tutorials/implementation-guide) will require some upfront effort, we recommend using Knock as the source of truth for your notification templates for a number of reasons:
- **A consistent editing experience.** When you manage all of your templates in Knock, your content authors have access to a unified template editor for a consistent experience across all delivery channels. Teams who collaborate on messaging can work with a single templating language (Liquid) for dynamic content.
- **Cross-channel engagement analytics.** With Knock [link and open tracking](/send-notifications/tracking) in your message templates, you have access to cross-channel engagement analytics for each of your notification use cases in a centralized tool.
- **Unlock greater efficiency.** In the same way that Knock combines the logic and delivery of all of your notifications into a single API, using Knock as the source of truth for your templates means streamlining your process for cross-functional work on notifications. All changes to your message content, regardless of delivery channel, will follow the same steps for previewing, testing, and committing updates to production.
- **Work with your templates programmatically.** With our [Management API](/mapi-reference) or [CLI](/cli/overview), you can work with all of your cross-channel templates as code via a single API. This enables you to integrate your templates with other tools, automate updates, and more.
- **Reusable content blocks.** Our [Partials](/template-editor/partials) feature allows you to create content blocks of various types that can be reused across all of your notification templates. This enables updates across all delivery channels with a single change when necessary.
- **Reference data from other resources stored in Knock.** In addition to the context that you pass to Knock on your workflow trigger calls and [reference as dynamic content](/template-editor/variables) in your notifications (like `recipient` and `tenant` properties, or custom `data` payload variables), the Knock template editor also allows you to [reference data](/template-editor/referencing-data) from any Users, Objects, and Tenants that exist within your Knock environment.
Referencing data is a powerful way to share context across entities in your templates without needing to manually pass the data in the `data` argument of your workflow trigger, and isn't possible with other templating solutions.
## Email templates
Learn how to work with email templates in Knock.
---
title: Email templates
description: Learn how to work with email templates in Knock.
tags:
[
"email",
"templates",
"notifications",
"email templates",
"email template editor",
"email template builder",
"email template designer",
"wysiwyg editor",
"visual editor",
"drag-and-drop editor",
]
section: Working with templates
---
Knock has full support for building rich email templates to power your transactional, lifecycle, and marketing emails. Teams use Knock's powerful component features to build email design systems and empower their product and marketing teams to create consistent, brand-compliant emails.
## Layouts and templates
When you use Knock to power your email notifications, you use two main concepts to build the notifications that will be sent to your users: layouts and templates.
The **layout** typically includes the header and footer of your email, as well as any other HTML or CSS that will be used across all (or multiple) templates. You can think of your email layout as the "frame" of your email notifications, where you define the shared structure and styles once for all your email notifications so they can look and feel consistently without having to repeat them in every template.
The **template** is the actual body and content of your email. When you add an email step to a workflow, the content that you edit within the template editor is the template that will be wrapped by the layout mentioned above. Under the hood, Knock is injecting this template into the `{{content}}` variable of the email layout.
Here's an example of a transactional email we send at Knock, complete with the template content merged into the layout. The area shaded in green is the template. The area shaded in blue is the layout.
When working with email templates, you can select the email layout that will be used by navigating the the "Template settings" modal.
[Learn more about working with layouts](/integrations/email/layouts).
## Visual editing with drag-and-drop components
Knock's email template editor includes a visual editor you can use to compose your template with drag-and-drop components. By default, Knock comes with a number of prebuilt components that you can use to compose your template (e.g. buttons, dividers, text, images, etc.).
Using [HTML partials](/template-editor/partials/html-partials), you can extend the components available in the visual editor with your own custom components.
## Working with templates in the code editor
In addition to the visual editor, you can also work with email templates in the code editor. This gives you full control over the HTML and CSS of your email templates, and is useful for more complex use cases.
You can enter the code editor by clicking the "Code editor" button in the top right of the template editor. Note: when in code editor, switching to the visual editor will not preserve any changes you've made.
## Working with partials in email templates
[Partials](/template-editor/partials) are reusable pieces of content you can use across any of your templates, including email templates. Partials can be HTML blocks that can also be shown as blocks in the visual editor. This allows your team to create a library of "components" for an email design system.
[Learn more about working with HTML partials](/template-editor/partials/html-partials).
## Previewing email templates
You can preview your email templates in the right hand preview pane in the template editor. This preview will show you how your email template will look when sent to a recipient.
### Client-specific previews
Knock provides client-specific previews of your email templates, powered by Litmus. This allows you to see how your email template will look in different email clients including Gmail, Outlook, and Apple Mail using our [Email client previews](/integrations/email/client-previews) feature.
## Frequently asked questions
Yes. Knock supports MJML for both email layouts and templates. You can use
MJML in the code editor or via the visual block editor. See the [MJML
support](/integrations/email/mjml) docs for details.
## Variables
A reference for the variables available in the Knock template editor.
---
title: "Template variables"
description: "A reference for the variables available in the Knock template editor."
tags: ["liquid", "template", "variables"]
section: Working with templates
---
When you build workflows in Knock, we auto-generate certain pieces of state (as a result of batch functions and other workflow steps) that you can use to control the copy you display to your end users in your notification templates.
| Variable | Description |
| ------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `activities` | A list of the activity objects included within the batch, where each activity equals the state sent across in your trigger call, and also includes the actor who performed the message and a timestamp of when the activity occurred. |
| `actor` | A serialized `Recipient` of the actor that triggered the workflow (may be `null`). Will include any custom properties set. |
| `actors` | A list of up to 10 of the unique actors included within the batch. |
| `current_message` | A serialized `CurrentMessage` (see below). |
| `data` | The complete data passed to the workflow trigger. |
| `recipient` | A serialized `Recipient` of the recipient of the workflow. Will include any custom properties set. |
| `tenant` | A serialized `Tenant` (see below) which is set when a `tenant` is passed to the workflow trigger. |
| `timestamp` | The time in which the activity occurred, as an ISO-8601 datetime string. |
| `total_activities` | The count of activities associated with a workflow run. |
| `total_actors` | The count of unique actors associated with a workflow run. |
| `vars` | Account and environment-specific variables. |
| `workflow` | A serialized `Workflow` (see below). |
all of the data supplied to your workflow trigger is always
available for use in your template under the data key.
}
/>
### Recipient (User or Object)
A serialized `User` or `Object`. The properties available are:
| Variable | Description |
| --------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `__typename` | Either `User` or `Object` |
| `id` | The id of the recipient |
| `collection` | The collection of the object (only set for `Object` recipients) |
| `*` | Any custom properties set |
| `created_at` | A datetime field for when the recipient was created (if set) |
| `updated_at` | A datetime field for when the recipient was last updated |
| `subscription` | An optional set of properties set on a `subscription`. Only available when a workflow is triggered via a [Subscription](/concepts/subscriptions). |
| `subscription.object` | The serialized `Object` that the recipient is subscribed to. Will include any custom properties set. Only available when a workflow is triggered via a [Subscription](/concepts/subscriptions). |
| `schedule` | A serialized `Schedule` including the `id`, `last_occurrence_at`, and `next_occurrence_at` of the schedule. Only available when a workflow is triggered via a [Schedule](/concepts/schedules). |
| `preferences` | The preference set for the recipient. Will contain a completely resolved `PreferenceSet` object, including tenant and environment defaults. |
### Activity
A serialized `Activity`, which represents a workflow trigger for the recipient. Activities may be accumulated during a batch operation. The properties available are:
| Variable | Description |
| ------------- | -------------------------------------------------- |
| `id` | The unique id of the activity |
| `*` | Trigger data sent that generated the activity |
| `inserted_at` | The datetime of when the activity was generated |
| `updated_at` | The datetime of when the activity was last updated |
### CurrentMessage
Provides access to the currently generated `Message` that the template is rendered against. The properties available are:
| Variable | Description |
| ------------- | ------------------------------------------------- |
| `id` | The id of the message |
| `inserted_at` | The datetime of when the message was created |
| `updated_at` | The datetime of when the message was last updated |
### Workflow
Provides access to serialized properties about the currently executing workflow. The properties available are:
| Variable | Description |
| ---------------------- | ------------------------------------------------------------------------------------------- |
| `id` | The id of the version of the current workflow |
| `key` | The unique key of the workflow |
| `categories` | A list of categories set for the workflow |
| `commercial` | Whether the workflow is marked as commercial messaging |
| `override_preferences` | Whether the workflow is configured to ignore recipient preferences and send to all channels |
### Tenant
A serialized `Tenant`. The properties available are:
| Variable | Description |
| ---------------------- | --------------------------------------------------------- |
| `id` | The id of the tenant |
| `*` | Any custom properties set on the tenant |
| `settings.preferences` | The default preferences set for the tenant. |
| `settings.branding` | The branding set for the tenant. |
| `created_at` | A datetime field for when the tenant was created (if set) |
| `updated_at` | A datetime field for when the tenant was last updated |
## Referencing data
Documentation outlining how to work with data in your templates.
---
title: "Referencing data in templates"
description: Documentation outlining how to work with data in your templates.
tags: ["liquid", "template", "objects", "users", "tenants", "subscriptions"]
section: Working with templates
---
In addition to the [variables](/template-editor/variables) available as part of the workflow run scope, you can also reference data from the users, objects, tenants, and subscriptions that exist within your Knock environment.
Referencing data is a powerful way to share context across entities in your templates without needing to manually pass the data in the `data` argument of your workflow trigger.
The user, object, tenant, and{" "}
subscriptions filters all dynamically load data from your
Knock environment at render time. You can find a full reference of these
filters in the{" "}
Liquid helpers reference
.
}
/>
## Referencing users via the `user` filter
To reference a user, you can use the `user` filter. This will return a serialized `User`, which you can then use to output data in your template.
Users returned will have all custom properties available, as well as the `id`, `name`, `email`, `phone_number`, `created_at`, and `updated_at` properties.
```liquid title="Referencing a user via a static identifier"
{% assign user = "chris" | user %}
```
```liquid title="Referencing a user via a dynamic identifier"
{% assign user = data.other_user_id | user %}
```
## Referencing objects via the `object` filter
To reference an object, you can use the `object` filter. This will return a serialized `Object`, which you can then use to output data in your template. When referencing an object, you'll also need to specify the `collection` of the object you're loading.
Objects returned will have all custom properties available, as well as the `id`, `collection`, `created_at`, and `updated_at` properties. Read more about [working with objects](/concepts/objects).
```liquid title="Referencing an object in the 'projects' collection via a static identifier"
{% assign project = "proj_1" | object: "projects" %}
```
```liquid title="Referencing an object in the 'projects' collection via a dynamic identifier"
{% assign project = data.project_id | object: "projects" %}
```
If you're looking to reference the parent object that the recipient is
subscribed to when they are notified via a{" "}
subscription, you can use the{" "}
recipient.subscription.object property.
}
/>
## Referencing tenants via the `tenant` filter
To reference a tenant, you can use the `tenant` filter. This will return a serialized `Tenant`, which you can then use to output data in your template.
Tenants returned will have all custom properties available, as well as the `id`, `created_at`, and `updated_at` properties. Read more about [working with tenants](/concepts/tenants).
```liquid title="Referencing a tenant via a static identifier"
{% assign tenant = "acme" | tenant %}
```
```liquid title="Referencing a tenant via a dynamic identifier"
{% assign tenant = data.other_tenant_id | tenant %}
```
## Referencing subscriptions via the `subscriptions` filter
To reference the subscriptions for a user, you can use the `subscriptions` filter. This filter loads up to 25 active subscriptions for the given user and returns a list of serialized subscription objects.
Each subscription returned includes the `object` the user is subscribed to, along with any custom `properties` set on the subscription. You can iterate over the results to render subscription-specific content in your templates.
```liquid title="Loading subscriptions for the current recipient"
{% assign subs = recipient.id | subscriptions %}
{% for sub in subs %}
{{ sub.object.id }} - {{ sub.properties.role }}
{% endfor %}
```
```liquid title="Loading subscriptions for a user via a dynamic identifier"
{% assign subs = data.user_id | subscriptions %}
{% for sub in subs %}
{{ sub.object.id }}
{% endfor %}
```
## Frequently asked questions
If you reference a user, object, or tenant that doesn't exist, the value will be `null` in your template. Trying to use it to output data will return an empty string.
If you want to conditionally display data based on whether a user, object, or tenant exists, you can do so using Liquid's `if` statement.
Knock cannot constrain the entities that are available in your template based on the recipient of the workflow run or the tenant passed in. It is your responsibility to ensure that any entities loaded as part of executing a template are accessible to the recipient.
## Partials
## Overview
Learn how to create reusable pieces of content using partials.
---
title: Partials
description: Learn how to create reusable pieces of content using partials.
tags:
["partials", "templates", "custom blocks", "message templates", "workflows"]
section: Working with templates
---
Partials are reusable pieces of content you can use across any of your channel templates. [HTML partials](/template-editor/partials/html-partials) can be enabled as "blocks" for use in Knock's drag-and-drop email editor.
In this page, we'll walk through how to create partials and use them in your templates using Knock's code editor or visual editor.
## Managing partials
### Creating and editing partial properties
To get started, navigate to **Content** > **Partials** in the main sidebar where you can create a new partial.
When creating or editing partials, you can use the following properties:
| Property | Description |
| ------------- | ------------------------------------------------------------------------------------------------------------------- |
| `Name` | A name for your partial. |
| `Key` | A unique key for your partial. Cannot be edited after creation. |
| `Type` | The type of content you want to create. One of HTML, markdown, plaintext, or JSON. Cannot be edited after creation. |
| `Description` | An optional description of your partial. |
| `Is block` | Whether or not to enable this partial as a block within the visual editor (HTML partials only). |
| `Icon name` | An icon to display for this partial within the visual editor. |
Partials are environment-specific and follow the same [version control model](/version-control/commits) as the rest of Knock.
### Creating partial content
After creating a partial, you can edit its content in the code editor.
You can include Liquid variables in your content which will be scoped to your partial. When using the partial in a template, you can pass in values for these variables. To include a variable in your partial, use the following syntax: `{{ variable_name }}`.
Partials must be committed (or promoted) before they can be used by
templates in a given environment. Templates will always use the published
version of a partial.
If you're using a partial that is not yet committed while editing a template,
you will not see your latest changes.
}
/>
### Updating existing partial content
To update the content of an existing partial, you can return to the partial's code editor.
When you commit or promote your changes, they will be immediately applied to all templates that use the partial in that environment. If you add or remove variables from your partial, you'll want to be sure to update the input values for those variables in any layouts or message templates that use your partial before promoting your changes to higher environments.
### Archiving partials
Partials can be archived from the "Partials" page or from a specific partial's details page.
If an archived partial is used in a template, it will continue to render
until the workflow containing that template is published again.
After the workflow has been published, the partial will not render in your
messages.
}
/>
## Using partials in templates
Partials can be used in templates with the code editor or visual editor. You can also include partials in other partials. Knock will render partials recursively up to a maximum depth of 5.
This means that booleans, lists, and other JSON values will be treated as
strings when passed directly as a partial input value.
If you use an HTML partial that is enabled as a block, you can create an optional{" "}
schema for your partial
to set input types other than plaintext, like JSON. See the
frequently asked questions
below for common implementation patterns for working with structured data
in a partial.
}
/>
### In the code editor
Use partials by using the render tag with the following syntax: `{% render 'partial_key' %}`. You can also use the partial button in the toolbar to insert a partial.
Pass variables into your partial using the following syntax: `{% render 'partial_key', variable_name: 'value' %}`. You can pass in plaintext values or Liquid expressions like `{% render 'partial_key', variable_name: data.variable_name %}`.
The Knock render tag does not support the `for` and `with` modifiers.
To replicate the `for` modifier, use the Liquid `for` block.
```liquid title="Partials in a loop"
{% for item in data.items %}
{% render 'partial_key', variable_name: item.value %}
{% endfor %}
```
To replicate the `with` modifier, use the `{% assign %}` tag to re-assign a variable.
```liquid title="Alternative to the 'with' modifier"
{% assign item = data.item %}
{% render 'partial_key', variable_name: item.value %}
```
### In the visual editor
[HTML partials](/template-editor/partials/html-partials) can be used in the visual editor if they are enabled as blocks. Add a partial to your template by dragging it from the "Custom blocks" section of the sidebar into the template.
Click a custom block to open the inspect panel to edit variable values. You can enter a plaintext value or a Liquid expression like `{{ data.variable_name }}`.
## Frequently asked questions
To use a partial in the visual editor, it must be an HTML partial and enabled as a block.
Partials must be committed before they can be used
by templates in a given environment. Templates will always use the
published version of a partial.
If you're using a partial that is not yet committed while editing a template, you will not see your latest changes.
Because partial variable inputs are treated as plaintext values by default, you need to take an extra configuration step to directly pass a JSON object or array of items to a partial variable and then iterate over them within the partial's content.
You have two options, depending on your use case:
**1. Create a schema for your HTML partial and set the variable's input type to list or JSON.**
When you create a [schema](/template-editor/partials/schema-reference) for your HTML partial, you can pick an input type that preserves the structure of the data passed in:
- Use the [`list`](/template-editor/partials/schema-reference#list) input type when you want to pass an array of items (for example, a list of products or line items).
- Use the [`json`](/template-editor/partials/schema-reference#json) input type when you want to pass a single object (for example, a user profile or other structured payload).
**Working with a list of items**
If you want a partial to render a list of items, you can define a `list` field in your schema and pass your array to the partial input.
```json title="A schema for an HTML partial's 'items' variable"
[{
"type": "list",
"key": "items",
"label": "Items list",
"settings": {
"required": true,
"description": "A list of items to render",
"itemSchema": {
"type": "object",
"properties": {
"name": { "type": "string" },
"value": { "type": "string" }
},
"required": ["name", "value"]
}
}
}]
```
```liquid title="Passing a list of items to the partial's 'items' input"
{{ data.items_list }}
```
Then, in the partial you can iterate over the items directly:
```liquid title="Partial content with a list of items"
{% for item in items %}
{{ item.name }}: {{ item.value }}
{% endfor %}
```
**Working with a single JSON object**
If you want a partial to render a single structured object, you can define a `json` field in your schema and pass your object to the partial input.
```json title="A schema for an HTML partial's 'user' variable"
[{
"type": "json",
"key": "user",
"label": "User",
"settings": {
"required": true,
"description": "The user profile to render",
"schema": {
"properties": {
"name": { "type": "string" },
"email": { "type": "string" },
"company": { "type": "string" }
},
"required": ["name", "email"]
}
}
}]
```
```liquid title="Passing an object to the partial's 'user' input"
{{ recipient }}
```
Then, in the partial you can reference the object's properties directly:
```liquid title="Partial content with a JSON object"
Hello {{ user.name }}
Email: {{ user.email }}
{% if user.company != blank %}
Company: {{ user.company }}
{% endif %}
```
You can follow a similar pattern for working with your full `data` payload, `recipient`, or other object [variables](/template-editor/variables) that are available in the workflow run scope; pass a Liquid reference to the variable into the partial input (i.e. `{{ data }}`), then reference the object's properties within the partial content.
**2. Use Knock's Liquid helpers to transform your input data into a JSON string.**
For use cases where you don't want to create a schema or you want to pass JSON into a different input type, you can use Knock's `json` [Liquid helper](/template-editor/reference-liquid-helpers) to transform your input data into a JSON string. Then, you can use the `from_json` helper within your partial to transform the JSON string back into a Liquid object that you can reference.
For example, if you want a partial to render a list of items, you can pass your list to the partial input like this:
```liquid title="Transforming your input data into a JSON string"
{{ data.items_list | json }}
```
You can provide the logic to convert the JSON string back into a Liquid object and iterate over the items within your partial:
```liquid title="Partial content with deserialized structured data"
{% assign items = input | from_json %}
{% for item in items %}
{{ item.name }}: {{ item.value }}
{% endfor %}
```
Yes! However, you'll need to be careful with how you configure them in your partial to ensure that they evaluate the way you expect.
Because variable inputs for partials are plaintext values by default, booleans will be interpreted as strings when passed directly into a partial. This means that an input value of the boolean `false` will be treated as the string `"false"` in your partial's content, which evaluates as truthy in Liquid.
If you're working with an HTML partial and you create a [schema](/template-editor/partials/schema-reference), you can set your variable's input type to `json`. This will preserve the `true` or `false` boolean value that is passed in.
For any other input type, you can use the `from_json` [Liquid helper](/template-editor/reference-liquid-helpers) to transform the input string back into a boolean value:
```liquid title="Use a boolean value in a partial"
{% assign boolean_value = input | from_json %}
{% if boolean_value %}
The value is true.
{% endif %}
```
Alternatively, you can use a Liquid expression to check the string value of the boolean input:
```liquid title="Check a dynamic string value in a partial"
{% if boolean_value == "true" %}
The value is true.
{% endif %}
```
Because empty strings are also truthy in Liquid, if you'd like to check whether or not a value was provided to a partial at runtime you can use the `blank` object:
```liquid title="Check if an input value exists"
{% if input_value != blank %}
The input value is not an empty string.
{% endif %}
```
Not directly. Liquid variables in your partials are scoped to the partial itself, and serve as placeholders for values that you'll configure within your message templates that use the partial.
To reference [variables](/template-editor/variables) like `recipient`, `current_message`, or `workflow` within a partial, you can use a placeholder variable in your partial and configure the input value in the template editor to reference these values.
```liquid title="Use a recipient property in a partial"
{% render 'partial_key', recipient_name: recipient.name %}
```
See the FAQ above on how to reference structured data (like a full `recipient` object) in a partial.
## HTML partials
Learn how to create reusable pieces of content using HTML partials.
---
title: HTML partials
description: Learn how to create reusable pieces of content using HTML partials.
tags:
["partials", "templates", "custom blocks", "message templates", "workflows"]
section: Working with templates
---
HTML partials are reusable components that can be used across any of your email templates. You can use HTML partials in Knock to create an email design system to empower your product and marketing teams to create consistent, brand-compliant emails.
HTML partials must contain HTML and cannot include MJML markup. When an
HTML partial is used inside an MJML template, Knock wraps the partial's
content in <mj-raw> tags automatically. See the{" "}
MJML support docs for details.
}
/>
Learn more about partials in the [Partials overview](/template-editor/partials/overview) page.
## Enabling HTML partials as blocks
In Knock's visual email editor, blocks are the building blocks you use to compose your email templates. By default, Knock comes with a number of prebuilt blocks (e.g. buttons, dividers, text, images, etc.). You can extend these with your own custom HTML partials by enabling them as blocks.
To enable an HTML partial as a block, you can set the "Enable as block" property when creating or editing the partial. Enabling as a block will ensure that the partial is displayed in the blocks menu in the visual editor.
When enabling a partial as a block, you can also set the icon that's displayed for the partial in the visual editor.
You can also disable any of the prebuilt HTML blocks that come with Knock
by going to Settings > Templates.
}
/>
## Schemas for HTML partials
HTML partials support the ability to include schemas that define the fields that can be used in the partial. If you're used to a component way of thinking, you can think of the schema as the "props" for the partial.
You can create a schema for an HTML partial by clicking the "Edit schema" button in the partial overview page. The schema editor allows you to define the fields that are displayed in the partial's block in the visual editor.
```json title="An example schema for an HTML partial"
[
{
"type": "text",
"key": "title",
"label": "Title"
},
{
"type": "boolean",
"key": "show_warning",
"label": "Show warning icon"
},
{
"type": "select",
"key": "icon",
"label": "Icon",
"settings": {
"options": [
{ "label": "Skull", "value": "skull-icon.svg" },
{ "label": "Heart", "value": "heart-icon.svg" }
],
"default": "skull-icon.svg"
}
}
]
```
Read more about the schema reference for HTML partials in the [Partial schema reference](/template-editor/partials/schema-reference) page.
## Editing HTML partial content
HTML partials display a preview alongside the editor. Open the preview by clicking the "Preview" button or using the `Cmd + ]` keyboard shortcut on Mac, or `Ctrl + ]` on Windows.
- Select an [email layout](/integrations/email/layouts) to preview the partial within.
- Use the `
This is a partial CSS example.
```
When you include this partial in an email template, either via a render tag or as a block in the visual editor, the CSS from this partial will be extracted and included at the top of the `` of the compiled email template. Styles are deduplicated and are only included at-most once in the final email template.
## Frequently asked questions
Because Knock hoists `
```
Do this:
```html title="Correct usage of Liquid variables inside
```
## Schema reference
Learn more about partial schemas and available fields for partials.
---
title: Partial schema reference
description: Learn more about partial schemas and available fields for partials.
tags:
["partials", "templates", "custom blocks", "message templates", "workflows"]
section: Working with templates
---
When using [HTML partials](/template-editor/partials/html-partials), you can create an optional schema for your partial to set field types, default values, and require inputs for variables that are passed into the partial.
Partial schemas support the following field types:
## Fields
All fields must have:
- `type`: The type of the field to render (see below)
- `key`: A unique key for the field in the variant
- `label`: A label to render
## Field types
### Text
A plain text, single line text field.
#### Settings
- **required** (`boolean`) - Indicates this field is required
- **description** (`string`) - An optional friendly description
- **default** (`string`) - The default value to display
- **minLength** (`integer`) - The minimum length to validate
- **maxLength** (`integer`) - The maximum length to validate against
**Example**
```json
{
"type": "text",
"key": "title",
"label": "Title",
"settings": {
"required": true,
"default": "Card title",
"minLength": 3,
"maxLength": 32
}
}
```
### Markdown
A markdown editor for creating rich text. Will always be rendered as HTML.
#### Settings
- **required** (`boolean`) - Indicates this field is required
- **description** (`string`) - An optional friendly description
- **default** (`string`) - The default value to display
#### Example
```json
{
"type": "markdown",
"key": "body",
"label": "Body",
"settings": {
"default": "**Default markdown**"
}
}
```
### Textarea
A multi-line plain text area
#### Settings
- **required** (`boolean`) - Indicates this field is required
- **description** (`string`) - An optional friendly description
- **default** (`string`) - The default value to display
- **minLength** (`integer`) - The minimum length to validate
- **maxLength** (`integer`) - The maximum length to validate against
#### Example
```json
{
"type": "textarea",
"key": "body",
"label": "Body",
"settings": {
"default": "My body"
}
}
```
### Boolean
A checkbox that returns either true or false (checked or unchecked).
#### Settings
- **required** (`boolean`) - Indicates this field is required
- **description** (`string`) - An optional friendly description
- **default** (`boolean`) - The default value to set
#### Example
```json
{
"type": "boolean",
"key": "dismissable",
"label": "Can be dismissed?",
"settings": {
"default": true
}
}
```
### Number
A numeric input field with optional min/max bounds and a unit label shown next to the input.
#### Settings
- **required** (`boolean`) - Indicates this field is required
- **description** (`string`) - An optional friendly description
- **placeholder** (`string`) - An optional placeholder to display in the input
- **default** (`number`) - The default numeric value
- **min** (`number`) - The inclusive minimum allowed value
- **max** (`number`) - The inclusive maximum allowed value
- **unitLabel** (`string`) - A short label shown after the input (e.g. `px`, `kg`)
#### Example
```json
{
"type": "number",
"key": "ship_number",
"label": "Ship number",
"settings": {
"description": "Displayed next to the hull ID",
"placeholder": "0",
"required": true,
"default": 42,
"min": 0,
"max": 999999,
"unitLabel": "TEU"
}
}
```
### Color
A hex color input field that accepts values in `#RGB` or `#RRGGBB` format. Editors can also pick a color from the [branding variables](/template-editor/branding) defined on the environment, in which case the value is stored as a reference to that variable (e.g. `{{ vars.branding.primary_color }}`).
#### Settings
- **required** (`boolean`) - Indicates this field is required
- **description** (`string`) - An optional friendly description
- **placeholder** (`string`) - An optional placeholder to display in the input
- **default** (`string`) - The default hex color value
#### Example
```json
{
"type": "color",
"key": "accent_color",
"label": "Accent color",
"settings": {
"description": "A hex color for the accent",
"placeholder": "#000000",
"required": true,
"default": "#FF0000"
}
}
```
### Select
A single select box that defines a static list of options for editors to pick from.
#### Settings
- **options** (`object[]`) - A list of option objects that must include a `label` and a `value`
- **required** (`boolean`) - Indicates this field is required
- **default** (`string`) - The value of the default option to set
#### Example
```json
{
"type": "select",
"key": "icon",
"label": "Icon",
"settings": {
"options": [
{ "label": "Skull", "value": "skull-icon.svg" },
{ "label": "Heart", "value": "heart-icon.svg" }
],
"default": "skull-icon.svg"
}
}
```
#### Usage
In your template preview, you can access the `value` of the selected option using the field's `key`. For example:
```liquid title="Accessing the selected value"
```
### Multi-select
A multi-select box that defines a static list of options for editors to pick from.
#### Settings
- **options** (`object[]`) - A list of option objects that must include a `label` and a `value`
- **required** (`boolean`) - Indicates this field is required
- **default** (`string[]`) - The values of the default options to set
#### Example
```json
{
"type": "multi_select",
"key": "icons",
"label": "Icons",
"settings": {
"options": [
{ "label": "Skull", "value": "skull-icon.svg" },
{ "label": "Heart", "value": "heart-icon.svg" },
{ "label": "Star", "value": "star-icon.svg" }
],
"default": ["skull-icon.svg", "heart-icon.svg"]
}
}
```
#### Usage
In your template preview, you can access the selected values using the field's `key`. For example:
```liquid title="Accessing the selected values"
{% for icon in icons %}
{% endfor %}
```
### Button
A button, with text to display and an action to perform when clicked.
Every button field contains two subfields:
- **text** (`string`) - A text field that represents the button's text
- **action** (`string`) - A text field that represents the button's action
#### Settings
- **required** (`boolean`) - Indicates this field is required
- **description** (`string`) - An optional friendly description
#### Example
```json
{
"type": "button",
"key": "primary_button",
"label": "Primary button",
"text": {
"type": "text",
"key": "text",
"label": "Button text",
"settings": {
"required": true,
"default": "Learn more"
}
},
"action": {
"type": "text",
"key": "action",
"label": "Button action",
"settings": {
"required": true,
"default": "https://example.com/"
}
},
"settings": {
"required": true
}
}
```
### URL
#### Settings
- **required** (`boolean`) - Indicates this field is required
- **description** (`string`) - An optional friendly description
- **default** (`string`) - The default URL to display
#### Example
```json
{
"type": "url",
"key": "contact_url",
"label": "Contact link",
"settings": {
"required": true,
"default": "https://example.com/"
}
}
```
### Image
An image field, used to display an image with alt text and an optional action to perform when clicked.
Every image field contains three subfields:
- **url** (`string`) - A URL field that represents the source of the image to be displayed
- **alt** (`string`) - A text field that represents the image's alt text
- **action** (`string`) - An optional text field that represents an action to perform when the image is clicked
#### Settings
- **required** (`boolean`) - Indicates this field is required
- **description** (`string`) - An optional friendly description
#### Example
```json
{
"type": "image",
"key": "hero_image",
"label": "Hero image",
"url": {
"type": "url",
"key": "url",
"label": "Image URL",
"settings": {
"required": true,
"default": "https://example.com/image.png"
}
},
"alt": {
"type": "text",
"key": "alt",
"label": "Image alt text",
"settings": {
"required": true,
"default": "Lorem ipsum"
}
},
"action": {
"type": "text",
"key": "action",
"label": "Image action",
"settings": {
"required": true,
"default": "https://example.com/"
}
},
"settings": {
"required": true
}
}
```
### JSON
A JSON input field with schema validation.
#### Settings
- **required** (`boolean`) - Indicates this field is required
- **description** (`string`) - An optional friendly description
- **default** (`json`) - The default value of the JSON field
- **schema** (`object`) - A [JSON Schema](https://json-schema.org/) object that validates the expected structure of the input. Supports `properties` to define the expected keys and their types, and `required` to specify which keys must be present.
#### Example
```json
{
"type": "json",
"key": "data",
"label": "Data",
"settings": {
"description": "A description of the JSON field",
"required": true,
"default": { "key": "value" },
"schema": {
"properties": {
"key": { "type": "string" }
},
"required": ["key"]
}
}
}
```
### List
A list of items, with an optional JSON Schema that validates the structure of each item in the list.
#### Settings
- **required** (`boolean`) - Indicates this field is required
- **description** (`string`) - An optional friendly description
- **default** (`array`) - The default list value
- **itemSchema** (`object`) - A JSON Schema object that validates the structure of each item in the list.
#### Example
```json
{
"type": "list",
"key": "faqs",
"label": "FAQs",
"settings": {
"description": "Frequently asked questions",
"required": true,
"default": [],
"itemSchema": {
"type": "object",
"properties": {
"question": { "type": "string", "title": "Question" },
"answer": { "type": "string", "title": "Answer" }
},
"required": ["question", "answer"]
}
}
}
```
#### Usage
When a list input is referenced in a template, its value is decoded into a Liquid array so you can iterate over it and access each item's fields.
The most common pattern is to loop over the items:
```liquid title="Iterating over a list field"
{% for faq in faqs %}
{{ faq.question }}
{{ faq.answer }}
{% endfor %}
```
You can also access a single item by index:
```liquid title="Accessing a list item by index"
{{ faqs[0].question }}
```
Note that printing the array directly with `{{ faqs }}` only works when the items are primitives (strings, numbers). For lists of objects, use the `json` filter to render the full value:
```liquid title="Rendering a list of objects"
{{ faqs | json }}
```
## Example usage
Here's an example of a partial schema, and using it in a template.
```json title="A partial schema example"
[
{
"type": "text",
"key": "title",
"label": "Title"
},
{
"type": "image",
"key": "image",
"label": "Image"
},
{
"type": "boolean",
"key": "show_button",
"label": "Show button"
},
{
"type": "button",
"key": "primary_button",
"label": "Primary button",
"text": {
"type": "text",
"key": "text",
"label": "Button text",
"settings": {
"required": true,
"default": "Learn more"
}
},
"action": {
"type": "text",
"key": "action",
"label": "Button action",
"settings": {
"required": true,
"default": "https://example.com/"
}
},
"settings": {
"required": true
}
}
]
```
```liquid title="Using a partial schema in a template"
```
## Frequently asked questions
It's important to note that when you define a schema for your partial, each
field will have a default value.
If you don't set an explicit default value, the default will be set according
to the field type. When working with string-based fields like `Text`, `Textarea`, and `Markdown`,
the default will be an empty string (`""`).
In Liquid, an empty string is considered truthy, so if you want to render content in your partial based on whether an input is provided for that field, you should use a Liquid condition to check if the field is not empty.
```liquid title="Patterns for conditionally rendering content based on whether a text field has a provided input"
// render a heading if the user provides a title field input
{% if title != "" %}
{{ title }}
{% endif %}
// alternatively, you can use the `blank` object:
{% if title != blank %}
{{ title }}
{% endif %}
```
For `Boolean` fields, you can simply check the truthiness of the input with an `if` statement:
```liquid title="Pattern for conditionally rendering content based on a boolean input"
{% if show_button %}
{{ primary_button.text }}
{% endif %}
```
## Branding
Learn how to use branding to customize the look and feel of your notifications.
---
title: Branding
description: Learn how to use branding to customize the look and feel of your notifications.
tags:
[
"branding",
"templates",
"email",
"notifications",
"brand colors",
"brand fonts",
"brand images",
"brand logos",
"brand icons",
]
section: Working with templates
---
## Set custom branding
Account members with `admin` or `owner` roles can set branding for an account under the **Settings** > **Branding** page in the Knock dashboard. From here, you can set the logo, icon, primary color, and primary contrast color.
It's also possible to set any number of custom branding properties as key-value pairs by clicking the "Add variable" button, or by using the bulk editor to set multiple variables at once.
Any branding variables you set will be available under the `vars.branding.*` namespace in your templates, layouts, and HTML partials.
## Per-tenant branding
Knock supports setting custom branding for each tenant, via the dashboard or programmatically via the API. Using per-tenant branding lets you override the account-level branding for all messages sent within the context of that tenant.
[Learn more about working with tenants](/concepts/tenants).
## Using branding variables in templates
Once you've set your branding variables, you can use them within your templates using the `vars.branding.*` namespace. These variables are available in your templates, layouts, and HTML partials.
```liquid title="Using a branding variable in CSS"
```
## Translations (i18n)
Learn how to use translations to localize your notifications.
---
title: Translations
description: Learn how to use translations to localize your notifications.
tags:
[
"translation",
"translations",
"translate",
"locale",
"localization",
"l10n",
"how knock works",
"language",
"i18n",
"internationalization",
]
section: Working with templates
---
[Translations](/mapi-reference/translations) localize the notifications you send with Knock.
## Get started
Translations are only available on our{" "}
Enterprise plan
.
}
/>
To get started, enable translations for your account. Go to "Settings" under your account name in the left sidebar and click "Enable translations".
Next you'll need to set a default `locale`. Knock uses the default `locale` when it can't find a translation for a given recipient's `locale`.
Once you've set your default `locale`, you should see a new "Translations" page under "Content" in the sidebar. This is where you'll be working with your translations.
## Basic usage
[Translations](/mapi-reference/translations/schemas/translation) are JSON objects that contain the text for your messages in various locales. For example, let's say you have a customer order notification that you want to localize for French and English users.
```json title="en translation"
{
"OrderReady": "Your order is ready.",
"OrderDelayed": "Your order is delayed."
}
```
```json title="fr translation"
{
"OrderReady": "Votre commande est prête.",
"OrderDelayed": "Votre commande est retardée."
}
```
Once you have those translations created for the `en` and `fr` locales, you can reference their translation strings in your message templates using the `t` filter:
```json title="Message template editor"
{{ "OrderReady" | t }}
```
Your users must have a `locale` property set for the helper to find translations in their locale, otherwise Knock will use the default locale. You can set a user's `locale` with the [identify endpoint](/api-reference/users/update).
## Translation methods
There are two methods available to you to translate your message templates: the `t` filter and the `t` tag.
### The `t` filter
The `t` filter is used to reference existing translation files. It works best when you have translations that are already created and you want to reference them in your message templates.
```json title="Using t filter in a message template"
{{ "congratulationsMessage" | t: recipientName: recipient.name }}
```
In the example above, the `t` filter finds the recipient's `locale` and looks for the `congratulationsMessage` key in the translation file for that locale. It then replaces the `recipientName` variable with the recipient's name.
### The `t` tag
The `t` tag is used to write templates in their default language and automatically generate translations for additional locales. It is best when you have less technical users authoring templates, and you want to automatically generate translations for their templates behind the scenes.
```json title="Using t tag in a message template"
{% t %}Congratulations, {{ recipient.name }}!{% endt %}
```
In the example above, we author content in our English default language, wrap that content in our `t` tag, and Knock automatically generates translation files for us behind the scenes.
We cover how to use the `t` filter and `t` tag in more detail below.
## Using the `t` filter
You can use `t` filter to reference your translations from within a message template. The `t` filter also allows you to use variables, other filters, and special pluralization rules.
### Variables and interpolation
You can use variable interpolation in your translations.
```json title="en translation"
{
"comment": "New comment from {{ actorName }} on your post {{ postName }}.",
"like": "{{ actorName }} liked your photo {{ photoTitle}}!"
}
```
You can pass variables to the `t` filter:
```json title="Message template editor"
```
### Pluralization
Translations support pluralization rules. When you pass the `count` variable to a translation, it looks for pluralization keys in your translation. Those keys are `zero`, `one`, and `other`. You don't need to reference these in the template. If you pass the `count` variable, it will evaluate it and choose one for you.
```json title="en translation"
{
"orders": {
"shipping": {
"zero": "You have no orders currently being shipped.",
"one": "You have one order being shipped.",
"other": "You have {{ count }} orders being shipped."
}
}
}
```
To pluralize content in a message template, pass the `count` variable:
```json title="Message template editor"
{{ "orders.shipping" | t: count: count }}
```
- If the count is 0, it will choose `zero`, unless `zero` does not exist and then it will use `other`.
- 1 corresponds to `one`, and everything else will fall under `others`.
### Other filters in combination
You can still use other filters in combination with `t` but you'll use them **after** you use the `t` filter.
For example, to titlecase a translation:
```json title="Message template editor"
{{ "congratulationsMessage" | t | titlecase }}
```
### Namespaced translations
When you create a translation, you can supply an optional "namespace." The namespace helps organize translations of the same locale so you can keep similar concepts together. Below you'll see examples of how to reference namespaced translations from your message templates.
Let's start with a translation with a namespace of `shipping`:
```json title="en:shipping translation"
{
"backordered": "Your order has been backordered so shipping will be delayed.",
"shipped": "Your order has been shipped.",
"canceled": "Your shipment has been canceled."
}
```
To access the contents of the `shipping` translation in your message template you'll reference the namespace before the key followed by a colon (":"):
```json title="Message template editor"
{{ "shipping:canceled" | t }}
```
This can be helpful if you use the `canceled` key elsewhere in your translations so that there isn't a collision. For example, if you had a `payments` translation like this:
```json title="en:payments translation"
{
"success": "Your payment has been processed.",
"canceled": "Your payment was canceled."
}
```
You would reference it with the `payments` namespace as well:
```json title="Message template editor"
{{ "payments:canceled" | t }}
```
And if you had a translation that wasn't namespaced, say the `en` translation, you would simply use the key alone. All together in a template, it would look like this:
```json title="Message template editor"
Hello,
{{ "payments:canceled" | t }}
{{ "shipments:canceled" | t }}
{{ "canceled" | t }}
```
### Nested translations
You can create whatever JSON structure you need to hold your translations.
Given the following translation:
```json title="en translation"
{
"customers": {
"orders": {
"beenReceived": "Have you received your order?",
"survey": "How was your order?"
},
"reminder": {
"paymentInfo": "Remember to update your payment information!"
}
}
}
```
You can access the content with dot-syntax like this:
```json title="Message template editor"
{{ "customers.orders.beenReceived" | t }}
```
The same goes for namespaced translations. If the above translation was in a namespace called `services`, you would do the following:
```json title="Message template editor"
{{ "services:customers.orders.beenReceived" | t }}
```
## Using the `t` tag
Knock also provides an editor-friendly `t` tag which you can use to write templates in your default language. Translation files for any supported languages will be automatically generated in the background when you commit a workflow.
Wrap content you want to translate in a t tag. Any content between the opening and closing t tags will be used as the content for your account's default locale.
```liquid title="Message template"
{% t %}Have you received your order?{% endt %}
```
After you commit your workflow, Knock will look for changes to your message templates and update a system translation file. Translation keys will be automatically generated based off of the content of the t tag.
A Knock bot will commit these changes to your account with a message indicating which workflow generated the new translations.
```json title="System translation file"
{
"Have you received your order?": "Have you received your order?"
}
```
You can then translate the default content into additional locales by manually editing your translation files or programmatically updating them using the Knock API and a translation service.
### Variables
You can reference variables inside a `t` tag by writing the variable's path inline. Knock resolves the path against the workflow run scope when it renders the message.
```liquid title="Message template"
{% t %}Congratulations, {{ recipient.name }}!{% endt %}
```
unlike the t filter, the t tag doesn't accept
arguments. You can't pass or alias a variable. Write the variable's actual
path inside the tag instead.
}
/>
When you commit your workflow, the variable reference becomes part of the auto-generated translation key and is preserved verbatim in your system translation file:
```json title="System translation file"
{
"Congratulations, {{ recipient.name }}!": "Congratulations, {{ recipient.name }}!"
}
```
As you translate that content into other locales, keep the `{{ ... }}` reference intact in the translated value. You can move it to wherever the grammar of the target language requires, but if you remove or rename it, the variable will no longer resolve.
```json title="fr translation"
{
"Congratulations, {{ recipient.name }}!": "Félicitations, {{ recipient.name }}!"
}
```
At send time, Knock renders the translated value as Liquid, resolving `recipient.name` from the workflow run scope.
## Translation version control
All changes to translations are version controlled. Versions are stored in commits. You can create translations directly in production, but most customers choose to create them in development and promote them to production when they're ready to go live.
Read more about [environments](/version-control/environments) and [versioning](/version-control/commits) in Knock.
in order to see translation updates in your template previews, you'll need
to commit them to your development environment first.
}
/>
## Per-tenant translations
If you use Knock's [multi-tenancy](/multi-tenancy/overview) support, you can create tenant-scoped translation files that override specific keys for individual tenants. Knock deep-merges the tenant's translations on top of your base translation files at render time, so you can power per-tenant copy. For implementation details, see [per-tenant translations](/multi-tenancy/per-tenant-translations).
## Locale prioritization
When Knock renders a template for a given user and encounters our `t` helper, translations are resolved based on the recipient's locale and the tenant provided in the workflow trigger. The resulting merge maintains the following prioritization:
1. Tenant-scoped, language + region (e.g. `fr-BE`, tenant: `acme-corp`)
2. Tenant-scoped, language (e.g. `fr`, tenant: `acme-corp`)
3. Tenant-scoped, default locale (e.g. `en`, tenant: `acme-corp`)
4. Language + region (e.g. `fr-BE`)
5. Language (e.g. `fr`)
6. Default locale (e.g. `en`)
Tenant-scoped translations take precedence over base translations and regional locales take precedence over language locales. If a translation is not found in the user's locale, Knock will fall back to the default locale.
## Automate localization with our CLI
In addition to working with translations in the Knock dashboard, you can programmatically create and update translations using the [Knock CLI](/developer-tools/knock-cli) or our [Management API](/developer-tools/management-api).
If you manage your own translation files within your application, you can automate the creation and management of Knock translations so that they always reflect the state of the translation files you keep in your application code.
The Knock CLI supports both JSON and the Portable Object (PO) file formats. When using PO files, the Knock CLI will handle converting between the Knock translation format and the PO format.
The Knock CLI can also be used to commit changes and promote them to production, which means you can automate Knock translation management as [part of your CI/CD workflow](/tutorials/integrating-into-cicd).
See the [Translation file structure](/cli/translation/file-structure) section in the CLI reference for details on how translation files are organized when working with the CLI.
You can learn more about automating translation management in the [Knock CLI reference](/cli/overview). Feel free to contact us if you have questions.
## Supported locales
Below is a list of the available locales to choose from for your translations. If you need one added, contact us at support@knock.app.
## Frequently asked questions
Yes, translations support markdown formatting. You can create a translation value like the following:
```json title="An English translation with bolded markdown text"
{
"orderShipped": "Your order **{{ orderNumber }}** is on its way."
}
```
In-app and chat channels render markdown from translation values at send time, so the `t` filter on its own is all you need in your message templates for those channels:
```liquid title="In-app or chat template"
{{ "orderShipped" | t: orderNumber: order.number }}
```
Email is different. Knock compiles an email template's markdown content to HTML at commit time, before you send the message, while translation values are injected at send time. This means that by default, Knock doesn't convert markdown placed inside a translation value (or inside `{% t %}` tags), and your recipients will see the literal markdown characters (for example, `**bold**`) in their emails.
To convert the resolved value at runtime and render it appropriately, chain the `from_markdown` [filter](/template-editor/reference-liquid-helpers) onto the `t` filter:
```liquid title="Email template"
{{ "orderShipped" | t: orderNumber: order.number | from_markdown }}
```
Two things to keep in mind as you apply this pattern:
- `from_markdown` can only be used alongside the `t` filter. You can't use it with `{% t %}` tags, so you should plan to author your translations with `t` filters if you want to support markdown inside your translated content.
- Use `from_markdown` in email templates only. It outputs HTML, and Knock already converts your markdown to the platform-specific markup that Slack, Microsoft Teams, and other platforms expect.
For simpler cases, keep the markdown formatting outside of the translation and translate only the plain text:
```liquid title="Message template"
**{% t %}Bold text{% endt %}**
```
## Testing & debugging
Learn how to test and debug your message templates.
---
title: Testing & debugging templates
description: Learn how to test and debug your message templates.
tags:
[
"template",
"liquid",
"testing",
"debugging",
"test runner",
"send test",
"test notifications",
"test workflow",
"test workflow run",
"test broadcast run",
]
section: Working with templates
---
## Previewing templates
The preview pane in the template editor will show you an approximation of how your template will render, using the properties that you've set within the state pane as inputs.
If you need to adjust the properties that are used in the preview, or see what the template will look like for a different recipient or tenant, editing the data in the state pane will automatically cause the preview to update.
## Sending test messages
You can send a test message by clicking the "Run a test" button in the top right of the template editor. From here, you can select a recipient and provide any of the data that you'd like to pass to the template.
## Debugging template errors
If Knock cannot render your template, you'll see an error message in the preview pane. Most commonly, you'll see this error when you've got invalid Liquid syntax in your template that's preventing the template from being rendered.
When a template fails to render during a workflow run (typically due to
missing or malformed trigger data values), Knock will retry
the step up to 3 times. If all attempts fail, the entire workflow run is
halted. See our{" "}
debugging workflows documentation
{" "}
for more details.
If you're seeing the "Powered by Knock" branding appear multiple times in
your email notifications, it's because you're double wrapping your email
template in HTML.
Remember that an{" "}
email template is wrapped
by the email layout, which already includes <html> and{" "}
<body> tags.
## Liquid helpers reference
A reference to help you work with the Liquid templating language in Knock.
---
title: "Liquid helpers"
description: A reference to help you work with the Liquid templating language in Knock.
tags:
[
"liquid",
"template",
"variables",
"currency",
"timezone",
"pluralize",
"user",
"object",
"tenant",
"subscriptions",
]
section: Working with templates
---
The Knock template editor uses Liquid syntax for control flow and variable declaration. Here are a few of the most common Liquid keywords our customers use within Knock. We recommend referencing the Liquid documentation for comprehensive syntax and usage information.
## Knock-specific Liquid helpers
Knock extends Liquid with helpers that format, transform, and evaluate data when rendering notification templates.
### Date and time
Takes an ISO 8601 timestamp and returns it in the [IANA tz database timezone](https://en.wikipedia.org/wiki/List_of_tz_database_time_zones) provided. You can use the built-in `timestamp` [template variable](/template-editor/variables) to reference the current datetime. When formatting with the `date` filter, we recommend using the `timezone` option on the `date` filter instead.
| Example | Output |
| --- | --- |
| `{{ timestamp \| timezone: "America/New_York"}}` | 2023-12-31T19:30:00-05:00 |
This filter has been extended to take an additional `timezone` option. It accepts strftime-style format strings, but Knock's Liquid implementation does not support the full strftime specification. Notably, `%e` and `%l` are not fully supported.
| Example | Output |
| --- | --- |
| `{{ startDate \| date: "%-I:%M %p %Z" , "America/New_York" }}` | 2:30 PM EST |
Converts an ISO 8601 timestamp to a localized date string. Requires a [`locale`](#localization-parameters) parameter and accepts an optional `date_format`: `"short"` (default), `"medium"`, `"long"`, or `"full"`. See the [date format options](#date-format-options) table below for examples.
| Example | Output |
| --- | --- |
| `{{ timestamp \| format_date_in_locale: "en-GB", "long" }}` | 31 December 2023 |
Converts an ISO 8601 timestamp to a localized date and time string. Requires [`locale`](#localization-parameters), `date_format`, and `time_format` parameters. Date and time formats can be: `"short"` (default), `"medium"`, `"long"`, or `"full"`. See the [date format options](#date-format-options) and [time format options](#time-format-options) tables below for examples.
| Example | Output |
| --- | --- |
| `{{ timestamp \| format_datetime_in_locale: "en-GB", "medium", "short" }}` | 31 Dec 2023, 14:30 |
### Numbers and currency
Takes an integer and formats it to the local number format of the provided [`locale`](#localization-parameters).
| Example | Output |
| --- | --- |
| `{{ 10000 \| format_number: "en" }}` | 10,000 |
Takes an integer and returns a USD formatted value with two decimal points. You can pass a currency type and a [`locale`](#localization-parameters) through to the currency helper to tell it which currency to use.
| Example | Output |
| --- | --- |
| `{{ 10 \| currency: "GBP", "en" }}` | £10.00 |
Takes an integer and returns a USD formatted value rounded to nearest whole number. You can pass a currency type and a [`locale`](#localization-parameters) through to the currency helper to tell it which currency to use.
| Example | Output |
| --- | --- |
| `{{ 10.99 \| rounded_currency: "GBP", "en" }}` | £11 |
### Text and data
Takes a value and returns as a formatted JSON string.
| Example | Output |
| --- | --- |
| `{{ recipient \| json }}` | `{"id": "user_123", "name": "John Hammond"}` |
Takes a JSON string and returns a parsed object whose properties can be referenced via their keys.
| Example |
| --- |
| `{% assign recipient = input \| from_json %}` |
Takes an integer and a pluralize helper with two strings. If the integer is one, the helper returns the first string. If the helper is greater than one, it returns the second string.
| Example | Output |
| --- | --- |
| `{{ total_actors \| pluralize: "user", "users" }}` | users |
Takes a string and reformats it into Title case.
| Example | Output |
| --- | --- |
| `{{ project_name \| titlecase }}` | My Project Name |
Takes a string of markdown and converts it to HTML.
| Example | Output |
| --- | --- |
| `{{ data.comment_body \| from_markdown }}` | `
Hello
` |
Returns the intersection of two arrays (the elements common to both).
| Example | Output |
| --- | --- |
| `{{ arr1 \| intersect: arr2 }}` | `["Acme Corp", "InGen"]` |
For a given [semantic version](https://semver.org/) string, compares it to a second version string provided as an argument. Returns an integer indicating the order of the versions; `-1` if the first version is less than the second, `0` if they are equal, and `1` if the first version is greater than the second.
| Example | Output |
| --- | --- |
| `{{ "1.0.0" \| compare_versions: "2.0.0" }}` | `-1` |
### Hashing
Takes a string and returns an md5 hash.
| Example |
| --- |
| `{{ recipient.id \| md5 }}` |
Takes a string and returns an sha256 hash.
| Example |
| --- |
| `{{ recipient.id \| sha256 }}` |
Takes a string and returns an hmac hash given a key provided to `hmac_sha256` helper.
| Example |
| --- |
| `{{ recipient.id \| hmac_sha256: "some-key" }}` |
### Localization and formatting
#### Date format options
The `format_date_in_locale` and `format_datetime_in_locale` helpers accept date format options that control how the date portion is displayed.
#### Time format options
The `format_datetime_in_locale` helper accepts time format options that control how the time portion is displayed.
#### Localization parameters
The `format_date_in_locale`, `format_datetime_in_locale`, `format_number`, `currency`, and `rounded_currency` helpers take an optional locale parameter to format the output into a localized format. If we're missing a locale that you'd like us to support, please [reach out](mailto:support@knock.app).
**Supported locales.** `af`, `ar`, `az`, `be`, `bg`, `bn`, `bs`, `ca`, `cs`, `cy`, `da`, `de`, `de-DE`, `el`, `en`, `en-US`, `en-GB`, `eo`, `es`, `es-419`, `et`, `eu`, `fa`, `fi`, `fr`, `fr-CA`, `fr-FR`, `gl`, `he`, `hi`, `hr`, `hu`, `id`, `is`, `it`, `ja`, `ja-JP`, `ka`, `km`, `kn`, `ko`, `lb`, `lo`, `lt`, `lv`, `mk`, `ml`, `mn`, `mr`, `ms`, `nb`, `ne`, `nl`, `nn`, `no`, `or`, `pa`, `pl`, `pl-PL`, `pt`, `pt-BR`, `rm`, `ro`, `ru`, `sk`, `sl`, `sq`, `sr`, `sv`, `sw`, `ta`, `te`, `th`, `tr`, `tt`, `ug`, `uk`, `ur`, `uz`, `vi`, `wo`, `zh`, `zh-CN`, `zh-Hans`, `zh-Hant`
## Dynamic data filters
Knock provides a set of Liquid filters that dynamically load data from your Knock environment at template render time. These filters enable you to reference entities like users, objects, tenants, and subscriptions in your templates without passing all of the data in your workflow trigger call. For more details and examples, see [referencing data in templates](/template-editor/referencing-data).
# Send messages
Learn how to send and debug notifications using Knock.
## Triggering workflows
## Overview
Learn more about how to trigger cross-channel notification workflows in Knock.
---
title: Triggering workflows
description: Learn more about how to trigger cross-channel notification workflows in Knock.
tags: ["trigger", "notify", "data", "actor"]
section: Send notifications
---
Knock executes workflow runs when workflows are triggered. A workflow can be triggered in these ways:
- By a [direct API call](/send-notifications/triggering-workflows/api) to the `trigger` endpoint
- By a [source event](/send-notifications/triggering-workflows/events)
- On a [recurring, or one-off schedule](/send-notifications/triggering-workflows/schedules)
- When a user becomes [a member of an audience](/send-notifications/triggering-workflows/audiences)
These trigger methods are not mutually exclusive. For example, a workflow with an event trigger configured can still be triggered via the API, and vice versa.
Recipients can opt out of notifications through preferences. Knock handles
all preference-based opt-outs automatically. Learn more about{" "}
preference management
{""}.
}
/>
## Conditionally executing a workflow trigger
A trigger step can have one or more [step conditions](/designing-workflows/step-conditions) that determine if the workflow executes. When conditions evaluate to false, the workflow terminates and no other steps execute.
## Controlling workflow trigger frequency
Sometimes you need to limit how often a recipient runs through a workflow. For example, you might want an account signup workflow to run only once per recipient. Workflow trigger frequency controls this behavior.
Trigger frequency lets you set if a workflow should run every time or at most once per recipient. By default, workflows trigger every time for a recipient.
When you specify "Once per recipient" frequency, you can include the tenant in this control. This ensures your workflow triggers once per-recipient, per-tenant.
## Frequently asked questions
A workflow whose [status](/concepts/workflows#workflow-status) is set to
`Inactive` will return a `workflow_inactive`
[error](/api-reference/overview/errors) when triggered and will not generate
any workflow recipient runs.
No. Trigger frequency is not enforced by the [workflow test
runner](/send-notifications/testing-workflows). Settings like "once per
recipient" are bypassed — the workflow will execute for the selected
recipient every time you run a test, regardless of your frequency setting.
This is expected behavior. To test trigger frequency as it works in
production, trigger the workflow via the [trigger
API](/send-notifications/triggering-workflows/api) directly.
## With the API
Learn more about how to trigger cross-channel notification workflows in Knock via the API.
---
title: Triggering workflows via the API
description: Learn more about how to trigger cross-channel notification workflows in Knock via the API.
tags: ["trigger", "notify", "data", "actor"]
section: Send notifications
---
The trigger API endpoint executes workflows for your recipients. When you call the `trigger` endpoint, Knock runs your specified [Recipients](/concepts/recipients) and `data` through the workflow.
Learn more about triggering workflows in [our API reference](/api-reference/workflows).
## Trigger payload
| Property | Type | Description |
| ---------------- | --------------------- | ----------------------------------------------------------------------------------------------------------- |
| key\* | string | The human-readable key of the workflow from the Knock dashboard |
| actor | RecipientIdentifier | An identifier of who or what performed this action (optional) |
| recipients\* | RecipientIdentifier[] | One or more recipient references of who/what to notify for this workflow |
| data | map | A map of properties that are required in the templates in this workflow |
| cancellation_key | string | A unique identifier to reference the workflow when canceling |
| tenant | string | An optional identifier of the owning tenant object for the notifications generated during this workflow run |
| settings | map | An optional map of settings that control how this workflow run is executed |
## Recipient identifiers
When you want to identify a recipient in a workflow, either as an actor or as a recipient you can send either:
- A string indicating a user that you have previously identified to Knock (e.g. `user-1`).
- A reference of an object that you have previously set within Knock (e.g. `{ id: "project-1", collection: "projects" }`).
- A complete `Recipient`, to be identified inline during the workflow execution.
## Response
Triggering a workflow will always return a unique UUID v4 representing the workflow run.
```json title="Trigger workflow response"
{
"workflow_run_id": "05f8a70d-e42a-46dc-86fa-aada5752f6cf"
}
```
a workflow run ID is a unique identifier that represents the workflow run
for all recipients of the workflow. Each individual in the workflow run
will have a unique workflow recipient run ID, which is derived from the
workflow run id.
}
/>
## Passing data to your trigger
Pass schema data required by the workflow in your `trigger` call. The payload must be a valid JSON object. There is a 10MB limit on the size of the full `data` payload. Any individual string value greater than 1024 bytes in length will be [truncated](/developer-tools/api-logs#log-truncation) in your logs.
The workflow builder determines which data keys are required.
For more information on validating trigger data and working with JSON
schemas, see our documentation on{" "}
validating trigger data
.
}
/>
## Attributing the action to a user or object
Pass an `actor` in your trigger call to attribute the workflow run to a specific user or object.
Calling a workflow trigger with an actor:
- Records who triggered the workflow
- Links the actor to any in-app feed messages
- Includes the actor in batch steps via the `actors` key
- Excludes the actor from notifications when they are a [subscriber](/concepts/subscriptions) to an Object recipient
## Generating a cancellation key
Include a `cancellation_key` in your `trigger` call to enable workflow cancellation.
You can read more about canceling workflows [in our documentation](/send-notifications/canceling-workflows).
The key should uniquely identify the workflow run you want to cancel. We recommend using:
- A UUID v4
- A hash of relevant workflow data
- A timestamp combined with recipient and workflow identifiers
## Deduplicating workflow runs
You can include an optional `Idempotency-Key` header in your trigger call to safely retry requests without creating duplicate workflow runs. This helps prevent users from receiving duplicate messages if the same trigger is accidentally sent more than once. If a request is retried with the same idempotency key within 24 hours, Knock will return the same response as the original request. Idempotent requests are expected to be identical. To prevent accidental misuse, Knock returns an error when incoming parameters don't match those from the original request.
You can read more about how Knock handles idempotent requests in [our API reference](/api-reference/overview/idempotent-requests).
## Identifying recipients inline
You can pass a complete `Recipient` entity to the `recipients` or `actor` property when triggering a workflow. When passing the recipient, the recipients will be guaranteed to be identified **before** the workflow is triggered for the recipient with the properties passed in.
| Property | Description |
| --------------- | ------------------------------------------------------------------------------------------------------ |
| `id` | Required. An identifier for this user or object |
| `collection` | Required when identifying an object. Indicates the collection the object belongs to |
| `channel_data` | A dictionary containing a `channelId` key and a dictionary of channel data to be set for the recipient |
| `preferences` | A dictionary containing a preference set ID key and a `PreferenceSet` object to set for the recipient |
| `$trigger_data` | Any recipient-specific trigger data to merge in with the `data` available on the workflow run |
| \* | An arbitrary set of key/value pairs to set for the recipient |
```json title="Example inline recipient definition"
{
"id": "user-1",
"name": "Jean Luc-Picard",
"email": "jpicard@starfleet.org",
"channel_data": {
"4672d685-c586-4ec6-ad88-52185262af97": {
"tokens": ["apns-push-token"]
}
},
"preferences": {
"default": {
"channel_types": {
"email": true,
"sms": false
}
}
}
}
```
## Per-recipient trigger data
Per-recipient data is useful when you want to notify an array of recipients with a single trigger, but include custom data per-recipient.
You can pass per-recipient data to your trigger by passing a dictionary of data under the `$trigger_data` property for each recipient. Any data provided under this property will be merged with the data passed in the `data` property to produce the final data available for the recipient's workflow run.
```json title="Example per-recipient data"
{
"data": {
"alert_type": "security_breach",
"location": "Visitor Center"
},
"recipients": [
{
"id": "jhammond",
"name": "John Hammond",
"$trigger_data": {
"role": "Park Owner",
"dashboard_url": "https://jurassicpark.com/dashboard/jhammond"
}
},
{
"id": "esattler",
"name": "Ellie Sattler",
"$trigger_data": {
"role": "Paleobotanist",
"dashboard_url": "https://jurassicpark.com/dashboard/esattler"
}
},
{
"id": "dnedry",
"name": "Dennis Nedry",
"$trigger_data": {
"role": "Systems Programmer",
"dashboard_url": "https://jurassicpark.com/dashboard/dnedry"
}
}
]
}
```
For example, the final merged data available to Ellie Sattler's workflow run would be:
```json title="Final merged data for esattler"
{
"alert_type": "security_breach",
"location": "Visitor Center",
"role": "Paleobotanist",
"dashboard_url": "https://jurassicpark.com/dashboard/esattler"
}
```
## Multi-tenancy in notifications
You can optionally pass a `tenant` to your `trigger` call. If you are a product that allows users to belong to multiple tenants,
you'll want to pass a `tenant` to Knock in your trigger calls so that you can make sure a given user's in-app feed is scoped to the
tenants to which they belong in your product.
You can read more about [supporting multi-tenancy in our documentation](/concepts/tenants).
## Testing workflows with trigger settings
You can pass an optional `settings` object in your `trigger` call to control how the workflow run is executed. These settings are useful when testing a workflow, and mirror the options available in the [workflow test runner](/send-notifications/testing-workflows#test-run-settings).
| Property | Type | Description |
| ------------ | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| sandbox_mode | boolean | When `true`, all messages in the workflow run are forced to send in [sandbox mode](/integrations/overview#sandbox-mode), overriding the per-channel configuration. Messages are generated but not delivered to the underlying providers. Defaults to `false`. |
| skip_delay | boolean | When `true`, all [delay steps](/designing-workflows/delay-function) in the workflow are force skipped, so the run executes straight through without waiting. Defaults to `false`. |
```json title="Example trigger with settings"
{
"recipients": ["user-1"],
"data": {
"message": "Life finds a way"
},
"settings": {
"sandbox_mode": true,
"skip_delay": true
}
}
```
## Frequently asked questions
You can trigger a workflow for a single recipient by passing a single
recipient identifier to the `recipients` property in your trigger call.
You can trigger a workflow for multiple recipients by passing an array of
recipient identifiers to the `recipients` property in your trigger call.
You can trigger a workflow for an object by passing an object identifier to
the `recipients` property in your trigger call.
An object identifier looks like:
```json
{
"id": "project-1",
"collection": "projects"
}
```
You can trigger a workflow for the subscribers of an object by passing an object identifier to the `recipients` property in your trigger call. Knock will automatically create a workflow run for the object itself and for each subscriber of the object.
It's not yet possible to trigger a workflow for an audience via the API. If you're looking to trigger a workflow for a specific audience, please get in touch with us. We're currently considering how to best support this use case and would love to discuss your specific needs.
You can trigger a workflow for up to 1000 recipients at a time. If you need to manage a larger list of recipients, you might want to consider using our [subscriptions feature](/concepts/subscriptions) to have Knock manage the set of recipients who need to be notified instead.
It's not currently possible to issue bulk trigger requests to the API. If you need to trigger workflows for multiple recipients with per-recipient data, you can pass per-recipient trigger data.
You can cancel a workflow run by calling the `cancel` endpoint.
Yes, you can [validate the data you're passing to a workflow trigger](/developer-tools/validating-trigger-data) by
providing a JSON schema in your workflow trigger step.
Yes, you can [generate types for your workflow triggers](/developer-tools/type-safety) by providing a trigger data schema in your workflow trigger step.
## On a schedule
Learn more about how to trigger cross-channel notification workflows in Knock on a schedule.
---
title: Triggering workflows on a schedule
description: Learn more about how to trigger cross-channel notification workflows in Knock on a schedule.
tags: ["trigger", "notify", "data", "actor"]
section: Send notifications
---
Schedules allow you to express complex repeating schedules for your workflow triggers so that you can trigger workflows on a one-off or a recurring basis for one or more recipients.
You can think of a schedule as a managed, recipient-timezone-aware cron job that Knock will run on your behalf.
[Learn more about schedules](/concepts/schedules)
## Creating a schedule
You can create a workflow schedule via the API. Schedules cannot be created in the Knock dashboard.
```typescript title="Creating a schedule for multiple recipients"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
const schedules = await knock.workflows.createSchedules("park-alert", {
recipients: ["jhammond", "esattler", "dnedry"],
repeats: [
// Repeat daily at 9.30am only on weekdays
{
frequency: "daily",
days: "weekdays",
hours: 9,
minutes: 30,
},
],
});
```
## Providing per-recipient schedule data
It's possible to provide per-recipient schedule data to your workflow runs by setting the `data` property on each schedule created via the API. When your schedule runs, the data provided will be set on the workflow run for each recipient.
## Reviewing scheduled workflow runs
You can see all scheduled workflow runs under the **Schedules** section of a given workflow. Please note that this tab will only display if there are recipient schedules configured for the workflow.
## Frequently asked questions
Yes, but you'll need to add each user to the schedule manually via the API.
There's no way to automatically add all users to a schedule.
No, it's currently not possible to trigger a workflow for a set of
subscribers to an object.
## From an event
Learn more about how to trigger cross-channel notification workflows in Knock via an event.
---
title: Triggering workflows via an event
description: Learn more about how to trigger cross-channel notification workflows in Knock via an event.
tags: ["trigger", "source", "event", "segment", "cdp", "customer data platform"]
section: Send notifications
---
Events from customer data platforms like [Segment](/integrations/sources/segment) or direct HTTP webhook integrations trigger workflows.
Event-triggered workflows decouple notifications from your backend systems — enabling non-developers to set up and configure notifications based on business events in your product.
Event-triggered workflows require that you have one or more [Sources](/integrations/sources/overview) configured and connected to Knock.
## Configuring an event trigger
You can create and manage event triggers for your workflows in the **Sources** section (under **Platform** in the sidebar) or directly from the workflow builder when you click the "Trigger" step.
From the Trigger step sidebar, if you have events connected to Knock you'll see the option to switch the trigger type to "Event" from the dropdown menu. Once here, you can select an event that will trigger this workflow when it's received. You can also map the critical fields needed to run a workflow to the fields that will be in the incoming event payload.
[Learn more about sources](/integrations/sources/overview)
## Frequently asked questions
Yes. Configuring an event trigger does not prevent you from triggering the
workflow via the [API](/send-notifications/triggering-workflows/api). Both
trigger methods work independently, so you can use event triggers to
automate notifications from external sources while still calling the API
directly when needed.
Yes, it's possible to override the default behavior of a source event
trigger to point the trigger to a property on the event that resolves to a
list of recipients.
Yes, you can cancel any workflow that contains a pause step (batch, delay,
or fetch function). The ability to cancel depends on the workflow structure,
not how it was triggered. See our documentation on [canceling
workflows](/send-notifications/canceling-workflows) for details.
## For an audience
Learn more about how to trigger cross-channel notification workflows in Knock via an audience.
---
title: Triggering workflows via an audience
description: Learn more about how to trigger cross-channel notification workflows in Knock via an audience.
tags: ["trigger", "audience"]
section: Send notifications
---
[Audience](/concepts/audiences) workflow triggers execute a workflow run when a user joins a specific audience. An audience consists of users who share a common characteristic, such as users on a paid plan or users who made a purchase in the past 30 days.
To use audience triggers, you need an audience created in Knock. [Create an audience](/concepts/audiences#creating-an-audience) in the **Audiences** section of the dashboard.
## Configuring an audience trigger
Create or open the workflow you'd like to trigger for your audience, then open the workflow editor. Click on the "Trigger" step, then click "Edit trigger type" in the top right corner. Click "Audience" and then select the audience you'd like this workflow to trigger from.
Commit your workflow to your current environment. At this point, every time a user is added to the selected audience a workflow will be triggered with that user as a recipient.
The workflow will run in the environment where the user was added to the
audience. If you use a production API key to add users to an audience in
production, your workflow will trigger in the production environment.{" "}
Learn more about environments.
}
/>
## Frequently asked questions
No, workflows trigger only for **new users** who join an audience.
No, a workflow accepts only one audience as its trigger source.
No, workflows trigger only when users join an audience.
Yes, use the workflow trigger frequency setting to control if a workflow
should trigger for users who have already completed the workflow.
## Canceling workflows
Learn more about canceling workflows in Knock and see code examples to get started.
---
title: Canceling workflows
description: Learn more about canceling workflows in Knock and see code examples to get started.
tags: ["cancellations", "cancellation_key", "cancel", "batch", "remove"]
section: Send notifications
---
Canceling a workflow allows you to stop a workflow run mid-execution. This action will stop the workflow from sending new messages to recipients. This can be useful in situations like reminder workflows, where a notification needs to be canceled once a user has performed an intended action.
Only workflows with a step that can pause the run can be canceled, since otherwise Knock will _immediately_ send a notification to your recipients. The steps that can pause a workflow run are:
- [Batch functions](/send-notifications/designing-workflows/batch-function) will pause workflows while the batch window is open.
- [Delay functions](/send-notifications/designing-workflows/delay-function) will pause workflows for the configured delay window.
- [Wait for event functions](/send-notifications/designing-workflows/wait-for-event-function) will pause workflows until a matching event is received or the wait time expires.
- [Fetch functions](/send-notifications/designing-workflows/fetch-function) may pause workflows during a [retry backoff](/send-notifications/designing-workflows/fetch-function#error-handling).
## Canceling a triggered workflow
To perform a cancellation, you first need to provide a `cancellation_key` in the [workflow trigger](/send-notifications/triggering-workflows) request. Knock will use this key to uniquely identify the triggered workflow for cancellation.
You can read about generating workflow cancellation keys and some best practices in the [triggering workflows documentation](/send-notifications/triggering-workflows/api#generating-a-cancellation-key).
### Schema
| Property | Type | Description |
| ---------------- | --------------------- | ------------------------------------------------------------------------------ |
| key\* | string | The human readable key of the workflow from the Knock dashboard |
| cancellation_key | string | A unique identifier for the workflow run |
| recipients | RecipientIdentifier[] | A list of specific recipient identifiers to cancel the workflow for (optional) |
## Canceling for subsets of recipients
In some cases you may need to cancel a workflow for a subset of recipients only. You can do this by specifying the recipients list on the cancellation:
## Gotchas and recommendations
There are a few fundamentals to consider when using workflow cancellations:
1. A cancellation cannot be performed on a specific channel step, it can only be performed against the _entire_ workflow.
2. You cannot cancel a given workflow run after it has finished. If you need to revoke messages for persistent channels like the in-app feed, then you can `archive` a message instead.
3. Workflow cancellations are both deferred and executed concurrently to the workflow run itself. The [cancel workflow API](/api-reference/workflows/cancel) will return a `204 No Content` response on success, but this only means Knock has successfully enqueued the cancellation request, _not_ that the cancellation has been performed. **We recommend against issuing a cancellation request within 5 seconds of a given workflow trigger**. Cancellations issued too soon after a workflow trigger may not cancel the intended target. Cancellations issued prior to a workflow trigger may overtake and cancel the subsequent workflow.
4. Canceling a workflow with a [batch step](/send-notifications/designing-workflows/batch-function) will not close the open batch window. Read more [here](/designing-workflows/batch-function#using-workflow-cancellation-with-batches).
## Frequently asked questions
Yes, you can. Because workflow cancellation requests can be scoped to one or
more specific recipients, you can target any recipient who was notified via
an object subscription, even if that recipient was not explicitly included
in the workflow trigger request.
## Delivering notifications
Learn how Knock sends in-app and out-of-app notifications to email, SMS, push, and chat channels (such as Slack).
---
title: Delivering notifications
description: Learn how Knock sends in-app and out-of-app notifications to email, SMS, push, and chat channels (such as Slack).
tags: ["delivery", "channels", "delivery status", "retry logic", "resilience"]
section: Send notifications
---
## Overview
When a workflow is executed, its [channel steps](/designing-workflows/channel-step) may produce zero or more messages for the workflow run's recipient. Each message is then sent to its channel's provider using Knock's resilient sending pipeline which handles retries and logging for you.
## Retry logic
### Send retries
We will retry sending notifications to the underlying provider when:
- There is an error contacting the provider (e.g. a network connection issue).
- The provider responds with a retryable error (e.g. server overloaded, rate limit exceeded).
- There is a transient error in our sending pipeline.
We will retry delivery up to **8 times over a 30-minute window**, utilizing an exponential back-off strategy with jitter.
We will also change the [message delivery status](/send-notifications/message-statuses#delivery-status) and emit corresponding [message events](/send-notifications/message-statuses#message-events) during this delivery lifecycle. You can expect to see:
- A `queued` status when the message has been enqueued for a delivery attempt.
- A `delivery_attempted` status when Knock has attempted delivery but the attempt has failed. The delivery may or may not be retried.
- A `bounced` status when the provider indicates a message has been bounced and Knock will not retry.
- An `undelivered` status when Knock has failed to deliver the message and will not retry (either retries have been exhausted or an unretryable error was encountered).
### Delivery status tracking
For certain channel types where it is supported by the provider, Knock tracks [delivery status](/send-notifications/message-statuses#delivery-status) updates. Knock supports two methods for tracking delivery status:
#### Provider webhooks
When provider webhooks are enabled, your provider sends delivery status updates directly to Knock.
To enable provider webhooks, configure the webhook URL in your channel settings and add it to your provider's webhook configuration. See your provider's integration page for detailed setup instructions.
#### Polling
If provider webhooks are unsupported or not enabled, Knock periodically polls the provider's API to check delivery status.
On success, we update the message delivery status to `delivered`. We retry a delivery status check when:
- There is an error contacting the provider (e.g. a network connection issue).
- The provider indicates the request is retryable (e.g. there's no delivery status being presented yet).
- There is a transient error in the delivery status check pipeline.
For specific providers, on failure we will update the delivery status to `undelivered` or `bounced` depending on the error status. We will not retry a delivery status check in these cases.
We will retry delivery status checks up to **10 times over a 30-minute window,** utilizing an exponential back-off strategy with jitter.
### Manually retrying delivery
If a message is in an `undelivered` [state](/send-notifications/message-statuses#1-undelivered) and you would like to re-attempt delivery, you can manually retry delivery from the Knock dashboard. Navigate to the message and select the "Retry delivery" button in the upper right-hand corner of the message detail view.
Retrying delivery re-enqueues the message for a new delivery attempt, moving it back through the delivery lifecycle. This is helpful once you've resolved the underlying cause of the failure, such as correcting recipient data or updating your provider configuration.
## Sending logs and debugging
For all out-of-app providers you can find logs of the requests we make and the responses we receive under the "Logs" tab of an individual message in the dashboard. You can use these logs to understand any errors coming from the provider while we were executing your requests.
If you find an error that you cannot fix yourself, please contact [our support team](mailto:support@knock.app) for help.
## Message statuses
How to work with the Knock message statuses to understand notification delivery and engagement rates.
---
title: Message statuses
description: How to work with the Knock message statuses to understand notification delivery and engagement rates.
tags: ["delivery status", "engagement status", "delivery rates"]
section: Send notifications
---
Knock uses the [Message](/concepts/messages) model to represent a notification delivered to a recipient on a particular channel. Knock Messages can have one or more statuses, which indicate the delivery state of your notification or how your recipient is engaging with the message. Knock captures changes in message status as Message Events, which you can hook into with [outbound webhooks](/developer-tools/outbound-webhooks/overview).
Knock manages two types of notification statuses:
- **Delivery status** — Was the message successfully delivered to your messaging providers and to your recipient? Delivery statuses are mutually exclusive, hierarchical, and implicitly managed by Knock as part of notification delivery.
- **Engagement status** — How has your recipient engaged with the notification once received? A message can have multiple engagement statuses, or none. Knock will implicitly manage some engagement statuses for you, but you can also manage them yourself via the Knock API.
## Delivery status
When you trigger a Knock workflow, any channel step within that workflow generates a Message for each recipient. Once the message is generated, Knock manages delivery to the recipient via the downstream provider for your channel (e.g. SendGrid for email delivery). Knock uses delivery statuses to track this lifecycle and show you where a given message resides within it.
You can use the "Logs" tab in the message detail view in the Knock dashboard to examine the history of requests Knock makes to the downstream provider to determine delivery status. The "Delivery status" field will show you the current status for your message.
### Delivery tracking methods
Knock uses two methods to track delivery status updates from your providers:
- **Provider webhooks.** Your provider sends delivery status updates directly to Knock via webhooks. This is the recommended method for real-time, reliable delivery tracking at scale. Provider webhooks eliminate rate limiting concerns and provide immediate status updates.
- **Polling.** Knock periodically polls your provider's API to check delivery status. This method is available for providers that don't support webhooks or as a fallback option.
You can configure which method to use in your channel settings. See the [delivery status tracking section](/send-notifications/delivering-notifications#delivery-status-tracking) for more details on how each method works. Check your provider's [integration page](/integrations/overview) for information about webhook support.
Figure 1 — The Knock message delivery status lifecycle.
Figure 1 above illustrates the full delivery status lifecycle. As the diagram implies, a message can only ever have one delivery status at a time. Plus, not all delivery statuses are available to all channels.
Lastly, delivery statuses are also hierarchical. Knock considers certain statuses more precedent than others when performing comparisons for things like [message status conditions](/designing-workflows/step-conditions#message-status-conditions).
Below we break down each status in detail (including any channel-specific limitations) in ascending order of precedence.
### 1) Undelivered
We attempted to deliver your message, we encountered an error, and _we will not retry delivery_. Your message has not made it from Knock to your provider.
You can use the message delivery logs to help identify what went wrong between Knock and the downstream provider. For more information about how Knock handles delivery attempts and retries, see our documentation on [message delivery retries](/send-notifications/delivering-notifications#retry-logic).
After you've resolved the underlying issue, you can [manually retry delivery](/send-notifications/delivering-notifications#manually-retrying-delivery) from the message detail view in the dashboard.
### 2) Bounced
Your message was successfully sent to the downstream provider, but the message was dropped by your provider due to bad recipient data, resulting in a bounce, and _we will not retry delivery_.
You can use the message delivery logs to help debug what may have gone wrong between Knock and the downstream provider. See our documentation on [message delivery retries](/send-notifications/delivering-notifications#retry-logic) for more details on how delivery attempts and retries at Knock work.
### 3) Delivery attempted
We attempted to deliver your message, but we encountered an error. If we deem the error retryable and we have not hit our retry limit, we will re-enqueue the message for another delivery attempt.
You can use the message delivery logs to help debug what may have gone wrong between Knock and the downstream provider. See our documentation on [message delivery retries](/send-notifications/delivering-notifications#retry-logic) for more details on how delivery attempts and retries at Knock work.
### 4) Queued
Your message has been created and has been queued to be sent to the provider. This may be the first attempt to deliver the message, or it may be a retry following an error. Messages sent outside a send window will remain queued until their scheduled send time.
### 5) Not sent
Your message was processed successfully but was not sent to the downstream provider because your channel is in [sandbox mode](/integrations/overview#sandbox-mode).
### 6) Sent
Your message has successfully made it from Knock to the delivery provider. It is their responsibility to ensure the message is properly _delivered_ to the recipient. Knock may be awaiting further information to determine if the message was successfully delivered.
On a per-channel level, `sent` means that:
- **Chat** — Your message has successfully been sent by Knock to the destination chat platform.
- **Email** — Your message made it to the delivery provider. We're waiting to learn if it made it to recipient.
- **In-app** — In-app messages automatically skip to the [`delivered`](#7-delivered) status. We always successfully deliver the message to the Knock Feed API.
- **Push** — Your message has successfully been sent by Knock to the destination push platform.
- **SMS** — Your message made it to the delivery provider. We're waiting to learn if it made it to recipient.
- **Webhook** — Webhook messages automatically skip to the [`delivered`](#7-delivered) status when Knock receives a `2xx`-status response from your endpoint.
### 7) Delivered
We've received confirmation from the delivery provider that your message was successfully sent to the recipient.
On a per-channel level, `delivered` means that:
- **Email** — Your message was successfully delivered to the recipient's email service provider.
- **In-app** — Your message was successfully delivered to the recipient's feed.
- **Push** — We do not support delivery tracking for push channels, so push channel messages will never have a delivery status greater than `sent`. However, you can introduce a handler into your mobile app to update a given message's [engagement status](#engagement-status) when the message has successfully made it to your recipient's device, using the `knock_message_id` from the push notification payload.
- **SMS** — Your message was successfully sent to the recipient's SMS provider. Note that not all SMS delivery providers support delivery tracking. See the [Knock integration documentation for SMS providers](/integrations/sms/overview) for more information.
- **Chat** — Delivery tracking is not available for chat platforms, so chat channel messages will never have a delivery status greater than `sent`. In most cases, a `sent` status will also mean that the message has been delivered to the recipient.
- **Webhook** — Your message was successfully delivered to your webhook endpoint.
Check your provider's [integration page](/integrations/overview) for specific information about `delivered` status support.
## Engagement status
Once delivered, Knock uses a set of engagement statuses to track how the recipient interacts with the notification. There are a few important things to note about how this works:
- **Engagement statuses are mutually inclusive.** Unlike delivery status, a message can have zero, one, or multiple engagement statuses. As an example, an in-app message can have an engagement status of both `seen` and `marked as read`.
- **Engagement statuses are hierarchical.** Like delivery status, engagement statuses have a concept of hierarchy. Knock sometimes uses this hierarchy when evaluating [message status step conditions](/designing-workflows/step-conditions#message-status-conditions).
- **Implicitly managed only sometimes.** In a couple cases, Knock will manage engagement status on your behalf. The [Knock React SDK](/in-app-ui/react/overview) will set engagement statuses for your in-app feed channels. Knock will also manage engagement statuses for any channel configured to use [Knock link and open tracking](/send-notifications/tracking). For other cases, you can use the [Knock Message status API](/api-reference/messages) to explicitly manage engagement statuses yourself.
Knock will include the set of current engagement statuses for your message in API responses as a list under the `engagement_statuses` field. Knock also uses timestamp columns to model the latest such action for each engagement type.
Below we review the possible engagement statuses and various per-channel caveats for how they work.
### Seen
| Timestamp field | Badge |
| --------------- | ------ |
| `seen_at` | `seen` |
Knock only implicitly manages this status for the in-app feed channel.
The `seen` status indicates that the message has been retrieved for display in the recipient's in-app feed at least once. The timestamp represents the time of the most recent action. The `seen` status is separate from an [opened/read status](/send-notifications/message-statuses#marked-as-read--opened), in that it doesn't indicate the recipient has explicitly interacted with the message itself.
### Marked as read / opened
| Timestamp field | Badge |
| --------------- | ------ |
| `read_at` | `read` |
The message has been opened and read by the recipient at least once. The timestamp represents the time of the most recent action.
Knock will implicitly manage this status only for the following channel configurations:
- **Email** — [Knock open tracking](/send-notifications/tracking) needs to be enabled.
- **In-app** — When you're using the [Knock ReactFeedProvider SDK](/in-app-ui/react/feed).
- **Push** — Not implicitly managed by Knock. However, you can manually set this status using the message engagement API with the `knock_message_id` from the push payload. If you're using one of Knock's mobile SDKs, this is handled automatically when a notification is tapped.
- **SMS** — Not directly supported. But, if [Knock link tracking](/send-notifications/tracking) is enabled, we will count a link-click action as also an open event.
- **Chat** — Not directly supported. But, if [Knock link tracking](/send-notifications/tracking) is enabled, we will count a link-click action as also an open event.
- **Webhook** — Not currently supported.
### Link clicked
| Timestamp field | Badge |
| ----------------------------------- | -------------- |
| `link_clicked_at` -or- `clicked_at` | `link_clicked` |
A link within your message was clicked by the recipient. The timestamp represents the time of the most recent action.
Knock will implicitly manage this status only for the following channel configurations:
- **Email** — [Knock link tracking](/send-notifications/tracking) needs to be enabled.
- **In-app** — [Knock link tracking](/send-notifications/tracking) needs to be enabled for link clicks to count towards this status. Only links within the message body will be tracked; clicks on the [action URL](/integrations/in-app/knock#action-url) that can be configured on the notification cell are tracked as [`interacted` events](#interacted). (**Note:** clicking “mark all as read” does not result in a message being marked as clicked; rather, as the phrasing implies, we bulk update the message engagement statuses to opened/read.)
- **Push** — Not supported. Push notifications don't support clickable links within their content, so Knock link tracking is not available for push. To track tap events on a push notification, use the [`interacted` status](#interacted) with its `metadata`.
- **SMS** — [Knock link tracking](/send-notifications/tracking) needs to be enabled.
- **Chat** — [Knock link tracking](/send-notifications/tracking) needs to be enabled.
- **Webhook** — Not currently supported.
### Interacted
| Timestamp field | Badge |
| --------------- | ------------ |
| `interacted_at` | `interacted` |
Knock only implicitly manages this status for the in-app feed channel.
For the in-app feed case, this indicates that your recipient has explicitly clicked on the notification cell in their feed. The timestamp represents the time of the most recent action.
### Archived
| Timestamp field | Badge |
| --------------- | ---------- |
| `archived_at` | `archived` |
Knock only implicitly manages this status for the in-app feed channel.
The message has been archived by the recipient. The timestamp represents the time of the most recent action.
## Message events
Knock records each change in message status, whether delivery or engagement, as a message event. You can view these events in chronological order of occurrence in the message timeline view in the Knock dashboard. Knock also uses these message events to power webhooks. See our [documentation on outbound webhooks](/developer-tools/outbound-webhooks/overview) to learn more about how you can hook into the Knock message status lifecycle.
## Link & open tracking
How to use Knock tracking to extend your ability to observe user engagement from right within your Knock account.
---
title: Link and open tracking
description: How to use Knock tracking to extend your ability to observe user engagement from right within your Knock account.
tags: ["link tracking", "open tracking", "open rates", "link clicks"]
section: Send notifications
---
## Overview
Knock provides opt-in, provider-agnostic tracking capabilities for your notifications. With Knock tracking, you get the same features with cross-channel tracking
events surfaced as first-class entities in a single place: your Knock account. Knock offers two types of tracking:
- **Link tracking.** Knock will wrap URLs in your notification and capture link-click events before directing your recipient to the destination.
- **Open tracking.** Currently for email channels only. Knock uses a 1x1 transparent "tracking pixel" to determine when a recipient opens and reads your email notifications.
Support for link and open tracking varies by channel type.
## Configuring Knock tracking
You can configure Knock tracking on a per-environment basis, using your channel's [per-environment configurations](/integrations/overview#per-environment-configurations). Open and link tracking will always default to `OFF` when you first create a channel.
Configuring Knock tracking for an email channel.
You won't find a configuration option for open tracking in the in-app feed
channel settings because open tracking is enabled implicitly whenever you
use the{" "}
KnockFeedProvider{" "}
component. If you're building your own in-app feed view with a Knock SDK,
you'll need to manage open tracking yourself by manually marking messages
as read.
}
/>
### Custom tracking domains
You can also configure custom domains for your account to use for link tracking, short links in SMS and WhatsApp, and email open tracking. See the [custom domains documentation](/manage-your-account/custom-domains) for more details.
### Step-level overrides
You can also configure Knock tracking on a per-workflow level. If a channel step in your workflow supports Knock tracking, you'll see tracking option toggles just below the channel selector form in the workflow editor. These toggles will reflect the environment-level channel configurations you have set until you modify them otherwise.
Step-level overrides allow you to opt-out of tracking for a specific workflow step, or vice versa.
Configuring Knock tracking for a workflow step.
## Working with Knock tracking
### Message events
Knock tracking events will be available in the message detail view in the Knock Dashboard.
When open tracking is enabled for an email channel, Knock will capture email-open actions as `message.read` events. You'll see a "Read at" timestamp reflecting the time of latest open event and a "Message read" item in the timeline view for each open action.
When link tracking is enabled, Knock will capture link-click actions as `message.link_clicked` events. You'll see a "Clicked at" timestamp reflecting the time of the latest link-click event and a "Message link clicked" item in the timeline view for each link-click action.
### Link-click trigger conditions
When link tracking is enabled for your channel, you can stitch link-click events into your workflows as a step condition. For example, you can require that at least one link in a previous channel step has been clicked for the current step to execute.
See the [step conditions documentation](/designing-workflows/step-conditions) for more details.
### Knock Webhooks
If you use Knock's outbound webhooks, you can hook into the `message.read` and `message.link_clicked` events captured via Knock tracking. See the [outbound webhooks documentation](/developer-tools/outbound-webhooks/overview) for more details.
## How it works
### Link-click tracking
When Knock renders a workflow step template into a notification message, it will additionally wrap URLs as trackable links. When a recipient opens one of these trackable links, Knock will record a link-click event before redirecting the user to the target destination. Knock defers the link-click event capture process, so redirects should be fast.
Knock is able to identify many types of URLs for tracking:
- **Hyperlinks** — Knock will replace HTML anchor tag and Markdown link target URLs with trackable links.
- **Chat app JSON** — Knock will traverse chat app JSON blobs (e.g. Slack Block Kit) and replace URL cards or anchor tags found within.
- **Bare URLs** — In Markdown templates, Knock will replace full-form URLs with trackable links wrapping the origin URL. For example, `https://foobar.com/` would become `[https://foobar.com/]()`.
In order for your URLs to be qualified as eligible for click tracking,
they must include the https:// protocol.
}
/>
There are two types of trackable links Knock may generate: standard and short. Standard links encode the target URL (and other event metadata) into a variable-length token added to the link path. Short links instead use a lookup key added to the link that maps to a record of the target URL. The short link lookup key will always be 10-characters in length, with short links always 31-characters long in total.
Given their brevity and consistent length, Knock will use short links for channels that often have character constraints. Specifically these are:
- All SMS channels
- WhatsApp chat channel
#### Opting single links out of tracking
When link tracking is enabled, Knock wraps every eligible URL in a notification as a trackable link, so a click on any of these links counts toward your engagement metrics. For some notifications, such as campaign emails, you may only care about clicks on your primary calls to action and you don't want footer or utility links—a privacy policy or help center link, for example—to count toward your click-through metrics.
To opt a single link out of tracking, add the `data-knock-no-track` attribute to its HTML anchor tag:
```html
Privacy policy
```
When Knock renders the notification, it will:
- Leave the link's original `href` untouched, so the recipient is sent directly to the destination URL.
- Remove the `data-knock-no-track` attribute from the rendered output.
- Skip capturing a `message.link_clicked` event when the recipient clicks the link.
Because this relies on an HTML attribute, opting out is available in channels that render HTML, such as email.
### Link-click tracking domains
In all cases, Knock trackable links will use one of the following domains:
| Subdomain | Series range | Example full domain |
| --------- | ------------ | ------------------------ |
| c | 1–3 | `https://c1.knock.app/` |
| e | 1–12 | `https://e2.knock.app/` |
| eg | 1–10 | `https://eg4.knock.app/` |
| ef | 1–10 | `https://ef3.knock.app/` |
**Other domains in use:**
- `https://c.knock.app/`
- `https://c1.knoclick.com/`
### Email-open tracking
Knock uses a 1x1 transparent PNG image to power email open tracking, often called a "tracking pixel." When you enable open tracking for an email channel, we embed a link to this image in the footer of the email message. The URL to load the image contains an identifier we can use to associate the image with the notification. When your recipient opens the email and loads the image for view, we register an open event with the associated message.
#### Email-open tracking limitations
Using tracking pixels to record email-open events has limitations. For one, it requires your recipients to use an HTML-enabled email client. In addition, many contemporary email providers and applications provide robust user privacy protections that purposefully limit open tracking capabilities. Some providers automatically block remote content (including images); others will cache images after an initial request, limiting our ability to track repeat opens.
Knock tracking tries to capture email-open events in as many possible cases, while still respecting end-user privacy restrictions.
Here are the email open tracking limitations we are currently aware of:
| Email provider / app | Limitation | Effect |
| ------------------------- | -------------------------------- | ------------------------------------------------------------------------------------------------- |
| Mail.app (iOS & macOS) | Optional remote content blocking | When enabled by the recipient, open tracking will not work. |
| iCloud Mail | Remote content blocking | This is enabled by default, and when enabled open tracking will not work. |
| Gmail (Android, iOS, Web) | Remote image caching | Gmail may preload the image, registering a false open event. Repeat email opens may not register. |
| Protonmail | Remote image caching | Images are always preloaded a single time following email delivery. Open tracking will not work. |
## Video walkthrough
## Frequently asked questions
Many of our [supported integrations](/integrations/overview) offer native link or engagement tracking that can be enabled in your Knock dashboard under that integration's [channel settings](/concepts/channels#channel-settings). Knock supports enabling these native tracking solutions alongside or instead of Knock tracking.
There are several Knock-tracking-specific features to keep in mind when configuring your channel's tracking settings:
- **Cross-channel reporting.** Knock link and open tracking allows you to analyze user engagement across all of your delivery channels in a single tool.
- **Step conditions.** With Knock tracking, you can use message engagement events to [power conditional logic in your workflows](/designing-workflows/step-conditions).
- **Capture events via webhooks.** When Knock tracking is enabled, you can power other event-based flows in your product with Knock's [outbound webhooks](/developer-tools/outbound-webhooks/overview).
No. While some providers offer native open and link tracking that can be enabled in your Knock dashboard under that integration's [channel settings](/concepts/channels#channel-settings), these native tracking solutions will not report back to Knock and do not enable the same functionality.
## Analytics
Learn how to measure message volume, delivery, and engagement across your workflows, guides, and channels.
---
title: Analytics
description: Learn how to measure message volume, delivery, and engagement across your workflows, guides, and channels.
tags:
[
"analytics",
"metrics",
"engagement",
"message volume",
"delivery rates",
"dashboard",
]
section: Send notifications
---
The [Analytics](https://dashboard.knock.app/~/analytics) page in the Knock dashboard gives you a high-level view of message volume, delivery, and engagement across your account. Use it to see how many messages you're processing, track delivery and engagement rates over time, and find the workflows, guides, and channels that drive the most activity.
## Overview
Metrics found on the Analytics page are scoped to the [environment](/concepts/environments) you're viewing and reflect your account's [data retention period](/manage-your-account/data-retention). The top of the page summarizes message activity for your selected time range and filters. Knock generates a [message](/concepts/messages) each time a workflow or broadcast runs a channel step for a recipient and the summary metrics roll those messages up by [delivery status](/send-notifications/message-statuses#delivery-status).
Below the summary metrics, you'll find two additional views:
- **Total messages processed chart.** A time series of message volume across the selected range. You can break this chart down by dimension — see [grouping data](#grouping-data) for details.
- **Top results tables.** Breakdown tables that rank your highest-volume workflows, guides, and channels for the current range and filters.
## Filtering data
The time range and the filter menu scope every metric, chart, and table on the page to your selections.
Use the time range selector to choose your reporting window, such as **Last 7 days**. You can report on any window within your account's data retention period.
Use the **Filter** menu to narrow the data to a subset of your messages. You can filter by:
- **Channel.** A specific configured [channel](/concepts/channels).
- **Channel type.** A class of channel, such as email, in-app feed, push, SMS, or chat.
- **Delivery status.** A point in the delivery lifecycle, such as `delivered` or `undelivered`.
- **Tenant ID.** The [tenant](/concepts/tenants) a message is scoped to.
- **Workflow.** The [workflow](/concepts/workflows) that generated the message.
- **Guide.** The [guide](/concepts/guides) that generated the message.
Select your filters and choose **Apply** to update the page, or **Clear** to reset them.
## Grouping data
The total messages processed chart supports grouping, which splits the single line into one line per value of the chosen dimension. Open the **Group by** menu on the chart and select one dimension:
- **Channel.** One line per configured channel.
- **Channel type.** One line per class of channel.
- **Delivery status.** One line per delivery status.
- **Engagement status.** One line per [engagement status](/send-notifications/message-statuses#engagement-status), such as seen, read, link clicked, interacted, or archived.
- **Workflow key.** One line per workflow.
- **Guide key.** One line per guide.
For example, grouping by engagement status renders a separate line for read, link clicked, seen, archived, and interacted, so you can compare how recipients engage over time. You can also set the chart type used to render the series.
## Understanding message events
Knock analytics are based on [message events](/send-notifications/message-statuses#message-events) which affects how engagement is counted and dated.
### Event counts
Engagement metrics include every event, not just the first occurence. A recipient who clicks the same message three times is reported as three clicks rather than one.
### Event dates
Engagement metrics are dated to when the event occurred, not when the message was created. For a message sent on March 1st and clicked on March 2nd, Knock shows a click event on March 2nd.
### Unique recipients
Unique recipients is a top-level metric that counts the number of distinct recipients across all messages processed for your selected time range and filters.
## Related docs
- [Message statuses](/send-notifications/message-statuses) — how Knock tracks delivery and engagement for each message.
- [Link and open tracking](/send-notifications/tracking) — capture the link clicks and email opens that feed engagement metrics.
- [Guide analytics and observability](/in-app-ui/guides/analytics-and-observability) — per-guide metrics for in-product messaging.
## Testing workflows
Learn more about how to test workflows you build in Knock.
---
title: Testing workflows
description: Learn more about how to test workflows you build in Knock.
tags: ["test", "testing", "CI", "continuous integration"]
section: Send notifications
---
Once you've built your workflow, you'll want to test it to make sure it works as expected. Knock provides a number of tools to help you test your workflows.
## The workflow test runner
You can use the Knock workflow test runner to test an end-to-end workflow and verify that it works as expected.
To use the workflow test runner, navigate to the workflow you want to test and click "Run a test." You'll have options to select the workflow's recipient, actor, tenant, and input any data that you'd like to pass to the workflow.
Two things to know about workflow test configuration:
- The data field is populated using the workflow's schema as defined in your templates. You can click "Reset" at any time to reset the data field to the latest and greatest schema for your workflow.
- The recipient and actor fields can contain either a [user](/concepts/users) or an [object](/concepts/objects). Use the toggle above the field to switch between these options.
After clicking "Run test," you will see a confirmation and a link to see the log to review the output and what was sent. You can learn more about Knock logs and the debugger [here](/send-notifications/debugging-workflows).
Note that [trigger frequency](/send-notifications/triggering-workflows/overview#controlling-workflow-trigger-frequency) is not enforced during test runs. Settings like "once per recipient" are bypassed — each time you run a test, the workflow will execute for the selected recipient regardless of your frequency setting. To validate trigger frequency as it behaves in production, use the [trigger API](/send-notifications/triggering-workflows/api).
You can also use the workflow test runner to run a test payload for a [source event trigger](/integrations/sources/overview#workflow-triggers). If your workflow is triggered by an event, you will automatically see a JSON payload of the last received event that you can use to run a test. You can edit this payload or click "Fetch the latest event" to get the most recent from your source.
### Test run settings
The test runner includes a few settings that control how the workflow executes during a test run:
- **Sandbox mode.** When enabled, all messages sent from the workflow are forced to send in [sandbox mode](/integrations/overview#sandbox-mode). Knock generates and previews the messages without delivering them to the underlying providers, regardless of how sandbox mode is configured on each channel. This is useful for testing a workflow end-to-end without sending real notifications to your recipients.
- **Skip delays.** When enabled, all [delay steps](/designing-workflows/delay-function) in the workflow are force skipped. The workflow runs straight through without waiting, which lets you verify the full execution path without waiting for delays to elapse.
You can also apply both of these settings when triggering a workflow via the API using the `settings.sandbox_mode` and `settings.skip_delay` properties, which is useful when testing workflows programmatically.
The workflow test runner uses the last saved version of the workflow, not
the last committed version. This means that you don't need to commit
workflow changes before testing them using the test runner. This is
different than calling the workflow with the API, which will always use
the last committed version of the workflow.
}
/>
## Testing workflows using the Knock CLI
You can also generate workflow runs using the `workflow run` command from the Knock CLI. You can learn more in our [CLI reference](/cli#workflow-run).
## Debugging workflows
Learn more about how to work with Knock's workflow debugger and API logs to easily debug your notification workflows.
---
title: Debugging workflows
description: Learn more about how to work with Knock's workflow debugger and API logs to easily debug your notification workflows.
tags: ["debugger", "logs", "errors"]
section: Send notifications
---
Sometimes you'll encounter issues with a workflow run that require more visibility into the Knock engine. Knock comes pre-built with a powerful workflow debugger that you can use to understand the state of individual workflow runs.
Using the workflow debugger, you can answer questions such as:
- What messages did this workflow run generate?
- Why did this step not produce any messages?
- Did this recipient have preferences set that opted them out from receiving a notification?
- What prevented this step from executing?
You can see a video of our workflow debugger in action here:
## Accessing the workflow debugger
See the{" "}
data retention docs for
more details on how Knock enforces this policy.
}
/>
You can access the workflow debugger from the "Runs" tab on a given workflow or the "Workflow runs" tab on a recipient record. You can also access it under **Observability** > **Runs** in the dashboard sidebar, which lists every workflow run in the current environment. Filter that list if desired, then select a run to open it in the debugger.
Finally, you can reach the debugger under **Observability** > **API logs** in the dashboard sidebar. From there:
1. Find an API log that triggered a workflow run (**hint**: you can use the filters to find only workflow API requests)
2. In the right hand panel, click the "Workflow runs" tab
3. Select a workflow run for any recipient to view the debugger
## Understanding workflow execution behavior
When a workflow runs, each step is executed in sequence. Sometimes an individual step is skipped or encounters an error, and it's important to understand how this affects the workflow run as a whole.
If you're reviewing a{" "}
test run, keep in mind
that{" "}
trigger frequency
{" "}
is not enforced by the dashboard test runner. Settings like {'"'}once per
recipient{'"'} are bypassed during test runs, so the workflow will execute
for the selected recipient each time regardless of your frequency setting.
This is expected behavior. To validate trigger frequency as it works in
production, trigger the workflow using the{" "}
API directly.
}
/>
### When a workflow step is skipped
There are several controlled scenarios where a step is skipped and the workflow run continues to execute subsequent steps.
Steps are skipped when:
- **Step conditions are not met.** If a step has [conditions](/designing-workflows/step-conditions) configured and they evaluate to false, the step is skipped.
- **Channel configuration is missing.** If the channel associated with a step has not been configured in the current environment, the step is skipped.
- **Recipient preferences opt out.** If the recipient has set [preferences](/preferences/overview) that opt them out of this notification type or channel, the step is skipped.
- **Recipient is missing required data.** If the recipient lacks the data required for delivery on this channel (for example, no `email` address for an email step, or no [channel data](/managing-recipients/setting-channel-data) for a push step), the step is skipped.
- **A dynamic [batch](/designing-workflows/batch-function), [delay](/designing-workflows/delay-function), or [throttle](/designing-workflows/throttle-function) step encounters an invalid window value.** If a workflow step encounters a missing or invalid dynamic window value (like a timestamp in the past), the step is skipped.
The workflow debugger will indicate when a step has been skipped and provide the reason why. This can help you understand why a recipient did not receive a notification on a particular channel, or why a workflow function was not processed as expected.
### When a workflow step fails
When a workflow step encounters an error during execution (such as a template rendering error or an error response from a [fetch](/designing-workflows/fetch-function) step), Knock will retry the step **up to 3 total times**. If all retry attempts fail, the step is marked as failed and **the workflow run is halted.** No subsequent steps will execute.
Common causes of workflow step failures include:
- **Template rendering errors.** Invalid Liquid syntax or missing required variables that prevent the message template from rendering.
- **Fetch step errors.** Errors or timeouts from the HTTP request made by the fetch step.
You can identify failed steps in the workflow debugger by looking for error states on individual steps. The debugger will show you the error details to help diagnose and fix the issue.
## Debugging workflows with a batch step
A [batch step](/designing-workflows/batch-function) aggregates many workflow runs into a single notification. The first trigger for a recipient opens the batch window. Every trigger that arrives while that window is open is added to the batch as an `activity`, and its own workflow run terminates at the batch step. When the window closes, the run that opened the batch continues to the next step.
This means that a workflow with a batch step produces two types of runs:
- **Runs that open a batch.** These runs pause at the batch step, then resume and execute the remaining steps when the window closes. Look here for any messages that were generated after the batch closed, along with any errors.
- **Runs that join a batch.** These runs terminate at the batch step. Steps after the batch step show "Will not execute" with the log "This workflow run was added to the batch function of a pre-existing workflow run." See the instructions below for finding the run that opened the batch and any messages that it generated after the batch window closed.
The batch step is what links runs together, and the workflow debugger surfaces that link in both directions.
### Finding the run that executed
Open any workflow run and **select the batch step** in the debugger. What you see depends on which type of run you selected:
| Label | Application | Description |
| ------------------------- | ------------------------------------------------------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Batched by** | Shown on a run that joined an open batch | Displays a link to the workflow run that started the batch. That run is where the rest of the workflow executes after the batch window closes. |
| **Batch closes at** | Shown on a run that opened a batch, while its window is still open | Displays a timestamp indicating when the batch window will close. The run remains in a `Paused` status until the window closes. Subsequent runs that are added to the batch will not be listed here until the window closes and the batch is finalized. |
| **Batched workflow runs** | Shown on a run that opened a batch, after its window has closed | Displays a list of up to ten of the runs collected into the batch, followed by the total number of runs in the batch (including the run that opened the batch; for example, "Showing 4 of 5 total batched workflow runs"). Follow any link to open a batched run in the debugger. |
### Batches that immediately flush the leading item
When a batch step is configured to [immediately flush its leading item](/designing-workflows/batch-function#immediately-flushing-the-first-item-in-a-batch), the run that opens the batch continues past the batch step right away and is not included in the final batch. Additional batched triggers are aggregated on the _second_ run added to the batch, so that is the run where you will find the batched workflow runs list and any messages that the batch generated.
# Recipients
Learn more about how to manage notification recipients with Knock.
## Overview
Learn more about managing recipients within Knock.
---
title: Overview
description: Learn more about managing recipients within Knock.
section: Managing recipients
---
[Recipients](/concepts/recipients) in Knock are the [users](/concepts/users) and [objects](/concepts/objects) that receive notifications. In this section, we walk you through managing recipient data for your environment, using both our API and Dashboard.
you may think it's odd to think about Objects as a recipient of a
notification. We use Objects as a way to model non-user recipients that
you may need to send a notification to from your system.
}
/>
#### Quick links
- [Identifying recipients](/managing-recipients/identifying-recipients)
- [Setting preferences](/preferences/custom-preference-center#set-user-preferences)
- [Setting channel data](/managing-recipients/setting-channel-data)
## Recipients and environments
Your recipient data exists **per environment**, meaning that each [environment](/concepts/environments) you have in your Knock account will contain a unique set of recipient data. If you have recipients that need to span across environments, then you should identify those recipients across each environment.
## Storing recipient data in Knock
In Knock, we refer to the process of storing recipient data as "identifying" one or many recipients. Your recipient data must exist in Knock to send notifications to those recipients or to reference the recipient within a notification template.
Identifying recipients is done programmatically via our REST API, either individually, in bulk, or inline when specifying a recipient in other calls.
[Learn more about identifying recipients ->](/managing-recipients/identifying-recipients)
### Why store recipient data in Knock
If you're used to sending notifications via single-channel APIs, the idea of storing recipient data in a messaging platform such as Knock may sound odd to you.
Here are a few reasons why we store recipient data in Knock:
- **Multi-channel notifications.** When you're using a single-channel API, you can pass through the recipient's email address or phone number when you trigger a message. In a multi-channel platform like Knock, that would mean passing through _all_ of a recipient's channel information every time you trigger a notification. By keeping a recipient model in Knock, you can update a recipient's channel information once, then reference them via their recipient ID from that point on. We take care of the rest.
- **Stateful in-app notifications.** The Knock Feed API returns a stateful feed of the in-app notifications a given recipient has received from your product. The Knock recipient model is used to store a given recipient's notification feed and to give you a way to retrieve that feed via the recipient identifier you keep for them in your product.
- **Preferences model.** The Knock recipient model enables advanced functionality such as preferences support, where you store a given recipient's notification preferences in Knock and we reference that recipient's preferences during the run of a given notification workflow.
- **Leverage recipient traits in notification templates.** The Knock recipient model also enables you to store custom traits on a given recipient that you can reference in a notification template. This is helpful when you want to add conditional copy to a notification based on a recipient's role or plan.
We do not take storing your recipient data lightly. You can learn more about our security posture and best practices on [our security page](/security).
## Fetching recipient data
From the API you can retrieve information about the recipient data that you have stored inside of Knock. Recipient information is accessible from both the client-side and server-side using the appropriate [API keys](/developer-tools/api-keys).
You can find more about retrieving recipients in the [API reference](/api-reference).
## Working with recipients in the dashboard
The Knock dashboard also provides access to the Users and Objects that you have identified within each environment. From the dashboard you can:
- Search for a specific recipient by id, name, or email
- View the recipient, including any custom properties set
- View recipient channel data
- View and manage recipient preferences
- View recent messages sent to the recipient
- View recent workflow runs for the recipient
- View any schedules for the recipient
## Identifying recipients
Learn more about how to identify your user and object recipients to power your notifications.
---
title: Identifying recipients
description: Learn more about how to identify your user and object recipients to power your notifications.
tags:
[
"recipients",
"inline identify",
"identify",
"bulk identify",
"import users",
"create users",
"users",
"objects",
]
section: Managing recipients
---
To send notifications to a recipient or reference them as an actor in a notification, their data must be stored in Knock. This process is called **identifying** and works across user and object recipients.
Recipient properties enable Knock to deliver personalized notifications. Properties like `email` and `phone_number` are essential for message delivery, while `name` and custom properties power personalization in your notification content and workflow logic. Properties like `timezone` and `locale` enable you to design mindful notifications for users around the world via [send windows](/designing-workflows/send-windows) and [translations](/template-editor/translations). Knock also tracks [delivery and engagement analytics](/send-notifications/message-statuses) for each identified recipient, giving you insights into notification performance and user behavior.
There are three ways to identify recipients:
- **Direct identification**. Make a single server-side API request (`PUT /v1/users/{user_id}`) to upsert one recipient.
- **Inline identification**. Upsert recipients by including recipient data in other server-side API requests (e.g., `POST /v1/workflows/{workflow_key}/trigger`) or when initializing the `KnockProvider` client-side.
- **Bulk identification**. Make a single server-side API request (`POST /v1/users/bulk/identify`) to upsert many recipients at once.
All identification methods in Knock use an upsert approach. This means any
existing data for a recipient is merged during the upsert operation.
}
/>
## Direct identification
Make a server-side API request to upsert a single recipient in Knock. This is useful to ensure that recipient data is updated on an ongoing basis, like reflecting updates to user information or changes to object properties in your system.
[API reference ->](/api-reference/users/update)
## Inline identification
You can also identify recipients during other operations, eliminating the need for separate identification API calls.
When using inline identification, Knock guarantees that recipients are identified before executing any other action. This enables lazy recipient creation within Knock and ensures that your recipients exist within Knock before executing calls that reference them. Inline identification is available server-side for both users and objects, and client-side for users only.
Inline identification requires a list of [recipient objects](/api-reference/recipients/schemas/recipient_request) where each object must include an `id`, but may include other properties to be upserted.
Server-side, inline identification works with any endpoint that accepts a list of recipients:
- [Workflow triggers](/api-reference/workflows/trigger)
- [Schedules](/api-reference/schedules/create)
- [Bulk schedules](/api-reference/schedules/bulk/create)
- [Subscriptions](/api-reference/objects/add_subscriptions)
- [Bulk subscriptions](/api-reference/objects/bulk/add_subscriptions)
[API reference ->](/api-reference/workflows/trigger)
Client-side identification is handled automatically when you initialize the `KnockProvider` with user data provided. When mounted, the provider will identify the user in Knock by upserting the provided user information.
This approach is particularly useful for in-app UI components like [feeds](/in-app-ui/react/feed#rendering-the-component) and [guides](/in-app-ui/guides/render-guides#getting-started), where user data is immediately required in your frontend application. Note that client-side identification is currently only available for users.
```jsx title="Client-side identification with KnockProvider in React"
import { KnockProvider } from "@knocklabs/react";
const YourAppLayout = ({ user }) => {
return (
{/* Your app content with Knock guides or feed components */}
);
};
```
Client-side identification should only be used with your{" "}
public API key and is best suited for use cases where you're
displaying in-app notifications. For more sensitive operations or when you
need to set extensive user properties, use server-side identification methods.
} />
## Bulk identification
The bulk identification endpoint enables you to upsert many recipients in a single server-side request. This is ideal for initial data imports or large-scale updates.
[API reference ->](/api-reference/users/bulk/identify)
## Setting recipient properties
When identifying recipients, you pass a set of properties that are persisted. We recommend using your internal user identifier for the `id` value, which is the only required property. Although additional properties aren't required for identification, some properties such as `email` or `phone_number` are required for certain [channel steps](/designing-workflows/channel-step).
### Reserved properties
Recipients have some reserved property names:
| Property | Description |
| -------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name` | The name of the recipient. |
| `email` | A valid email address to deliver email notifications to. |
| `avatar` | A URL for the avatar of the recipient. |
| `locale` | A locale code for the recipient, used for internationalizing content. |
| `phone_number` | An E.164 compliant phone number field used when sending SMS messages. |
| `timezone` | A valid tz database time zone string used for [send windows](/designing-workflows/send-windows) and [schedules](/concepts/schedules). |
| `created_at` | An ISO-8601 datetime indicating when the recipient was created. **Note:** This is an optional property that you must explicitly set from your system - Knock does not handle this implicitly and it will be `null` unless provided. |
### Custom properties
Recipients also accept any number of custom properties as key-value pairs that you define. Custom properties enable you to reference recipient attributes when sending notifications.
When directly identifying your recipients, an update that would result in
a total custom properties size exceeding this limit will result in a{" "}
422 response.
}
/>
## When to identify
Knock provides a flexible set of APIs for you to manage your user data as you scale with us. Ultimately, it's up to you to decide upon the best approach for how you manage your user data with Knock.
### Initial setup
When getting started with Knock, you'll likely have existing recipients to migrate into Knock:
- **Quick start**. Use [inline identification](#inline-identification) to start calling your workflows without any prerequisite calls to the Knock API.
- **Data import**. Use our [bulk identification](/api-reference/users/bulk/identify) to import all recipient data into Knock first.
### Ongoing updates
After identifying your current recipients in Knock, you'll want to continue to update this data when:
- New recipients sign up for your product.
- Knock-relevant data (e.g., `name` or `email`) about a user changes.
A common approach is making subsequent calls to Knock's user identify API following such events. Many customers do this via a deferred job in their backend systems.
Another option is to offload these updates to your workflow trigger calls via inline identification. If you always send Knock the full set of data for your recipients [via workflow trigger calls](/api-reference/workflows/trigger), you can keep your user data up to date in Knock without any additional handling on your end.
## Frequently asked questions
A common mistake when implementing inline identification is accidentally passing a list of user ID strings instead of user objects. Inline identification requires user objects (even if they only contain an `id` property), not ID strings.
```json title="Incorrectly passing ID strings"
{
"recipients": ["user-123", "user-456"]
}
```
```json title="Correctly passing user objects"
{
"recipients": [ { "id": "user-123" }, { "id": "user-456" } ]
}
```
Yes, preferences can be set during identification, but it's important to understand the implications. Unlike our preferences endpoints, setting preferences during identification will perform a deep merge of the provided preferences into any existing preferences (just like any other properties stored on the recipient). Unless you intend to leverage this behavior for a specific use case, we generally recommend updating preferences directly via the preferences endpoints.
To set preferences during identification, provide a dictionary under the `preferences` key with each key representing a preference set ID. Unlike the preferences [endpoints](/preferences/overview), setting preferences during identification requires explicitly providing the `default` preference set key when updating default preferences.
```json title="Providing preferences during identification"
{
"id": "user-123",
"name": "John Doe",
"preferences": {
"default": {
"channel_types": { "email": true, "sms": false }
}
}
}
```
For workflow triggers with [inline identify](/send-notifications/triggering-workflows/api#identifying-recipients-inline), one or more preference sets (including [per-tenant preferences](/multi-tenancy/per-tenant-preferences)) can be upserted by passing a dictionary of [PreferenceSets](/preferences/overview).
[API reference ->](/api-reference/workflows/trigger)
Yes, channel data can be set during identification by passing a dictionary under the `channel_data` key, where each key represents the channel ID and the value contains the channel-specific data.
```json title="Setting channel data during identification"
{
"id": "user-123",
"name": "John Doe",
"channel_data": {
"some-uuid-for-a-channel": {
"tokens": ["my-push-token"]
}
}
}
```
This is particularly useful for setting push notification tokens, device information, or other channel-specific configuration data when identifying users.
## Recipient schemas
Curate the schemas Knock infers for your users, tenants, and objects. Hide properties, add labels and descriptions, and set preview text.
---
title: Recipient schemas
description: Curate the schemas Knock infers for your users, tenants, and objects. Hide properties, add labels and descriptions, and set preview text.
section: Managing recipients
---
Knock builds a schema for each type of recipient in your environment (your [users](/concepts/users), your [tenants](/multi-tenancy/overview), and each [object](/concepts/objects) collection) by inferring the properties, types, and preview text from the recipient data you send. Schema management gives you control over that schema. You can hide properties you don't want to surface, add human-readable labels and descriptions, and set preview text that is used when previewing templates.
Curating a schema shapes how recipient properties appear across the Knock dashboard: in the template editor, in condition and segment builders, and in recipient tables. It also makes your data legible to the Knock agent, which reads your schema to understand what properties exist and what they mean.
## How recipient schemas work
As you [identify recipients](/managing-recipients/identifying-recipients), Knock observes the properties on that data and records them on the schema for that recipient type. Each property carries:
- **Key.** The property name, such as `plan` or `address.city`.
- **Type.** The data type Knock inferred from your data, such as `string`, `number`, `boolean`, `object`, or `array`. Types are read-only.
- **Source.** Whether Knock inferred the property from your data or it is a built-in system property, such as `email` on a user. This is read-only.
- **Preview text.** A value Knock has seen for the property, used to render realistic previews of templates that reference it.
Schemas are logically isolated per [environment](/version-control/environments), the same way recipient data is. A property that only appears in production will not show up on your development schema until Knock sees it there.
Schema management applies to recipient data: users, tenants, and object
collections. Source events, workflow trigger data, and broadcast data are
not part of recipient schemas.
}
/>
## Curate a schema in the dashboard
Go to **Settings** > **Schemas** and select a recipient type: users, tenants, or one of your object collections. You will see every property Knock has inferred for that type, along with its type, source, and preview text.
### Hide or show a property
Toggle a property's visibility to control where Knock offers it. When you hide a property, Knock stops offering it across the dashboard: template variable suggestions, condition and audience segment builders, and recipient table columns no longer list it.
Hiding a property controls where it is offered, not whether it exists.
Anything that already references a hidden property keeps working, and the
property is still returned by the API. Because nothing can break, you can
hide properties to tidy up what your team sees.
}
/>
### Add a label and description
Give a property a **label** to set a human-readable display name, and a **description** to explain what the property is for and how it should be used. Labels and descriptions help your team choose the right property, and they give the Knock agent context about your data.
### Set the preview text
Set the **preview text** for a property to control how it renders in template previews. When you preview a template that references the property, Knock uses this value so the preview reflects realistic data. In the Management API and CLI, this is the property's `preview_text` field.
## Where curated schemas appear
Once you curate a schema, it drives every place Knock surfaces recipient properties, including:
- **Template editor.** Variable suggestions offer only visible properties, and previews use your preview text.
- **Condition and segment builders.** Property pickers for [conditions](/designing-workflows/step-conditions) and [audiences](/concepts/audiences) list only visible properties.
- **Recipient tables.** Column options reflect the curated schema.
## Permissions
Access to schema management is tied to your [role](/manage-your-account/roles-and-permissions).
| Capability | Roles |
| --------------------------------------------------- | -------------------- |
| View schemas | Member, Admin, Owner |
| Set the preview text, or add a property | Member, Admin, Owner |
| Hide or show a property, add a label or description | Admin, Owner |
## Environments and branches
Schema configuration is scoped to an environment and applies immediately when saved, the same way [environment variables](/concepts/variables) do, rather than through commit and promote. Curate the schema in the environment whose data you want to manage.
[Branch](/version-control/branches) environments inherit the schema and curation from their parent environment and are read-only for schema changes. Editing a schema from a branch is rejected with a pointer to the parent environment. Manage the schema from the parent environment instead.
## Sync schemas with the Management API
You can read and update recipient schemas with the [Management API](/developer-tools/management-api). This is useful for version-controlling your schema configuration or for applying the same curation across environments.
| Method and path | Description |
| -------------------------------------- | ---------------------------------------------- |
| `GET /v1/schemas` | List the schemas in an environment. |
| `GET /v1/schemas/{item_type}` | Retrieve the schema for a recipient type. |
| `PUT /v1/schemas/{item_type}` | Update the schema for a recipient type. |
| `PUT /v1/schemas/{item_type}/validate` | Validate a schema payload without applying it. |
`item_type` is `user`, `tenant`, or `object`. For object schemas, pass the collection with a `collection` query parameter.
Each schema is a list of properties:
```json title="A user schema"
{
"item_type": "user",
"item_id": null,
"properties": [
{
"key": "plan",
"type": "string",
"preview_text": "\"enterprise\"",
"visible": true,
"label": "Plan",
"description": "The account's current billing plan."
}
]
}
```
The curatable fields on a property are:
| Field | Type | Description |
| -------------- | ------- | ------------------------------------------------------------------------- |
| `visible` | boolean | Whether the property is offered across the dashboard. Defaults to `true`. |
| `label` | string | An optional human-readable display name. |
| `description` | string | An optional description of the property. |
| `preview_text` | string | The preview text, JSON-encoded, used to preview templates. |
A property's `type` and `source` are inferred by Knock and are read-only.
The same role-based permissions govern the Management API: any member can
read schemas, set preview text, and add properties, while hiding or
showing a property or setting a label or description requires an admin or
owner.
}
/>
## Sync schemas with the CLI
The [Knock CLI](/cli/overview) can pull schemas from an environment to local files and push local changes back, so you can keep your schema configuration in version control alongside your other Knock resources.
```bash title="Pull and push schemas"
# Pull every schema in the environment into a local schemas directory
knock schema pull --all
# Push a single recipient schema to an environment
knock schema push user --environment=production
# Push an object collection schema
knock schema push object --collection=projects --environment=production
```
Schemas are stored in a `schemas/` directory, one file per recipient type. See the [schema CLI reference](/cli/schema) for the full set of commands and flags.
## Limitations
- Hidden properties are still returned by the API. Hiding affects where a property is offered in the dashboard, not API responses.
- Property types are inferred and read-only.
- Schemas cover recipients only: users, tenants, and objects. Source events, workflow trigger data, and broadcast data are not yet included.
- Knock does not yet track where a property is used or validate incoming data against your schema.
## Setting channel data
Learn about how to set channel data for your recipients and users to make it easy to connect recipients with push and chat channels.
---
title: Setting channel data
description: Learn about how to set channel data for your recipients and users to make it easy to connect recipients with push and chat channels.
tags: ["channels", "slack", "push", "tokens", "recipients", "msteams", "teams"]
section: Managing recipients
---
Some channel integrations require user and channel-specific data to send notifications. Push channels like APNs (Apple Push Notification Service) and FCM (Firebase Cloud Messaging) are good examples, where both require that there are device-specific tokens that target the user in a push notification. Slack is another good example, where the channel data from a Slack integration in your product is stored on a Knock [object](/concepts/objects).
At Knock we call this concept `ChannelData`. For most channels, `ChannelData` lives under a [user](/concepts/users) or an [object](/concepts/objects) and stores channel-specific data to be used when that user or object is included as a recipient on a [triggered workflow](/send-notifications/triggering-workflows). For chat providers that support tenant-stored credentials, `ChannelData` can also live on a [tenant](/multi-tenancy/overview) to provide shared auth while the recipient stores the destination.
## Things to know about channel data
- For channel types that require channel data (such as [push](/integrations/push/overview) channels and [chat](/integrations/chat/overview) channels like Slack), the channel step will be skipped during a workflow run if the required `channel_data` is not stored on the recipient.
- Knock stores channel data for you but makes no assumptions about whether the stored channel data is valid. That means that if a push token expires, it's your responsibility to omit/update that token for future notifications.
- For push providers, Knock offers an opt-in [token deregistration](/integrations/push/token-deregistration) feature that automatically removes invalid tokens from a recipient's channel data when messages bounce.
- Setting channel data always requires a `channel_id`, which can be obtained in the Dashboard under the **Channels and sources** page in your account settings. A channel ID is always a UUID v4.
## Setting channel data
Before getting or setting channel data, you must first configure that channel in your environments. You can do this inside the Knock dashboard under the **Channels and sources** page in your account settings. Once the channel for which you want to store channel data has been created, you're ready to store the channel data for your users and objects.
There are three ways of setting channel data for a given recipient:
1. Explicitly using the set channel data method
2. Inline through a workflow trigger
3. When identifying a recipient
You can set channel data for a given user using the `users.setChannelData` method. Please note that the channel data will always be overwritten with each `set` call.
If no user exists in the current environment for the given `user_id`, Knock will create the user entry as part of this request.
In the example below, we're setting a user's device token when they download our mobile app so we can send them push notifications. If this token wasn't set for the user, they wouldn't receive push notifications from our notification workflows.
To directly set user channel data from iOS, Android, or Flutter applications, see [iOS push notifications](/in-app-ui/ios/sdk/push-notifications), [Android push notifications](/in-app-ui/android/sdk/push-notifications), and [Flutter push registration](/in-app-ui/flutter/sdk/reference#registertokenforchannel).
You can set channel data for a given object using the `objects.setChannelData` method. Please note that the channel data will always be overwritten with each `set` call.
In the example below, we're setting an object's Slack channel ID and access token, presumably after a user in our product has decided to connect the object to their Slack workspace. This enables us to send Slack notifications to the connected Slack channel when an event is triggered within the scope of the object.
You can learn more about objects in [the objects concept overview](/concepts/objects) and [API reference](/api-reference/objects).
For both user and object recipients, channel data can be specified inline during a [workflow trigger call](/managing-recipients/identifying-recipients#inline-identification).
When setting channel data inline for a recipient entity, you must supply the channel data as a dictionary containing the channel ID as a key, and a dictionary of channel data to set for that channel.
For both [user](/api-reference/users/update) and [object](/api-reference/objects/set) recipients, channel data can be specified as a recipient property on an identify request.
When setting channel data for a recipient entity on an identify request, you must supply the channel data as a dictionary containing the channel ID as a key, and a dictionary of channel data to set for that channel. The below example is for a `User`, but the same pattern can be followed for an `Object`.
## Getting channel data
To retrieve the currently set channel data, you can use the `getChannelData` method on `users` and `objects`. If
channel data is not set for the recipient you'll receive a `404` response.
## Clearing channel data
Any previously set channel data can be cleared by issuing an `unsetChannelData` call. Unsetting channel data for a recipient requires a valid channel ID to be passed.
For push providers, Knock can automatically remove invalid tokens from a
recipient's channel data when messages bounce. Learn more about this
opt-in feature in our{" "}
token deregistration documentation
.
}
/>
## Provider data requirements
Channel data requirements for each channel type and provider are listed below. Typically `channel_data` comprises a `token` or other value that is used to uniquely identify a user's device.
### Push channels
You can set push channel data by passing either:
- A list of `tokens` (or `target_arns` for [Amazon SNS](/integrations/push/aws-sns)) strings
- A list of `devices` objects for supported push providers. If set, this [device-level metadata](/integrations/push/device-metadata) will be used when evaluating [translations](/template-editor/translations) and [send windows](/designing-workflows/send-windows).
#### The `PushDevice` object
The `PushDevice` object is used to optionally set device-level metadata for a push channel. It contains the following properties:
| Property | Type | Description |
| ------------ | -------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| token\* | `string` | The device token to send the push notification to. Required for providers other than Amazon SNS. |
| target_arn\* | `string` | The ARN of a platform endpoint associated with a platform application and a device token. Required for Amazon SNS. |
| locale | `string` | The [locale](/template-editor/translations#supported-locales) of the device. |
| timezone | `string` | The timezone of the device. Must be a valid tz database time zone string. |
#### Provider-specific requirements
You must provide one of `tokens` or `devices`.
| Property | Type | Description |
| --------- | ---------------------------------------- | --------------------------- |
| tokens\* | `string[]` | One or more device tokens. |
| devices\* | [`PushDevice[]`](#the-pushdevice-object) | One or more device objects. |
You must provide one of `tokens` or `devices`.
| Property | Type | Description |
| --------- | ---------------------------------------- | --------------------------- |
| tokens\* | `string[]` | One or more device tokens. |
| devices\* | [`PushDevice[]`](#the-pushdevice-object) | One or more device objects. |
You must provide one of `tokens` or `devices`.
| Property | Type | Description |
| --------- | ---------------------------------------- | --------------------------- |
| tokens\* | `string[]` | One or more device tokens. |
| devices\* | [`PushDevice[]`](#the-pushdevice-object) | One or more device objects. |
You must provide one of `target_arns` or `devices`.
| Property | Type | Description |
| ------------- | ---------------------------------------- | ------------------------------- |
| target_arns\* | `string[]` | One or more device target ARNs. |
| devices\* | [`PushDevice[]`](#the-pushdevice-object) | One or more device objects. |
| Property | Type | Description |
| ------------ | ---------- | ---------------------- |
| player_ids\* | `string[]` | One or more player_ids |
### Chat app channels
| Property | Type | Description |
| ----------- | ------------------- | -------------------------------- |
| connections | `SlackConnection[]` | One or more connections to Slack |
A `SlackConnection` can have one of two schemas, depending on whether you're using standard Slack OAuth scopes or an incoming webhook.
We cover Slack app scopes in detail in our [Slack scopes documentation](/in-app-ui/react/slack-kit).
If you're using standard Slack OAuth with access token scopes, your `SlackConnection` schema looks like this. You'll use
either a `channel_id` or `user_id` depending on whether you're storing connection data to message a channel or user in Slack:
| Property | Type | Description |
| ------------ | -------- | ------------------------------------------------------------------------------------------------------------------------------------ |
| access_token | `string` | A bot access token. Not required when the token is [stored on a tenant](/integrations/chat/slack/overview#tenant-channel-data-requirements). |
| channel_id | `string` | A Slack channel ID |
| user_id | `string` | A Slack user ID |
If you're using a Slack app with the `incoming-webhook` scope your `SlackConnection` schema is quite simple:
| Property | Type | Description |
| -------------------- | -------- | --------------------------------------------------------------------------- |
| incoming_webhook.url | `string` | The Slack incoming webhook URL (to be used instead of the properties above) |
| Property | Type | Description |
| ----------- | --------------------- | ---------------------------------- |
| connections | `DiscordConnection[]` | One or more connections to Discord |
A `DiscordConnection` has the following schema:
| Property | Type | Description |
| -------------------- | -------- | ----------------------------------------------------------------------------- |
| channel_id | `string` | A Discord channel ID |
| incoming_webhook.url | `string` | The Discord incoming webhook URL (to be used instead of the properties above) |
| Property | Type | Description |
| ----------- | --------------------- | ---------------------------------- |
| connections | `MsTeamsConnection[]` | One or more connections to MsTeams |
An `MsTeamsConnection` can have one of two schemas, depending on whether you're using a Microsoft Teams bot or an incoming webhook.
If you're using a Microsoft Teams bot, your `MsTeamsConnection` schema looks like this. You'll use either
`ms_teams_channel_id` or `ms_teams_user_id` depending on whether you're storing connection data to message
a channel or user in Microsoft Teams:
| Property | Type | Description |
| ------------------- | -------- | ----------------------------------------------------------------------------------------------------------------------------------------- |
| ms_teams_tenant_id | `string` | A Microsoft Entra tenant ID. Not required when stored on a [tenant](/integrations/chat/microsoft-teams/overview#tenant-channel-data-requirements). |
| ms_teams_team_id | `string` | A Microsoft Teams team ID |
| ms_teams_channel_id | `string` | A Microsoft Teams channel ID |
| ms_teams_user_id | `string` | A Microsoft Teams user ID |
If you're using an incoming webhook, your `MsTeamsConnection` schema is quite simple:
| Property | Type | Description |
| -------------------- | -------- | --------------------------------- |
| incoming_webhook.url | `string` | The Microsoft Teams incoming webhook URL (to be used instead of the properties above) |
## Deleting users
Learn more about how user deletions work within Knock and how deletion can help with data privacy controls.
---
title: Deleting users
description: Learn more about how user deletions work within Knock and how deletion can help with data privacy controls.
tags: ["right to be forgotten", "gdpr", "rtbf", "forgotten"]
section: Managing recipients
---
Knock provides a programmatic user deletion API that you can use to hard delete users and the data associated with users. This can be especially useful in fulfilling GDPR right-to-be-forgotten requests.
deleting users is a destructive operation and once deleted, the data for
that user cannot be recovered.
}
/>
## What data is deleted for a user?
When a user is deleted in Knock, we will **hard delete**:
- All system and custom properties set on the user
- All preferences associated with the user
- All channel data associated with the user
- All subscriptions associated with the user
- All schedules associated with the user
- All messages sent to that user, including the content of those messages and any debugging events associated
- All activity associated with a user, including the workflow run logs the user was a recipient of
**Note**: deletion requests can take up to 10 minutes to process. During this time, you may still see some data associated with the user.
## Frequently asked questions
Yes, you can manually delete individual users from the Knock dashboard.
Yes, Knock is GDPR compliant.
Absolutely. You can use our single-user deletion endpoint, or batch up
deletion requests per-day using our bulk delete endpoint.
Please get in touch with us if you have this requirement.
You can re-add the same user using the previous user's identifier. The new
user will not inherit any of the past user's data, given that will have been
deleted.
## Merging users
Learn more about merging user data.
---
title: Merging users
description: Learn more about merging user data.
section: Managing recipients
---
You might run into the scenario where you've identified an invited user to send them a notification and then that user "graduates" to a fully-fledged user after they sign up, leaving you with two users in Knock. That's where the merge users method comes in handy.
Merging two users will merge the `secondary` user (the invited user in our example) into the `primary` user (the signed-up user), and the secondary user will be deleted in the process.
performing a merge is a destructive operation and cannot be undone.
}
/>
## What's merged?
- **Properties**: Properties are deep merged, but if there are any conflicts between the secondary and primary user then the value is selected from the primary user.
- **Preferences**: Preference sets are shallow merged between the users. Any preference sets that don't exist on the primary from the secondary are added.
- **Channel data**: Channel data is shallow merged from the secondary to the primary. Any channel data that doesn't exist on the primary from the secondary is added, determined by the channel_id.
- **Message history**: The past 30 days of message history of the secondary user will now be owned by the primary recipient.
- **Activities**: Any activities from the past 30 days that the secondary user was an `actor` or `recipient` of will be transferred to the primary user.
If you need to retain more than 30 days worth of history, please contact us.
## Frequently asked questions
Merging does not transfer in-flight workflow or broadcast runs to the primary user. If a run for the secondary user is paused at a delay, batch, or wait-for-event step, it remains associated with that user. When the run resumes, it is stopped before sending a notification because the secondary user has been deleted. Knock does not redirect the run to the primary user.
To make sure an in-flight notification is still delivered, wait for the workflow or broadcast to complete before merging the users.
# Multi-tenancy
Learn how to use Knock's multi-tenancy features to power per-tenant notification experiences.
## Overview
Learn how to map your multi-tenant application into Knock using tenants.
---
title: Tenants
description: Learn how to map your multi-tenant application into Knock using tenants.
tags:
["tenant", "tenancy", "saas", "how knock works", "custom brand", "branding"]
section: Multi-tenancy
---
Tenants represent segments your users belong to. You might call these "accounts," "organizations," "workspaces," or similar. This is a common pattern in many SaaS applications: users have a single login joined to multiple tenants to represent their membership within each.
You use tenants in Knock to:
- [Scope in-app feeds](/multi-tenancy/tenant-scoped-messaging) so users only see notifications relevant to their active workspace.
- Apply [per-tenant branding](/multi-tenancy/per-tenant-branding) in emails.
- Define [per-tenant preference defaults](/multi-tenancy/per-tenant-preferences#create-a-per-tenant-default-preferenceset) that apply to all users within that tenant and [per-user, per-tenant preferences](/multi-tenancy/per-tenant-preferences#set-a-per-tenant-user-preferenceset).
- Apply [per-tenant translations](/multi-tenancy/per-tenant-translations).
- Hold shared channel credentials as [channel data](/managing-recipients/setting-channel-data), so one integration connection can serve recipients and objects in the tenant.
## How tenants work
Each tenant is uniquely identified by an `id` [per-environment](/concepts/variables) — in most cases the same ID you use in your own system. Tenants can store any number of custom properties alongside branding overrides and preference defaults, and are fully manageable via the API.
Behind the scenes, a tenant is a system-level [Object](/concepts/objects) in a special collection called `$tenants`, which means anything you can do with an object you can do with a tenant.
By default, Knock creates a stub tenant object for any tenant ID you pass when triggering a workflow. You can also use the [tenant APIs](/api-reference/tenants) to create and manage tenants explicitly.
## Creating tenants
Use the [tenant API methods](/api-reference/tenants) to create or update a tenant, including any custom properties and settings.
### Required attributes
| Property | Description |
| -------- | ---------------------------------------- |
| `id` | A string to uniquely identify the tenant |
### Optional attributes
| Property | Description |
| ---------- | ----------------------------------------------------- |
| `name` | An optional name to associate with the tenant |
| `*` | Any custom properties you wish to store on the tenant |
| `settings` | A `TenantSettings` object to apply (see below) |
### `TenantSettings`
| Property | Description |
| -------------------------------------- | ---------------------------------------------------------------------------------------------------------- |
| `branding.logo_url` | A fully qualified URL for an image to use as the logo of this tenant |
| `branding.icon_url` | A fully qualified URL for an image to use as the icon of this tenant |
| `branding.dark_logo_url` | A fully qualified URL for the logo to use in dark mode. Defaults to `logo_url` if not set |
| `branding.dark_icon_url` | A fully qualified URL for the icon to use in dark mode. Defaults to `icon_url` if not set |
| `branding.primary_color` | A hex value for the primary color. Defaults to `#000000` |
| `branding.primary_color_contrast` | A hex value for the contrasting color to use with the primary color. Defaults to `#FFFFFF` |
| `branding.dark_primary_color` | A hex value for the primary color in dark mode. Defaults to `#FFFFFF` |
| `branding.dark_primary_color_contrast` | A hex value for the contrasting color in dark mode. Defaults to `#000000` |
| `preference_set` | A complete `PreferenceSet` to use as a default for all recipients with workflows triggered for this tenant |
In Knock's Python SDK v1.0+, the optional name property and
any custom properties provided must be passed in via the{" "}
extra_body parameter. See the{" "}
Python SDK documentation
{" "}
for details.
}
/>
## Tenant-scoped workflows
Tenants **do not** have a relationship to the [users](/concepts/users) and [objects](/concepts/objects) you've identified in Knock — Knock does not know which tenant to associate with a given set of users. Instead, you must explicitly pass a tenant when triggering a workflow.
Tenants have a loose coupling to your users so Knock does not need to know anything about the roles and permissions model associated with your product. This means you have less data to synchronize to Knock and reduces the risk of drift between what's current in your system and what's reflected in Knock. If you need to model groups or lists of users, you can use our [subscriptions model](/concepts/subscriptions) to do that.
Once a workflow run has been triggered with a `tenant`, the Knock workflow engine will:
- Find the tenant or create an empty `tenant` object if one does not exist.
- Expose the tenant object to the workflow run scope as a `tenant` variable.
- Tag all messages produced in the workflow run with the tenant `id`.
- Apply any branding overrides to templates rendered.
- Apply any preference defaults to the recipient's preference set.
- Fetch any recipient-specific tenant preference sets.
Tagging messages by tenant makes it possible to query for tenant-specific messages in both the API and the dashboard, and to scope in-app feeds to a specific tenant.
## Tenant data in templates
The full tenant object, including any custom properties, is available in your templates under the `tenant` [namespace](/template-editor/variables#tenant).
```markdown title="Using tenant data in a notification template"
# Hello from {{ tenant.name }}
This is a message directly from {{ tenant.name }} going to {{ recipient.email }}.
```
You can also use the tenant in step conditions to only trigger steps for particular tenants.
## Per-tenant preferences
Per-tenant user preferences and tenant preference defaults are only
available on our{" "}
Enterprise plan
.
}
/>
You can manage different sets of preferences for each user-tenant pair. A user may have different preferences configured for "Acme Fish Co." than they do for "Bell's Bagels," two workspaces within the same product. You can also set per-tenant defaults, where an admin in a tenant can set the default preferences for all users within that tenant. You can learn more in [our per-tenant preferences documentation](/multi-tenancy/per-tenant-preferences).
## Frequently asked questions
You can find tenant information on the **Tenants** page under the **Recipients** section in the main sidebar. From there you can view custom properties, message logs, workflow run history, branding settings, and default preferences for any tenant.
There are no limits associated with tenants.
Yes, you can still use our APIs to work with tenant data, and trigger workflow runs for specific tenants. However, per-tenant preferences and custom branding are features gated for enterprise plans only.
Knock does not know anything about the mapping between your users and your tenant entities, meaning you do not need to map user permissions.
Absolutely, you can use a tenant as a `recipient` or `actor` in a workflow trigger by referencing it as an object with the structure `{ collection: "$tenants", id: "tenant-id" }`.
Yes, you can subscribe recipients to a tenant by setting the collection of the object to subscribe to as `$tenants` and using the `id` of the tenant as the object id.
Per-tenant template overrides at the workflow step level are not yet supported. As an alternative, [per-tenant translations](/multi-tenancy/per-tenant-translations) enables you to customize template content on a per-tenant basis, even if you're not working with multiple locales.
If this is blocking your adoption of Knock, [please get in touch](mailto:support@knock.app?subject=Per-tenant%20templates).
While it's technically possible to create per-tenant workflows in Knock, we recommend not doing this where possible and opting to use our step conditions, preferences, and per-tenant templates to provide the customizations you need. The reason is creating and managing per-tenant workflows increases the surface area of the number of notifications you need to support, and more commonly what we've found from working with customers is there are more similarities between per-customer workflows than differences, which can usually be encapsulated in our workflow model.
If you find that you have different needs here, we'd love to speak with you. Please [get in touch](mailto:support@knock.app) and we can arrange a consultation with a notification support specialist on the Knock team to walk through your use case.
No, today it's only possible to have a single-level of hierarchy for your tenants. If you need to apply deeper hierarchy to your tenant objects, please [get in touch](mailto:support@knock.app) and we can discuss your use case further.
## Tenant scoping
Learn how to use tenants to scope in-app feeds so users only see notifications relevant to their active workspace.
---
title: Tenant scoping for in-app messaging
description: Learn how to use tenants to scope in-app feeds so users only see notifications relevant to their active workspace.
tags:
["tenant", "tenancy", "in-app feed", "multi-tenancy", "scoping", "workspace"]
section: Multi-tenancy
---
When your users belong to multiple workspaces or organizations, you'll want their [in-app feed](/in-app-ui/feeds/overview) to only show notifications relevant to their currently active workspace. You can do this by associating workflow runs with a tenant and passing that tenant when initializing the feed.
## How it works
Pass a `tenant` identifier in your workflow trigger call. The tenant does not need to be configured beforehand — any unique string you use to identify the workspace will work.
When retrieving the feed, pass the same tenant identifier so Knock scopes the feed to only show messages associated with that tenant:
```jsx title="Scope the feed client to a tenant"
// If you're using our `client-js` SDK:
import Knock from "@knocklabs/client";
const knockClient = new Knock(process.env.KNOCK_PUBLIC_API_KEY);
const feedClient = knockClient.feeds.initialize(
process.env.KNOCK_FEED_CHANNEL_ID,
{
// Scope all requests to the current workspace
tenant: currentWorkspace.id,
},
);
// Or if you're using the React SDK:
...
;
```
Knock will ensure that badge counts are scoped to the active workspace, and that real-time notifications are not received for messages belonging to other tenants.
## Example
Imagine a SaaS application, Collaborato, where users belong to one or more workspaces. When a user is active in the "Acme Fish Co." workspace, they should only see notifications relevant to that workspace.
By passing `tenant: "acme-fish-co"` in both the workflow trigger and the feed initialization, Knock will filter all feed requests and real-time events to that tenant — even if the same user has notifications from other workspaces.
## Per-tenant branding
Learn how to use tenants to apply custom branding to email notifications on a per-tenant basis.
---
title: Per-tenant branding
description: Learn how to use tenants to apply custom branding to email notifications on a per-tenant basis.
tags:
[
"tenant",
"tenancy",
"branding",
"email",
"multi-tenancy",
"white-label",
"custom brand",
]
section: Multi-tenancy
---
Per-tenant branding enables you to override your account-level email branding settings for individual tenants. When you trigger a workflow with a `tenant`, Knock uses any branding settings defined on that tenant in place of your account defaults.
Per-tenant branding is only available on our{" "}
Enterprise plan
.
}
/>
## Branding settings
Branding settings are stored on the tenant's `settings` object. You can set them via the [tenant API](/api-reference/tenants) or directly in the dashboard.
| Property | Description |
| --------------------------------- | -------------------------------------------------------------------- |
| `branding.primary_color` | A hex value for the primary color |
| `branding.primary_color_contrast` | A hex value for the contrasting color to use with the primary color |
| `branding.logo_url` | A fully qualified URL for an image to use as the logo of this tenant |
| `branding.icon_url` | A fully qualified URL for an image to use as the icon of this tenant |
## Setting branding via the API
Pass branding settings in the `settings` object when creating or updating a tenant:
## Setting branding in the dashboard
Navigate to the **Tenants** page under **Recipients** in the dashboard sidebar. Click into a tenant, then select the **Branding** tab to upload a logo, icon, and set primary colors directly from the interface.
## Using per-tenant branding
Once branding settings are configured on a tenant, pass the tenant `id` when triggering a workflow with an email step. Knock will automatically apply the tenant's branding to the email layout for that workflow run.
If no branding settings are defined on the tenant, Knock falls back to your account-level branding defaults.
## Example
Let's say you're a hospitality company with two boutique hotels — "The Black Lodge" and "The Great Northern" — each with its own brand identity for reservation update emails.
Create each hotel as a tenant and configure their branding in the dashboard or via the API. When triggering a reservation reminder, pass the relevant tenant `id` (e.g. `black-lodge`) and Knock will style the email with that tenant's logo and colors instead of your account defaults.
## Per-tenant translations
Learn how to create tenant-scoped translation files that override your base translations for specific tenants.
---
title: Per-tenant translations
description: Learn how to create tenant-scoped translation files that override your base translations for specific tenants.
tags:
[
"tenant",
"translations",
"i18n",
"localization",
"l10n",
"multi-tenancy",
"per-tenant",
]
section: Multi-tenancy
---
Per-tenant translations are only available on our{" "}
Enterprise plan
.
}
/>
Per-tenant translations enable you to override specific translation keys for individual tenants. When Knock renders a notification for a workflow run associated with a tenant, the tenant's translation content are deep-merged on top of your base translation files. The tenant-specific translations take precedence while everything else falls back to your base translations.
## How it works
When a notification is rendered, Knock will [translate](/template-editor/translations) the content if a `t` tag or `t` filter is found, following the [locale prioritization chain](/template-editor/translations#locale-prioritization) to identify the appropriate translation file to use. When a notification is scoped to a tenant, that flow prioritizes tenant-specific translations over base translations. Keys not present in the tenant-scoped file fall back to the base translation.
Given a tenant-scoped translation for `acme-corp`:
```json title="Tenant-scoped en translation for acme-corp"
{
"greeting": "Greetings from Acme Corp!"
}
```
And a base `en` translation:
```json title="Base en translation"
{
"greeting": "Hello from Knock",
"order_ready": "Your order is ready."
}
```
When a notification is sent for a workflow run associated with the `acme-corp` tenant, the resolved translations are:
```json title="Resolved translations for acme-corp"
{
"greeting": "Greetings from Acme Corp!",
"order_ready": "Your order is ready."
}
```
The `greeting` key is overridden by the tenant-scoped file; `order_ready` falls back to the base translation.
## Tenant-scoped translations
Tenant-scoped translations are managed via the [Management API](/developer-tools/management-api) using the existing translations endpoints. Add the `tenant` query parameter to scope a translation to a specific tenant.
### Create translations
```http title="Create a tenant-scoped translation"
PUT /v1/translations/:locale_code?tenant=
```
The request body is the same as a standard [translation upsert](/mapi-reference/translations/upsert):
```json title="Request body"
{
"translation": {
"content": "{\"greeting\": \"Greetings from Acme Corp!\"}",
"format": "json"
}
}
```
### Get translations
#### List all translations for a tenant
Use the `tenant` query parameter to filter the translations list to a specific tenant:
```http title="List translations for a tenant"
GET /v1/translations?tenant=
```
#### Get a specific translation for a tenant
Use the `tenant` query parameter and the `locale_code` path parameter to get a specific translation set:
```http title="Get a tenant-scoped translation"
GET /v1/translations/:locale_code?tenant=
```
## Translations in templates
In your templates, use the `t` filters or `t` tags to indicate content blocks that should be translated to tenant-specific copy. Knock will resolve the appropriate translation based on the tenant provided in the workflow trigger and, if applicable, the recipient's locale.
```liquid title="Using the t filter"
{{ "greeting" | t | default: "Hello" }}
```
```liquid title="Using the t tag"
{% t %}Hello from Knock{% endt %}
```
When these templates are rendered for a workflow run associated with the `acme-corp` tenant, Knock uses the tenant-scoped value if one exists for the recipient's locale.
```markdown title="Resulting copy for acme-corp"
Greetings from Acme Corp!
```
See [translations](/template-editor/translations) for more information on using translations in templates.
## Frequently asked questions
Yes. By default, the Management API enforces environment restrictions on
translation upserts. To write directly to production, pass `force=true` as a
query parameter. This bypasses the development-only environment check and
origin environment checks, allowing you to upsert tenant-scoped translations
directly to any environment.
Yes. You can manage tenant-scoped translations from the **Translations**
page in the Knock dashboard. Filter the translations list by tenant using
the tenant filter, click into a translation to view its tenant scope, and
edit and save changes directly from the detail view.
Yes, per-tenant translations can be used to customize templates on a
per-tenant basis, even if you're not working with multiple locales. Set all
of your customizable content as translation keys in your templates, then
upsert tenant-scoped translation files that override those keys for each
tenant. This gives you per-tenant control over notification content without
requiring separate templates or workflows per tenant.
## Per-tenant preferences
Learn how to enable your customer admins to set default preferences for users in their tenant.
---
title: Per-tenant preferences
description: Learn how to enable your customer admins to set default preferences for users in their tenant.
tags:
[
"tenant",
"tenant preferences",
"per-tenant preferences",
"per tenant preferences",
"preferences",
]
section: Multi-tenancy
---
Per-tenant user preferences and tenant preference defaults are only
available on our{" "}
Enterprise plan
.
}
/>
You can use tenant preferences to enable your customers' admins to create a tenant-specific default `PreferenceSet` for users in their tenant.
If you're a B2B application or a multi-tenant SaaS product, you can use tenant preferences to allow your customers to set default preferences for their users. For example, in Slack, your notification preferences are set _per Slack workspace_ (that is, per-tenant), not as global preferences that apply across all of your Slack workspaces.
This documentation assumes you know about tenants in Knock and what they
do. If you're new to tenants, we recommend familiarizing yourself with the
concept of tenants before
continuing.
}
/>
## Overview
Here is how tenant preferences work and the steps you'll take to implement them:
1. Enable your tenant admins to create a default `PreferenceSet` for their tenant.
2. Enable your users to override that tenant default `PreferenceSet` with their own preferences.
3. Trigger your workflows with a `tenant` parameter to apply tenant-specific preferences.
## Create a per-tenant default `PreferenceSet`
You set the default `PreferenceSet` for a tenant via the API by calling the `tenants.set` [method](/api-reference/tenants/set). The preferences should follow the format of a recipient PreferenceSetRequest.
```javascript title="Set the default preferences for a tenant"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
const preferences = {
workflows: {
"new-comment": {
channel_types: {
email: false,
sms: true,
chat: false,
},
channels: {
"550e8400-e29b-41d4-a716-446655440000": true,
"6ba7b810-9dad-11d1-80b4-00c04fd430c8": false,
},
},
},
};
await knock.tenants.set("tenant-id", {
settings: {
preference_set: preferences,
},
});
```
### Updating the per-tenant default `PreferenceSet`
You can update the per-tenant default `PreferenceSet` by calling the `tenants.set` method with the same `tenant_id` and the updated preferences that you'd like to set.
The default behavior for this action is to merge the new preferences with any existing preferences. This means that any existing preferences will only have their values updated but not removed. See the [frequently asked questions](#frequently-asked-questions) section below for more information on how you can use a "replace" persistence strategy to overwrite existing preferences instead, or how you can remove a tenant's default preference set entirely.
## Set a per-tenant user `PreferenceSet`
A `PreferenceSet` has an `id`. When you [set a given user's preferences](/api-reference/users/set_preferences) in Knock, you'll use the `default` ID to apply the preferences universally for the user. When using one of our [SDKs](/developer-tools/sdks), the `default` preference set is used if you don't provide an `id`.
You'll encounter "default" in a few places in the Knock preferences model:
At the environment-level when you set your default{" "}
PreferenceSet for all users.
At the tenant-level when you set the default{" "}
PreferenceSet for all users in a tenant.
At the user-level when you set a user's PreferenceSet{" "}
without providing a tenant ID.
}
/>
To set per-tenant preferences for a recipient, you'll use the ID of the tenant that they should be associated with as the `PreferenceSet`'s ID.
The examples below use the server-side Node SDK with a secret API key. To manage a user's own per-tenant preferences from your frontend, use a public API key with a signed user token and pass the tenant ID as the `preferenceSet`. See [Custom preference center](/preferences/custom-preference-center) for details.
```javascript title="Set tenant preferences for a user"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await knock.users.setPreferences(
"user-id",
{
channel_types: {
email: true,
sms: false,
chat: true,
},
channels: {
"f47ac10b-58cc-4372-a567-0e02b2c3d479": false,
"123e4567-e89b-12d3-a456-426614174000": true,
},
},
{
preferenceSet: "tenant-id",
},
);
```
You can also get a user's tenant-specific preferences.
```javascript title="Get tenant preferences for a user"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
const preferences = await knock.users.getPreferences("user-id", {
preferenceSet: "tenant-id",
});
```
## Trigger per-tenant workflows
When you trigger a workflow run, you pass a `tenant` parameter to tell Knock which tenant in your application the workflow is executing for.
```javascript title="Trigger a workflow with a tenant"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await knock.workflows.trigger("workflow-name", {
tenant: "spotify",
});
```
The Knock workflow engine uses that `tenant` parameter to evaluate the user's `PreferenceSet`. If the user has a tenant-specific preference set, Knock uses that to determine whether to send the notification. If the user does not have a `tenant`-specific preference set, Knock uses the tenant's default preference set.
## Tenant preference evaluation rules
Here are a few things to keep in mind when using tenant preferences. You can learn more about how preferences are merged and evaluated [here](/preferences/overview#tenant-specific-preference-merge-hierarchy).
- When executing a workflow trigger, passing in a `tenant` will automatically load that tenant's default `PreferenceSet` (if one exists) for all recipients of the workflow. These tenant-level defaults will override a recipient's own `default` preferences.
- If the recipient has any per-tenant preferences set for that `tenant.id`, they will take precedence over the tenant-level default preferences. For more information on how to override a recipient's per-tenant preferences to respect the tenant-level default preferences, see the [frequently asked questions](#frequently-asked-questions) below.
- If there is no default `PreferenceSet` on the tenant AND the recipient has no per-tenant preferences set, the recipient's `default` preferences will be used. As always, the recipient's `default` preferences are [merged](/preferences/overview#tenant-specific-preference-merge-hierarchy) with the environment-level preference defaults.
## Frequently asked questions
Yes. You can do this by setting the `__persistence_strategy__` key on your `PreferenceSet` to `"replace"` when calling the `tenants.set` method. This will overwrite any existing preferences with the new preferences provided.
```javascript title="Replacing a per-tenant default preference set using the Node SDK"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
const preferences = {
__persistence_strategy__: "replace",
workflows: {
"new-comment": {
channel_types: {
email: false,
sms: true,
chat: false,
},
channels: {
"550e8400-e29b-41d4-a716-446655440000": true,
"6ba7b810-9dad-11d1-80b4-00c04fd430c8": false,
},
},
},
};
await knock.tenants.set("tenant-id", {
settings: {
preference_set: preferences,
},
});
```
To remove a tenant's default `PreferenceSet` entirely, call the `tenants.set` method with `settings.preference_set` set to `null`. This clears the tenant's default preferences.
```javascript title="Remove a tenant's default preference set using the Node SDK"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await knock.tenants.set("tenant-id", {
settings: {
preference_set: null,
},
});
```
By default, a recipient's individual preferences will always take the highest precedence in the merge when preferences are evaluated (according to the hierarchy outlined [here](/preferences/overview#merging-preferences)).
Some applications have use cases where it's necessary for a preference that is set at the tenant level to override a user's individual preference. For example, you may want to allow a team admin to disable a certain type of notification for their entire team, regardless of whether an individual user has opted in to that notification. To achieve this, you can set the `__strategy__` key on the preference you'd like to override to a value of `"replace"`.
In the following example, although the user has specifically opted into receiving email notifications for the `collaboration` category, email notifications with that category will not send because the `tenant`'s default preference set has set the `collaboration` category to `false`. Consider the following preference sets:
```json title="A user's tenant-specific preference set"
{
"categories": {
"collaboration": {
"channel_types": {
"email": true
}
},
"project-updates": {
"channel_types": {
"email": true
}
}
}
}
```
```json title="The tenant's default preference set"
{
"categories": {
"collaboration": {
"__strategy__": "replace",
"channel_types": {
"email": false
}
},
"project-updates": {
"channel_types": {
"email": false
}
}
}
}
```
The merge during preference evaluation will look like this:
{/* Note: The original image can be found in Figma here: https://www.figma.com/board/LlFCmkX4jgGDRcfJuTqkhl/Preferences-diagrams */}
The recipient's preference for the `project-updates` category is preserved in the merge, but their preference for `collaboration` notifications is overridden by the tenant's preference due to the `replace` strategy.
This `replace` strategy will also be reflected when you request the user's preferences via API. Although the user's tenant-specific preferences have explicitly been set to the above, the `__strategy__` key will be present on the `PreferenceSet` returned, indicating that their preference has been overridden by the tenant's:
```json title="The returned user preference set"
{
"categories": {
"collaboration": {
"__strategy__": "replace",
"channel_types": {
"email": false
}
},
"project-updates": {
"channel_types": {
"email": true
}
}
}
}
```
You can also use the `replace` strategy to override top-level `channel_types` or `channels` preferences:
```json title="Tenant default preference set with top-level channel_types override"
{
"channel_types": {
"__strategy__": "replace",
"email": false,
"sms": true
}
}
```
Here are some important things to keep in mind when using the `replace` strategy:
- This strategy will only apply to the specific preference(s) where it's included; there's no way to override the entire `PreferenceSet`.
- When the preference with the `replace` strategy is removed, any existing recipient preferences that were overridden by the `replace` strategy will be immediately restored to their original values. For the example above, the user will once again be opted in to `collaboration` notifications.
#### Removing the `replace` strategy
Setting preferences on a tenant has [the default behavior](#updating-the-per-tenant-default-preferenceset) of merging the new preferences with any existing preferences. This means that once a preference has been set with the `replace` strategy, simply omitting the `__strategy__` from your next request will not remove it.
There are two ways to remove it from the preference set:
- Explicitly set the `__strategy__` key to `"merge"` for the preference(s) that should no longer override the user's preferences. This is the default behavior (a user's tenant-specific preferences will take precedence over the tenant's own default).
- Use the `__persistence_strategy__` key on your request to replace the entire preference set rather than merging your new preferences with the existing ones. See the FAQ above for more information.
A `commercial_subscribed` value on a recipient's `default` preference set always takes precedence over tenant and environment defaults. However, in a multi-tenant application you may want to give tenant admins a switch that turns off [commercial messages](/preferences/commercial-unsubscribe) for everyone in their tenant, even for users who are individually opted in.
You can model this by storing a user's opt-in as a [condition](/preferences/preference-conditions) on their `commercial_subscribed` preference that references the tenant's setting at send time.
First, set the tenant's `commercial_subscribed` preference with a boolean value according to the admin's setting:
```javascript title="Opt a tenant out of receiving commercial messages using the Node SDK"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await knock.tenants.set("tenant-id", {
settings: {
preference_set: {
commercial_subscribed: false,
},
},
});
```
Then, a recipient's `commercial_subscribed` opt-in can be stored as a condition that dynamically references a tenant's setting, rather than as an explicit `true` setting:
```json title="A recipient preference set that defers to the tenant"
{
"id": "default",
"commercial_subscribed": {
"conditions": [
{
"variable": "tenant.settings.preferences.commercial_subscribed",
"operator": "not_equal_to",
"argument": "false"
}
]
}
}
```
When a commercial workflow runs for this recipient, Knock evaluates the condition at send time. If a `tenant` is applied to the workflow trigger and its `commercial_subscribed` preference is set to `false`, the user will not receive the message. If there is no `tenant` applied, or the tenant's `commercial_subscribed` preference is set to anything other than `false`, the user will receive the message.
To comply with CAN-SPAM regulations, you should never use preference conditions to opt a recipient in to commercial messages under a given tenant when they have explicitly opted out under their own settings. Always set a false value on a user's preferences when they opt out of commercial messages.
}
/>
# Preferences
Learn how to power notification preferences with Knock.
## Overview
Learn how to implement notification preferences in Knock.
---
title: "Preferences overview"
description: "Learn how to implement notification preferences in Knock."
tags: ["recipients", "conditions", "prefs", "preferences"]
section: Preferences
---
[Preferences](/api-reference/recipients/preferences) enable your users to opt-out of the notifications you send using Knock.
## How preferences work
A user has a `PreferenceSet`. A `PreferenceSet` is a JSON object that tells Knock which channels, categories, and/or workflows a user has opted out of receiving.
When Knock runs a workflow for a user, we evaluate their `PreferenceSet`. A message will not send if the user has opted out of receiving it.
A preference set is built using four keys: `categories`, `channels`, `channel_types`, `workflows`. These keys resolve to boolean values to determine if a user has opted out of receiving a notification.
A recipient's `default` preference set also has a `commercial_subscribed` key which determines if the recipient should receive notifications sent by commercial workflows or broadcasts. Read more about commercial unsubscribe [here](/preferences/commercial-unsubscribe).
A few examples:
```json title="Unsubscribe user from admin category notifications"
{
"categories": { "admin": false }
}
```
```json title="Unsubscribe user from email notifications"
{
"channel_types": { "email": false }
}
```
```json title="Unsubscribe user from a specific email channel"
{
"channels": { "550e8400-e29b-41d4-a716-446655440000": false }
}
```
```json title="Unsubscribe user from at-mention notifications"
{
"workflows": { "mention": false }
}
```
## Channels vs. channel types
Channel preferences provide more granular control than channel types by allowing you to specify preferences for individual channels rather than entire channel types.
- **Channel type preferences** (`channel_types`) control broad categories like `email`, `sms`, or `push`
- **Channel preferences** (`channels`) control specific channel instances using their UUID identifiers
Channel preferences always take precedence over channel type preferences because they are more specific. See [preference evaluation rules](#preference-evaluation-rules) below for more information.
You can combine these keys to create preference grids like the one in the image below:
```json title="A preference grid for categories and channels"
{
"categories": {
"collaboration": {
"channel_types": {
"email": true,
"in_app_feed": true
},
"channels": {
"550e8400-e29b-41d4-a716-446655440000": false,
"6ba7b810-9dad-11d1-80b4-00c04fd430c8": true
}
},
"project-updates": {
"channel_types": {
"email": false,
"in_app_feed": true
}
}
},
"workflows": {
"invoice-issued": {
"channel_types": {
"email": true
},
"channels": {
"6ba7b810-9dad-11d1-80b4-00c04fd430c8": true,
"f47ac10b-58cc-4372-a567-0e02b2c3d479": false
}
}
}
}
```
The `PreferenceSet` above models this preference grid in your application:
Check out{" "}
our interactive example app
{" "}
to see how making changes to the preference center UI updates the values
of a
PreferenceSet
}
/>
## Environment-level default preferences
You can set an environment-level default `PreferenceSet` in the Knock dashboard that applies to all recipients in an environment. When Knock evaluates preferences for a recipient who has not set any preferences of their own, the environment default serves as the baseline. This is useful when you want to establish a baseline that differs from Knock's default of opting all recipients in to all notifications.
The environment-level default is always the lowest priority in the [merge hierarchy](#merging-preferences). Any preferences set at the recipient or tenant level will take precedence over it.
To set up an environment-level default preference set, see [Create a default preference set](/preferences/custom-preference-center#create-environment-level-default-preferences).
## Merging preferences
When a default `PreferenceSet` exists for an environment or tenant, Knock will merge all applicable preferences for a recipient when evaluating whether or not to send a notification. Any preferences set at the recipient level will take precedence in the merge, according to the hierarchy outlined below.
### Merge hierarchy
The following hierarchies are used when merging preferences.
{/* Note: The original diagrams for the merge hierarchy images can be found in Figma here: https://www.figma.com/board/LlFCmkX4jgGDRcfJuTqkhl/Preferences-diagrams */}
The following standard hierarchy is used to merge preferences when no `tenant` is applied to the workflow trigger. Each item in the list takes precedence over the ones that follow it:
1. A [recipient's default preference](/preferences/overview#how-preferences-work) set
2. The [environment-level default preference](/preferences/custom-preference-center#create-environment-level-default-preferences) set
Let's take a look at an example to visualize this merge. Suppose that you have the following preference sets:
To visualize the resulting merged preferences, we'll start at the bottom of the hierarchy and work our way up, adding any preferences from the environment default preference set that are not already present in the recipient's `default` preference set. Any preferences that are set in both places will keep the value from the recipient's `default` preference set:
The resulting merged preferences will look like this:
The environment-level setting to opt all users into `collaboration` notifications will be respected because the recipient doesn't have an explicit preference for that category, but the recipient's preference to specifically opt in to SMS messages will override the environment-level setting to opt out.
The following hierarchy is used to merge preferences when a `tenant` is applied to the workflow trigger. Each item in the list takes precedence over the ones that follow it:
1. A recipient's [tenant-specific preference](/multi-tenancy/per-tenant-preferences) set
2. The [tenant's default preference](/multi-tenancy/per-tenant-preferences#create-a-per-tenant-default-preferenceset) set
3. The [environment-level default preference](/preferences/custom-preference-center#create-environment-level-default-preferences) set
This merge works in the same way as the standard merge above, but it evaluates different preference sets. Let's take a look at an example to visualize this merge. Suppose that you have the following preference sets:
To visualize the resulting merged preferences, we'll start at the bottom of the hierarchy and move upward—first adding preferences from the environment default to the tenant's default preference set, then adding any of those preferences that are not already present in the recipient's tenant-specific preference set. At each step, if a preference exists in both sets, the value from the higher level in the hierarchy takes precedence:
The resulting merged preferences will look like this:
The environment-level settings to opt all users out of SMS messages and into `collaboration` notifications will be respected because neither the tenant nor the recipient have an explicit preference for these items. The tenant's preference to opt users in to `reminders` notifications will be overridden by the recipient's setting to opt out.
If a tenant is applied to the workflow trigger but there are no
tenant-specific preferences set on the tenant or the recipient, the
recipient's default preference set will be evaluated according to
the standard merge hierarchy, as if no tenant were applied.
} />
The `commercial_subscribed` preference is an exception to both hierarchies above. When it's set on a recipient's `default` preference set, it always takes precedence over tenant and environment defaults. This keeps a user's commercial opt-out with them across every tenant they belong to.
For more information on how you can override these hierarchies, see the [frequently asked questions](#frequently-asked-questions) section below.
## Preference evaluation rules
When a workflow is triggered, Knock will evaluate the preferences for each `recipient` of the workflow and send notifications for each channel step in the workflow based on that evaluation. There are some important rules and caveats to consider:
- If you do not set a preference for a given channel, workflow, or workflow category, Knock defaults them to `true`.
- When a recipient clicks an unsubscribe link, their `default` preference set will be updated, marking `commercial_subscribed` as `false`. They will be opted-out of commercial messages, and they will continue to receive transactional messages based on their other preferences. Read more about commercial unsubscribe [here](/preferences/commercial-unsubscribe).
Knock only sends a notification if all preference combinations that exist on the recipient evaluate to `true`.
- A workflow can belong to multiple `categories`. Only one of those category preferences needs to evaluate to `false` for the notification not to send.
- If a workflow's `category` is set to `false`, the notification will not send even if a `channel_type` or `channel` on the workflow is explicitly set to `true`.
- Channel preferences take precedence over channel type preferences. If a specific `channel` is set to `true` but the `channel_type` is set to `false`, the notification will still send through that specific channel.
- If both `channel` and `channel_type` preferences exist for the same notification, the `channel` preference is evaluated first and takes priority.
Our [Preferences API](/api-reference/recipients/preferences) provides endpoints for retrieving all of the preferences that have been set on a recipient.
You can also use the [workflow debugger](/send-notifications/debugging-workflows) in your dashboard to view the preferences that were evaluated for the recipient on a given workflow run.
## Going live with preferences
Once you've configured your preference model, you need a way for users to manage their preferences. Knock offers two approaches:
- **Hosted preference center.** Knock hosts and renders a preference page for each user, accessible via a signed URL. You configure rows, labels, and branding in the dashboard - no code required. Supports the user's `default` preference set only. See [hosted preference center](/preferences/hosted-preference-center) for more information.
- **Custom preference center.** You build the UI and embed it in your product, using Knock's preferences API to read and write preference values. This gives you full control over layout, UX, and which preferences you surface—including [per-tenant](/multi-tenancy/per-tenant-preferences) and [object](/preferences/object-preferences) preferences. You can optionally use the dashboard-managed configuration to drive your row definitions without hardcoding them. See [custom preference center](/preferences/custom-preference-center) for more information.
## Bulk set user preferences
You can update the preferences of up to 1000 users in a single batch by using the `users.bulkSetPreferences` method. This executes an asynchronous job which will overwrite any existing preferences for the users provided. You can track the progress of the `BulkOperation` returned via the [bulk operation API](/api-reference/overview/bulk-endpoints).
## Advanced concepts
- [Per-tenant preferences](/multi-tenancy/per-tenant-preferences). In multi-tenant B2B applications, an advanced use case is customer admins who want to set the tenant-level default `PreferenceSet` for new users within their tenant.
- [Object preferences](/preferences/object-preferences). You can set preferences for object recipients, just as you can for users.
- [Preference conditions](/preferences/preference-conditions). You can build advanced conditions and store them on Knock’s preference model to power use cases such as per-resource muting (example: mute notifications about this task) or threshold alerts (example: only notify me if my account balance is below $5).
- Merge strategy. It's possible to configure the merge strategy on specific preferences within a `PreferenceSet`. This allows you to override the default merge hierarchy when preferences are evaluated. See the [frequently asked questions](#frequently-asked-questions) section below for more details and use cases.
- Workflow overrides. If you need to override a recipient's notification preferences to send notifications like a password reset email, you can override the preferences model. To do this, go to your workflow, click "Manage workflow," and enable "Override recipient preferences." You will need to commit this change for it to take effect. When enabled, the workflow will send to all of its channels, regardless of the recipient's preferences.
- [Commercial unsubscribe](/preferences/commercial-unsubscribe). You can configure 1-click unsubscribe links to help users opt-out of commercial or promotional notifications and comply with CAN-SPAM requirements.
## Frequently asked questions
Yes. While our preferences API endpoints will default to overwriting the existing `PreferenceSet` with the new preferences provided, it's possible to update a single preference using either of the two options below.
<>
**1. Setting a `__persistence_strategy__` key on your `PreferenceSet` to `"merge"`**
You can provide an optional `__persistence_strategy__` key when providing your `PreferenceSet` to our preferences API endpoints. Setting this key to `"merge"` will perform a deep merge of the provided preferences into any existing preferences.
Here's what this looks like in practice. If a user has these existing `default` preferences:
```json title="An existing default preference set"
{
"categories": {
"collaboration": {
"channel_types": {
"email": true,
"in_app_feed": true
}
}
}
}
```
and they would like to update their email preference for the `collaboration` category to `false`, you can do so by providing the following `PreferenceSet` to our [user preferences endpoint](/api-reference/users/set_preferences):
```javascript title="Updating a single preference using the Node SDK"
import Knock from '@knocklabs/node';
const client = new Knock({
apiKey: 'My API Key',
});
const preferenceSet = await client.users.setPreferences('user_id', 'default', {
__persistence_strategy__: 'merge',
categories: {
collaboration: {
channel_types: {
email: false
}
}
}
});
```
This will result in the following `PreferenceSet` being set on the recipient:
```json title="The resulting default preference set"
{
"categories": {
"collaboration": {
"channel_types": {
"email": false,
"in_app_feed": true
}
}
}
}
```
<>
**2. Inline identifying preferences**
You can update a single preference inline by using any of our [recipient identification
methods](/managing-recipients/identifying-recipients), including while triggering a workflow (as seen in the example below).
This will perform a deep merge of the provided preferences into any
existing preferences, just like any other [properties stored on the
recipient](/concepts/users#storing-user-properties).
Note that the syntax for providing the `id` of the preference set on an [`InlinePreferenceSetRequest`](/api-reference/recipients/preferences/schemas/inline_preference_set_request)
is slightly different than the way that our preferences endpoints handles them; you'll simply provide a key-value pair where the key is the `id` of the preference set and the value is the `PreferenceSet` you'd like to merge.
Here's what this looks like in practice. If a user has these existing `default` preferences:
```json title="An existing default preference set"
{
"categories": {
"collaboration": {
"channel_types": {
"email": true,
"in_app_feed": true
}
}
}
}
```
and they would like to update their email preference for the `collaboration` category to `false`, you can do so by providing the following `InlinePreferenceSetRequest` while triggering a workflow:
```javascript title="Triggering a workflow with inline preferences using the Node SDK"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await knock.workflows.trigger("new-comment", {
data: { project_name: "My Project" },
recipients: [
{
id: "1",
preferences: {
default: {
categories: {
collaboration: {
channel_types: {
email: false
}
}
}
}
}
},
],
});
```
This will result in the following `PreferenceSet` being set on the recipient prior to the workflow being triggered:
```json title="The resulting default preference set"
{
"categories": {
"collaboration": {
"channel_types": {
"email": false,
"in_app_feed": true
}
}
}
}
```
By default, a recipient's individual preferences will always take the highest precedence in the merge when preferences are evaluated (according to the hierarchy outlined under [Merging preferences](#merging-preferences) above).
Some applications have use cases where it's necessary for a [preference that is set at the tenant level](/multi-tenancy/per-tenant-preferences#set-a-per-tenant-user-preferenceset) to override a user's individual preference. For example, you may want to allow a team admin to disable a certain type of notification for their entire team, regardless of whether an individual user has opted in to that notification. To achieve this, you can set the `__strategy__` key on the preference you'd like to override to a value of `"replace"`.
In the following example, although the user has specifically opted into receiving email notifications for the `collaboration` category, email notifications with that category will not send because the `tenant`'s default preference set has set the `collaboration` category to `false`. Consider the following preference sets:
```json title="A user's tenant-specific preference set"
{
"categories": {
"collaboration": {
"channel_types": {
"email": true
}
},
"project-updates": {
"channel_types": {
"email": true
}
}
}
}
```
```json title="The tenant's default preference set"
{
"categories": {
"collaboration": {
"__strategy__": "replace",
"channel_types": {
"email": false
}
},
"project-updates": {
"channel_types": {
"email": false
}
}
}
}
```
The merge during preference evaluation will look like this:
{/* Note: The original diagram for this image can be found in Figma here: https://www.figma.com/board/LlFCmkX4jgGDRcfJuTqkhl/Preferences-diagrams */}
The recipient's preference for the `project-updates` category is preserved in the merge, but their preference for `collaboration` notifications is overridden by the tenant's preference due to the `replace` strategy.
This `replace` strategy will also be reflected when you request the user's preferences via API. Although the user's tenant-specific preferences have explicitly been set to the above, the `__strategy__` key will be present on the `PreferenceSet` returned, indicating that their preference has been overridden by the tenant's:
```json title="The returned user preference set"
{
"categories": {
"collaboration": {
"__strategy__": "replace",
"channel_types": {
"email": false
}
},
"project-updates": {
"channel_types": {
"email": true
}
}
}
}
```
You can also use the `replace` strategy to override top-level `channel_types` or `channels` preferences:
```json title="Tenant default preference set with top-level channel_types override"
{
"channel_types": {
"__strategy__": "replace",
"email": false,
"sms": true
}
}
```
Here are some important thing to keep in mind when using the `replace` strategy:
- This strategy will only apply to the specific preference(s) where it's included; there's no way to override the entire `PreferenceSet` at the top level.
- When the preference with the `replace` strategy is removed, any existing preferences that were overridden by the `replace` strategy will be immediately restored to their original values. For the example above, the user will once again be opted in to `collaboration` notifications.
#### Removing the `replace` strategy
Setting preferences on a tenant has [the default behavior](/multi-tenancy/per-tenant-preferences/#updating-the-per-tenant-default-preferenceset) of merging the new preferences with any existing preferences. This means that once a preference has been set with the `replace` strategy, simply omitting the `__strategy__` from your next request will not remove it.
There are two ways to remove it from the preference set:
- Explicitly set the `__strategy__` key to `"merge"` for the preference(s) that should no longer override the user's preferences. This is the default behavior (a user's tenant-specific preferences will take precedence over the tenant's own default).
- Use the `__persistence_strategy__` key on your request to replace the entire preference set rather than merging your new preferences with the existing ones. See the FAQ [here](/multi-tenancy/per-tenant-preferences#frequently-asked-questions) for more information.
In the workflow debugger, Knock will show you the preferences that were evaluated for the recipient on a given workflow run. You may notice `channel_types` preferences, even if you didn't explicitly set them on the recipient or in your environment default preference set.
This is because Knock automatically opts all recipients in to all `channel_types` by default, to ensure that the recipient receives notifications unless they have been explicitly opted out.
If you want to override this behavior, you can set the `channel_types` preference to `false` for all channel types in your environment default preference set. This will opt the recipient out from all notifications.
Channel preferences and channel type preferences work together to provide different levels of granularity:
- **Channel type preferences** (`channel_types`) control broad categories like `email`, `sms`, or `push`
- **Channel preferences** (`channels`) control specific channel instances using their UUID identifiers
Channel preferences always take precedence over channel type preferences. This allows users to:
- Opt out of all email notifications but still receive critical transactional emails from a specific channel
- Opt into SMS notifications generally but exclude marketing messages from a particular provider
- Have fine-grained control over their notification experience
For example, if a user has:
```json
{
"channel_types": { "email": false },
"channels": { "550e8400-e29b-41d4-a716-446655440000": true }
}
```
They will not receive email notifications in general, but will still receive notifications sent through the specific channel with ID `550e8400-e29b-41d4-a716-446655440000`.
## Hosted preference center
Learn how to use Knock's hosted preference center to enable your users to manage notification preferences without writing any code.
---
title: "Hosted preference center"
description: "Learn how to use Knock's hosted preference center to enable your users to manage notification preferences without writing any code."
tags:
["preferences", "preference center", "hosted", "unsubscribe", "commercial"]
section: Preferences
---
Knock's hosted preference center is a page where your users manage their `default` notification preferences. Knock hosts and renders the page, so you can launch a preference center without building or hosting any UI yourself.
- **Knock hosts the page.** Users access their preferences through a signed URL.
- **Configure in the dashboard.** Set rows, labels, and branding under **Platform** > **Preferences** > **Preference center**.
- **No code required.** Enable the preference center and [link to it from your notifications](#linking-to-the-preference-center).
- **User default preferences only.** The hosted preference center does not support [per-tenant](/multi-tenancy/per-tenant-preferences) or [object](/preferences/object-preferences) preferences.
The hosted preference center enables you to give users a way to manage their notification preferences without building or hosting the UI yourself. If you need more control over the experience, see the [custom preference center](/preferences/custom-preference-center). Not sure which approach fits? See [Going live with preferences](/preferences/overview#going-live-with-preferences).
The hosted preference center currently supports user recipients only. It
doesn't support managing preferences for{" "}
objects or{" "}
tenants.
}
/>
## How it works
Knock hosts the preference center at `p.knock.app` by default. Each user accesses their own preferences through a signed link that looks like this:
```
https://p.knock.app/p/
```
You can also serve the preference center from your own subdomain. See [Custom domain for the preference center](#custom-domain-for-the-preference-center) below.
The token identifies the recipient, so users don't need to log in to your product to view or update their preferences.
When a user opens the link, they see their preference settings based on the configuration in your dashboard, with your account branding, preference options, and the ability to opt out of commercial messaging.
When the user clicks **Save preferences**, Knock writes their changes back to their `default` preference set. The link never expires.
If a preference row, or a channel type within a row, currently has{" "}
conditional preferences
for a given user, the preference center renders that key but the user
can't modify their preference for it.
}
/>
## Configure your preference center
You configure the preference center from the Knock dashboard under **Platform** > **Preferences** > **Preference center**. Your configuration is environment-specific.
When the preference center is saved and enabled, changes go live in the environment right away. When the preference center is disabled, users can only edit their [commercial messages opt-out](/preferences/commercial-unsubscribe) preference.
Toggle **Show account name** to display your account name alongside your logo at the top of the page.
Set the **title** and **body** copy that appear at the top of the page. Use these to tell your users what the page does, for example "Notification preferences" and "Manage your preferred notification channels and categories."
Each preference option is a row that your users can toggle. For each row, you configure:
- **Type.** Map the row to a [category](/preferences/overview#how-preferences-work), a [workflow](/concepts/workflows), or a [channel](/concepts/channels). For categories and workflows you can select an existing key or create a new one.
- **Display name and description.** The label your users see for this row, for example "Comments and replies," and an optional line of supporting text shown beneath it.
- **Channel types.** For category or workflow rows, limit the row to specific channel types, such as email, in-app, push, or SMS. When you select one or more channel types, the row renders a toggle per channel type so users can opt in or out of each one. This doesn't apply to channel rows, which already map to a single channel type.
The commercial messages row gives your users a single place to opt out of promotional or non-essential notifications. This is backed by the same `commercial_subscribed` preference used for commercial unsubscribe, so opting out here also satisfies one-click CAN-SPAM requirements for your commercial messaging.
The commercial messages row is mandatory and always renders in the preference center, whether the preference center is enabled or disabled. You can change the title and body copy for the row, but you can't remove it.
The preference center uses the branding configured for your account, including your logo, icon, and primary color. See [branding](/template-editor/branding) for more on how branding works in Knock.
Before you save, you can preview the preference center as a specific user. This renders that user's page exactly as they would see it with their current preferences and your latest configuration, so you can confirm the experience before it goes live. When a custom domain is assigned to the current environment, the preview uses that domain.
Toggle **Enabled** to turn the preference center on for the environment.
## How configuration maps to preferences
Each row in your preference center maps to a key in the recipient's `PreferenceSet`. A row can point at a `category`, a `workflow`, or a `channel`, and can scope to one or more channel types.
The hosted preference center doesn't support top-level{" "}
channel type{" "}
preferences. Channel types can only be configured as part of a category or
workflow row.
}
/>
When a user saves their preferences, Knock updates the corresponding keys on the recipient's `default` preference set. These changes are merged with any environment or tenant defaults during [preference evaluation](/preferences/overview#preference-evaluation-rules), with the recipient's preferences taking precedence according to the [merge hierarchy](/preferences/overview#merging-preferences).
## Linking to the preference center
### In workflow templates
To link a user directly to their preference center from a notification, include the URL in your message template or [email layout](/integrations/email/layouts) using the built-in variable:
```liquid title="Link to the hosted preference center in an email template"
Manage your preferences
```
Knock renders the user-specific link in the notification. Use `vars.manage_preferences_url` when you want to give users full control over their preferences via the hosted preference center. For single-click opt-out of commercial messages via the commercial unsubscribe feature, use `vars.commercial_unsubscribe_url` instead.
### In your application
If you need to link a user to their preference center from outside of a notification (for example, from your app settings page or an admin panel), you can generate a link to the hosted preference center.
Call [`POST /v1/users/{user_id}/preference_center/signed_url`](/api-reference/users/preference_center/generate_signed_url) from your backend with a **secret API key**. The response includes:
- **`url`.** The full hosted preference center URL for the user.
```bash title="Generate a preference center signed URL"
curl -X POST "https://api.knock.app/v1/users/user_id/preference_center/signed_url" \
-H "Authorization: Bearer $KNOCK_API_KEY" \
-H "Content-Type: application/json"
```
If your environment uses a [custom preference center domain](/preferences/hosted-preference-center#custom-domain-for-the-preference-center), the returned `url` reflects that domain.
See the [create preference center signed URL API reference](/api-reference/users/preference_center/generate_signed_url) for details.
## Copying configuration between environments
Your preference center configuration is environment-specific, just like your [preference defaults](/preferences/overview#environment-level-default-preferences). You can copy it from one environment to another using the "Copy to..." button in the upper right corner of the preference center settings. This enables you to keep your environments in sync as you move from development to production.
## Custom domain for the preference center
By default, the hosted preference center is served at `p.knock.app`. You can configure a custom domain to serve it from your own subdomain instead (i.e. `prefs.yourcompany.com`).
Once a custom domain is assigned to an environment, your templates will automatically resolve `{{vars.manage_preferences_url}}` variables with your custom domain.
For configuration steps, see [Setting up a custom domain](/manage-your-account/custom-domains#setting-up-a-custom-domain). Assignment changes take effect immediately.
## Learn more
To learn more about the preferences model behind the preference center, see the [preferences overview](/preferences/overview).
## Custom preference center
Learn how to build and embed a custom notification preference center in your application using Knock's preferences API.
---
title: "Custom preference center"
description: "Learn how to build and embed a custom notification preference center in your application using Knock's preferences API."
tags: ["preferences", "preference center", "custom", "in-app"]
section: Preferences
---
Build a custom preference center when you need to embed notification settings directly in your product, control the layout and UX, or support [per-tenant preferences](/multi-tenancy/per-tenant-preferences) or [object preferences](/preferences/object-preferences).
If you want a no-code option instead, see the [hosted preference center](/preferences/hosted-preference-center). Not sure which approach fits? See [Going live with preferences](/preferences/overview#going-live-with-preferences).
## Build a custom preference center
There are four steps to building a preference center with Knock.
The examples on this page focus on a user's default preference set. For other implementations, see [per-tenant preferences](/multi-tenancy/per-tenant-preferences) and [object preferences](/preferences/object-preferences).
An environment-level default preference set is the `PreferenceSet` users fall back to when they first sign up for your product. Any user who doesn't have a preference set of their own will use these environment defaults. You can create your environment default preferences in the Knock dashboard under **Platform** > **Preferences**.
Each environment has its own default preferences. You can copy the default preference set from one environment to another to keep your environments in sync.
If you create either an environment or tenant default{" "}
PreferenceSet those preferences will be merged with changes a
user makes in the UI, with the user-specified changes taking precedence. See{" "}
Merging preferences{" "}
for more information.
}
/>
Once you have your environment-level default preferences created, use the Knock client to retrieve the authenticated user's own `PreferenceSet`. If the user hasn't set any preferences of their own, `getPreferences()` returns the environment default set you created in the step above (merged with any tenant default), so you always have values to render.
```javascript title="Get preferences in your application"
import Knock from "@knocklabs/client";
const knockClient = new Knock(process.env.KNOCK_PUBLIC_API_KEY);
knockClient.authenticate({ id: user.id }, userToken);
const preferences = await knockClient.user.getPreferences();
```
For per-tenant preferences, pass the tenant id as the `preferenceSet` parameter on `knockClient.user.getPreferences()`. See [Per-tenant preferences](/multi-tenancy/per-tenant-preferences) for details.
Once you have loaded a user's preferences, you'll need to render an interface in your application so they can update their notification preferences. Typically you encapsulate all of the getting and setting of preferences in a single component.
There are two options for driving the rows in your UI:
- **Define labels and rows in application code.** Map preference keys to labels, descriptions, and channel type toggles directly in your component. See [Implementation examples](#implementation-examples) below for in-depth React walkthroughs.
- **Fetch dashboard-managed configuration from Knock.** Pull the row definitions you configured in the dashboard so non-engineers can manage the layout. See [Enable dashboard-managed configuration](#enable-dashboard-managed-configuration) below.
When a user makes changes to their preferences in your application, you will use the `setPreferences` method to save those changes back to Knock.
By default, `setPreferences` replaces any existing `PreferenceSet`, so include the complete set in your request. In this example, the user has opted out of collaboration emails:
```javascript title="Set preferences in your application"
await knockClient.user.setPreferences({
categories: {
collaboration: {
channel_types: {
email: false, // Changed to false after the user opted out.
in_app_feed: true,
},
},
"project-updates": {
channel_types: {
email: false,
in_app_feed: true,
},
},
},
});
```
To learn more about how to update just a single preference, see the [frequently asked questions](/preferences/overview#frequently-asked-questions) on the preferences overview.
## Enable dashboard-managed configuration
Instead of hardcoding row labels and structure in your application, you can fetch your preference center configuration from Knock and use it to drive your UI. This allows your team to manage rows, labels, and branding from the dashboard without shipping a code change.
You configure the preference center from the Knock dashboard under **Platform** > **Preferences** > **Preference center**. Note that this configuration is environment-specific.
Fetch the configuration using the same credentials as `getPreferences()`:
```javascript title="Get preference center config in your application"
const response = await fetch(
`https://api.knock.app/v1/users/${user.id}/preference_center/config`,
{
headers: {
Authorization: `Bearer ${process.env.KNOCK_PUBLIC_API_KEY}`,
"X-Knock-User-Token": userToken,
},
},
);
const { config, branding, enabled } = await response.json();
```
The [response](/api-reference/users/preference_center/get_config) returns everything you need to render and brand your UI:
| Field | Description |
| -------------- | ------------------------------------------------------------------------- |
| `config` | The `title`, `body`, and `rows` that make up the preference center. |
| `branding` | Your logo, icon, and brand colors, with an optional `dark` mode override. |
| `enabled` | Whether the preference center is enabled for this environment. |
| `account_name` | The account name to display alongside your logo. |
| `user_email` | A display label for the user, resolved as email, then user id. |
Each row in `config.rows` describes one preference control:
| Field | Description |
| --------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `type` | The kind of control: `workflow`, `channel`, `category`, `channel_types`, or `commercial_subscribed`. |
| `name` | The display name for the row. |
| `description` | Supporting text shown below the name. |
| `identifier` | The category name, workflow key, or channel ID the row controls. Present for `workflow`, `channel`, and `category` rows. |
| `channel_types` | The channel types the row is scoped to. An empty list or `null` means all channel types. Present for `workflow`, `category`, and `channel_types` rows. |
## Implementation examples
The following tutorials provide an in-depth walkthrough of how to build a preference center UI with React:
- **[React tutorial](/in-app-ui/react/preferences).** Build a `PreferenceCenter` component with `@knocklabs/client`.
- **[Headless tutorial](/in-app-ui/react/headless/preferences).** Build a custom preference interface with the `usePreferences` hook from `@knocklabs/react`.
## Object preferences
Documentation about storing preferences on objects.
---
title: Object preferences
description: Documentation about storing preferences on objects.
tags: ["object preferences", "preferences"]
section: Preferences
---
You can set a `PreferenceSet` on an object, just as you would for a user.
## Preferences conditions
Power advanced conditional logic in your preferences.
---
title: Preference conditions
description: Power advanced conditional logic in your preferences.
tags: ["preference conditions"]
section: Preferences
---
Preference conditions are [Knock condition models](/concepts/conditions) that are evaluated when computing the current state of your preferences during workflow execution.
## Overview
Typically, a `PreferenceSet` evaluates to boolean values representing whether your recipient has opted in or out of receiving notifications on a given channel, workflow, or category.
With preference conditions you can add additional custom expressions to a `PreferenceSet`, where the notification is only sent if all preferences (including every condition in the preference `conditions` list) evaluate to `true` at runtime.
When using a{" "}
batch function,
preference conditions for subsequent channel steps will only be evaluated
against the first activity in the batch.
}
/>
Below is an example of a workflow preference that has conditions applied to determine if the preference is `true` or `false`:
```json title="An example of preferences with conditions"
{
"id": "default",
"workflows": {
"dinosaurs-loose": {
"conditions": [
{
"variable": "recipient.muted_dinos",
"operator": "not_contains",
"argument": "data.dino"
}
]
}
}
}
```
## Set preference conditions for a user
To set preference conditions for a user, include a `conditions` array when you update the user's `PreferenceSet`. Conditions use the same preferences APIs as channel, category, and workflow preferences. You can call these endpoints from your backend with a secret API key, or from your application with a public API key and signed user token. See [Security and authentication](/in-app-ui/security-and-authentication) for details.
Follow this{" "}
link
{" "}
to see an example of how to set preferences with conditions.
}
/>
## Frequently asked questions
A condition can be applied at different points in the preference set:
- Inside `workflows`, `categories`, `channel_types`, or `channels` preferences.
- Inside an individual `workflows[workflow].channel_types` or `workflows[workflow].channels` preference.
- Inside an individual `categories[category].channel_types` or `categories[category].channels` preference.
- On the `commercial_subscribed` key of a recipient's `default` preference set. Useful for [suppressing commercial messages under a tenant](/multi-tenancy/per-tenant-preferences#frequently-asked-questions).
Knock will capture conditions evaluation details for all preference conditions resolved while executing your workflows. See the [documentation on debugging conditions](/concepts/conditions#debugging-conditions) for more info.
Yes. You can use multiple conditions within a single preference `conditions` array. Note that all conditions in the array must evaluate to `true` in order for the notification to be sent; this is a logical `AND` operation.
```json title="An example of multiple conditions on a single preference"
{
"conditions": [
{
"variable": "recipient.muted_dinos",
"operator": "not_contains",
"argument": "data.dino"
},
{
"variable": "recipient.id",
"operator": "not_equal_to",
"argument": "actor.id"
}
]
}
```
No, this is not currently supported. Each condition in the `conditions` array must evaluate to `true` for a notification to be sent.
## Commercial unsubscribe
Learn how to manage commercial email unsubscribe functionality in Knock.
---
title: "Commercial unsubscribe"
description: "Learn how to manage commercial email unsubscribe functionality in Knock."
tags: ["preferences", "unsubscribe", "commercial", "broadcasts", "workflows"]
section: Preferences
---
Knock provides built-in support for commercial email unsubscribe functionality, allowing recipients to opt out of promotional or commercial messages with a single click.
## How commercial unsubscribe works
When you mark a workflow or broadcast as commercial, Knock automatically handles the necessary unsubscribe functionality:
1. Adds required unsubscribe headers to all emails sent through that workflow or broadcast.
1. Provides an unsubscribe URL variable that can be included in your email templates.
1. Manages recipient opt-outs during [preference set evaluation](/preferences/overview#preference-evaluation-rules).
## Configuring commercial workflows
To enable commercial unsubscribe functionality for a workflow or broadcast:
1. Navigate to the workflow or broadcast.
1. For a workflow, click "Manage workflow." For a broadcast, click "Edit details."
1. Toggle "Commercial."
1. Save your changes.
1. For a workflow, commit your changes.
Once enabled, Knock will automatically include the necessary unsubscribe headers in all emails sent through that workflow.
## Adding unsubscribe links to emails
### Using footer links
When configuring an email layout using the visual editor, you can add an unsubscribe link to your email footer by clicking the "Add link" dropdown and selecting "1-click unsubscribe".
### Using the code editor
You can add an unsubscribe link to your email layouts or templates using the built-in variable:
```liquid title="Show unsubscribe link"
Unsubscribe
```
You can conditionally include the link by checking if the variable is present:
```liquid title="Show unsubscribe link only for commercial messages"
{% if vars.commercial_unsubscribe_url %}
Unsubscribe
{% endif %}
```
## Configuring the confirmation page
When a user unsubscribes by clicking the unsubscribe link, Knock displays a confirmation page showing they have been successfully unsubscribed from commercial messages. You can customize this page by navigating to **Platform** > **Preferences**, then clicking the **Unsubscribe** tab.
You can customize the title and body text that will appear on the Knock confirmation page.
You can provide a URL that recipients should be redirected to after unsubscribing.
## Preference evaluation rules
When a recipient clicks the unsubscribe link, their `default` preference set will be updated, marking `commercial_subscribed` as `false`. They will be opted-out of commercial messages, and they will continue to receive transactional messages based on their other preferences.
This recipient-level preference will take precedence over other environment or tenant preferences. Learn more about [preference merging](/preferences/overview#preference-evaluation-rules).
## Setting `commercial_subscribed` via API
The unsubscribe link writes this preference for you, but you can also set it yourself. This is useful to sync an opt-out you captured elsewhere in your product, or to backfill preferences across your existing users.
`commercial_subscribed` lives on the recipient's `default` preference set. Call the [set user preferences endpoint](/api-reference/users/set_preferences) with a `merge` persistence strategy to update this key without replacing the rest of the preference set.
```javascript title="Opt a user out of commercial messages"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await knock.users.setPreferences("user-id", "default", {
__persistence_strategy__: "merge",
commercial_subscribed: false,
});
```
To update many users at once, use [bulk set preferences](/preferences/overview#bulk-set-user-preferences).
## Learn more
To learn more about managing recipient preferences and building preference centers with Knock, visit our [preferences overview](/preferences/overview).
# Version control
Learn how versioning works within your Knock resources.
## Environments
Learn how to use Knock environments.
---
title: Environments
description: Learn how to use Knock environments.
tags:
[
"env",
"version control",
"variables",
"promote",
"promotion",
"staging",
"production write access",
"production member role",
"clone",
"cloning",
"duplicate",
"rename",
"renaming",
"slug",
]
section: Concepts
---
Knock environments enable you to test and review changes before you ship them to production.
Each Knock environment has its own isolated data (such as users, tenants, and objects) and its own version-controlled content (such as workflows, guides, and layouts.)
## How environments work
Your Knock account starts with two environments: development and production.
You can [create additional environments](/version-control/environments#create-additional-environments) (for example, a Staging environment to mirror your own development lifecycle.)
Environments contain isolated data (such as users, objects, and logs) and version-controlled content (such as workflows, layouts, and partials.)
With Knock environments you:
- Use environment-specific API keys to send data to your environments.
- Create, update, and version content within any environment.
- For production-critical use cases, create content in your development environment, then **promote** it to production.
Here's a typical setup for customers using Knock with two environments. 1.
**Development environment.** Usually used by engineering and product teams.
Contains your development data, and any transactional workflows or other
content you do not want people updating directly in production. 2.
**Production environment.** Usually used by growth and marketing teams.
Contains your production data, and your lower-risk content that does not
need to follow promotion, such as lifecycle workflows and one-time
announcements.
### Send data to environments
Each environment has a set of **data resources** that are per-environment and will never be shared between environments. These data resources are not version-controlled.
The following data resources are per-environment and not version-controlled:
- Users
- Audiences
- Tenants
- Objects
- Messages
- Analytics
- Logs
- Events
- Broadcasts
An example: the users you identify in Knock. Your real production users are identified in your production environment, while your test development users are identified in your development environment.
Each environment has its own set of API keys which you use to send data to the environment. You can find your environment-specific API keys under "Platform" > "API keys" in the Knock dashboard.
### Create content in environments
Each environment has a set of **content resources** that are managed via version control. These are resources associated with the creation and orchestration of the content you send to your customers.
The following content resources are version-controlled:
- Workflows
- Guides
- Layouts
- Partials
- Translations
- Reusable requests
Here's how content resources work:
- Content can be created in any environment.
- Content can be promoted upwards through environments.
- Content can only be edited in the environment in which it was created.
- Content is versioned with [commits](/version-control/commits). You can roll back to earlier commits at any time.
These rules enable two ways of working with content and shipping it to your end users in production:
For content managed by engineering, such as high-volume transactional workflows, this path ensures that content can only be updated in development before being promoted to production.
1. Create and update the content in your development environment
2. Commit the changes to your development environment
3. Promote the changes to your production environment when ready
For content managed by growth, marketing, and product, such as feature announcements and lifecycle workflows, this path is faster and doesn't require the promotion step.
1. Create and update the content in your production environment
2. Publish (commit) the changes to your production environment when ready
If you want to disable the ability to create content directly in production, you can do so in account settings under the Permissions page.
}
/>
If you are a pre-January-2026 customer, your account will default to
having production write access disabled. This means that your users will
only be able to create content in the development environment, then
promote it to production.
You can enable production write access in account settings under the{" "}
Permissions page, at which point
your users will be able to create content directly in production.
}
/>
## Clone resources across environments
You can clone supported resources from one environment to another in the Knock dashboard. Cloning creates a new copy of the resource in the destination environment. The clone gets a new key by default (with a `-copy` suffix) and is independent from the original.
Open a resource's action menu and select **Clone** (or **Duplicate** for email layouts) to start a clone. When your account has more than one writable destination environment, you can choose which environment to clone into.
Cloning is a dashboard-only feature. It is not available through the [Knock CLI](/cli/overview) or [Management API](/developer-tools/management-api) at this time.
### Supported resources
You can clone the following resources across environments:
- Workflows
- Broadcasts
- Guides
- Message types
- Email layouts
- Audiences
- Partials
- Translations
- Reusable requests
- Source event mappings
Archived resources cannot be cloned.
### Clone vs promote
Clone and promote solve different problems:
1. **Clone.** Creates a new resource in another environment. Use this when you want a copy to exist in both environments, or when you need to copy content to an environment lower in the promotion chain (for example, from production to development).
2. **Promote.** Moves committed changes for an existing resource up through your environment chain, keeping the same key. Use this when you are following the development-to-production workflow and want the same resource to exist across environments.
When you clone a workflow, Knock also copies its channel step templates and workflow schema into the destination environment.
### Environment targeting
Which environments you can clone into depends on your account's **production write access** setting on the **Permissions** page in your account settings:
1. **Production write access enabled.** You can clone into any environment in your project.
2. **Production write access disabled.** You can only clone into your Development environment.
This follows the same rules as creating and editing content in an environment. If production write access is disabled, environments other than Development are read-only and cannot be selected as a clone destination.
Branch environments cannot be used as clone targets.
### Common use cases
1. **Copy a broadcast from development to production.** Create and test a broadcast in development, then clone it to production when you are ready to send it to real users.
2. **Copy production content back to development.** If you created a workflow directly in production and want to edit it using the promotion model, clone it into your development environment. You can give the clone the same key as the production resource if you plan to promote it back and overwrite the production version later.
3. **Duplicate a workflow for experimentation.** Clone a workflow within the same environment (or into another environment) to try changes without affecting the original.
## Create additional environments
If you're looking for a way to isolate changes per-developer working
within Knock, you may want to consider using{" "}
branches.
}
/>
By default your Knock account comes with two environments: development and production. If you need an additional environment in Knock to mirror your own development lifecycle (for example, a staging environment) you can add it on the settings page of the Knock dashboard.
To create a new environment, go to the **Environments** page under the **Version control** section of your account settings. You'll see a button to "Create environment."
### Choose where the new environment goes
Environments are ordered, and that order determines your promotion path. When you create an environment, the **Insert after** select in the create modal determines where it lands. Choose the environment that the new environment should come directly after, and Knock inserts it one "level" above that environment.
Two constraints apply to the position you choose:
- **You cannot insert an environment above production.** Production is always the highest environment, so it isn't available in the select.
- **You cannot insert an environment below development.** Development is always the lowest environment, so the new environment will always sit above it.
By default the select is set to the second-to-last environment, which places the new environment directly below production. In a new account with only development and production, that means a new environment is inserted between the two.
Environments cannot be re-ordered after they're created, as this would break the promotion model for previously-promoted changes.
### What's in a new environment
A new environment is not empty. Knock seeds it from the environment directly below it when you create it, and different parts of your account are seeded in different ways:
| Resource | What the new environment starts with |
| --------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| Workflows, guides, layouts, partials, translations, and reusable requests | Promoted from the environment directly below it (the latest committed version of each item; archived items are skipped). |
| Environment variable values | Empty. Values are per-environment and you need to set them. |
| Channel settings | Provider credentials are not copied and you need to configure them. |
| Source settings | Every source in your project appears in the new environment with default settings and its own newly generated source URL. No settings are copied, so you need to point your provider at the new environment's URL. |
| Hosted preference center configuration | The default configuration. |
| API keys | A new public and secret key pair. |
| Users, tenants, objects, messages, and logs | Nothing. Data is never copied between environments. |
A new environment can look fully configured in the dashboard because its
variable keys and channels are all present, but it will not send anything
until you set your variable values and reconfigure your provider
credentials for each channel.
}
/>
## Rename an environment
You can rename any additional environment that you created. Your Development and Production environments cannot be renamed.
{/* prettier-ignore */}
Navigate to the **Environments** page under the **Version control** section of your dashboard's account settings.
Open the action menu next to the environment you want to rename, select
**Edit environment**, update the **Name** field, and click **Update**.
Knock derives an environment's slug from its name, so renaming an
environment also changes its slug. Update the following after you rename an
environment:
**CLI commands and CI pipelines.** Any `--environment` flag that uses
the old slug, such as `knock workflow list --environment=staging`.
**Management API requests.** Any `environment` or `to_environment` query
parameter that uses the old slug.
A renamed environment keeps its unique ID, its API keys, and its position in your promotion path. Workflows, guides, layouts, and other content are untouched, and no data moves between environments. Any environment-specific [custom permissions](/manage-your-account/roles-and-permissions#custom-permission-groups) are also preserved on the renamed environment.
Renaming an environment requires the `owner` or `admin` role, or a custom role with environment management permissions.
A branch takes the name you give
it when you create it, and that name is fixed for the life of the branch.
If you need a different name, delete the branch and create a new one.
}
/>
## Environment access controls
We recognize the importance of protecting your sensitive data, so we designed Knock from the ground-up with privacy and security in mind.
There are two tools you can use to control access to your data in the Knock dashboard:
- [Roles and permissions.](/manage-your-account/roles-and-permissions) Knock offers built-in roles for common team functions, and on Enterprise plans [custom permission groups](/manage-your-account/roles-and-permissions#custom-permission-groups) with per-environment access controls. For example, you can give support team members access to debug issues without permission to change notification logic, or deny access to an environment entirely.
- [Customer data obfuscation.](/manage-your-account/data-obfuscation) Use environment-level controls to hide customer data for every team member in an environment. On Enterprise plans, [custom permission groups](/manage-your-account/roles-and-permissions#customer-data-obfuscation) can also set per-environment obfuscation rules.
## Frequently asked questions
Not at this time. You can only create, rename, and delete environments
through the Knock dashboard.
Yes. Use [cloning resources across
environments](/version-control/environments#clone-resources-across-environments)
to copy the resource into your development environment. By default a `-copy`
suffix will be added to the key of the cloned resource. Set the key to match
the production resource that you're cloning if you want promotions from the
lower environment to overwrite the production version later on.
## Branches
Learn how to use branches to isolate changes to your Knock resources.
---
title: "Branches"
description: "Learn how to use branches to isolate changes to your Knock resources."
tags: ["version control", "branches", "environments", "commits"]
section: Version control
---
## What are branches in Knock?
Branches in Knock are a way to isolate changes to your Knock resources, like workflows, layouts, and guides. They're like sandboxes for your changes, allowing you to make changes to your versionable resources without affecting the `main` branch (your `development` environment), or other branches in your account.
Knock branches are conceptually similar to Git branches, and are designed to be used in a similar way as part of your development workflow with Knock. You can create a branch, make changes to your resources, and merge those changes into the main branch when you're ready. Your Knock branches can mirror your Git branches, so that you can coordinate feature changes between your application and Knock.
Branches are a completely optional feature in Knock. If you don't use branches, you can still use Knock's [commit model](/version-control/commits) to version changes to your resources [in isolated environments](/version-control/environments).
## Create a branch
**In the dashboard**
You can create a new branch in the Knock dashboard by going to the **Branches** page in your account settings and clicking the "Create branch" button. Alternatively, you can type into the branch selector at the top of the Knock dashboard to quickly create a new branch. By default, you'll be on the `main` branch.
The branch selector in the Knock dashboard.
**In the CLI**
```bash title="Creating a new branch in the CLI"
knock branch create my-branch
```
## Making changes on a branch
Once you create a branch, Knock will copy over all of the resources from the main branch into your new branch so they're available to be worked on. You can then select the branch you want to work on in the branch selector at the top of the Knock dashboard, or alternatively you can work with your resources on the branch via the [Knock CLI](/developer-tools/knock-cli) or [Management API](/developer-tools/management-api).
**In the dashboard**
You can select a branch via the branch selector at the top of the Knock dashboard. Once you've selected a branch, making changes to your resources on that branch is the same as making changes to your resources on the main branch. You can edit workflows, layouts, audiences, and other resources just as you would on the main branch.
Any changes you've made to your resources will not be able to be called via the API until you commit those changes to the branch. You can commit changes under the "Commits" section of the dashboard, or under each resources "Changes" tab.
**In the CLI**
To work with your resources on a branch via the CLI, you can use the `knock branch switch` command to switch to the branch you want to work on.
```bash title="Switching to a branch in the CLI"
knock branch switch my-branch
```
Once you've switched to the branch you want to work on, you can make changes to your resources just as you would on the main branch. You can then push and commit those changes to the branch.
```bash title="Pushing and committing changes in the CLI for a branch"
knock workflow push my-workflow --commit
```
You can also pass in the optional `--branch` flag to specify the branch you want to work with.
```bash title="Pushing and committing changes in the CLI for a specific branch"
knock workflow push my-workflow --branch my-branch --commit
```
If you need to overwrite existing content in Knock (for example, when local changes should replace what is currently stored), you can add the `--force` flag to the push command.
## Rebase a branch
When `main` moves ahead while you're working on a branch, you can rebase the branch to bring in the latest changes from `main` while preserving your branch's commits. Rebase updates your branch in place. It does not promote your branch's changes to `main` — use [merge](#merging-changes-from-a-branch) for that.
Rebasing always syncs a branch onto `main` in the `development` environment. You cannot rebase onto staging, production, or another branch.
**In the dashboard**
When your branch is behind `main`, Knock shows a banner on the **Commits** page indicating how many commits behind you are. You can rebase from there, from the branch selector, or when resolving a merge conflict.
**In the CLI**
```bash title="Rebasing a branch in the CLI"
knock branch rebase my-branch
```
See the [CLI reference](/cli/branch/rebase) for flags and error handling.
### How rebase works
During a rebase, Knock compares each resource on `main` with the same resource on your branch and applies automatic resolution:
| Situation | What happens |
| ------------------------------------------------------ | ------------------------------------------------------------ |
| You have unmerged commits for a resource on the branch | Your branch version is preserved |
| You have not changed a resource on the branch | The branch receives the latest committed version from `main` |
| A resource exists on `main` but not on the branch | The resource is copied into the branch |
Knock does not perform a Git-style three-way merge or per-field conflict resolution during rebase. For resources you have changed on the branch, your branch's version wins automatically.
Rebasing also resets the conflict-detection baseline for your branch. If the branch and `main` both changed the same resource and Knock previously flagged a merge conflict, rebasing can clear that conflict by absorbing the changes from `main` that your branch had not modified.
### Before you rebase
Rebase may be blocked when you have **unpublished changes on shared resources** where `main` has moved ahead since your branch last synced. In that case, commit or discard the blocking drafts before rebasing. Knock returns an error listing the affected resources.
Rebase is **not** blocked by:
- Unpublished changes on resources you have already committed to on the branch
- Unpublished changes on resources that exist only on your branch
- Unpublished changes on shared resources where `main` has not changed
## Merging changes from a branch
**In the dashboard**
You can view the changes made to a branch in the Knock dashboard by going to the **Commits** page. From there you can navigate to the "Unmerged changes" tab to see all changes that have not been merged into the main branch.
When you're ready to merge the changes from a branch into the main branch, you can click the "Merge all changes" button to merge all commits from the branch into the main branch, or you can merge individual commits from the branch into the main branch.
## Delete a branch
Once a branch is merged into the main branch, you may wish to delete the branch from your account. Deleting a branch is a permanent operation and cannot be undone. Doing so will delete all of the resources in the branch, including all commits and changes made to your resources on the branch that have not been merged into `main`.
**In the dashboard**
You can delete a branch in the Knock dashboard by going to the **Branches** page in your account settings and clicking the "Delete branch" button next to the branch you want to delete.
**In the CLI**
```bash title="Deleting a branch in the CLI"
knock branch delete my-branch
```
## Working with branches in the API
Branches are fully supported in the Knock API so that you can execute workflows, create users, and manage preferences in a branch-specific environment. When making requests to the API for your branch, you **must use the API key for your `development` environment**, along with a special `X-Knock-Branch` header to specify the branch you want to work with.
```bash title="Specifying a branch in the API"
curl -X POST "https://api.knock.app/v1/workflows/my-workflow/trigger" \
-H "Authorization: Bearer $KNOCK_API_KEY" \
-H "X-Knock-Branch: my-branch" \
-d '{"recipient": "jhammond"}'
```
Branches are fully supported in our server-side and client-side SDKs as well.
```javascript title="Specifying a branch in the SDK"
import Knock from "@knocklabs/node";
const knock = new Knock({
apiKey: process.env.KNOCK_API_KEY,
branch: "my-branch",
});
await knock.workflows.trigger("my-workflow", {
recipient: "jhammond",
});
```
## Working with branches in the CLI
Branches are supported in the Knock CLI for all commands that interact with resources in your Knock account. You can always use the `--branch` flag to specify the branch you want to work with or set a `.knockbranch` file in your home directory to specify the branch you want to work with.
```bash title="Specifying a branch in the CLI"
knock workflow list --branch my-branch
```
It's also possible to use the CLI to programmatically create, update, delete, rebase, and merge branches.
## Working with branches via the Management API
When using the management API, you can specify the branch you want to work with by passing the `branch` query parameter to the API endpoint, similar to how you would specify the environment.
```bash title="Specifying a branch in the Management API"
curl -X GET "https://control.knock.app/v1/workflows?branch=my-branch" \
-H "Authorization: Bearer $KNOCK_SERVICE_TOKEN"
```
It's also possible to use the management API to programmatically create, update, delete, and rebase branches.
```bash title="Rebasing a branch via the Management API"
curl -X PUT "https://control.knock.app/v1/branches/my-branch/rebase?environment=development" \
-H "Authorization: Bearer $KNOCK_SERVICE_TOKEN"
```
## Recipients and audiences
Branches share the same set of [users, objects, and tenants](/concepts/recipients) as the main branch. In other words, if you add, remove, or update a user, object, or tenant on the main branch, the change will be reflected on all branches, and vice versa. This means you can instantly start testing the changes you make on a branch: as soon as you create a branch, you can send notifications to the same users, objects, and tenants as you would on the main branch.
Similarly, [audience](/concepts/audiences) membership changes in the main branch are reflected in all branches: if a user is added to an audience on the main branch, they will be added to the same audience on all branches.
## Limitations
There are a few limitations to branches in Knock:
- Branches are **only** available in the `development` environment.
- Rebase is **only** available in the `development` environment and always targets `main`.
- Rebase uses automatic branch-wins resolution. Knock does not provide per-field merge or conflict resolution during rebase.
- Rebase may be blocked when you have unpublished changes on shared resources where `main` has moved ahead. Commit or discard those drafts before rebasing.
- If you have merge conflicts on a resource that is part of a branch, you can rebase the branch to absorb non-conflicting changes from `main`, or resolve the conflicts outside of the dashboard via the CLI in order to continue.
- [Audiences](/concepts/audiences) cannot be created or updated on a branch.
- Branches are not supported for [broadcasts](/concepts/broadcasts).
- Branches are not supported for [sources](/integrations/sources/overview).
- Branches are not supported for [webhooks](/integrations/webhooks/overview).
## Frequently asked questions
A branch is a way to isolate changes to your Knock resources. It's like a
sandbox for your changes.
Branches will always use the channel settings configured for the `development` environment (the `main` branch).
No, you cannot yet block changes being made directly to your development
environment. However, we're considering this feature and would love to hear
your use case if you'd like to see this feature. Please [get in
touch](mailto:support@knock.app) and we can discuss your use case further.
No, there's not currently a way to put a review process in place before
merging changes from a branch into the main branch.
No, there's no limit to the number of branches you can have in your account.
## Commits
Learn about how Knock's commit and promotion model works.
---
title: Commits
description: Learn about how Knock's commit and promotion model works.
tags:
[
"branches",
"env",
"version control",
"versions",
"commit",
"promote",
"promotion",
"revert",
"rollback",
"staging",
"active",
"inactive",
"diffs",
"push",
]
section: Concepts
---
To version the content changes you make in your [environments](/version-control/environments), Knock uses a commit model.
## How commits work
When you make a change to a content resource (like a workflow or a layout) in the Knock dashboard, you need to commit it to your current environment before those changes will appear in workflows triggered via the API.
Commits can be promoted to higher environments, such as production, and they can also be rolled back to prior commits. Lastly, commits provide a comprehensive version history for all content resources in your account.
A few additional notes:
- **A commit is not a save.** When you're drafting a workflow or a template, you can save and test your changes. Saved changes apply when you're using the test runner, but they do not apply to workflow runs or guide renders that are invoked via the API. To test changes via the API, you must commit them.
- **"Publish" in production = commit to production.** If you're working [directly in production](/version-control/environments), the "Publish" button is the same as the "Commit" button. You'll still get a commit history and be able to roll back to prior versions if needed.
- **Account-level resources are not version controlled.** Channel configurations, branding, and variables do not need to be committed, as they live at the account-level. This means that if you make a change to a channel configuration, it will update immediately on notifications sent in that environment.
- **You can commit changes using our CLI and management API.** We offer both a [Management API](/developer-tools/management-api) and a [command line interface](/developer-tools/knock-cli) for interacting with Knock resources programmatically, both of which support programmatic commits.
## Empty commits
An empty commit lets you commit (publish) a versioned resource without changing its content, similar to `git commit --allow-empty`. Empty commits are useful when you need to promote a resource to another environment, but the resource has no unpublished changes in the current environment.
Knock tracks promotable changes by comparing each resource's identifier (`ref`) and version (`version_id`). If a resource already points to the published version (`current_version_id == published_version_id`), a standard commit does not create a new promotable change. An empty commit solves this by creating a new version with the same content, then publishing that version, giving Knock a new `version_id` to include in promotion diffs, so you can promote the commit downstream even though the resource content has not changed.
What happens when you create an empty commit depends on the resource's current state:
- **The resource has unpublished changes.** The empty-clone step is skipped, and a normal publish happens instead.
- **The resource is already published with no changes.** An empty commit creates a new version with identical content.
Commit log entries for empty commits include audit metadata with `empty: true` and an optional message.
You can create empty commits using the [CLI](/cli/commit/all) or the [Management API](/developer-tools/management-api#committing-changes). The bulk commit endpoint (`PUT /v1/commits`) supports the following resource types:
- `workflow`
- `email_layout`
- `partial`
- `translation`
- `message_type`
- `guide`
- `audience`
For translations, the `resource_id` can be a locale (`es`), a locale and namespace (`es/courses`), or a locale, namespace, and tenant (`es/courses~tenant`).
The bulk commit endpoint doesn't support reusable_step. To
create an empty commit for a reusable step, use a resource upsert with{" "}
commit=true and allow_empty=true, or publish via
the dashboard.
}
/>
## Visualizing commit changes
Clicking the "Commit to development" button will show you a view of changes between your current commit and the most recent version of the resource that you're updating. Commit diffs are also available on your full commit log (viewable on the "Commits" page in your dashboard), so you can view the commit history for a resource and know exactly what was changed with each commit.
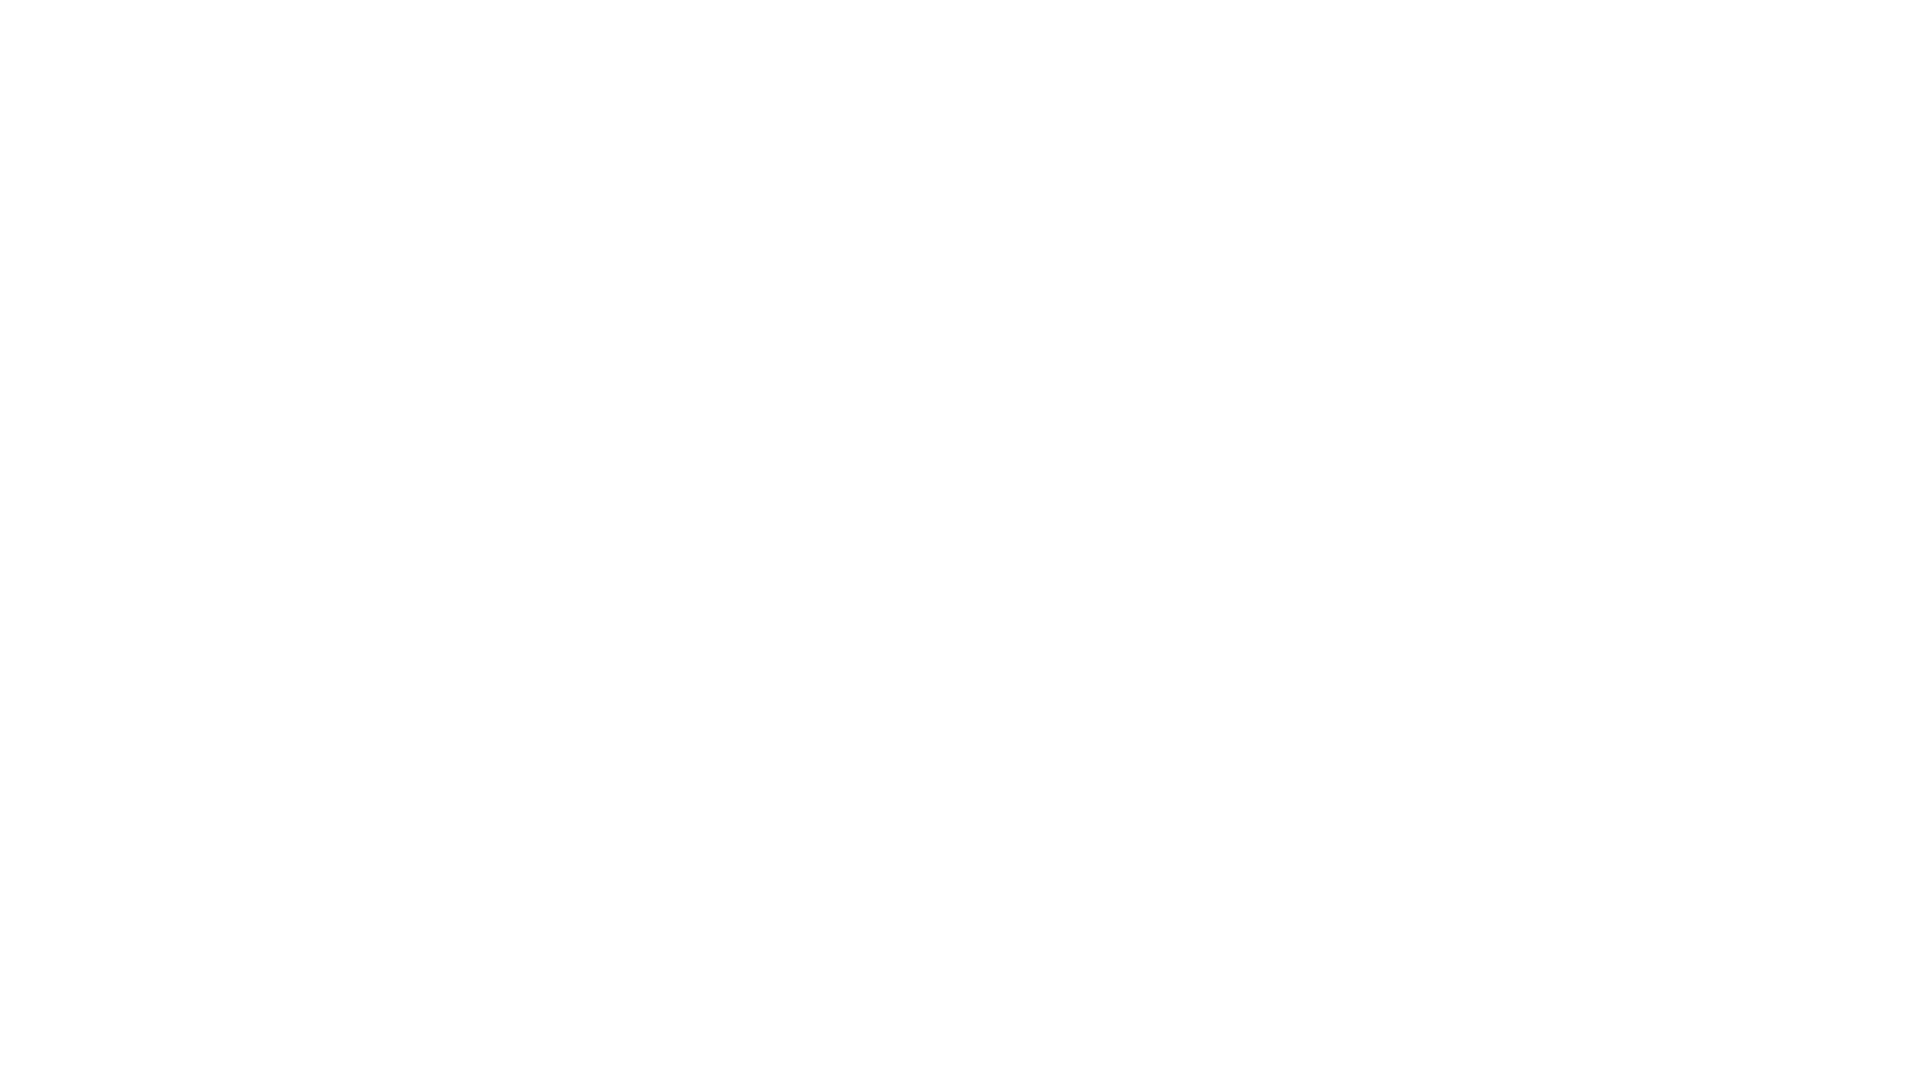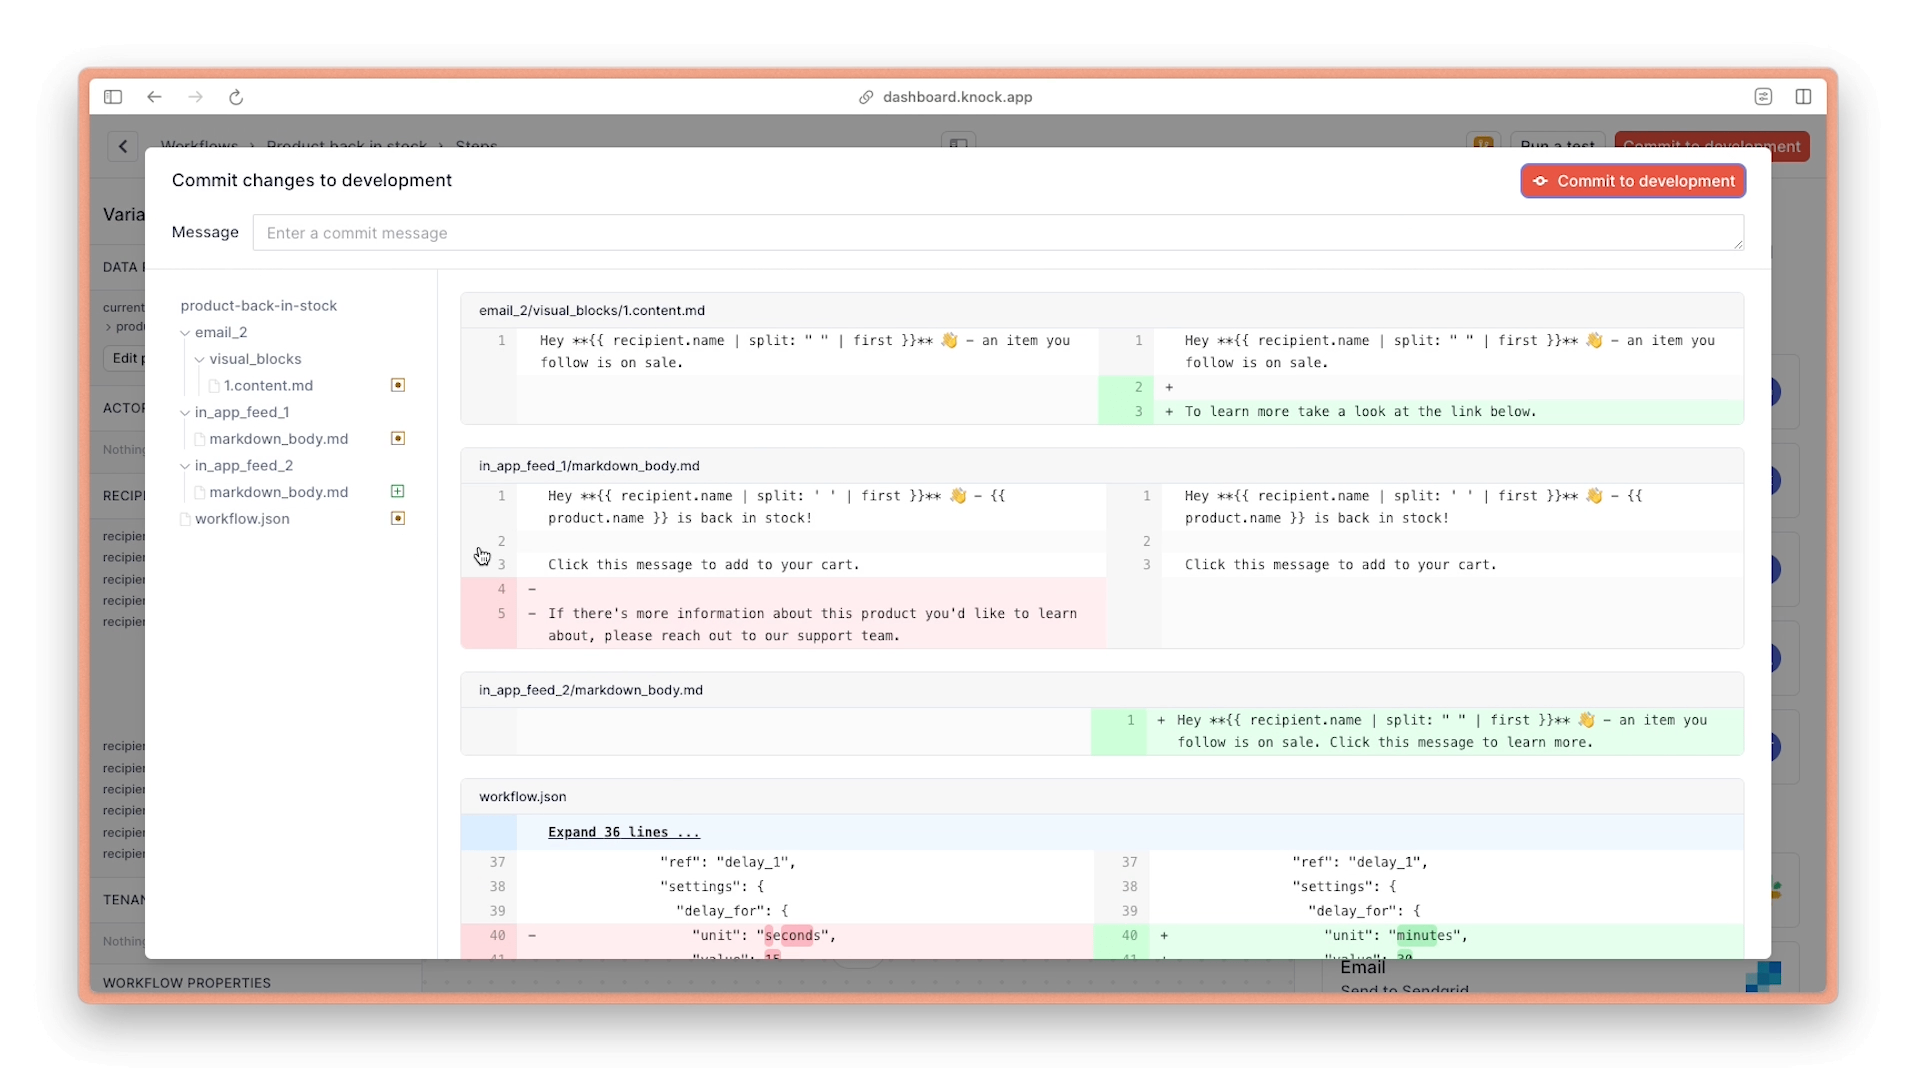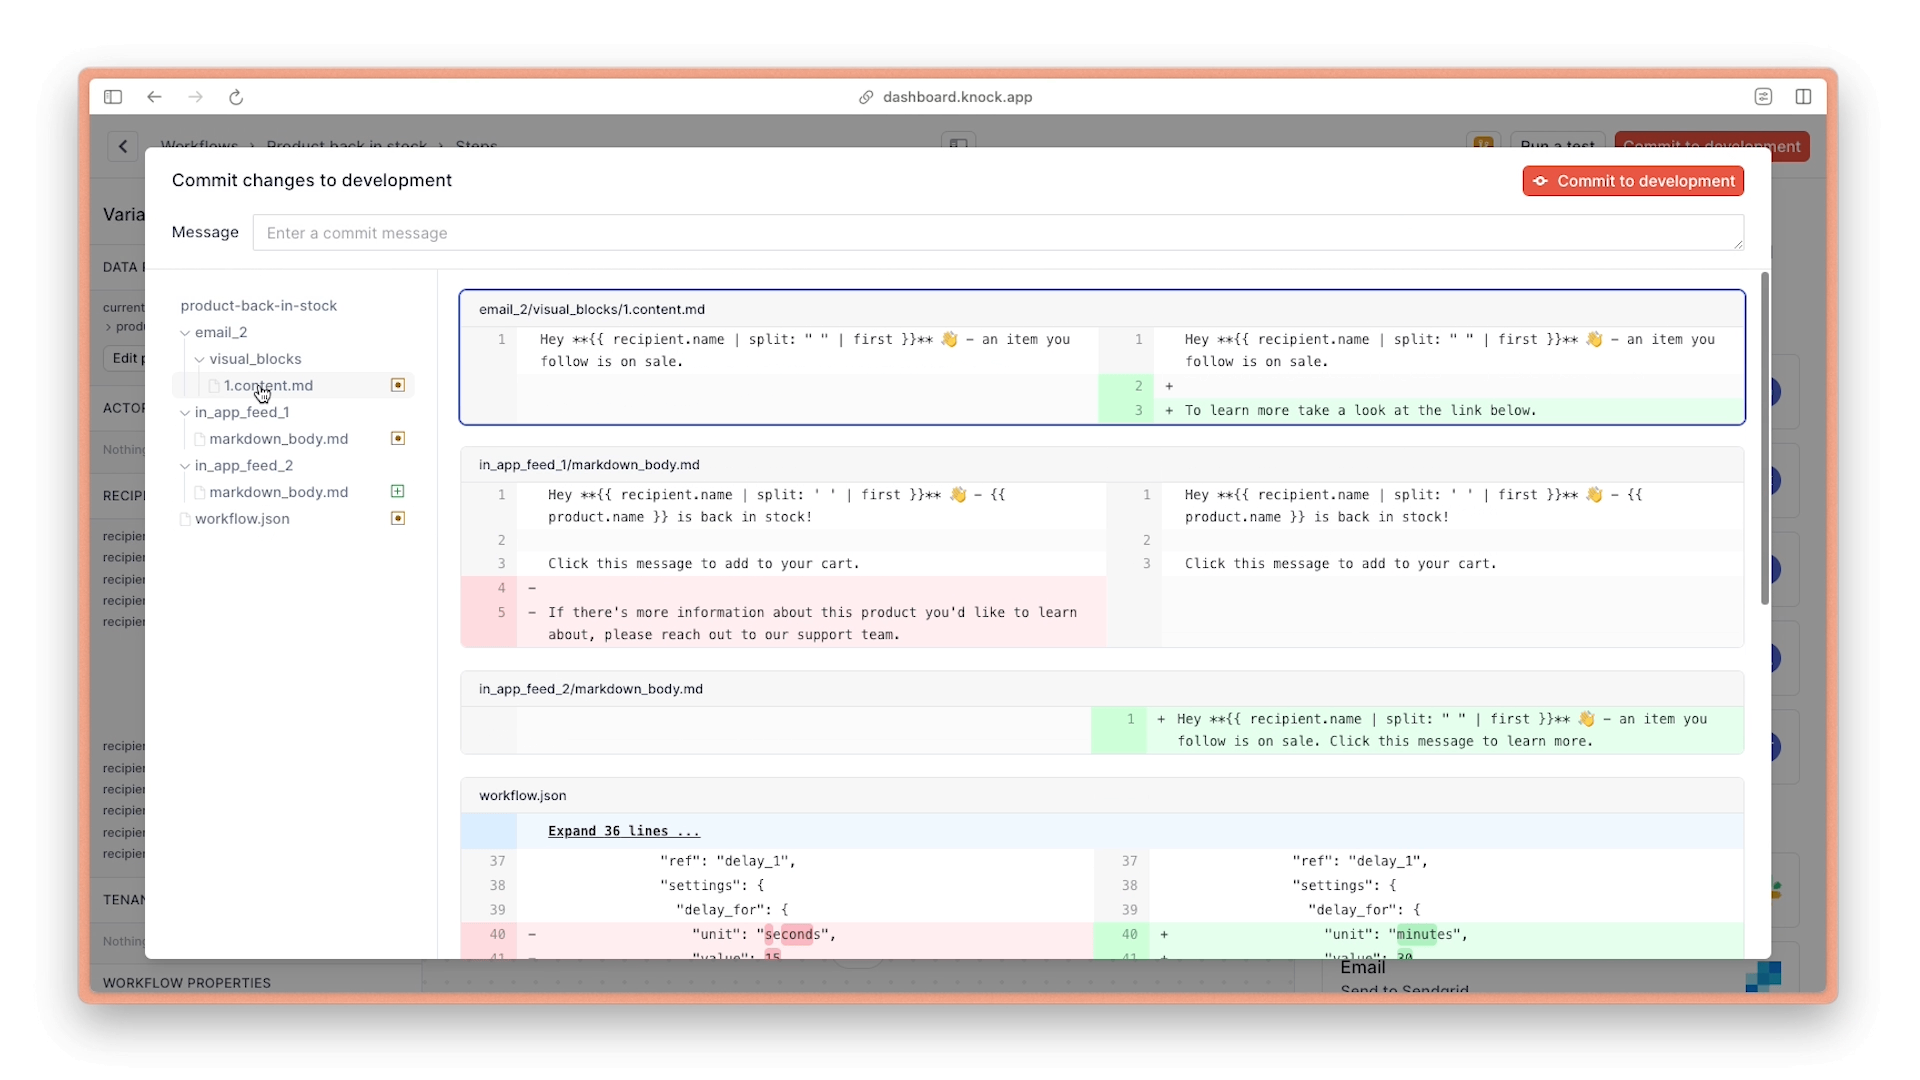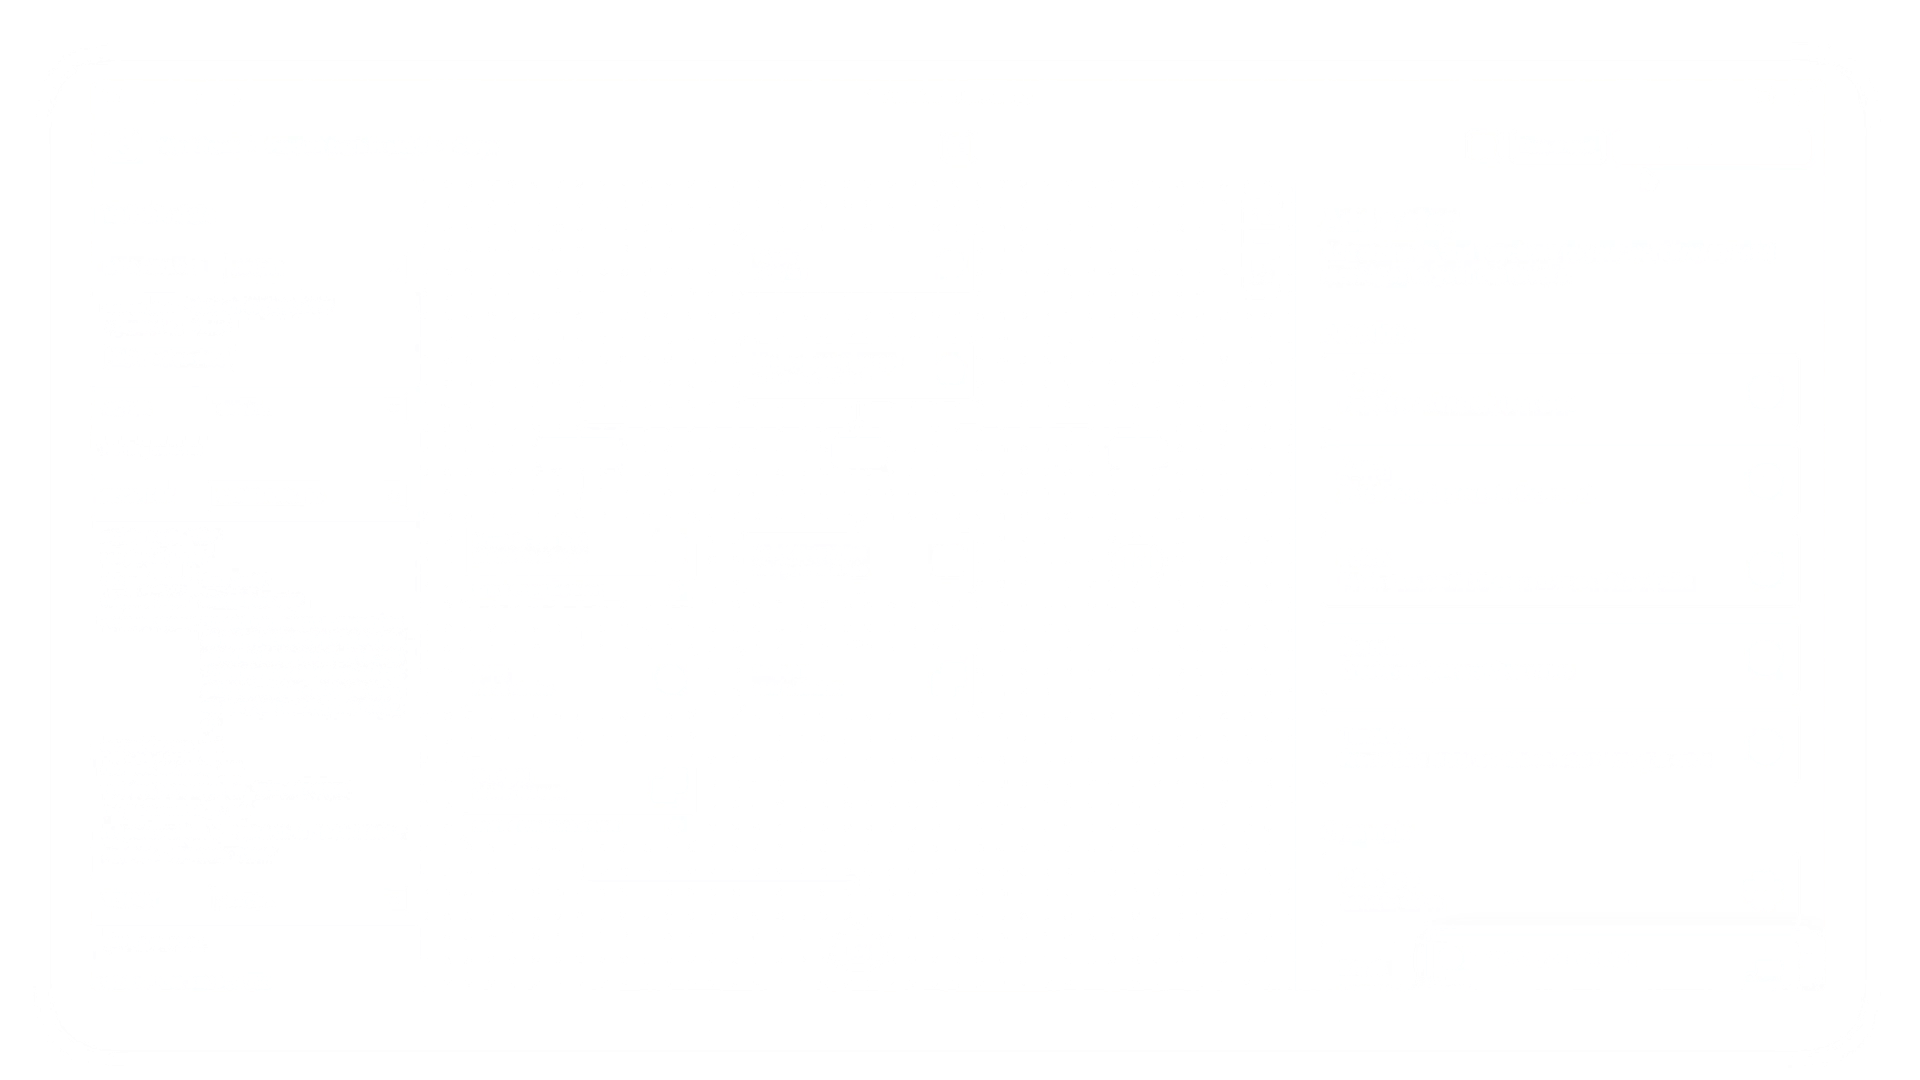
## Promoting commits
If you're working in a non-production environment such as development, you can promote your changes to the production environment when you're ready to go live.
You can promote your commits from a given resource's page. You can also view all commits in one place in the **Commits** page, where you can promote individual or multiple commits at once.
Learn more about promoting commits in our [environments documentation](/version-control/environments).
## Reverting a commit
If you've made a change in a commit that you want to revert, you can use the "Revert commit" feature to "undo" that change. You can find the revert commit action on the **Commits** page in the dashboard, under the "Unpromoted changes" and "Commit log" tabs.
For resources promoted from development, reverts must be made in the
development environment and then promoted to production to revert the
production commit.
}
/>
**Reverting a commit will**:
- Create a new commit with a message that indicates the commit reverts a preceding commit
- Wind back the state of the resource to the change that precedes the commit
- Undo any uncommitted changes on the resource
Because the revert will produce a new commit, you can then promote that commit to other environments to make that change live in those environments.
# Manage your account
Learn more about the tools available in managing your Knock account.
## Authentication methods
Learn more about the authentication methods available to members on your Knock account.
---
title: Authentication methods
description: Learn more about the authentication methods available to members on your Knock account.
tags: ["auth", "login", "sso", "security"]
section: Manage your account
---
Understand and select your preferred authentication method in Knock.
## Overview
We support three methods of authenticating users to get access to the Knock dashboard: email based passwordless authentication, Google SSO, and SAML 2.0 SSO.
You can add an extra layer of security on top of email and Google login with [multi-factor authentication (MFA)](/manage-your-account/multi-factor-authentication), which supports authenticator apps and passkeys.
## Email (passwordless)
With this authentication method users will receive an email to authenticate themselves in order to access the Knock dashboard. The email contains a "magic link" that expires after 5 minutes of being generated. Clicking the link will authenticate the user and grant access to the Knock dashboard.
## Google SSO
Users can authenticate using their Google account to access their Knock account. Google SSO works for both personal and organizations using Google Workspace (formerly G Suite).
## SAML 2.0 SSO
Users can authenticate with their chosen corporate identity provider (i.e. Okta) to access their Knock account.
Once SSO is enabled for an account, all members are redirected through that identity provider's authentication flow. Moving forward, they must pass through SSO to access their Knock account.
**Note**: SAML 2.0 SSO is only available to **Enterprise** plan customers. Enabling SAML 2.0 SSO will force all members of your account on a matching domain to authenticate via your identity provider.
## Multi-factor authentication
Add an extra layer of security to your Knock account by enabling multi-factor authentication (MFA) with an authenticator app or passkey for dashboard login.
---
title: Multi-factor authentication
description: Add an extra layer of security to your Knock account by enabling multi-factor authentication (MFA) with an authenticator app or passkey for dashboard login.
tags:
[
"mfa",
"2fa",
"two-factor",
"authenticator",
"passkey",
"webauthn",
"biometric",
"backup codes",
"security",
"login",
]
section: Manage your account
---
## Overview
Multi-factor authentication (MFA) adds a second verification step on top of your existing [login method](/manage-your-account/authentication-methods). After you sign in with email or Google, Knock prompts you to verify your identity before granting access to the dashboard.
Knock supports two MFA methods:
1. **Authenticator app (TOTP).** Enter a one-time 6-digit code from an app such as 1Password, Authy, or Google Authenticator.
2. **Passkey.** Authenticate with a WebAuthn-compatible device using biometrics, a device PIN, or a hardware security key.
MFA applies to email (passwordless) and Google logins. If your account uses [SAML SSO](/manage-your-account/saml-sso), your identity provider handles MFA for those users and Knock does not prompt for an additional factor.
## Enroll in MFA
Any member can enroll in MFA from their profile settings in the Knock dashboard. Account owners and admins who want to require MFA for all members use a separate account-level setting (see [Enforce MFA for your account](#enforce-mfa-for-your-account) below).
If your account owner or admin has enabled account-wide MFA enforcement, you are prompted to complete enrollment the next time you log in before you can access the dashboard.
### Enroll with an authenticator app
1. Click **Overview** in the sidebar, then open your **profile settings** and navigate to the **Security** section.
2. Under **Two-factor authentication**, click **Set up**.
3. Scan the QR code with an authenticator app (such as 1Password, Authy, or Google Authenticator).
4. Enter the 6-digit code from your authenticator app to confirm enrollment.
5. Save your backup codes in a secure location. Knock shows these codes once during enrollment.
### Enroll with a passkey
1. Click **Overview** in the sidebar, then open your **profile settings** and navigate to the **Security** section.
2. Under **Two-factor authentication**, click **Add passkey**.
3. Select your preferred authenticator when prompted. Available options depend on your browser and device (for example, Touch ID, Face ID, Windows Hello, a hardware security key, or a password manager).
4. Follow the on-device prompts to complete registration.
5. The passkey appears in your list of enrolled MFA methods in **Security** settings.
You can enroll multiple passkeys, such as one for your laptop and one for your phone. Remove any passkeys you no longer use from your profile **Security** settings.
## Backup codes
When you enroll with an authenticator app, Knock generates a set of backup codes you can use to sign in if you lose access to your app. Each backup code is single-use.
You can regenerate backup codes from your profile **Security** settings at any time. Regenerating codes invalidates any previously issued backup codes.
If you enroll with a passkey, you verify your identity with your enrolled device or security key at login instead of using backup codes.
## Logging in with MFA
When MFA is enabled on your account, Knock prompts you to verify your identity after you complete the initial sign-in step (email magic link or Google SSO).
1. **Authenticator app.** Open your authenticator app and enter the current 6-digit code on the MFA challenge screen.
2. **Passkey.** Click **Sign in with passkey** on the MFA challenge screen and complete the WebAuthn prompt on your device.
3. **Backup codes.** If you cannot access your authenticator app, click **Use a backup code** and enter one of your saved backup codes instead.
After you verify your identity, Knock authenticates your session and redirects you to the dashboard.
## Enforce MFA for your account
Account owners and admins can require all members to enroll in MFA before they can access the dashboard. This is separate from enrolling MFA for your own login on the **Profile** page.
1. Log in to your Knock dashboard.
2. Navigate to the **Security** page under **Admin** in your account settings (`dashboard.knock.app//settings/security`, where `` is your account identifier).
3. Toggle **Require multi-factor authentication** to enable enforcement for all members.
When enforcement is enabled, members who have not yet enrolled in MFA are prompted to enroll at their next login or token refresh. They can choose an authenticator app or a passkey. They cannot access the dashboard until enrollment is complete.
The require MFA toggle is not available for accounts with SAML SSO
enabled. Your identity provider manages authentication, including MFA, for
members who sign in through SSO.
}
/>
## Reset a member's MFA
If a member loses access to their MFA methods, an account owner or admin can reset their MFA from the account **Security** settings. Resetting a member's MFA removes all enrolled factors, including authenticator apps, passkeys, and backup codes. The member must enroll again at their next login.
## Frequently asked questions
Knock supports TOTP-based authenticator apps, including 1Password, Authy,
Google Authenticator, and other apps that scan QR codes or accept
`otpauth://` URIs.
Passkeys work in WebAuthn-compatible browsers and devices. You can use
biometrics such as Touch ID or Face ID, a device PIN, a password manager, or
a hardware security key.
Yes. You can enroll an authenticator app, one or more passkeys, or both. At
login, Knock prompts you to verify with whichever method you choose on the
MFA challenge screen.
Yes. You can remove individual passkeys from your profile **Security**
settings at any time.
Yes. You can disable MFA from your profile **Security** settings. You must
verify your identity to confirm, such as by entering a current code from
your authenticator app or using a passkey. If your account owner or admin
has enabled account-wide MFA enforcement, you cannot disable MFA until
enforcement is turned off.
Contact an account owner or admin to reset your MFA. After the reset, you
enroll a new MFA method at your next login.
Contact an account owner or admin to reset your MFA. After the reset, you
enroll a new MFA method at your next login.
No. MFA applies to interactive dashboard login only. API keys, service
tokens, and other machine-to-machine credentials are not affected.
## SAML SSO
How to configure SAML SSO on your account.
---
title: SAML SSO
description: How to configure SAML SSO on your account.
tags: ["authentication", "SAML", "SSO"]
section: Manage your account
---
SAML SSO is only available on our{" "}
Enterprise plan.
}
/>
## SSO configuration
To configure SAML SSO, an **account owner** will need to complete the following steps:
1. Log in to your Knock dashboard
2. Navigate to the **Security** page under the account settings section of your dashboard
3. Locate the "Enable SAML SSO" panel
4. Click on the "Connect SSO provider" button to begin the configuration process. This will launch our SAML SSO configuration wizard where you can select and configure your identity provider.
SAML SSO configuration wizard
After completing the steps of the configuration walkthrough, SAML will be successfully
configured for your account. This will allow users with emails under your domain
to be able to log in successfully through the provider you have configured.
Self-service SAML SSO configuration will allow users to authenticate using
emails under the same domain as your own. If your setup requires support
for more than one domain, contact support.
}
/>
## SSO authentication
Once SAML SSO is configured on your account, all members will be required to log in using the provider you
configured. When visiting the login screen, users must use the email field to start the authentication flow.
Users will **not be allowed to authenticate** using other authentication methods while SAML SSO is enabled on your account.
## Directory sync (SCIM)
How to configure directory sync on your account to automate the management of users and their permissions from your identity management platform to Knock.
---
title: Directory sync (SCIM)
description: How to configure directory sync on your account to automate the management of users and their permissions from your identity management platform to Knock.
tags: ["authentication", "directory sync", "SCIM", "ULM", "permission groups"]
section: Manage your account
---
Directory sync is only available on our{" "}
Enterprise plan.
}
/>
## Overview
Directory sync allows you to automatically provision users and manage their permissions in Knock by leveraging the identity provider your organization is using (e.g. Okta) as the single source for user and group information.
Once configured, it enables automated syncing of user identity information from identity providers to Knock using SCIM (System for Cross-domain Identity Management), an open standard for managing automated user and group provisioning.
Any users that are assigned in the Knock application in your identity provider will be created in Knock (or vice versa), with their roles and permissions automatically configured based on their group memberships. Group memberships can map to built-in roles or to [custom permission groups](/manage-your-account/roles-and-permissions#custom-permission-groups). See the default group to [role mapping](/manage-your-account/directory-sync#group-to-role-mapping) for more details.
## Directory sync configuration
Contact the [Knock support team](mailto:support@knock.app) to set up directory sync for your account. You'll receive a custom link to step-by-step instructions for configuring the directory sync for your specific identity provider.
We support many common identity providers. For detailed, provider-specific setup documentation, please refer to the following:
- [CyberArk](https://workos.com/docs/integrations/cyberark-scim/2-select-or-create-your-cyberark-application)
- [Entra ID (formerly Azure AD)](https://workos.com/docs/integrations/entra-id-scim/2-select-or-create-your-azure-application)
- [JumpCloud](https://workos.com/docs/integrations/jumpcloud-scim/2-select-or-create-your-jumpcloud-application)
- [Okta](https://workos.com/docs/integrations/okta-scim/2-select-or-create-your-okta-application)
- [OneLogin](https://workos.com/docs/integrations/onelogin-scim/2-select-or-create-your-onelogin-application)
- [PingFederate](https://workos.com/docs/integrations/pingfederate-scim/2-install-the-scim-connector-in-pingfederate)
- [Rippling](https://workos.com/docs/integrations/rippling-scim/2-create-your-rippling-application)
Once the setup is complete and user data starts syncing from your identity provider to Knock, you'll see a "connected" status for directory sync on the **Security** page under the **Admin** section of your account settings in your Knock dashboard.
## Group-to-role mapping
You can optionally supply a set of group mappings for your organization. For instance, you might map the "Team Admins" group to the `admin` role, or the "Engineering" group to a [custom permission group](/manage-your-account/roles-and-permissions#custom-permission-groups) with the key `engineering`. You must supply this mapping to the Knock support team to set on your account as there is currently no way to self-service this information.
Groups must be mapped to either a built-in role (`owner`, `admin`, `member`, `production_only_member`, `billing`, `support`) or a custom permission group key. The mapping value should always be the role or permission group key itself (`admin`, `engineering`), not a `knock-role-` prefixed value. Knock's default `knock-role-{key}` group names always apply and cannot be overridden by a custom mapping.
### Built-in role groups
To assign a built-in role from your identity provider, use the following group names. Knock automatically allocates the matching role to users in that group.
| Group name | Role |
| --------------------------------- | ---------------------- |
| knock-role-owner | owner |
| knock-role-admin | admin |
| knock-role-member | member |
| knock-role-production_only_member | production_only_member |
| knock-role-billing | billing |
| knock-role-support | support |
### Custom permission groups
If your account uses [custom permission groups](/manage-your-account/roles-and-permissions#custom-permission-groups), directory sync can assign those groups as well.
Create a group in your identity provider named `knock-role-{key}`, where `{key}` is the permission group's key. For example, a group named `knock-role-engineering` maps to a custom permission group with the key `engineering`.
You can also include a custom permission group key in the custom mapping you send to Knock support. For example, mapping `"Engineering"` to `"engineering"` assigns that custom permission group to every member of the Engineering identity provider group.
Built-in role names always take precedence over a custom permission group with the same key. Avoid using a permission group key that matches a built-in role (`owner`, `admin`, `member`, `production_only_member`, `billing`, `support`). If you create a custom group whose key is `admin`, `knock-role-admin` still maps to the built-in admin role.
Missing or archived custom permission groups are ignored at sync time. If no live custom group remains, Knock falls back to the highest-privilege mapped built-in role, or to the support role if none is mapped.
## How Knock assigns roles
Knock resolves each user's assignment from their identity provider group memberships:
1. **Custom permission groups.** A user can belong to more than one identity provider group. If any of those memberships map to live custom permission groups, Knock assigns the **Custom** role and the combined permissions of every matching group. This takes precedence over the owner and admin roles. A member cannot have both a built-in role and custom permission groups.
2. **Highest-privilege built-in role.** If no live custom permission group matches, Knock assigns the highest-privilege mapped built-in role. See [roles and permissions](/manage-your-account/roles-and-permissions) for more details.
3. **No mapped group.** If a user does not belong to any mapped group, Knock assigns the **support** role.
## Preventing account lockout
Because Knock uses your identity provider as the source of truth, role changes coming from your identity provider are applied even when they would remove or demote your last account owner. As a result, it's possible to end up with an account that has no owner — for example, if the only user mapped to the `owner` role is removed from your directory (or from the `knock-role-owner` group).
To avoid losing owner access, make sure at least one person is always
mapped to the owner role — via the{" "}
knock-role-owner group or your custom group-to-role mapping —
and is not removed from your identity provider. If a live custom
permission group mapping also matches that user, the custom assignment
wins and re-adding knock-role-owner does not restore owner
access. See{" "}
custom permission groups and owner access
{" "}
for how to recover, or contact the{" "}
Knock support team.
}
/>
### Custom permission groups and owner access
If a user belongs to both an owner-granting group and a group that maps to a live custom permission group, the custom assignment wins. Re-adding the user to `knock-role-owner` does not restore the owner role while that custom mapping still matches.
To restore the owner role, do one of the following:
- **Remove the custom group memberships.** Remove the user from the identity provider groups that map to custom permission groups.
- **Archive the permission group.** Archive the custom permission group in Knock so Knock ignores it at sync time.
Then keep the user in `knock-role-owner` or in a group that your custom mapping assigns to `owner`.
## Frequently asked questions
Knock will identify existing users based on their email, and update (i.e. overwrite) their access and roles based on the user data synced from your identity provider.
Any users that exist in Knock but not in identity providers will retain access to Knock and retain its role originally assigned to them.
If directory sync connection becomes disabled, all users and roles will be left in the state at the time of disconnection and stop syncing from your identity provider.
Yes, please contact the [Knock support team](mailto:support@knock.app) to configure a custom mapping. Values can be a built-in role or a custom permission group key. You cannot override Knock's default `knock-role-{key}` mapping.
Yes. Use a group named `knock-role-{key}` in your identity provider, where `{key}` matches the custom permission group's key, or include that key in the custom mapping you send to Knock support. If one or more memberships map to live custom permission groups, Knock assigns the Custom role and the combined permissions of every matching group. This takes precedence over the owner and admin roles. Custom permission groups are available on the [Enterprise plan](/manage-your-account/knock-plans). Learn more in [custom permission groups](/manage-your-account/roles-and-permissions#custom-permission-groups).
Yes, you can still invite users to Knock from the Knock dashboard, but keep in mind that users created via directory sync will take precedence. This means if you invite a user who is managed via directory sync, the user's role will be updated to reflect the state of your identity provider. Once you enable directory sync, Knock uses your identity provider as the source-of-truth for any users synced via SCIM.
## Managing members
Learn how to invite, manage, and remove members on your Knock account.
---
title: Managing account members
description: Learn how to invite, manage, and remove members on your Knock account.
tags:
[
"team",
"team members",
"account members",
"invites",
"inviting",
"auto join",
"auto-join",
]
section: Manage your account
---
## Overview
People with access to your Knock account are called members. Each member has a [role](/manage-your-account/roles-and-permissions) that determines what they can do in your account. Only account owners and admins can invite, manage, and remove members.
Account owners and admins will find the **Members** page in the Knock dashboard's settings:
## Adding members
### Inviting members
You can invite new members to your account by selecting the "New member" button on the **Members** page. Members are always invited via their email address and must be assigned [a role](/manage-your-account/roles-and-permissions). On Enterprise plans, you can assign one or more [custom permission groups](/manage-your-account/roles-and-permissions#custom-permission-groups) instead of a built-in role. You can optionally include a message that will appear in the invitation email.
The member will be sent a reminder email if the invite is not accepted within 3 days. Account invites will automatically expire after 2 weeks.
An example invitation email inviting a user to a Knock account
### Managing invitations
Once you invite a user to your Knock account, their invitation appears as a "pending invite" on the **Members** page until they accept. You can revoke pending invitations, which marks the invite as invalid and expires it immediately.
Once you revoke an invitation for a user, you can reinvite them by following the same "New member" process. This will generate a new invitation for the user to join your account.
### Enabling auto-join
You can enable auto-join on your account to let users that belong to your domain automatically join your account when signing up for Knock. This is helpful for cases where people from your organization sign up for Knock on their own without realizing your account already exists.
You can enable auto-join on the **Security** page under the **Admin** section of your account settings in your Knock dashboard.
#### Selecting approved domains
When you enable auto-join, you'll need to select which domains can auto-join your account. For security reasons, we only let you select non-public domains that belong to the owners of your account.
This means that you cannot enable auto-join for public domains (such as gmail.com). Additionally, before you can add a new domain to auto-join, someone with an email address from that domain must have an [owner role](/manage-your-account/roles-and-permissions) on your account.
#### Setting a default role
When you enable auto-join, new users are assigned the `member` role by default. You can change the default auto-join role to `admin`, `member`, or `support`.
If you want to assign a different role to someone from your domain, send them an invitation as usual. The role assigned in the invitation takes precedence over the auto-join default.
## Managing members
The following restrictions apply when managing members:
- Members can't change their own roles.
- Members can't remove themselves from a Knock account.
- Accounts must have at least one `owner` at all times.
### Updating member roles
Account members with appropriate [permissions](/manage-your-account/roles-and-permissions) can update the roles of others by selecting "Change role" from the three-dot menu. You can switch a member between a built-in role and custom permission groups, or update which custom groups they belong to. The change takes effect immediately.
If the member is managed by [directory sync](/manage-your-account/directory-sync), Knock overwrites their role and custom permission groups based on their identity provider group memberships. Dashboard role changes for those users do not persist across the next sync.
### Removing members
Members with appropriate [permissions](/manage-your-account/roles-and-permissions) can remove other members from an account by clicking the "Remove member" option found in the three-dot menu. Removing a member will revoke their access to Knock and immediately invalidate any session associated with the member. The removed member will receive an email informing them of the change in account access.
## Roles and permissions
Learn about roles, permissions, and custom permission groups in Knock.
---
title: Roles and permissions
description: Learn about roles, permissions, and custom permission groups in Knock.
tags:
[
"team",
"team members",
"account members",
"invites",
"inviting",
"permission groups",
"custom roles",
]
section: Manage your account
---
## Overview
Knock uses an account-level roles model, where a given account member's role determines what they'll be able to do in your account.
You set an account member's role when you invite them to the Knock dashboard. You can update their role on the **Members** page under the **Admin** section of your account settings. Learn more in our [managing members documentation](/manage-your-account/managing-members).
Knock provides a set of built-in roles for common team functions.
Here's an overview of the built-in roles available to Knock account members:
- **Owner.** For your primary admin who manages billing. This role can invite and manage members, manage billing, and do anything available in the admin role. Your account must always have at least one account owner.
- **Admin.** For admins who need to manage account-level settings. This role can invite and manage members (excluding owner and billing roles), manage account branding, manage environments, and manage advanced developer concepts such as signing keys, enhanced security mode, variables, and webhooks. This role has all permissions available to the member role.
- **Member.** For users who are editing notification workflows and templates in Knock. This role can manage workflows, layouts, users, objects, and tenants. It can make commits and push changes to subsequent environments, and has full access to message and API logs for debugging.
- **Production-only Member.** Available when production write access is enabled in your account settings. For team members who should only work in production (such as lifecycle marketers managing in-app announcements). This role has the same permissions as the member role, but only has access to the production environment.
- **Support.** For users who shouldn't have access to workflows and templates, but should be able to dig into message and API logs for debugging purposes.
- **Billing.** For account members who shouldn't have access to anything in Knock but billing.
For a complete overview of which permissions are available to which built-in roles, see the [lookup table](#roles-and-permissions-lookup-table) below.
## Custom permission groups
Custom permission groups are only available on our{" "}
Enterprise plan.
}
/>
Custom permission groups enable you to define your own roles with specific capabilities. Create and manage them under **Settings** > **Permissions**.
When you create a permission group, you set a unique **key** (lowercase letters, numbers, underscores, and hyphens). The key cannot be changed after creation. [Directory sync](/manage-your-account/directory-sync#custom-permission-groups) uses this key to map identity provider groups to the permission group.
### Capabilities
When you create a permission group, you choose which capabilities members in that group receive. Capabilities fall into two scopes:
- **Account.** Settings and resources that apply across the whole account, such as members, billing, integrations, and API keys.
- **Environment.** Resources that live in an environment, such as workflows, guides, content, broadcasts, audiences, recipient data, observability, and release management.
Most capabilities support none, view, and manage. Release management uses a different set of levels:
- **None.** No commit or promotion access in that environment.
- **Commit.** Commit changes in that environment.
- **Manage.** Commit and promote changes between environments.
### Environment access
For environment-scoped capabilities, you control both what members can do and which environments they can access:
1. **Same access in every environment.** Apply one set of environment capabilities across development, production, and any additional environments.
2. **Per-environment access.** Use granular mode to set different capability levels in each environment. For example, grant manage access to workflows in development, and view-only access in production.
3. **No access to an environment.** Deny an environment to hide it from members in the group and block all environment-scoped permissions there, including on its branches. Account-level capabilities still apply. At least one environment must remain accessible.
### Customer data obfuscation
Custom permission groups can enable [customer data obfuscation](/manage-your-account/data-obfuscation) under environment access. When enabled, all message, user, and object data will be obfuscated in the Knock dashboard for members of that group.
You set the rule in the same all or granular mode you use for environment capabilities:
1. **Same access in every environment.** Enable obfuscation once to apply it across every environment.
2. **Per-environment access.** Use granular mode to enable obfuscation in specific environments.
A group's rule for a parent environment also applies to that environment's branches.
If a member belongs to more than one custom permission group, Knock hides customer data when any assigned group enables obfuscation for that environment.
If customer data obfuscation has been enabled at the environment level, that setting applies to every member and cannot be overridden by a permission group. Built-in roles have no per-role obfuscation setting. Only the environment setting applies to them.
### Assigning permission groups
You assign custom permission groups when you [invite a member](/manage-your-account/managing-members) or change their role. You can also add members from a permission group's detail page, or assign groups through [directory sync](/manage-your-account/directory-sync#custom-permission-groups).
- Choose either a built-in role **or** one or more custom permission groups. You cannot combine a built-in role with custom groups on the same member.
- When you assign custom groups, the member's role becomes **Custom**. Their effective permissions are the union of every assigned group.
- An environment is accessible to a custom member if any of their assigned groups grants access to it.
- When [directory sync](/manage-your-account/directory-sync) is enabled, Knock uses your identity provider as the source of truth for synced users. If a synced user belongs to any group that maps to a live custom permission group, that custom assignment replaces their built-in role, including owner and admin.
Archiving a custom permission group removes its grants from any members who had it assigned. If that was their only group, they keep the Custom role and have no permissions until you assign another group or a built-in role. Knock does not fall back to the support role.
For directory-synced users, Knock recomputes the assignment when you archive a mapped group. Those users fall back to their highest-privilege mapped built-in role, or to support if none is mapped.
## Roles and permissions lookup table
## Audit logs
Learn more about audit logs of actions performed on your Knock account.
---
title: Audit logs
description: Learn more about audit logs of actions performed on your Knock account.
tags: ["audit", "audit log", "access log", "security"]
section: Manage your account
---
Search your account's audit log to review member actions and events.
## Overview
See the{" "}
data retention docs for
more details on how Knock enforces this policy.
}
/>
The account audit log lets you review actions performed by individual members of the account. In addition, each audit log includes events detailing who performed the action, when it happened, and information about the originating IP address and location of the action.
**Note**: accessing an account's audit log is restricted to admins and account owners.
## Review your account audit log
You can review your account audit log under your Knock account settings: `dashboard.knock.app//settings/audit-log` where the `slug` is your account identifier (e.g. `foo-corp`).
Once there, you can filter the audit log by the **Actor** who performed the action, and/or the type of **Action** performed.
## Frequently asked questions
When events occur that do not originate from a user action (like a side
effect as the result of a merge), we attribute these events to a
Knock-created "Migration Bot."
Please contact the [Knock support team](mailto:support@knock.app) if you
need to export the data inside your audit logs. We'd be happy to assist.
## Data obfuscation
Learn more about how to protect your customer's production data in the Knock dashboard.
---
title: Customer data obfuscation
description: Learn more about how to protect your customer's production data in the Knock dashboard.
tags: ["privacy", "data controls", "security", "privacy controls"]
section: Manage your account
---
Enable customer data obfuscation at the environment level, or through custom permission groups on Enterprise plans, to determine what data your team members can see in the Knock dashboard.
## Overview
When you choose Knock to power your notifications, you're also choosing to trust us with your customer data and the data you pass in your notifications. This is why [security](/security) is a foundational priority for us at Knock, and it's also why we built our customer data obfuscation controls.
With customer data obfuscation controls, the Knock dashboard automatically hides any data that might contain either user PII or customer proprietary data. This means that the only data your team members will see in the Knock dashboard is anonymous data such as UUIDs. Customer data obfuscation is managed via our backend, so users won't be able to get at this data through their browser consoles.
You can enable customer data obfuscation in two ways:
- **Environment-level.** Hide customer data for every team member in a given [environment](/concepts/environments). Use this to obfuscate production data while keeping development data visible for testing and debugging.
- **Permission group.** On Enterprise plans, hide customer data for members of a [custom permission group](/manage-your-account/roles-and-permissions#custom-permission-groups), either in every environment or in specific environments.
## Environment-level obfuscation
Environment-level obfuscation applies to every member in that environment, including members with built-in roles. Built-in roles have no per-role obfuscation setting.
To enable customer data obfuscation for an environment, go to the **Environments** page under the **Version control** section of your account settings in the Knock dashboard. Select the "..." for the environment you'd like to configure and click "Edit environment."
## Per-member role obfuscation
Permission group data obfuscation is only available on our{" "}
Enterprise plan.
}
/>
Custom permission groups can enable customer data obfuscation under environment access. When enabled, all message, user, and object data will be obfuscated in the Knock dashboard for members of that group.
Create and manage permission groups under **Settings** > **Permissions**. You set the obfuscation rule in the same editor you use for environment capabilities:
1. **Same access in every environment.** Enable obfuscation once to apply it across development, production, and any additional environments.
2. **Per-environment access.** Use granular mode to enable obfuscation in specific environments. For example, hide customer data in production for a support group, and leave it visible in development.
A group's obfuscation rule for a parent environment also applies to that environment's branches.
If a member belongs to more than one custom permission group, Knock hides customer data when any assigned group enables obfuscation for that environment. Learn more in our [roles and permissions documentation](/manage-your-account/roles-and-permissions#customer-data-obfuscation).
## Precedence
If customer data obfuscation is enabled at the environment level, that setting applies to every member in the environment. A permission group cannot turn environment-level obfuscation off or reveal data the environment already hides.
A permission group can only add obfuscation. When the environment setting is off, the group's rule determines whether members of that group see customer data in that environment.
## Account timezone
Learn how to set the default timezone for your account.
---
title: Account timezone
description: Learn how to set the default timezone for your account.
tags: ["default timezone", "recipient timezone"]
section: Manage your account
---
## Overview
You can set a default timezone for your account by navigating to the **General** page under your account settings and selecting a timezone.
The account timezone will be used as a fallback for [send windows](/designing-workflows/send-windows) and [schedules](/concepts/schedules) if the recipient does not have a timezone set. If no account timezone is set, Knock falls back to `Etc/UTC`.
## Data retention
How Knock enforces data retention policies on your account.
---
title: Data retention
description: How Knock enforces data retention policies on your account.
tags: ["data", "retention"]
section: Manage your account
---
Knock applies a retention policy to some of the data within your account. Once data exceeds its retention period, it will no longer be accessible in the Knock Dashboard, the Management API, or the public API. Knock will eventually prune data that has aged out of its retention period.
## Data retention policies
If custom retention windows are critical to your usage of Knock, please
click the "Contact support" button at the top of this page to reach our
support team.
}
/>
Some Knock data is subject to a retention policy based on your account plan. These policies are:
- **Enterprise plans**: 90 days
- **All other plans**: 30 days
Knock applies this plan-based retention policy to the following data:
- [Audit logs](/manage-your-account/audit-logs)
- [Message log data](/concepts/messages)
- [Outbound webhook delivery logs](/developer-tools/outbound-webhooks/overview#reading-webhook-delivery-logs)
- [Source event and action logs](/integrations/sources/overview#logging)
- [Workflow run logs](/send-notifications/debugging-workflows#accessing-the-workflow-debugger)
Additionally, Knock applies a universal, 30-day retention policy to the following data:
- [API logs](/developer-tools/api-logs)
## Message log data retention details
Message log data subject to your account's retention policy includes both the message log itself and associated metadata, including:
- Message contents
- Message events
- Delivery logs
- Activities
However, this does not mean that the associated notification has been completely removed from Knock's systems. Your recipients can still interact with these older notifications, and you can still take some specific actions on them.
1. **In-app feed notifications are available indefinitely.** Even after your message log data has expired, you can still fetch the associated `FeedItem` data from the [Show feed endpoint](/api-reference/users/feeds/list_items) to deliver in-app notifications to your recipients. You can also still use the [message status update endpoints](/api-reference/messages/) to update the status of these feed items. These status updates will still generate new message events and trigger your [outbound webhooks](/developer-tools/outbound-webhooks/overview), even though you will not be able to view the message in the Knock Dashboard any longer.
2. **Tracking behavior will persist.** Your recipients can still click [tracked-links](/send-notifications/tracking#link-click-tracking).
## Custom domains
Learn more about how to configure custom domains for your Knock account to use for link tracking, email open tracking, and the hosted preference center.
---
title: Custom domains
description: Learn more about how to configure custom domains for your Knock account to use for link tracking, email open tracking, and the hosted preference center.
tags:
["custom domains", "domains", "email", "email tracking", "preference center"]
section: Manage your account
---
Knock supports setting up custom domains for your account to use for [link tracking](/send-notifications/tracking#how-it-works) (including short links in SMS and WhatsApp), [email open tracking](/send-notifications/tracking#email-open-tracking), and the [hosted preference center](/preferences/hosted-preference-center).
Setting a custom domain is important for deliverability and branding. You run the risk of having your messages marked as spam if the sending domain and the domain you're routing to for links are different.
By default, Knock uses [a variety of domains](/send-notifications/tracking#link-click-tracking-domains) for link tracking, short links in SMS and WhatsApp, and email open tracking. We also use the `p.knock.app` domain for the hosted preference center. These domains are shared across all accounts and are not configurable. Custom domains enable you to override these defaults and use your own domains.
## Setting up a custom domain
We recommend using a subdomain of an existing domain with established
email reputation (e.g., link.yourcompany.com) as a custom
domain. If using a brand new domain, consider warming it first to build
reputation and avoid deliverability issues.
Please note that
we do not currently support apex domains
(e.g., yourcompany.com) as custom domains. You must
use a subdomain.
}
/>
To set up a custom domain, navigate to the **Domains** page under the **Account** section of your Knock dashboard settings.
Click "Add domain" under the tracking link or preference center section, depending on what you'd like to configure.
You'll be prompted to enter the domain you want to use, such as `link.yourcompany.com` or `prefs.yourcompany.com`. Click "Continue to verification."
A subdomain used for the preference center cannot also be used for
tracked links, and vice versa.
}
/>
Before you can complete the setup process, you'll need to navigate to your domain registrar and add a CNAME record to the DNS configuration for your domain. The setup modal in your Knock dashboard will display the CNAME record you need to add.
The CNAME target depends on how you plan to use the domain:
- **Link tracking, short links, and open tracking.** Point the CNAME record to `cname.knock.app`.
- **Preference center.** Point the CNAME record to `prefs-cname.knock.app`.
Here are some DNS configuration instructions for common providers:
Once you've added the CNAME record, click "Check verification" to verify that the domain's DNS records are pointing to the correct value. Please note that it can take up to 48 hours for the DNS changes to propagate, so you may need to come back later and try again if verification does not succeed immediately.
Once the domain is verified, you'll assign it to one or more [environments](/concepts/environments). You can assign the same custom domain to multiple environments, or you can use different custom domains across environments for testing purposes.
For tracking links only, you will also need to select where the domain is used. Choose the relevant option(s) from the list of use cases:
- **Link tracking.** These are links used for tracking link clicks within your notifications. Link tracking is used across many different channels, including email, in-app feed, SMS, and WhatsApp.
- **Short links.** These are links used for generating tracked short links in SMS and WhatsApp messages.
- **Open tracking.** These are links used for generating a 1x1 transparent tracking pixel, currently used only within email notifications.
Once you've selected where the domain is used, click "Apply and activate" to save your changes. Assignment changes take effect immediately for both tracked link and preference center domains.
## Custom domains for the preference center
When a custom preference center domain is assigned to an environment, any `{{vars.manage_preferences_url}}` variables in your templates will automatically use your custom domain instead of `p.knock.app`.
Each environment can have at most one custom preference center domain. The same custom preference center domain can be assigned to multiple environments. To switch an environment to a different domain, verify the new domain and assign it. The previous domain will be automatically unassigned.
## When assignment changes take effect
Assignment changes take effect immediately for both tracked link and preference center domains. New messages will use the currently-assigned custom domains for that environment. Already-sent messages are not affected. Links in already-sent messages continue to work as long as the domain they used (whether a default Knock domain or a previously assigned custom domain) remains verified in Knock and its DNS CNAME record stays intact.
## Rolling out your custom domains
We strongly advise that you test out your custom domains in a
non-production environment before rolling them out to your production
environment.
}
/>
When you're ready to roll out your custom domains to production, assign the custom domain to your production environment.
## Frequently asked questions
Please check that the CNAME record is pointing to the correct value. You can
also try to verify the domain again by clicking the "Check verification"
button. It can take up to 48 hours for DNS changes on your domain to
propagate. If after 48 hours the domain is still not verified, please reach
out to our support team at
[support@knock.app](mailto:support@knock.app?subject=Custom%20domain%20verification%20issue).
Yes, you can use a brand new domain. However, we recommend that you warm up
the domain before using it for production traffic so that it has a good
reputation.
No. Links in already-sent messages that used default Knock domains (for both
tracked links and the preference center) continue to work after you set a
custom domain.
No, as long as the domain still exists in Knock and the DNS CNAME record is
intact. Links stop working only if you delete the domain in Knock or modify
the DNS record.
Yes. Verify the new domain and assign it to the environment. The previous
domain will be unassigned automatically. Links in already-sent messages will
continue to work if that domain still exists in Knock and the DNS CNAME
record is intact.
No. [Commercial unsubscribe](/preferences/commercial-unsubscribe) works
independently and is not affected by preference center custom domain
configuration.
## Managing assets
Learn how to upload and manage assets for use in your notification templates.
---
title: Managing assets
description: Learn how to upload and manage assets for use in your notification templates.
tags: ["assets", "images", "uploads", "templates"]
section: Manage your account
---
## Overview
Assets are files that you upload to Knock for use in your notification templates. You can upload images to be hosted by Knock and reference them via URL in your templates. This is useful for including logos, icons, and other visual elements in your notifications.
Account owners, admins, and members can manage assets from the **Assets** page in the Knock dashboard's settings.
## Uploading assets
To upload a new asset:
1. Navigate to **Content** > **Assets** in your dashboard sidebar.
2. Click the "Upload image" button.
3. Select an image file from your computer.
### File requirements
Keep the following requirements in mind when uploading assets:
- **File size.** Each image must be 2 MB or less.
- **File type.** Currently, only image files are supported (e.g., PNG, JPEG, GIF, SVG).
You can upload as many images as you need to your Knock account.
## Using assets in templates
Once you've uploaded an asset, you can copy its URL and use it in your notification templates. To copy the URL:
1. Navigate to **Content** > **Assets** in the Knock dashboard.
2. Find the asset you want to use.
3. Click the copy button to copy the asset URL to your clipboard.
You can then paste this URL into your notification templates wherever you need to reference the image, such as in email templates or in-app notifications.
## Deleting assets
To delete an asset:
1. Navigate to **Content** > **Assets** in the Knock dashboard.
2. Find the asset you want to delete.
3. Click the delete button to remove the asset.
If you delete an asset that is referenced in a notification template, the
image will no longer be displayed. Make sure to update any templates that
reference an asset before deleting it.
}
/>
## Frequently asked questions
Currently, only image files are supported. This includes common formats like
PNG, JPEG, GIF, and SVG. In the future, we may support additional asset
types.
There is no limit to the number of assets you can upload to your Knock
account.
Each image file must be 2 MB or less.
Account owners, admins, and members can upload and manage assets.
## Knock plans
Understand differences between Knock plans and how usage is metered.
---
title: "Knock plans and usage"
description: "Understand differences between Knock plans and how usage is metered."
tags:
[
"billing",
"pricing",
"plans",
"enterprise",
"usage",
"sandbox mode",
"accounts",
]
section: Manage your account
---
Knock offers a free Developer plan and two paid plans, Starter and Enterprise. Most features are available across all three plans, with a small set reserved for Enterprise customers only. See our pricing page for current pricing, included volumes, and a feature comparison.
## Enterprise features
Teams choose the Enterprise plan for higher message volume, multi-tenancy and security controls, and compliance requirements that call for a HIPAA business associate agreement (BAA).
The following features are reserved for the Enterprise plan:
- [Per-tenant preferences](/multi-tenancy/per-tenant-preferences) and [branding](/multi-tenancy/per-tenant-branding)
- [Per-tenant guides](/in-app-ui/guides/create-guides)
- [Translations (i18n)](/template-editor/translations)
- [Batch render limits beyond 10 items](/designing-workflows/batch-function#setting-the-batch-render-limit-beyond-10)
- [Custom permission groups](/manage-your-account/roles-and-permissions)
- [SAML SSO](/manage-your-account/saml-sso)
- [Directory sync](/manage-your-account/directory-sync)
- [Data warehouse sync](/integrations/extensions/data-sync)
- [Datadog](/integrations/extensions/datadog), [New Relic](/integrations/extensions/new-relic), [Segment](/integrations/extensions/segment), and [Heap](/integrations/extensions/heap) extensions
## How Knock meters usage
Knock plans vary in terms of usage models: notification-based plans meter usage on messages sent, while recipient-based plans meter usage based on monthly notified recipients. Regardless of plan, usage may be accrued in any Knock [environment](/version-control/environments).
### Message counts
A message is counted each time a notification is successfully delivered to a single user on a single channel. A workflow that notifies a user by both email and in-app results in two messages. If a channel step is not executed, there is no associated message. A channel step may be skipped due to user preferences, missing data, or other workflow logic.
Due to the nature of [guides](/concepts/guides), guides usage is metered separately and based on active guides users. A user is considered an active guides user if they have received at least one guide in a given month.
### Non-production usage
While using Knock, you'll often send messages in non-production environments to test changes. To avoid unexpected usage from testing, we recommend using [sandbox mode](/integrations/overview#sandbox-mode) or setting [channel conditions](/integrations/overview#channel-conditions) in your non-production environments.
#### Sandbox mode
When a channel is in sandbox mode, Knock does not pass messages downstream for delivery. Sandboxed messages are rendered for preview in the Knock dashboard, but do not count toward usage.
Enable sandbox mode in a channel's configuration to apply it across an environment, or use the workflow [test runner's sandbox setting](/send-notifications/testing-workflows#test-run-settings) to apply it for a single run, regardless of how the channel itself is configured.
#### Channel conditions
Channel conditions enable you to scope a channel's delivery to specific conditions per environment. For example, you might set a condition on your email channel to restrict sending to recipients on your own domain while in a non-production environment. Unlike sandbox mode, channel conditions gate delivery selectively rather than suppress it entirely. Any message that satisfies a channel condition may contribute to usage.
## Managing multiple accounts
Most customers need only one Knock account. As you map your resources into Knock, there are two ways to think about separating data within a single account:
- **[Environments](/version-control/environments)** isolate your development lifecycle, from development through production.
- **[Tenants](/multi-tenancy/overview)** scope notifications, branding, and preferences to your own customers, brands, or business units.
Some customers maintain separate Knock accounts under a single Enterprise agreement, often for fully distinct products or business units, or when they need independent account-level data, members, and authentication.
Each Knock account is independent: its resources, members, and analytics are scoped to that account, and no configuration is shared between accounts. Accounts can be synchronized programmatically via the [Management API](/developer-tools/management-api), but Knock does not provide any automatic synchronization between separate accounts.
## Frequently asked questions
{/* prettier-ignore */}
Dashboard users with billing permissions can review current usage under **Settings** > **Billing** in your Knock dashboard. See the pricing page for details about pricing and included usage per plan, or contact support with questions about your plan or invoice.
Yes. You can use Knock's APIs to work with [tenant](/multi-tenancy/overview)
data and trigger workflow runs for specific tenants on any plan. However,
per-tenant preferences, branding, translations, and guides are gated to the
Enterprise plan.
The in-app channel doesn't support sandbox mode. Knock manages in-app
delivery, so there's no downstream provider handoff to suppress. Use
[channel conditions](/integrations/overview#channel-conditions) to manage
when messages are created for in-app steps in your non-production
environments.
The guides channel does not support sandbox mode. To manage usage, use
audience-limiting [targeting
rules](/in-app-ui/guides/create-guides#targeting) while testing in
non-production environments.
## Account deletion
Learn how to permanently delete your Knock account and what happens to your data.
---
title: Account deletion
description: Learn how to permanently delete your Knock account and what happens to your data.
tags: ["account", "deletion", "delete"]
section: Manage your account
---
## Overview
Account owners can permanently delete their Knock account from the dashboard. This action is irreversible. Once you delete your account, all data associated with it is permanently removed and cannot be recovered.
## Before you delete
Consider the following before deleting your account:
- **Production workflows.** Deactivate or migrate any production workflows that are still sending notifications. Deleting your account will immediately stop all notification delivery.
- **API keys.** All API keys will be revoked immediately. Any applications or services using these keys will lose access to Knock.
- **Account members.** All [account members](/manage-your-account/managing-members) will lose access. They will receive an email informing them that the account has been deleted.
- **Integrations.** Any active channel integrations (email, push, chat, SMS) will stop working.
- **Billing.** If you are on a paid plan, cancel your subscription before deleting your account.
## Data deletion
When you delete your account, Knock permanently removes all data associated with it:
- **Account data.** Workflows, templates, layouts, assets, branding, and environment configuration
- **Recipient data.** Users, objects, tenants, and all associated data
- **Message history and logs.** Message logs, API logs, workflow run logs, and audit logs
For context on how Knock handles data during normal operation, see [data retention](/manage-your-account/data-retention).
## Account member deletion
All members are removed from the account when it is deleted. Each member receives an email informing them that the account has been deleted. Learn more about [managing account members](/manage-your-account/managing-members).
## How to delete your account
1. Open your account settings in the Knock dashboard.
2. Navigate to the **General** section.
3. Find the **Delete account** option and follow the prompts to confirm.
4. Enter your account slug to confirm the deletion.
5. Confirm the deletion. Your account and all associated data will be permanently removed after 24 hours.
---
# Overview
Learn more about the integrations that Knock supports to send notifications and receive events. Send notifications to Email, SMS, Push, and Chat apps like Slack with a single API call and trigger them via events from your customer data platforms.
---
title: Integrations overview
description: Learn more about the integrations that Knock supports to send notifications and receive events. Send notifications to Email, SMS, Push, and Chat apps like Slack with a single API call and trigger them via events from your customer data platforms.
tags:
[
"sandbox mode",
"sandbox",
"channel conditions",
"channel groups",
"multiple providers",
"change providers",
"new domain",
]
layout: integrations
Section: Integrations
---
You can use Knock to power sophisticated cross-channel notification workflows for your end users, triggered by your application or by events sent to Knock from various customer data platforms (CDPs) like Segment and RudderStack.
## Destination channels
We support the following channel types today:
- [Email](/integrations/email/overview) (such as Sendgrid, Postmark)
- [In-app](/integrations/in-app/overview) (such as feeds and toasts)
- [In-app guide](/in-app-ui/guides/overview) (such as banners, modals, and other in-product messaging)
- [Push](/integrations/push/overview) (such as APNs, FCM)
- [SMS](/integrations/sms/overview) (such as Twilio, Telnyx)
- [Chat](/integrations/chat/overview) (such as Slack, Microsoft Teams, and Discord)
- [Webhook](/integrations/webhook/overview) (send webhooks to custom channels or enable your own customers to configure webhooks in your product)
See a full list of supported channel providers.
## Source integrations
Sources connect external services to Knock so that events from those services can trigger workflows, identify users, and manage objects and tenants. Knock supports three categories of source integrations:
- **Incoming webhooks.** Receive events from services like [Stripe](/integrations/sources/stripe), [Clerk](/integrations/sources/clerk), [WorkOS](/integrations/sources/workos), [PostHog](/integrations/sources/posthog), and [Supabase](/integrations/sources/supabase), or create a [custom source](/integrations/sources/custom) for any webhook provider.
- **CDP integrations.** Forward `track` and `identify` events from platforms like [Segment](/integrations/sources/segment), [RudderStack](/integrations/sources/rudderstack), [Freshpaint](/integrations/sources/freshpaint), and [Jitsu](/integrations/sources/jitsu).
- **Reverse ETL integrations.** Sync warehouse data from platforms like [Hightouch](/integrations/sources/hightouch), [Census](/integrations/sources/census), and [Polytomic](/integrations/sources/polytomic).
See the [sources overview](/integrations/sources/overview) for configuration details, available actions, and debugging information.
## Platform extensions
Knock can also integrate with other tools for debugging, monitoring, and more, including the following:
- [Datadog](/integrations/extensions/datadog)/[New Relic](/integrations/extensions/new-relic). Receive Knock platform metrics for workflow & channel successes and errors.
- [Segment](/integrations/extensions/segment)/[Heap](/integrations/extensions/heap). Send Knock notification events to downstream analytics tools.
- [Vercel](/integrations/extensions/vercel). Synchronize your Knock API keys to one or more Vercel projects.
## Per environment configurations
Unlike most parts of the Knock model, your integrations live at the account-level. This means that when you create a new integration in Knock (say, SendGrid), you only have to create it once.
Once an integration is created, you can then configure it for each of your environments. There are a couple reasons we enable per-environment configuration for each.
- If you use different instances of a service for each of your environments, you can use the respective API key or destination webhook URL of each within your different Knock environments.
- You can provide environment-level config details to your channels. A common example is to add the suffix "(dev)" to the "From name" on all emails sent in your development environment.
If you want to use the exact same configuration for a given channel across all environments, you can use the "Copy from" button to duplicate your configuration across environments.
## Sandbox mode
Sometimes you don't want a message to be sent in a local or testing environment, but you _do_ want the ability to debug your messages and see what might have gone out.
Sandbox mode enables you to generate and preview messages for a given channel without delivering them. When sandbox is enabled, Knock will never send the request to your downstream provider, blocking all delivery. To gate delivery selectively rather than suppress it entirely, use channel conditions instead.
Sandbox mode is supported across all channel types (except for in-app) and can be enabled from the environment configuration view of a channel.
## Channel conditions
You can use channel conditions to place a [condition](/concepts/conditions) on all instances of a channel within a given environment. As an example, if you want to ensure that your email channel only sends to recipients from your domain when it's executing in your staging environment, a channel-level condition would be great way to do that.
To add a condition to a channel's environment configuration, navigate to **Channels and sources** in your dashboard account settings, click on the channel you'd like to update, then click "Manage configuration" next to the relevant environment. Select "Conditions" in the modal that is opened.
Managing channel conditions in Knock.
Knock will execute your channel conditions for every step using the given channel across all your workflow runs. Knock will join these channel conditions with any [step conditions](/designing-workflows/step-conditions) via an `AND`, meaning both channel and step conditions will need to pass evaluation for the step to execute. You can then use Knock's [conditions debugger](/concepts/conditions#debugging-conditions) to examine the evaluations of your channel conditions.
## Channel groups
A channel group enables you to combine multiple channels of the same type into a single workflow step, using one notification template across all providers in the group. These are commonly used to combine push channels: instead of maintaining a separate channel step and template for APNs and FCM in every workflow, create a push channel group holding both connections and add it to your workflows as one push step.
You can create and manage channel groups with the{" "}
Management API. Dashboard
support will soon be available. For help configuring a channel group,
reach out to us at{" "}
support@knock.app.
}
/>
### Channel group settings
Every channel group has a `key` that identifies it, along with these settings:
| Field | Description |
| --------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name` | The human-readable name of the group. |
| `channel_type` | The type of channels the group contains, such as `email`, `sms`, `push`, `chat`, or `http`. Every channel in a group shares this type. |
| `operator` | Determines how many matching rules will result in message routing: `any` or `all`. When set to `any`, Knock routes to the first matching rule's channel only. When set to `all`, Knock routes to every matching rule's channel. Defaults to `any`. |
| `channel_rules` | The ordered list of rules that determine which of the group's channels Knock routes to. |
| `visible_in` | Where the group appears as a step destination: `workflow`, `broadcast`, or both. Defaults to both. |
### Channel rules
Each rule in `channel_rules` points to one of the group's channels and sets the terms under which Knock routes to it:
| Field | Description |
| ------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `index` | The rule's position in the group's ordered list. |
| `channel_key` | The key of the channel the rule routes to. |
| `rule_type` | Determines when the channel should be used: `always`, `if`, or `unless`. When set to `always`, Knock routes to the channel on every workflow run. When set to `if` or `unless`, Knock routes to the channel conditionally based on the values of `variable`, `operator`, and `argument`. |
| `variable` | The workflow property to evaluate. Not applicable for `always` rules. |
| `operator` | The comparison to apply between the variable and the argument. Accepts any of the condition operators, plus `is_in_random_cohort` for percentage-based cohort routing. Not applicable for `always` rules. |
| `argument` | The value to compare the variable against. Not applicable for `always` rules. |
### Random cohorts
Random cohorts route recipients by percentage rather than by evaluating a property of the workflow run. Instead of making decisions based on who the recipient is, Knock assigns each recipient to a cohort and routes a percentage of them to a given channel. Splitting traffic this way enables you to shift volume to a new provider gradually rather than all at once. See our [sender domain migration tutorial](/tutorials/sender-domain-migration) for guidance on how to use cohort routing to warm a new email sending domain.
A cohort rule takes the following values:
| Field | Value |
| ----------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `rule_type` | `if` |
| `variable` | `recipient.id` |
| `operator` | `is_in_random_cohort` |
| `argument` | The cohort threshold, as a number from 0 to 100 with up to one decimal place, such as `12.5`. With a single cohort rule, this is the percentage of recipients routed to this channel. |
Knock hashes the recipient ID against the channel group to assign the cohort, so a given recipient consistently routes to the same channel across workflow runs.
A single cohort rule only determines routing for the recipients inside that cohort, so it should be paired with at least one additional rule to catch remaining recipients. Set the channel group's `operator` to `any` so that messages are routed to only the first matching rule. To route the remaining recipients, create an `always` rule pointing at the fallback channel. The fallback rule should be ordered after the cohort rule, so that only recipients not belonging to the cohort will reach it. With this configuration, Knock routes the cohort to the first channel and everyone else to the second.
#### Using more than one cohort
To route traffic across more than two channels, add a cohort rule for each one. Every cohort rule in a group hashes against the same channel group, so each recipient holds a single position that all of the group's cohort rules compare against. Percentages act as cumulative thresholds rather than independent shares: a rule routes the recipients below its percentage that the rules ahead of it didn't already take.
Order your cohort rules from the smallest percentage to the largest, and end the group with an `always` rule:
| Rule | `argument` | Recipients routed |
| ----------------------------------- | ---------- | ----------------- |
| Cohort rule pointing at channel A | `12` | The first 12% |
| Cohort rule pointing at channel B | `42` | The next 30% |
| `always` rule pointing at channel C | — | The remaining 58% |
Set each percentage to the running total of the shares ahead of it. Channel B receives 30% of recipients because its rule is set to `42`: the 12% already routed to channel A, plus its own 30%. Ordering a larger percentage ahead of a smaller one would prevent the smaller rule from ever matching, since every recipient below the smaller percentage is also below the larger one.
## Supported providers
Find supported integration providers listed by channel type: [Email](/integrations/email/overview#supported-providers), [Chat](/integrations/chat/overview#supported-providers), [In-app](/integrations/in-app/overview#supported-providers), [Push](/integrations/push/overview#supported-providers), and [SMS](/integrations/sms/overview#supported-providers). We're continuously adding new providers, so if you don't see your provider listed, please reach out to us at [support@knock.app](mailto:support@knock.app).
# Sources
## Overview
Learn how to connect external services to Knock using incoming webhooks, CDPs, or reverse ETL integrations.
---
title: Sources in Knock
description: Learn how to connect external services to Knock using incoming webhooks, CDPs, or reverse ETL integrations.
metaTitle: Source integrations overview
metaDescription: Connect external services to Knock using incoming webhooks, CDPs like Segment, or reverse ETL tools like Hightouch and Census.
section: Integrations > Sources
layout: integrations
---
Sources connect external services to Knock so that events from those services can drive actions such as triggering workflows, identifying users, and managing objects and tenants.
Knock supports three categories of source integrations:
- **Incoming webhooks.** Receive events from services like Stripe, Clerk, and WorkOS. Pre-built templates handle payload verification and provide default action mappings, or create a [custom source](/integrations/sources/custom) for any webhook provider.
- **CDP integrations.** Forward `track` and `identify` events from platforms like Segment and RudderStack to trigger workflows and keep recipient data in sync.
- **Reverse ETL integrations.** Sync warehouse data from platforms like Hightouch and Census to keep users, objects, and tenants up to date.
## Available sources
- [Amplitude](/integrations/sources/amplitude)
- [Census](/integrations/sources/census)
- [Clay](/integrations/sources/clay)
- [Clerk](/integrations/sources/clerk)
- [Custom source](/integrations/sources/custom)
- [Freshpaint](/integrations/sources/freshpaint)
- [Hightouch](/integrations/sources/hightouch)
- [Jitsu](/integrations/sources/jitsu)
- [Polytomic](/integrations/sources/polytomic)
- [PostHog](/integrations/sources/posthog)
- [RudderStack](/integrations/sources/rudderstack)
- [Segment](/integrations/sources/segment)
- [Stripe](/integrations/sources/stripe)
- [Supabase](/integrations/sources/supabase)
- [WorkOS](/integrations/sources/workos)
If you want us to add a new source to this list, please let us know at [support@knock.app](mailto:support@knock.app?subject=Integration%20Source%20Request).
## Configuring sources
You can configure sources from the **Platform** > **Sources** page in your Knock dashboard. Initial creation of a source is managed at the account level of your Knock account, though you configure specific events and their actions within your Knock environments.
### Per-environment source configuration
Each source has a unique configuration for every Knock environment in your account. This makes it possible to connect your development source environment to your Knock development environment. Use the environment dropdown in the top header to switch between environments and view their configurations.
## Triggering actions from source events
When a source event is received, you can configure Knock to execute any of the following actions:
| Action | Description |
| ---------------------- | ---------------------------------------------------------------------- |
| Trigger workflow | Start a [workflow](/concepts/workflows) run for one or more recipients |
| Cancel workflow | Cancel an in-progress workflow run |
| Identify user | Create or update a [user](/concepts/users) in Knock |
| Subscribe user | Add a user to an [object's subscribers list](/concepts/subscriptions) |
| Unsubscribe user | Remove a user from an object's subscribers list |
| Set object | Create or update an [object](/concepts/objects) |
| Delete object | Remove an object |
| Set tenant | Create or update a [tenant](/concepts/tenants) |
| Delete tenant | Remove a tenant |
| Add audience member | Add a member to an [audience](/concepts/audiences) |
| Remove audience member | Remove a member from an audience |
### Event-to-action mapping
After events start flowing into Knock you can configure mappings that tell Knock which action to run and how to populate its parameters. Mappings use dot-notation paths to extract values from the incoming payload and map them to the fields required by each action.
For example, a Stripe `invoice.paid` event includes nested data about the invoice and customer:
```json
{
"type": "invoice.paid",
"data": {
"object": {
"id": "in_1abc123",
"customer": "cus_abc123",
"customer_email": "jane@example.com",
"amount_due": 4999,
"currency": "usd",
"subscription": "sub_xyz789"
}
}
}
```
You could map `data.object.customer` to the `recipients` field and `data.object` to the `data` field when triggering a workflow, giving your templates access to the invoice amount, currency, and subscription details.
### Execution order for multiple mappings
If a single event type has multiple action mappings, Knock executes them in a fixed priority order based on action type, not the order in which you create mappings in the dashboard.
1. `users_identify`
2. `users_delete`
3. `objects_set`
4. `objects_delete`
5. `tenants_set`
6. `tenants_delete`
7. `objects_subscribe`
8. `objects_unsubscribe`
9. `audiences_add_member`
10. `audiences_remove_member`
11. `workflows_trigger`
This ordering is consistent across incoming webhook sources, including custom sources.
For full details on configuring custom event types and field mappings, see the [custom source page](/integrations/sources/custom).
## Debugging source events
In some cases, you may need to debug source event connections to ensure your integration is sending the correct payloads to Knock.
See the{" "}
data retention docs for
more details on how Knock enforces this policy.
}
/>
#### Event logs
Event logs show the contents of each event sent into Knock.
#### Action logs
Action logs describe what (if any) action Knock took after receiving an event. Action logs are a helpful starting point when troubleshooting workflows or auditing actions Knock has taken for any given event.
## Source event idempotency
By default, Knock processes every valid event received from your source. You can enable idempotency checks to deduplicate events that have already been received and processed. This is useful if you know your source may send duplicate events.
If you're interested in configuring a different idempotency window for
your account, please contact us at{" "}
support@knock.app.
}
/>
Idempotency configuration varies by source type. For pre-built webhook integrations, Knock auto-configures the idempotency key. For CDP sources and custom webhooks, you may need to enable idempotency and verify the key field. See your individual source page for setup details.
### Key validation
Your idempotency keys must be valid strings no more than 255 characters in length. If an invalid key is found, Knock still ingests your source event but will not attempt to execute your event idempotently. In addition, Knock drops the invalid idempotency key and you will not see it appear in your event logs.
### How Knock handles idempotent events
When Knock executes a source event with an idempotency key, it first checks whether a preceding execution should be replayed. Knock finds a preceding execution if it is recorded within the idempotency window with the same:
- Idempotency key value
- Event type
- Integration source configuration
- Knock environment in your account
If no preceding execution is found, Knock executes your event normally and records that execution for future replay by the same idempotency key. However, if Knock fails to execute your source event, it will not record the execution. Knock only records successful event executions for idempotent replay.
If Knock replays an event via an idempotency check, you will still see an event log for that execution. However, the log will not have any actions associated and Knock will label it as idempotent.
## Clerk
Receive Clerk webhook events in Knock to trigger workflows and automate actions based on authentication and user management events.
---
title: Clerk source
description: Receive Clerk webhook events in Knock to trigger workflows and automate actions based on authentication and user management events.
metaTitle: Clerk source integration
metaDescription: Connect Clerk webhooks to Knock to trigger notification workflows from user sign-ups, session events, and organization changes.
section: Integrations > Sources
layout: integrations
---
The Clerk source enables you to receive Clerk webhook events directly in Knock. Clerk sends webhook callbacks when events occur in your application, such as a new user signing up, a session being created, or an organization being updated. Knock verifies each payload using your Clerk webhook signing secret, identifies the event type, and executes the actions you configure.
This integration is useful for building notifications around user lifecycle events: triggering welcome workflows when users sign up, notifying admins about organization changes, or syncing user data into Knock when profile details are updated.
Knock supports ingesting any of Clerk's supported events, so you can map them to actions as your needs evolve.
## Prerequisites
- A Knock account with at least one [environment](/concepts/environments) configured.
- A Clerk application with access to the Webhooks settings in the Clerk dashboard.
## Getting started
Navigate to **Platform** > **Sources** in the Knock dashboard. Make sure
you're in the correct environment. Select the
**Clerk** template as the source type.
Once you've selected **Clerk** as a source, you can select your desired action mappings. These are helpful defaults to get you started, but Knock can ingest any event Clerk sends and you can adjust your mappings at any time. Click the **Connect Clerk** button to continue.
After creating the source, copy the webhook URL from the setup wizard for the environment you want to configure.
In the Clerk dashboard, navigate to
**Configure > Webhooks** and click "Add endpoint." Paste the Knock webhook URL and
select the events you want Clerk to send.
After creating the endpoint in Clerk, Clerk provides a signing secret. Copy
this value and paste it into the **Signing secret** field in your Knock
source environment configuration.
Once configured, Clerk sends webhook events to Knock in real time. You can verify that events are arriving by checking the event logs on the source environment page.
## Pre-configured events
Clerk sends events for user, session, and organization lifecycle changes. Below are common events you might map to actions in Knock. You can enable or disable individual event types from the source environment configuration.
| Event type | Description |
| ---------------------- | --------------------------------- |
| `user.created` | A new user signed up |
| `user.updated` | User profile details were updated |
| `user.deleted` | A user was deleted |
| `organization.created` | A new organization was created |
| `organization.updated` | Organization details were updated |
See the Clerk webhook events documentation for the full list of available events.
## Customization
You can modify the default action mappings or add new ones for any event type Knock receives from Clerk. For details on how field mapping works with dot-notation paths, see the [custom source](/integrations/sources/custom) page.
If a single event type maps to multiple actions, Knock executes those actions in a fixed order. See [execution order for multiple mappings](/integrations/sources/overview#execution-order-for-multiple-mappings).
If you need to map Clerk events to actions beyond triggering workflows, see the full list of [available actions](/integrations/sources/overview#triggering-actions-from-source-events) in the sources overview.
## Event idempotency
Knock automatically configures idempotency for the Clerk source so duplicate events are not processed twice. By default, Knock uses `headers.svix-id` from the Clerk webhook payload as the idempotency key.
You can change the idempotency key field or disable idempotency checks from the **Settings** tab in your source environment configuration. Events without an idempotency key attribute are processed normally.
For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## PostHog
Receive PostHog webhook events in Knock to trigger workflows and automate actions based on product analytics events.
---
title: PostHog source
description: Receive PostHog webhook events in Knock to trigger workflows and automate actions based on product analytics events.
metaTitle: PostHog source integration
metaDescription: Connect PostHog webhooks to Knock to trigger notification workflows from product analytics actions and custom events.
section: Integrations > Sources
layout: integrations
---
The PostHog source enables you to receive PostHog webhook events directly in Knock. PostHog sends webhook callbacks when actions fire in your product analytics, such as a user completing a key funnel step, a feature flag change, or a custom event you define. Knock verifies each payload, identifies the event type, and executes the actions you configure.
This integration is useful for building notifications triggered by product behavior: reaching out to users who complete onboarding milestones, alerting your team when a feature flag is changed, or triggering re-engagement workflows based on usage patterns.
Knock supports ingesting any of PostHog's supported events, so you can map them to actions as your needs evolve.
## Prerequisites
- A Knock account with at least one [environment](/concepts/environments) configured.
- A PostHog project with access to the Webhooks settings in the PostHog app.
## Getting started
Navigate to **Platform** > **Sources** in the Knock dashboard. Make sure
you're in the correct environment. Select the
**PostHog** template as the source type.
Once you've selected **PostHog** as a source, you can select your desired action mappings. The defaults map PostHog events like `$identify` and `$set` to identify users in Knock. These are helpful defaults to get you started, but Knock can ingest any event PostHog sends and you can adjust your mappings at any time. Click the **Connect PostHog** button to continue.
After creating the source, copy the event ingestion URL from the setup wizard. You will paste this into PostHog in the next steps.
In PostHog, navigate to **Data pipelines** and click **New destination**. Search for "Knock" and click **Create** on the Knock destination.
On the Knock destination configuration page, paste the Knock event ingestion URL into the **Knock.app webhook destination URL** field. Set the **User ID** field to the property that maps to your Knock user IDs (for example, `{person.id}`). You can optionally configure filters to limit which events are sent, add event matchers to target specific actions, and set up attribute mappings. When ready, click **Create & enable**.
Once configured, PostHog sends events to Knock based on your destination filters and event matchers. You can verify that events are arriving by checking the event logs on the source environment page.
## Pre-configured events
PostHog webhook events are driven by the actions and events you configure in your PostHog project. Common scenarios include:
| Event type | Description |
| -------------------- | ------------------------------------------------------------------------------------------------------ |
| Action webhooks | Fired when a PostHog action matches (for example, a user clicks a specific button or views a key page) |
| Custom events | Fired when your application sends a custom event to PostHog that matches your webhook criteria |
| Feature flag changes | Fired when a feature flag is updated |
The exact event types depend on how you configure your PostHog actions and webhook destinations. See the PostHog events documentation for more details on available event types and payload formats.
## Customization
You can modify the default action mappings or add new ones for any event type Knock receives from PostHog. For details on how field mapping works with dot-notation paths, see the [custom source](/integrations/sources/custom) page.
If a single event type maps to multiple actions, Knock executes those actions in a fixed order. See [execution order for multiple mappings](/integrations/sources/overview#execution-order-for-multiple-mappings).
If you need to map PostHog events to actions beyond triggering workflows, see the full list of [available actions](/integrations/sources/overview#triggering-actions-from-source-events) in the sources overview.
## Event idempotency
Knock automatically configures idempotency for the PostHog source so duplicate events are not processed twice. By default, Knock uses `body.messageId` from the PostHog webhook payload as the idempotency key.
You can change the idempotency key field or disable idempotency checks from the **Settings** tab in your source environment configuration. Events without an idempotency key attribute are processed normally.
For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## Stripe
Receive Stripe webhook events in Knock to trigger workflows and automate actions based on payment and subscription lifecycle events.
---
title: Stripe source
description: Receive Stripe webhook events in Knock to trigger workflows and automate actions based on payment and subscription lifecycle events.
metaTitle: Stripe source integration
metaDescription: Connect Stripe webhooks to Knock to trigger notification workflows from payment, subscription, and customer lifecycle events.
section: Integrations > Sources
layout: integrations
---
The Stripe source enables you to receive Stripe webhook events directly in Knock. Stripe sends webhook callbacks when events occur in your account, such as a successful payment, a subscription change, or a customer update. Knock verifies each payload using your Stripe webhook signing secret, identifies the event type, and executes the actions you configure.
This integration is useful for building notifications around payment lifecycle events: alerting customers about successful charges, notifying your team about failed payments, or triggering onboarding workflows when new customers are created.
Knock supports ingesting any of Stripe's supported events, so you can map them to actions as your needs evolve.
## Prerequisites
- A Knock account with at least one [environment](/concepts/environments) configured.
- A Stripe account with access to the Webhooks settings in the Stripe dashboard.
## Getting started
Navigate to **Platform** > **Sources** in the Knock dashboard. Make sure
you're in the correct environment. Select the
**Stripe** template as the source type.
Once you've selected **Stripe** as a source, you can select your desired action mappings. The defaults map common Stripe events like `customer.created` to identify users and `invoice.created` and `invoice.paid` to trigger workflows. These are helpful defaults to get you started, but Knock can ingest any event Stripe sends and you can adjust your mappings at any time. Click the **Connect Stripe** button to continue.
After creating the source, copy the event ingestion URL from the setup wizard. You will paste this into the Stripe dashboard in the next steps.
In the Stripe dashboard, click the **Developers** button in the bottom left corner of the sidebar to open the Workbench.
In the Workbench, click the **Webhooks** tab. Click **Add destination** to start creating a new webhook endpoint.
In the "Create an event destination" wizard, select **Your account** as the event source. Search for and select the events you want to send to Knock (for example, `customer.created`). Click **Continue** to proceed.
Select **Webhook endpoint** as the destination type and click **Continue**.
Give the destination a name (for example, "Knock"), paste the Knock event ingestion URL you copied earlier into the **Endpoint URL** field, and click **Create destination**.
After creating the destination, Stripe displays the destination detail page with a **Signing secret** (starts with `whsec_`). Copy this value and paste it into the **Signing secret** field in your Knock source environment configuration.
Once configured, Stripe sends webhook events to Knock in real time. You can verify that events are arriving by checking the event logs on the source environment page.
## Testing with the Stripe CLI
The Stripe Workbench includes a built-in Shell that you can use to send test events to your webhook endpoint. Use the `stripe trigger` command followed by the event name to generate a test event:
```bash
stripe trigger customer.created
stripe trigger customer.subscription.trial_will_end
```
This creates the necessary fixture data in your Stripe sandbox and sends the corresponding webhook event to all configured destinations, including Knock.
## Pre-configured events
Stripe sends a wide range of event types. Below are common events you might map to actions in Knock. You can enable or disable individual event types from the source environment configuration.
| Event type | Description |
| ------------------ | ---------------------------- |
| `invoice.paid` | An invoice payment succeeded |
| `invoice.created` | An invoice was created |
| `customer.created` | A new customer was created |
See the Stripe event types documentation for the full list of available events.
## Customization
You can modify the default action mappings or add new ones for any event type Knock receives from Stripe. For details on how field mapping works with dot-notation paths, see the [custom source](/integrations/sources/custom) page.
If a single event type maps to multiple actions, Knock executes those actions in a fixed order. See [execution order for multiple mappings](/integrations/sources/overview#execution-order-for-multiple-mappings).
If you need to map Stripe events to actions beyond triggering workflows, see the full list of [available actions](/integrations/sources/overview#triggering-actions-from-source-events) in the sources overview.
## Event idempotency
Knock automatically configures idempotency for the Stripe source so duplicate events are not processed twice. By default, Knock uses `body.id` from the Stripe webhook payload as the idempotency key.
You can change the idempotency key field or disable idempotency checks from the **Settings** tab in your source environment configuration. Events without an idempotency key attribute are processed normally.
For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## Supabase
Receive Supabase database webhook events in Knock to trigger workflows and automate actions based on row-level changes.
---
title: Supabase source
description: Receive Supabase database webhook events in Knock to trigger workflows and automate actions based on row-level changes.
metaTitle: Supabase source integration
metaDescription: Connect Supabase database webhooks to Knock to trigger notification workflows from row-level insert, update, and delete events.
section: Integrations > Sources
layout: integrations
---
The Supabase source enables you to receive Supabase database webhook events directly in Knock. Supabase sends webhook callbacks when row-level changes occur in your database tables, such as inserts, updates, or deletes. Knock identifies the event type and executes the actions you configure.
This integration is useful for building notifications that react to database changes: alerting users when a record relevant to them is created, triggering workflows when data is updated, or automating cleanup actions when rows are deleted.
Knock pre-processes each Supabase webhook to compile the schema, table, and operation into a unique event type (for example, `auth.users:INSERT`), so you can create targeted action mappings for any table and operation combination.
Supabase database webhooks do not include a signing secret or built-in
payload verification mechanism. Any request that reaches your Knock
webhook URL will be accepted. Consider restricting access at the network
level or validating payloads in your workflow logic if this is a concern.
}
/>
## Prerequisites
- A Knock account with at least one [environment](/concepts/environments) configured.
- A Supabase project with access to the Database Webhooks settings in the Supabase dashboard.
## Getting started
Navigate to **Platform** > **Sources** in the Knock dashboard. Make sure
you're in the correct environment. Select the
**Supabase** template as the source type.
Once you've selected **Supabase** as a source, you can select your desired action mappings. The default mappings use Supabase table events like `auth.users:INSERT` to identify users in Knock. These are helpful defaults to get you started, but Knock can ingest any event Supabase sends and you can adjust your mappings at any time. Click the **Connect Supabase** button to continue.
After creating the source, copy the event ingestion URL from the setup wizard. You will paste this into the Supabase dashboard in the next steps.
In the Supabase dashboard, select your project and navigate to **Integrations** > **Database Webhooks**. Click the **Webhooks** tab, then click **Create a new hook**.
In the webhook creation form, give the webhook a name and select the table you want to monitor (for example, `auth.users`). Under **Events**, check the operations you want to trigger notifications for: **Insert**, **Update**, and **Delete**. Under **Type of webhook**, select **HTTP Request**.
In the **HTTP Request** section, set the method to **POST** and paste the Knock event ingestion URL you copied earlier into the **URL** field. You can optionally add custom HTTP headers. Click **Create webhook** to finish.
Once configured, Supabase sends webhook events to Knock when the specified database changes occur. You can verify that events are arriving by checking the event logs on the source environment page.
## Pre-configured events
Supabase database webhooks fire based on the table operations you select when creating the hook. Knock pre-processes each incoming payload to compile the schema, table name, and operation type into a single event type using the format `{schema}.{table}:{operation}`. This enables you to create specific action mappings for each table and operation combination.
| Event type | Description |
| ------------------- | ---------------------------------------- |
| `auth.users:INSERT` | A new row was inserted into `auth.users` |
| `auth.users:UPDATE` | A row in `auth.users` was updated |
| `auth.users:DELETE` | A row was deleted from `auth.users` |
The exact event types depend on which tables and operations you configure in your Supabase database webhooks. Each event payload includes the row data (both old and new values for updates). See the Supabase database webhooks documentation for payload structure details. For more on how Knock pre-processes incoming payloads, see the [pre-processing](/integrations/sources/custom#preprocessing) section of the custom source page.
## Customization
You can modify the default action mappings or add new ones for any event type Knock receives from Supabase. For details on how field mapping works with dot-notation paths, see the [custom source](/integrations/sources/custom) page.
If a single event type maps to multiple actions, Knock executes those actions in a fixed order. See [execution order for multiple mappings](/integrations/sources/overview#execution-order-for-multiple-mappings).
If you need to map Supabase events to actions beyond triggering workflows, see the full list of [available actions](/integrations/sources/overview#triggering-actions-from-source-events) in the sources overview.
## Event idempotency
Supabase database webhooks do not include a built-in idempotency key. You can enable idempotency checks and configure a key field from the **Settings** tab in your source environment configuration if your payload contains a unique identifier you want to use for deduplication. Events without an idempotency key attribute are processed normally.
For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## Amplitude
Send Amplitude events, user updates, and cohort membership changes to Knock to trigger workflows and keep users and audiences in sync.
---
title: Amplitude source
description: Send Amplitude events, user updates, and cohort membership changes to Knock to trigger workflows and keep users and audiences in sync.
metaTitle: Amplitude source integration
metaDescription: Connect Amplitude Webhooks Streaming and Cohort Webhooks to Knock to trigger workflows, identify users, and sync cohort membership to audiences.
section: Integrations > Sources
layout: integrations
---
The Amplitude source enables you to send analytics events, user updates, and cohort membership changes from [Amplitude](https://amplitude.com) to Knock. Knock receives Amplitude's default webhook payloads, verifies a shared secret, identifies the incoming event type, and runs the actions you configure.
You can connect either or both of Amplitude's outbound webhook integrations to the same Knock source URL:
- [Webhooks Streaming](https://amplitude.com/docs/data/destination-catalog/webhooks) sends product events and user property updates as Amplitude ingests them.
- [Cohort Webhooks](https://amplitude.com/docs/data/destination-catalog/cohort-webhooks) sends batches when users enter or exit an Amplitude cohort.
Use these integrations to trigger notification workflows from product behavior, keep Knock user properties aligned with Amplitude, or use an Amplitude cohort as a [Knock audience](/concepts/audiences).
## How verification works
Amplitude supports custom headers but does not sign Webhooks Streaming or Cohort Webhook requests. The Knock source verifies a shared secret sent as a Bearer token in the `Authorization` header:
```text
Authorization: Bearer
```
The signing secret in Knock must match the token configured in every Amplitude destination that sends data to the source. Treat the secret like an API key, store it somewhere safe, and rotate it if it leaks.
## Prerequisites
- A Knock account with at least one [environment](/concepts/environments) configured.
- An Amplitude project with access to **Data** > **Catalog** > **Destinations**.
- A paid Amplitude plan if you want to use Cohort Webhooks.
## Set up the source in Knock
Navigate to **Platform** > **Sources** in the Knock dashboard. Make sure
you're in the correct environment, then select the **Amplitude** template.
The template includes mappings that identify users and add or remove cohort
members from Knock audiences. You can select which mappings to create and
change them later. Click **Connect Amplitude** to continue.
Copy the event ingestion URL from the setup wizard for the environment you
want to configure. Both Amplitude webhook integrations can send to this URL.
Generate a strong random string, such as with `openssl rand -hex 32`, and
paste it into the **Signing secret** field in the Knock source environment.
You will use the same value in the `Authorization` header in Amplitude.
## Send events and users with Webhooks Streaming
Use Amplitude's **Webhook: Events · User Properties** destination to stream product events and user profile updates to Knock in real time. This destination sends data as Amplitude ingests it; it does not backfill events that Amplitude received before you enabled the destination.
In Amplitude, navigate to **Data** > **Destinations**, then click **Add Destination**. Search for
"Webhook," select **Webhook: Events · User Properties**, enter a sync name,
and click **Create Sync**.
Paste the Knock event ingestion URL into the webhook URL field. Add a custom header
named `Authorization` with the value `Bearer `, using
the secret you set in Knock.
Under **Send Events**, enable **Events are sent to Webhook**. Keep the
default Amplitude event payload, then select and filter the events you want
Knock to receive. Each event retains its Amplitude `event_type`, so you can
add a Knock action mapping for any event you send.
Under **Send Users**, enable **User updates are sent to Webhook** if you want to
identify users in Knock. Keep the default Amplitude user payload. Amplitude
sends a user payload when it receives an event and when it receives an
[Identify API](https://amplitude.com/docs/apis/analytics/identify) call.
Finally, set the destination status to **Enabled** and click **Save**. Send a matching event
or Identify API update, then check the **Logs** tab on the Knock source
environment to confirm delivery.
An event payload includes fields such as `event_type`, `user_id`, `event_properties`, `groups`, and a unique `uuid`:
```json
{
"user_id": "user_123",
"uuid": "bf0b9b2a-304d-11e6-934f-22000b56058f",
"event_type": "Order Completed",
"event_time": "2026-07-23T16:20:30.123Z",
"event_properties": {
"order_id": "order_789",
"total": 149.99
},
"groups": {
"workspace": "workspace_123"
}
}
```
User payloads do not include `event_type`, so Knock normalizes them to `$identify`.
## Sync cohorts with Cohort Webhooks
Cohort Webhooks send batched membership changes to Knock. Knock maps entry batches to `cohort.entered` and exit batches to `cohort.exited`.
In Amplitude, open **Data** > **Destinations**, then click **Add Destination**. Search for
"Webhook," select **Webhook: Cohorts**. Enter a display name,
and click **Create Sync**.In the **Cohorts**
section, select **Webhook** and create a destination.
Enter a display name. Then, paste the same Knock event ingestion URL into the webhook URL field. Add a custom
`Authorization` header with the value `Bearer `, and
keep the default Amplitude cohort payload. Then click **Save**.
Open the cohort you want to export, click **Sync**, choose **Webhook**, and
select the destination you created. You can include up to 50 user
properties in the payload. Choose a one-time, recurring (hourly or daily),
or real-time sync, then click **Sync**.
Amplitude supports [three cohort sync behaviors](https://amplitude.com/docs/data/destinations/syncs):
| Cadence | Behavior |
| --------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| One-time | Sends the cohort membership once. Use this for a one-off campaign or test. |
| Hourly or daily | Recalculates the cohort on a schedule and sends membership additions and removals. |
| Real-time | Sends the initial cohort population, then checks for entry and exit changes every minute. The initial population can take longer for a large cohort. |
Amplitude sends cohort updates in batches with a unique `message_id`:
```json
{
"cohort_name": "Highly engaged users",
"cohort_id": "cohort_123",
"in_cohort": true,
"computed_time": "1784823900",
"message_id": "message_123",
"users": [{ "user_id": "user_123" }, { "user_id": "user_456" }]
}
```
## Default action mappings
The Amplitude template includes these mappings:
| Event type | Knock action | Default behavior |
| ---------------- | ----------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `$identify` | Identify user | Uses `user_id`, falling back to `device_id`, as the Knock user ID. Maps `user_properties.name`, `user_properties.email`, and the full `user_properties` object. |
| `cohort.entered` | Add audience members | Adds every user in the batch to the audience keyed `amplitude-`. Creates the audience if it does not exist. |
| `cohort.exited` | Remove audience members | Removes every user in the batch from the audience keyed `amplitude-`. |
The cohort name can change in Amplitude, so Knock uses the stable `cohort_id` when it constructs the audience key. Cohort membership payloads must include Amplitude `user_id` values to map members to Knock users.
### Align user identities
Set Amplitude `user_id` to the same stable identifier you use as the Knock user ID. This keeps product events, user updates, cohort membership, and workflow recipients attached to the same Knock user. See Amplitude's [user identity documentation](https://amplitude.com/docs/get-started/identify-users) for its identity model and user ID recommendations.
Amplitude can send an Identify payload with only a `device_id`. In that case, the default mapping creates or updates a Knock user keyed by that device ID. Knock does not merge that recipient with a later recipient keyed by Amplitude `user_id`, so use Amplitude `user_id` for signed-in users whenever possible.
## Map product events to workflows
Knock preserves the `event_type` for each streamed product event. After an event arrives, open the source's **Mappings** tab, select the event type, and create an action mapping.
For the `Order Completed` example above, you could configure a **Trigger workflow** action with these fields:
| Action field | Payload path |
| ----------------- | ------------------------------------ |
| Workflow | Select your order-completed workflow |
| Recipients | `body.user_id` |
| Data | `body.event_properties` |
| Tenant (optional) | `body.groups.workspace` |
This triggers the selected workflow for the Amplitude user and makes properties such as `order_id` and `total` available in the workflow's templates. If your events can be device-only, choose a field that always resolves to a Knock user ID or normalize the recipient in the source preprocessing script.
## Map Amplitude groups to objects or tenants
Amplitude group types and Knock [object collections](/concepts/objects) are customer-defined. The Amplitude template does not assume that a group such as `workspace`, `account`, or `project` should become a particular object collection or [tenant](/concepts/tenants).
For an event with `groups.workspace` and `group_properties.workspace`, you can [customize the Amplitude webhook payload](https://amplitude.com/docs/data/destination-catalog/webhooks#freemarker-templating-language) to include the Knock collection name, then add a **Set object** mapping:
```json
{
"object_collection": "workspaces",
"groups": { "workspace": "workspace_123" },
"group_properties": {
"workspace": {
"name": "Acme Corp",
"plan": "enterprise"
}
}
}
```
| Set object field | Payload path |
| ----------------- | -------------------------------------- |
| Collection | `body.object_collection` |
| Object ID | `body.groups.workspace` |
| Name | `body.group_properties.workspace.name` |
| Custom properties | `body.group_properties.workspace` |
If your Amplitude group represents a Knock tenant instead, create a **Set tenant** mapping with `body.groups.workspace` as the tenant ID and `body.group_properties.workspace` as its properties. Adjust every path and collection name to match your Amplitude taxonomy and Knock data model.
## Retries and idempotency
Amplitude [retries failed event and user deliveries](https://amplitude.com/docs/data/destination-catalog/webhooks#amplitudes-retry-mechanism) nine times over four hours after the first attempt. It also retries `5xx` and `429` responses within each attempt. Cohort Webhooks can retry timed-out batches, which can produce duplicate deliveries.
Knock configures idempotency for the Amplitude source using:
- `body.uuid` for streamed product events.
- `body.message_id` for cohort batches.
- A combination of the user or device ID and `body.event_time` for user updates.
Knock ignores a duplicate while its idempotency key remains in the source's idempotency window. You can change this behavior from the **Settings** tab. See [source event idempotency](/integrations/sources/overview#source-event-idempotency) for the window and key rules.
## Debugging
Open **Platform** > **Sources**, select the Amplitude source, and use its **Logs** tab to inspect received events and the actions they produced.
Common issues include:
- **Verification failed.** Confirm that Amplitude sends `Authorization: Bearer ` and that the token matches the signing secret in the current Knock environment.
- **No events arrive.** Confirm that the Amplitude destination is enabled and that the event matches its filters. Webhooks Streaming does not send events that Amplitude ingested before you enabled the destination.
- **An action was skipped.** Open the action log and check for a missing required field. Compare the mapping's dot-notation path with the received payload.
- **Cohort members do not match users.** Confirm that Amplitude `user_id` values match Knock user IDs and that the cohort payload includes those IDs.
You can modify the default action mappings or add mappings for any Amplitude event type. For details on field paths, preprocessing, and available actions, see the [custom source](/integrations/sources/custom) and [sources overview](/integrations/sources/overview#triggering-actions-from-source-events).
## WorkOS
Receive WorkOS webhook events in Knock to trigger workflows and automate actions based on directory sync and SSO events.
---
title: WorkOS source
description: Receive WorkOS webhook events in Knock to trigger workflows and automate actions based on directory sync and SSO events.
metaTitle: WorkOS source integration
metaDescription: Connect WorkOS webhooks to Knock to trigger notification workflows from directory sync and SSO lifecycle events.
section: Integrations > Sources
layout: integrations
---
The WorkOS source enables you to receive WorkOS webhook events directly in Knock. WorkOS sends webhook callbacks when events occur in your enterprise integrations, such as a user being provisioned via directory sync or an SSO connection being activated. Knock verifies each payload using your WorkOS webhook signing secret, identifies the event type, and executes the actions you configure.
This integration is useful for automating provisioning and access workflows: identifying users in Knock when they are provisioned through a directory, notifying admins about SSO configuration changes, or triggering onboarding workflows when new directory users appear.
Knock supports ingesting any of WorkOS's supported events, so you can map them to actions as your needs evolve.
## Prerequisites
- A Knock account with at least one [environment](/concepts/environments) configured.
- A WorkOS account with access to the Webhooks settings in the WorkOS dashboard.
## Getting started
Navigate to **Platform** > **Sources** in the Knock dashboard. Make sure
you're in the correct environment. Select the
**WorkOS** template as the source type.
Once you've selected **WorkOS** as a source, you can select your desired action mappings. These are helpful defaults to get you started, but Knock can ingest any event WorkOS sends and you can adjust your mappings at any time. Click the **Connect WorkOS** button to continue.
After creating the source, copy the webhook URL from the setup wizard for the environment you want to configure.
In the WorkOS dashboard, navigate to
**Webhooks** and click "Create webhook." Paste the Knock webhook URL and
select the events you want WorkOS to send.
After creating the endpoint in WorkOS, WorkOS provides a signing secret. Copy
this value and paste it into the **Signing secret** field in your Knock
source environment configuration.
Once configured, WorkOS sends webhook events to Knock in real time. You can verify that events are arriving by checking the event logs on the source environment page.
## Pre-configured events
WorkOS sends events for directory sync and SSO lifecycle changes. Below are common events you might map to actions in Knock. You can enable or disable individual event types from the source environment configuration.
| Event type | Description |
| -------------------------- | ----------------------------------------- |
| `dsync.user.created` | A user was provisioned via directory sync |
| `dsync.user.updated` | A directory sync user was updated |
| `dsync.user.deleted` | A directory sync user was deprovisioned |
| `dsync.group.created` | A group was created via directory sync |
| `dsync.group.updated` | A directory sync group was updated |
| `dsync.group.deleted` | A directory sync group was deleted |
| `dsync.group.user_added` | A user was added to a directory group |
| `dsync.group.user_removed` | A user was removed from a directory group |
| `connection.activated` | An SSO connection was activated |
| `connection.deactivated` | An SSO connection was deactivated |
See the WorkOS events documentation for the full list of available events.
## Customization
You can modify the default action mappings or add new ones for any event type Knock receives from WorkOS. For details on how field mapping works with dot-notation paths, see the [custom source](/integrations/sources/custom) page.
If a single event type maps to multiple actions, Knock executes those actions in a fixed order. See [execution order for multiple mappings](/integrations/sources/overview#execution-order-for-multiple-mappings).
If you need to map WorkOS events to actions beyond triggering workflows, see the full list of [available actions](/integrations/sources/overview#triggering-actions-from-source-events) in the sources overview.
## Event idempotency
Knock automatically configures idempotency for the WorkOS source so duplicate events are not processed twice. By default, Knock uses `body.id` from the WorkOS webhook payload as the idempotency key.
You can change the idempotency key field or disable idempotency checks from the **Settings** tab in your source environment configuration. Events without an idempotency key attribute are processed normally.
For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## Segment
Receive Segment webhook events in Knock to trigger workflows and keep user data in sync with track and identify events.
---
title: Segment source
description: Receive Segment webhook events in Knock to trigger workflows and keep user data in sync with track and identify events.
metaTitle: Segment source integration
metaDescription: Connect Segment webhooks to Knock to trigger notification workflows from track and identify events.
section: Integrations > Sources
layout: integrations
---
This is the updated Segment source integration. If you are looking for the
previous version that uses manual webhook destinations, see the{" "}
legacy Segment source.
}
/>
The Segment source enables you to receive Segment webhook events directly in Knock. Segment sends webhook callbacks when track and identify events flow through your workspace. Knock verifies each payload using your Segment webhook signing secret, identifies the event type, and executes the actions you configure.
This integration is useful for triggering notification workflows from track events, such as alerting users when key actions happen in your product, or syncing user data into Knock from identify events so recipient profiles stay up to date.
Knock supports ingesting any of Segment's supported events, so you can map them to actions as your needs evolve.
## Prerequisites
- A Knock account with at least one [environment](/concepts/environments) configured.
- A Segment workspace with access to webhook or destination settings.
## Getting started
Navigate to **Platform** > **Sources** in the Knock dashboard. Make sure
you're in the correct environment. Select the
**Segment** template as the source type.
Once you've selected **Segment** as a source, you can select your desired action mappings. These are helpful defaults to get you started, but Knock can ingest any event Segment sends and you can adjust your mappings at any time. Click the **Connect Segment** button to continue.
After creating the source, Knock displays a setup wizard. Copy the event ingestion URL from step 1 of the wizard. You will paste this into your Segment destination configuration in a later step.
In your Segment workspace, navigate to **Destinations** and click "Add Destination." Search for **Webhooks (Actions)** and select it. Choose the data source you want to receive events from, give the destination a name, and click "Create Destination."
In the Segment destination, navigate to the **Mappings** tab and click "New Mapping." Under Actions, click "Send." Configure the event conditions to determine which events are forwarded to Knock. For example, you can add conditions for **Event type is Track** and **Event type is Identify**, and set the top operator to **any** to send both event types.
After selecting your events, proceed to the **Map fields** step. Paste the Knock event ingestion URL you copied earlier into the **URL** field and set the **Method** to `POST`.
Unlike other webhook providers, Segment does not auto-generate a signing secret. You need to generate your own secret and enter it in both Segment and Knock.
In your Segment destination, navigate to the **Settings** tab. Enter your generated secret in the **Shared Secret** field and click "Save Changes."
Then, back in Knock, paste the same secret into the **Signing secret** field in step 2 of the setup wizard, or in the source environment configuration under the **Settings** tab.
Once configured, Segment sends webhook events to Knock in real time. You can verify that events are arriving by checking the event logs on the source environment page.
## Pre-configured events
Segment sends events based on the Segment spec. Below are common event types you might map to actions in Knock.
| Event type | Description |
| ---------- | ----------------------------------- |
| `track` | A user performed an action |
| `identify` | User traits were created or updated |
See the Segment spec documentation for the full list of available event types and their schemas.
## Customization
You can modify the default action mappings or add new ones for any event type Knock receives from Segment. For details on how field mapping works with dot-notation paths, see the [custom source](/integrations/sources/custom) page.
If you need to map Segment events to actions beyond triggering workflows, see the full list of [available actions](/integrations/sources/overview#triggering-actions-from-source-events) in the sources overview.
## Event idempotency
Knock uses the `messageId` field from the Segment event spec as the idempotency key. Segment includes a `messageId` in every track and identify event by default, so no additional field configuration is needed.
You can change the idempotency key field or disable idempotency checks from the **Settings** tab in your source environment configuration. Events without an idempotency key attribute are processed normally.
For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## Shopify
Receive Shopify webhook events in Knock to trigger workflows and automate actions based on customer and order lifecycle events.
---
title: Shopify source
description: Receive Shopify webhook events in Knock to trigger workflows and automate actions based on customer and order lifecycle events.
metaTitle: Shopify source integration
metaDescription: Connect Shopify webhooks to Knock to trigger notification workflows from customer and order lifecycle events in your store.
section: Integrations > Sources
layout: integrations
---
The Shopify source enables you to receive Shopify webhook events directly in Knock. Shopify sends webhook callbacks when events occur in your store, such as a new customer signing up, an order being placed, or a fulfillment being shipped. Knock verifies each payload using your Shopify webhook signing secret, identifies the event topic from the `X-Shopify-Topic` header, and executes the actions you configure.
This integration is useful for building ecommerce notifications: triggering order confirmations when customers check out, syncing Shopify customer data into Knock when profiles are created or updated, and powering downstream notifications like shipping updates or cancellation alerts as you add the topics you need.
Knock supports ingesting any of Shopify's supported webhook topics, so you can map them to actions as your needs evolve.
## Two ways to configure Shopify webhooks
Shopify supports two distinct ways to create webhooks, and Knock works with both. The payload format, headers, and signature verification are identical — only the setup path differs. Pick the option that matches how you operate your Shopify store.
### From the Shopify admin panel
A store owner adds webhook destinations manually in the Shopify admin panel under **Settings > Notifications > Webhooks**. The signing secret is displayed in that same section and is shared across every webhook on the store. This path is the best fit for merchants who run their own store and want to forward events to Knock without writing a Shopify app. [Learn more.](#send-webhooks-from-the-shopify-admin-panel)
### From a Shopify app
A Shopify app developer declares webhook subscriptions in the app's `shopify.app.toml` configuration, or creates them at runtime using the `webhookSubscriptionCreate` GraphQL mutation on the Admin API. The signing secret is the app's API client secret, so a single secret verifies webhooks from every store that installs the app. This path is the best fit for teams building a Shopify app or managing webhook subscriptions across many stores. [Learn more.](#send-webhooks-from-a-shopify-app)
Whichever path you choose, the steps for setting up the source in Knock are the same. Once the source exists in Knock, follow the section below that matches your setup.
## Prerequisites
- A Knock account with at least one [environment](/concepts/environments) configured.
- Either access to the Shopify admin panel for the store you want to ingest events from (for the admin path), or a Shopify app with permission to create webhook subscriptions on the stores you want to ingest from (for the app path).
## Set up the source in Knock
These steps are the same regardless of which Shopify path you use.
Navigate to **Platform** > **Sources** in the Knock dashboard. Make sure
you're in the correct environment. Select the
**Shopify** template as the source type.
Once you've selected **Shopify** as a source, you can select your desired action mappings. The defaults identify Knock users from `customers/create` and `customers/update` events, identify the customer attached to an `orders/create` event, and trigger an `order-confirmation` workflow for that customer. These are helpful defaults to get you started, but Knock can ingest any topic Shopify sends and you can adjust your mappings at any time. Click the **Connect Shopify** button to continue.
After creating the source, copy the webhook URL from the setup wizard for the environment you want to configure. You will use this URL as the destination for the webhooks you create in Shopify.
## Send webhooks from the Shopify admin panel
Use this path if you're a store owner and want to forward events directly from a single Shopify store without building an app.
{/* prettier-ignore */}
In the Shopify admin panel, navigate to **Settings > Notifications** and scroll to the **Webhooks** section. Click "Create webhook," paste the Knock webhook URL into the **URL** field, select the event topic you want to send (for example, `orders/create`), set the format to **JSON**, and save. Repeat this step for each topic you want to send to Knock.
After creating your first webhook, Shopify displays a **Signing secret** at
the bottom of the Webhooks section. Copy this value and paste it into the
**Signing secret** field in your Knock source environment configuration.
Shopify uses the same signing secret to sign every webhook from a given
store, so you only need to copy it once.
## Send webhooks from a Shopify app
Use this path if you're building a Shopify app and want webhook subscriptions to be installed automatically on every store the app runs on. You can declare subscriptions in your app's configuration file with the Shopify CLI, or create them at runtime with the Admin GraphQL API.
Declare your subscriptions in `shopify.app.toml` using the Shopify CLI
(3.63.0 or later). Set each subscription's `uri` to the Knock webhook URL
you copied earlier and include the topics you want to send.
```toml
# shopify.app.toml
[webhooks]
api_version = "2025-01"
[[webhooks.subscriptions]]
# Topics that match the source's pre-configured action mappings.
topics = ["customers/create", "customers/update", "orders/create"]
uri = "https://api.knock.app/v1/sources/shopify/..."
# Add additional subscriptions for any other topics you want to map in
# Knock (e.g. orders/paid, orders/fulfilled, orders/cancelled,
# customers/delete).
```
Run `shopify app deploy` to register the subscriptions with Shopify. If you'd rather create subscriptions at runtime instead of declaring them in your app config, call the `webhookSubscriptionCreate` mutation on the Admin GraphQL API and pass the Knock webhook URL as the `callbackUrl`.
See Shopify's subscribe to webhooks docs for the full subscription syntax and filtering options.
Open your app in the Shopify Partner dashboard and copy the **Client secret** from the app's API credentials page. Paste it into the **Signing secret** field in your Knock source environment configuration. Shopify uses this client secret to sign every webhook your app delivers, regardless of which store installed the app, so a single Knock source can verify events from every install.
Once configured, Shopify sends webhook events to Knock in real time. Knock verifies each payload by computing an HMAC-SHA256 of the raw request body using your signing secret and comparing it to the base64-encoded value in the `X-Shopify-Hmac-Sha256` header. You can verify that events are arriving by checking the event logs on the source environment page.
## Pre-configured events
Shopify sends events for customer and order lifecycle changes. Below are the topics Knock pre-configures with default action mappings. You can enable or disable individual topics, or add new ones, from the source environment configuration.
| Event topic | Action | Description |
| ------------------ | ------------------------------------- | ------------------------------------------------------------------------------ |
| `customers/create` | Identify user | A new customer was created in your store |
| `customers/update` | Identify user | A customer's profile details were updated |
| `orders/create` | Identify user | Identifies the order's customer in Knock before the workflow is triggered |
| `orders/create` | Trigger `order-confirmation` workflow | Triggers a workflow with the customer as the recipient and the order as `data` |
Customer events use the top-level `body.id` as the Knock user ID. The two `orders/create` mappings work together: the identify action upserts the customer from `body.customer.*` (with `body.customer.id` as the user ID) so the workflow trigger that runs right after can address that same customer as the recipient. The full Shopify order payload is sent as the workflow's trigger `data`, so your templates have access to line items, totals, shipping address, and order metadata.
To use the order mapping out of the box, create a workflow in Knock with the key `order-confirmation`. You can rename the workflow key at any time by editing the action mapping.
### Other common topics to add
Most Shopify customers extend the defaults with a few additional notification flows. Common topics worth adding as custom mappings:
| Event topic | Typical action | Description |
| ------------------ | ------------------------------------- | ------------------------------------------------------- |
| `orders/paid` | Trigger a `payment-received` workflow | An order's payment was captured |
| `orders/fulfilled` | Trigger an `order-shipped` workflow | An order was fulfilled, often with tracking information |
| `orders/cancelled` | Trigger an `order-cancelled` workflow | An order was canceled, often with associated refunds |
| `customers/delete` | Delete the user in Knock | A customer was deleted from your store |
For order topics, use `body.customer.id` as the workflow recipient and send `body` as the workflow data, matching the pattern of the pre-configured `orders/create` mapping. See the Shopify webhook topics documentation for the full list of available events.
## Customization
You can modify the default action mappings or add new ones for any topic Knock receives from Shopify. For details on how field mapping works with dot-notation paths, see the [custom source](/integrations/sources/custom) page.
Shopify puts the event topic in the `X-Shopify-Topic` HTTP header instead of the JSON body, so the Shopify source extracts the event type from `headers.x-shopify-topic`. You can reference other Shopify headers in your mappings using the same dot-notation — for example, `headers.x-shopify-shop-domain` to differentiate between stores when a single Knock environment ingests events from multiple Shopify stores or from many installs of the same Shopify app.
If a single topic maps to multiple actions, Knock executes those actions in a fixed order. See [execution order for multiple mappings](/integrations/sources/overview#execution-order-for-multiple-mappings).
If you need to map Shopify events to actions beyond triggering workflows, see the full list of [available actions](/integrations/sources/overview#triggering-actions-from-source-events) in the sources overview.
## Event idempotency
Knock automatically configures idempotency for the Shopify source so duplicate events are not processed twice. By default, Knock uses `headers.x-shopify-webhook-id` from the Shopify webhook payload as the idempotency key. Shopify generates a unique ID per webhook delivery and includes it in the `X-Shopify-Webhook-Id` header, which makes it a reliable way to deduplicate retries.
You can change the idempotency key field or disable idempotency checks from the **Settings** tab in your source environment configuration. Events without an idempotency key attribute are processed normally.
For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## RudderStack
Receive RudderStack webhook events in Knock to trigger workflows and keep user data in sync with track and identify events.
---
title: RudderStack source
description: Receive RudderStack webhook events in Knock to trigger workflows and keep user data in sync with track and identify events.
metaTitle: RudderStack source integration
metaDescription: Connect RudderStack webhooks to Knock to trigger notification workflows from track and identify events.
section: Integrations > Sources
layout: integrations
---
This is the updated RudderStack source integration. If you are looking for
the previous version that uses manual webhook destinations, see the{" "}
legacy RudderStack source
.
}
/>
The RudderStack source enables you to receive [RudderStack webhook events](https://www.rudderstack.com/docs/destinations/webhooks/webhook/) directly in Knock. RudderStack sends webhook callbacks when track and identify events flow through your workspace. Knock identifies the event type and executes the actions you configure.
This integration is useful for triggering notification workflows from track events, such as alerting users when key actions happen in your product, or syncing user data into Knock from identify events so recipient profiles stay up to date.
RudderStack webhook destinations do not generate a signing secret or
include a built-in payload verification mechanism. If you need to verify
incoming payloads, you can include a shared secret as a custom header in
your RudderStack destination configuration and use a{" "}
source script in
Knock to validate it.
}
/>
## Prerequisites
- A Knock account with at least one [environment](/concepts/environments) configured.
- A RudderStack workspace with access to destination settings.
## Getting started
Navigate to **Platform** > **Sources** in the Knock dashboard. Make sure
you're in the correct environment. Select the
**RudderStack** template as the source type.
Once you've selected **RudderStack** as a source, you can select your desired action mappings. The defaults map common RudderStack events like `identify` to identify users and `track/order_completed` to trigger workflows. You can always add additional action mappings later. Click the **Connect RudderStack** button to continue.
After creating the source, Knock displays a setup wizard. Copy the event ingestion URL from step 1 of the wizard. You will paste this into your RudderStack destination configuration in a later step.
In your RudderStack workspace, navigate to **Directory** > **Destinations** and search for "Webhook." Select the **Webhook** destination type from the results.
Give the destination a name to identify it in RudderStack, such as "Knock," and click **Continue**.
Select the RudderStack source you want to route events from. This determines which track and identify events are forwarded to Knock. Click **Continue** to proceed.
In the **Connection Settings** step, paste the Knock event ingestion URL you copied earlier into the **Webhook URL** field and set the **URL Method** to `POST`. You can also add a `content-type: application/json` header. Click **Continue** to finish creating the destination.
Once configured, RudderStack sends webhook events to Knock in real time. You can verify that events are arriving by checking the event logs on the source environment page.
## Pre-configured events
RudderStack sends events based on the [RudderStack event spec](https://www.rudderstack.com/docs/event-spec/standard-events/). Below are common event types you might map to actions in Knock.
| Event type | Description |
| ---------- | ----------------------------------- |
| `track` | A user performed an action |
| `identify` | User traits were created or updated |
See the [RudderStack event spec documentation](https://www.rudderstack.com/docs/event-spec/standard-events/) for the full list of available event types and their schemas.
## Customization
You can modify the default action mappings or add new ones for any event type Knock receives from RudderStack. For details on how field mapping works with dot-notation paths, see the [custom source](/integrations/sources/custom) page.
If you need to map RudderStack events to actions beyond triggering workflows, see the full list of [available actions](/integrations/sources/overview#triggering-actions-from-source-events) in the sources overview.
## Event idempotency
Knock uses the `messageId` field from the RudderStack event spec as the idempotency key. RudderStack includes a `messageId` in every track and identify event by default, so no additional field configuration is needed.
You can change the idempotency key field or disable idempotency checks from the **Settings** tab in your source environment configuration. Events without an idempotency key attribute are processed normally.
For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## Hightouch
Learn how to power your Knock product notifications using synced data from your data warehouse using Hightouch.
---
title: How to integrate Hightouch with Knock
description: Learn how to power your Knock product notifications using synced data from your data warehouse using Hightouch.
metaTitle: Hightouch source integration
metaDescription: Connect Hightouch to Knock to sync user, object, and tenant data from your data warehouse into Knock on a scheduled basis.
section: Integrations > Sources
layout: integrations
---
## Getting started
Knock integrates with Hightouch as a downstream destination to sync customer and event data from your data warehouse.
## Use cases
You can use our Hightouch integration to:
1. Sync customer data into Knock from your data warehouse (identify)
2. Trigger workflows from records added, changed, or removed in your data warehouse
3. Populate [Audiences](/concepts/audiences) with data from your data warehouse. Audiences can be used to trigger workflows or power conditional logic during workflow execution.
## Syncing customer data into Knock from Hightouch
You can use the HTTP request destination within Hightouch to sync your customer data from your data warehouse into Knock.
For this example, we're going to make a call to the [Knock API users identify endpoint](/api-reference/users/update).
you can also extend this technique to make other calls to the Knock API
from your Hightouch models to sync object data or trigger workflows.
Please{" "}
get in touch{" "}
if you'd like any additional help.
}
/>
1. Create a new HTTP request destination and select your model to query from
2. Set an `Authorization` header, with the value set to `Bearer `. You can find your secret API key in [your dashboard](https://dashboard.knock.app) under **Platform** > **API keys**
3. Name your destination "Knock API"
4. Create a new sync with your Knock API destination
5. Select the types of events that should trigger, the most common case here is "Rows added"
6. Set the HTTP request method to `PUT` and the URL to `https://api.knock.app/v1/users/{{ row.user_id }}` where `{{ row.user_id }}` corresponds to the user identifier in the table
7. Select a "JSON" payload and "Use the JSON editor" to craft the request
8. Add at least a `name`, `email`, or `phone_number` field from your users table
9. For the rate limit, you can specify 60 requests per second
10. You'll likely want to "backfill" all of the available rows meaning that any existing data will also be synced to Knock
11. Click "Continue"
12. Select your sync frequency
13. Click "Finish"
An example configuration for your sync may look something like this:
```json title="Example sync configuration"
{
"add": {
"enabled": true,
"method": "PUT",
"url": "https://api.knock.app/v1/users/{{ row.user_id }}",
"timeout": 30,
"contentType": "application/json",
"hasRateLimit": true,
"bodyType": "template",
"body": "{\n \"name\": \"{{ row.first_name }} {{ row.last_name }}\",\n \"email\": \"{{ row.email_address }}\",\n \"phone_number\": \"{{ row.phone_number }}\"\n}",
"rateLimit": 60,
"rateLimitTime": "second",
"onError": "retryRequest",
"retries": 3
},
"change": {},
"remove": {},
"skipFirstRun": false
}
```
## Syncing audiences into Knock from Hightouch
Hightouch models can be synced to Knock [audiences](/concepts/audiences) by configuring Knock as an Embedded Destination in Hightouch. This integration does not require any additional configuration in the Knock dashboard once the following steps are completed in Hightouch.
### Prerequisites
1. Determine which Knock environment you want to sync your audience to. You most likely want to sync in the Production environment, unless you’re configuring a test sync.
2. Have your Knock environment’s secret API key ready. Each environment has its own unique set of API keys; you can find your secret API key in your dashboard under **Platform** > **API keys**. Be sure that the correct environment is selected in the switcher at the top of the page.
### Configure Knock as a Hightouch Destination
Before you can sync audiences into Knock from Hightouch, you need to configure Knock as an Embedded Destination in Hightouch.
Navigate to the **Integrations** > **Destinations** page in Hightouch’s
sidebar, then click "Add destination."
Under "Developer tools," select "Embedded Destination" and then click "Continue."
Copy and paste the following into the URI field:
```txt title="Knock Embedded Destination URI"
https://api.knock.app/v1/integrations/hightouch/embedded-destination
```
Add the following under **Headers**. Be sure to toggle the "Secret" setting for the value:
| Header | Value |
| ------ | ----- |
| `Authorization` | `Bearer ` |
Your completed URI configuration should look something like this:
Click "Continue."
You'll be given the opportunity to configure alerts for this destination; if you don't need alerts, you can click "Continue" again.
Type in a name for your destination and click "Finish."
We recommend something like “Knock Production” so that its clear which environment the destination writes to.
### Add a sync to your Knock destination
Once you have configured Knock as an Embedded Destination in Hightouch, you can add a sync to your destination.
Navigate to **Activation** > **Syncs** in the Hightouch sidebar, then click "Add sync."
You'll be prompted to select a model for your source data. Select the model for the audience that you want to sync to Knock.
Next, you'll select the Knock Embedded Destination that you created above.
Select “Audiences” in the “Which object would you like to sync data to?” dropdown.
Then, select a mode for the sync:
- **Insert only:** Only new rows added to your model will be synced to Knock. Removing rows from your model will have no effect on your Knock audience.
- **Mirror:** New rows in your model will be added to your audience and removed rows in your model will be deleted from your audience.
Knock’s Embedded Destination only applies add and remove operations. It does not support update operations.
}
/>
Map your model’s fields to the audience fields.
You must map a model field to the audience "User ID" field. This field should correspond to the ID of the user in Knock.
If you’d also like to map a `tenant` field, click "Add mapping" and select the appropriate field from your model.
Next, enter the key of the Knock audience you want to sync to. If an audience with this key doesn't exist in Knock yet, it will be created automatically when the sync runs for the first time. Click "Continue."
Finally, you'll set your sync to run manually, on a schedule, or with an automation.
You can now click "Finish" to add the sync and run it whenever you’d like. Refer to Hightouch’s documentation for more information on syncs.
If you want to trigger any Knock workflows based on audience entry, ensure that the workflows are configured, committed, and promoted to the relevant environment before starting the Hightouch sync.
}
/>
You can verify that the sync is behaving as expected by:
- Comparing total user counts in your model and the audience in your Knock dashboard.
- Viewing the audience user list.
- Viewing workflow run logs for the audience (if you have workflow audience triggers configured).
## Census
Learn how to power your Knock product notifications using synced data from your data warehouse using Census.
---
title: How to integrate Census with Knock
description: Learn how to power your Knock product notifications using synced data from your data warehouse using Census.
metaTitle: Census source integration
metaDescription: Connect Census to Knock to sync user, object, and tenant data from your data warehouse into Knock on a scheduled basis.
section: Integrations > Sources
layout: integrations
---
## Getting started
Knock can be integrated as a downstream destination in Census to sync customer and event data from your data warehouse.
### Use cases
You can use our Census integration to:
1. Sync customer data into Knock from your data warehouse ([identify recipients](/managing-recipients/identifying-recipients)).
2. [Trigger workflows](/send-notifications/triggering-workflows/overview) from records added, changed, or removed in your data warehouse.
3. Populate [audiences](/concepts/audiences) with data from your data warehouse. Audiences can be used to trigger workflows or power conditional logic during workflow execution.
## Configure Knock as a destination in Census
Before you can sync data into Knock from Census, you need to configure Knock as a destination.
Our Census integration only requires configuration within Census. Once
you've completed the setup steps below, you will not need to take any
additional steps in the Knock dashboard.
}
/>
### Prerequisites
1. Determine which Knock environment you want to sync your Census data to. You most likely want to sync in the Production environment, unless you’re configuring a test sync.
2. Have your Knock environment’s secret API key ready. Each environment has its own unique set of API keys; you can find your secret API key in your dashboard under **Platform** > **API keys**. Be sure that the correct environment is selected in the switcher at the top of the page.
3. Choose your destination type. Your options are:
- **Custom destination** - Our recommended destination type for syncing audiences into Knock from Census. Setup is simpler and includes automatic support for removing a user from an audience during your syncs without additional configuration.
- **HTTP Request destination** - This destination type is required if you need to [sync users and their properties to Knock](#syncing-customer-data-into-knock-from-census) or if you need to include [tenant](/concepts/tenants) data in your Knock audience.
### Configuration instructions
Navigate to the **Destinations** tab in Census and click "Add a Destination."
Select "Custom Destination API."
**a.** Input a destination name. We recommend something like **Knock Production** that correlates to the Knock environment that you're syncing to.
**b.** Copy and paste the following into the API URL field:
```txt title="Knock Custom Destination API URL"
https://api.knock.app/v1/integrations/census/custom-destination
```
**c.** Click the "+ Add Header" button to add an `Authorization` header. Be sure to toggle the "Secret" setting for the value:
| Header | Value |
| ------ | ----- |
| `Authorization` | `Bearer ` |
**d.** Leave “1” selected as the API Version, then click "Connect" to complete the configuration.
Census will now test connectivity with Knock. This process may take a few moments to complete.
Navigate to the **Destinations** tab in Census and click "Add a Destination."
Select "HTTP Request."
**a.** Input a destination name. We recommend something like **Knock Production HTTP API** that correlates to the Knock environment that you're syncing to.
**b.** Leave the Authorization Type set to "Manual."
**c.** Copy and paste the following into the Base URL field:
```txt title="Knock API Base URL"
https://api.knock.app/v1
```
**d.** Click the "+ Add Header" button to add an `Authorization` header. Be sure to toggle the "Secret" setting for the value:
| Header | Value |
| ------ | ----- |
| `Authorization` | `Bearer ` |
**e.** Click "Connect" to complete the configuration.
## Syncing audiences into Knock from Census
Census Sources and Datasets can be synced to Knock audiences by configuring Knock as a custom destination or using an HTTP request destination connected to Knock’s audiences API.
This integration will only sync a user's audience membership to Knock. To
sync users and their properties into Knock, see the section below on{" "}
syncing customer data into Knock from Census
.
}
/>
### Prerequisites
1. Complete the steps to [configure Knock as a destination in Census](#configure-knock-as-a-destination-in-census).
2. Create, save, and commit a [static audience](/concepts/audiences#audience-types) in Knock that will serve as the target for your sync. Be sure that you create your audience in the same environment that you used to configure your Knock destination.
3. Ensure that any Knock workflows that should be [triggered by a user's audience entry](/send-notifications/triggering-workflows/audiences) are configured, committed, and promoted to your Knock environment before finalizing your Census sync.
### Add an audience sync to your Knock destination
Follow the steps below to add an audience sync to your configured Knock destination in Census.
Navigate to the **Syncs** tab in Census and click "Create a sync."
You'll be prompted to select a dataset for your source data. Select the dataset that you want to sync to Knock.
Next, you'll select the Knock custom destination that you created above. The "Audiences" object should be selected by default.
Select the sync behavior that you want to use.
- **Create only:** New rows added to your model will be synced to Knock. Removing rows from your model will have no effect on your Knock audience.
- **Mirror:** New rows added to your model will be added to your audience and removed rows in your model will be deleted from your audience.
Select a sync key from your source to map to the Knock audience User ID field. This field's value must be unique; if Census detects multiple rows with the same sync key value, it marks them as duplicates and does not sync them.
Under "Set Up Custom Destination API Field Mappings," you'll add the key of the Knock audience that you want to sync to.
**a.** Click the "Source value..." dropdown.
**b.** Click "Constant Value" on the left-hand side, then enter the key of your Knock audience in the input field.
**c.** Click "Save."
We recommend clicking "Run test" to test your sync. If successful, this will sync one row of data to your Knock audience, which you can confirm in the Knock dashboard. Any errors with your source data or field mappings will be displayed in the test results.
Click "Next." You'll be prompted to provide an optional label and select the trigger type for your sync.
Click "Create" to complete the sync creation process.
Navigate to the **Syncs** tab in Census and click "Create a sync."
You'll be prompted to select a dataset for your source data. Select the dataset that you want to sync to Knock.
Next, you'll select the Knock HTTP request destination that you created above.
Enter the following into the request endpoint input, replacing `` with the key of your destination audience. For example, if your audience key is `new-signups`, you’d enter `/audiences/new-signups/members`.
```txt title="Knock API audience members endpoint"
/audiences//members
```
Select "Records added" as the trigger type.
Select "Multiple records per request" to sync audience members in batches. Set the number of rows per batch to 500.
Select a sync key from your source to map to the Knock audience User ID field. This field's value must be unique; if Census detects multiple rows with the same sync key value, it marks them as duplicates and does not sync them.
Select `POST` as the request method.
Then, select "JSON" as the payload type and "Template editor" as the customization option.
Modify the following template, replacing `source_user_id` and `source_tenant_id` with the names of columns from your data source that map to the Knock user ID and the Knock tenant ID. Then paste it into the JSON payload form.
Note that column names are case-sensitive.
```json title="Request body template"
{
"members": [
{% for record in records %}
{
"user": { "id": "{{ record['source_user_id']}}" },
"tenant": "{{ record['source_tenant_id'] }}"
}
{% endfor %}
]
}
```
The rate limit for “Add member” API requests to Knock is 60 requests per second. We recommend choosing a lower number (such as 10 requests per second) to allow for multiple syncs to run at once.
Select "Backfill All Records" to sync all existing records in your source data to your Knock audience, or "Skip Current Records" to only sync new records going forward.
We recommend clicking "Run test" to test your sync. If successful, this will sync one row of data to your Knock audience, which you can confirm in the Knock dashboard. Any errors with your source data or field mappings will be displayed in the test results.
Click "Next." You'll be prompted to provide an optional label and select the trigger type for your sync.
Click "Create" to complete the sync creation process.
If you want your audience sync to run in “insert only” mode, you’re all set! If you’d like to also remove audience members when rows are deleted from your data source, proceed to the next step.
Repeat steps 1. and 2. above, using the same source data and your Knock HTTP request destination.
When you get to step 3., paste the following into the request endpoint, with replacements:
- `audience_key` should be the same audience key used in the previous section.
- `source_user_id` should be the name of the column that stores Knock user IDs.
- `source_tenant_id` should be the name of the column that stores Knock tenant IDs.
```txt title="Knock API audience members endpoint"
/audiences//members?members=[{"user": {"id": "{{ record['source_user_id'] }}"}, "tenant": "{{ record['source_tenant_id'] }}"}]
```
**a.** Select "Records removed" as the trigger type.
**b.** Select "One record per request" to remove audience members one at a time.
**c.** Select the same sync key as the one that you used in your "Add member" sync.
**d.** Select `DELETE` as the request method. The payload type will be "empty" for this request method.
**e.** Configure a rate limit for the sync. The same 60 requests per second rate limit as your "add member" sync applies to this endpoint, and we recommend a similar setting to allow for multiple syncs to run at once.
As above, we recommend clicking "Run test" to test your sync. If successful, this will remove one row of data from your Knock audience, which you can confirm in the Knock dashboard. Any errors with your source data or field mappings will be displayed in the test results.
Click "Next." You'll be prompted to provide an optional label and select the trigger type for your sync.
Click "Create" to complete the sync creation process. Your setup is now complete!
## Syncing customer data into Knock from Census
Census user records can be synced to Knock by configuring an HTTP request destination connected to Knock’s users API.
### Prerequisites
1. Complete the steps to [configure Knock as a destination in Census](#configure-knock-as-a-destination-in-census). You'll need to configure an HTTP Request destination.
### Add a user sync to your Knock destination
Follow the steps below to add a user data sync to your configured Knock HTTP request destination in Census. These instructions leverage our bulk identify endpoint to optimize migrating large numbers of user records to Knock, but you can adapt this approach to use our [identify endpoint](/api-reference/users/identify) for ongoing syncs of individual user records.
Navigate to the **Syncs** tab in Census and click "Create a sync."
You'll be prompted to select a dataset for your source data. Select the dataset that you want to sync to Knock.
Next, you'll select the Knock HTTP request destination that you created above.
Enter the following into the request endpoint input:
```txt title="Knock API bulk identify endpoint"
/users/bulk/identify
```
Select either "Records added" or "Records added or changed" as the trigger type. If you only plan to run a one-time sync to migrate your user data to Knock, your selection doesn’t matter. Ongoing syncs should use "Records added or changed" to ensure that updated user records are synced to Knock.
Select "Multiple records per request" to sync audience members in batches. Set the number of rows per batch to 1000.
Select a sync key from your source to map to the Knock audience User ID field. This field's value must be unique; if Census detects multiple rows with the same sync key value, it marks them as duplicates and does not sync them.
Select `POST` as the request method.
Then, select "JSON" as the payload type and "Template editor" as the customization option.
Define a template for your request body. The only required Knock field is `id`. To reference source columns, use the `{{ record['source_column_name'] }}` syntax. Note that column names are case-sensitive.
Here is an example template that identifies `id`, `name`, `email`, and `favorite_color` attributes in Knock using the columns from your source data:
```json title="Request body template"
{
"users": [
{% for record in records %}
{
"id": "{{ record['user_id'] }}",
"name": "{{ record['name'] }}",
"email": "{{ record['email'] }}",
"favorite_color": "{{ record['fav_color'] }}"
},
{% endfor %}
]
}
```
The rate limit for bulk identify API requests to Knock is 1 request per second.
Select "Backfill All Records" to sync all existing user records in your source data to Knock, or "Skip Current Records" to only sync new user records going forward.
We recommend clicking "Run test" to test your sync. If successful, this will sync one user to your Knock environment, which you can confirm in the Knock dashboard. Any errors with your source data or field mappings will be displayed in the test results.
Click "Next." You'll be prompted to provide an optional label and select the trigger type for your sync.
Click "Create" to complete the sync creation process.
## Clay
Sync enriched lead and contact data from Clay tables into Knock to identify users and trigger workflows from CRM enrichment events.
---
title: Clay source
description: Sync enriched lead and contact data from Clay tables into Knock to identify users and trigger workflows from CRM enrichment events.
metaTitle: Clay source integration
metaDescription: Add a Clay HTTP API enrichment column that POSTs enriched lead and contact data to Knock to identify users and trigger notification workflows.
section: Integrations > Sources
layout: integrations
---
The Clay source enables you to send enriched lead and contact data from your Clay tables directly into Knock. You configure this by adding an HTTP API enrichment column to a Clay table that POSTs each row's enriched data to your Knock source URL. Clay runs the column as part of your enrichment workflow, so Knock receives updated contact data as soon as a row finishes processing.
This integration is useful for sales and marketing notifications: identifying enriched leads in Knock as soon as Clay finishes researching them, triggering Slack or email alerts to your sales team when a high-fit account lands, and keeping user profile data in sync with the enrichment work happening in your Clay tables.
Because the HTTP API column lets you define an arbitrary JSON body and custom headers, you can map any Clay column to any field in your Knock action mappings as your needs evolve.
## How verification works
Clay does not sign outbound HTTP API requests with a built-in signature scheme. Instead, Knock verifies a shared secret that you send as a Bearer token in the `Authorization` header from your HTTP API column. Knock checks that the value of the `Authorization` header matches `Bearer ` before processing the event.
This means the signing secret you configure in Knock must match the token you send in the `Authorization` header from Clay. Treat this value like an API key: store it somewhere safe and rotate it if it leaks.
## Prerequisites
- A Knock account with at least one [environment](/concepts/environments) configured.
- A Clay workspace with a table you want to send enriched data from.
## Set up the source in Knock
Navigate to **Platform** > **Sources** in the Knock dashboard. Make sure
you're in the correct environment. Select the **Clay** template as the
source type.
Once you've selected **Clay** as a source, you can review the default action
mappings. The default identifies a Knock user from a `lead.enriched` event
using `body.email` as the user ID and maps common contact fields
(`full_name`, `email`, `phone_number`, `avatar_url`) into the identify
payload, plus the full row as `properties`. These are helpful defaults to
get you started, but Knock can ingest any event you POST from Clay and you
can adjust your mappings at any time. Click the **Connect Clay** button to
continue.
After creating the source, copy the event ingestion URL from the setup
wizard for the environment you want to configure. You will paste this URL
into the HTTP API enrichment column in Clay as the POST destination.
Generate a strong random string to use as your shared secret (for example,
with `openssl rand -hex 32`) and paste it into the **Signing secret** field
in your Knock source environment configuration. You will send this same
value as a Bearer token in the `Authorization` header from Clay in the next
steps.
## Add an HTTP API enrichment column in Clay
Add an HTTP API enrichment column to your Clay table so each enriched row POSTs to your Knock source URL with a Bearer token in the `Authorization` header. See Clay's HTTP API integration overview for column configuration details.
In your Clay table, click **Add column** and choose **HTTP API** from the enrichment menu. In the **Setup inputs** section, set the request method to **POST** and paste the Knock source URL you copied earlier into the **Endpoint** field.
In the **Accounts** section, add a HTTP API (Headers) account with key `Authorization` and value `Bearer `, replacing `` with the value you set in Knock. Knock uses this Bearer token to verify each POST from your Clay table before processing the row data.
Configure the JSON body to include the fields you want Knock to receive. At minimum, set an `event` field that names the event (for example, `lead.enriched`) so Knock can match it to an action mapping, plus the contact attributes you want to map to a Knock user.
```json
{
"event": "lead.enriched",
"full_name": "{{ Full Name }}",
"email": "{{ Work Email }}",
"phone_number": "{{ Phone Number }}",
"avatar_url": "{{ Profile Picture URL }}",
"job_title": "{{ Job Title }}",
"company_name": "{{ Company Name }}",
"company_domain": "{{ Company Domain }}"
}
```
Use Clay's templating to drop in values from other columns in your table. The event name (`lead.enriched` in this example) is what Knock looks for in `body.event` to decide which action mappings to run.
Run the HTTP API enrichment column on a row (or on the full table) to POST the enriched data to Knock. You can verify that events are arriving by checking the event logs on the source environment page in Knock.
Once configured, every time the HTTP API enrichment column runs on a row, Clay POSTs that row's data to your Knock source URL. Knock verifies the `Authorization` header against your signing secret, extracts the event name from `body.event`, and executes the actions you've mapped for that event.
## Pre-configured events
Your HTTP API enrichment column can send any event name in `body.event`, so the event types you POST to Knock are up to you. The default action mapping below identifies enriched leads as Knock users; add additional mappings for any other event names you decide to send.
| Event type | Action | Description |
| --------------- | ------------- | ---------------------------------------------------------------------------- |
| `lead.enriched` | Identify user | Identifies a user in Knock from an enriched Clay row, keyed off `body.email` |
The default identify mapping uses `body.email` as the Knock user ID and maps `body.full_name`, `body.email`, `body.phone_number`, and `body.avatar_url` to the corresponding user fields. The full row is sent as `properties`, so any additional columns you include in the request body (job title, company domain, ICP score, and so on) are stored on the Knock user and available in your templates.
### Other common events to add
Clay tables run a wide range of enrichment and research workflows. Common events worth adding as custom mappings:
| Event type | Typical action | Description |
| ------------------ | ----------------------------------------- | ------------------------------------------------------------------------------ |
| `account.enriched` | Identify [object](/concepts/objects) | Sync an enriched company or account as a Knock object |
| `lead.high_intent` | Trigger a `new-high-intent-lead` workflow | Notify your sales team when an enriched row crosses an ICP or intent threshold |
| `contact.updated` | Identify user | Re-identify a user when Clay re-runs enrichment on an existing contact |
For each new event you send from Clay, add a corresponding mapping in the Knock source environment so the event is routed to the right action.
## Customization
You can modify the default action mapping or add new ones for any event you POST from Clay. For details on how field mapping works with dot-notation paths, see the [custom source](/integrations/sources/custom) page.
Because the HTTP API enrichment column lets you set arbitrary headers on each POST, you can also reference custom headers in your mappings using dot-notation — for example, `headers.x-clay-table-id` if you want to differentiate between events from different Clay tables when one Knock environment ingests from many tables.
If a single event maps to multiple actions, Knock executes those actions in a fixed order. See [execution order for multiple mappings](/integrations/sources/overview#execution-order-for-multiple-mappings).
If you need to map Clay events to actions beyond identifying users, see the full list of [available actions](/integrations/sources/overview#triggering-actions-from-source-events) in the sources overview.
## Event idempotency
Clay does not include a built-in delivery ID in HTTP API enrichment column requests, so Knock does not configure idempotency for the Clay source by default. If you want to deduplicate events — for example, when the enrichment column is re-run on the same row — include a stable identifier in your request body or headers (such as the Clay row ID or a hash of the row's content) and configure that field as the idempotency key from the **Settings** tab in your source environment configuration.
For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## Polytomic
Learn how to power your Knock product notifications using synced data from your data warehouse using Polytomic.
---
title: How to integrate Polytomic to Knock
description: Learn how to power your Knock product notifications using synced data from your data warehouse using Polytomic.
metaTitle: Polytomic source integration
metaDescription: Connect Polytomic to Knock to sync user, object, and tenant data from your data warehouse into Knock on a scheduled basis.
section: Integrations > Sources
layout: integrations
---
## Getting started
Knock integrates with Polytomic as a downstream destination to sync customer and event data from your data warehouse.
Our Polytomic integration is currently in beta. If you'd like early
access, or this is blocking your adoption of Knock, please{" "}
get in touch
.
}
/>
## Use cases
You can use our Polytomic integration to:
1. Sync customer data into Knock from your data warehouse (identify)
2. Trigger workflows from records added, changed, or removed in your data warehouse
## Jitsu
Learn how to connect your Jitsu events to Knock to power your product notifications.
---
title: How to integrate Jitsu to Knock
description: Learn how to connect your Jitsu events to Knock to power your product notifications.
metaTitle: Jitsu source integration
metaDescription: Connect Jitsu to Knock to send events from your open-source data pipeline that trigger notification workflows.
section: Integrations > Sources
layout: integrations
---
## Getting started
Knock integrates with Jitsu as a downstream destination to sync customer and event data.
Our Jitsu integration is currently in beta. If you'd like early access, or
this is blocking your adoption of Knock, please{" "}
get in touch
.
}
/>
## Use cases
You can use our Jitsu integration to:
1. Sync customer data into Knock
2. Trigger workflows from track events
## Freshpaint
Learn how to connect your Freshpaint events to Knock to power your product notifications.
---
title: How to integrate Freshpaint to Knock
description: Learn how to connect your Freshpaint events to Knock to power your product notifications.
metaTitle: Freshpaint source integration
metaDescription: Connect Freshpaint to Knock to send healthcare-focused CDP events that trigger notification workflows and keep user data in sync.
section: Integrations > Sources
layout: integrations
---
## Getting started
Knock integrates with Freshpaint as a downstream destination to sync customer and event data.
Our Freshpaint integration is currently in beta. If you'd like early
access, or this is blocking your adoption of Knock, please{" "}
get in touch
.
}
/>
## Use cases
You can use our Freshpaint integration to:
1. Sync customer data into Knock
2. Trigger workflows from track events
## Custom source
Send custom webhook events from any service into Knock and map them to actions like triggering workflows and identifying users, with optional scripting for verification and preprocessing.
---
title: Custom source
description: Send custom webhook events from any service into Knock and map them to actions like triggering workflows and identifying users, with optional scripting for verification and preprocessing.
metaTitle: Custom source integration
metaDescription: Send webhook events from any service into Knock using a custom source with configurable event types, field mapping, and scripting for verification and preprocessing.
section: Integrations > Sources
layout: integrations
---
The custom source enables you to receive webhook events from any service that can make HTTP callbacks and map those events to actions inside Knock. Use it when you need to connect a service that Knock does not yet offer a [pre-built integration](/integrations/sources/overview) for, or when you want to send events from your own internal tools and applications. The custom source supports optional [scripting](#scripting) so you can verify incoming payloads and pre-process them before field mapping.
## When to use custom webhooks
Custom webhooks are the right choice when:
- The service you want to connect does not have a pre-built Knock source integration.
- You are sending events from an internal tool, custom application, or microservice.
- You need full control over event type identification and field mapping.
For services with pre-built integrations (Stripe, Clerk, WorkOS, Supabase, PostHog), use those dedicated source pages instead. They provide automatic signature verification and pre-configured event types.
## Getting started
Navigate to **Platform** > **Sources** in the Knock dashboard. Make sure
you're in the correct environment. Select the **Custom HTTP** template as
the source type. You can select default action mappings to get started, then
click the **Connect Custom HTTP** button to continue.
After creating the source, Knock displays a setup wizard. Copy the event
ingestion URL from step 1 of the wizard. You will paste this into your
service's webhook or callback settings.
In step 2 of the setup wizard, configure the event type path so Knock knows
how to identify the event type from incoming payloads. The default path is
`body.type`, but you should update this to match the structure of your
payload. For example, if your service sends payloads with an `event_type`
field at the top level, set the path to `body.event_type`. You can also
update this later from the **Settings** tab on the source environment page
under **Key path configuration**.
Paste the webhook URL into your service's webhook or callback settings.
Knock accepts `POST` requests with a JSON body. If your source includes a
[script](#scripting), Knock runs it on every incoming request to handle
verification and any preprocessing you need.
## Scripting
Each custom source can have a script that runs every time Knock receives a webhook request. Scripts enable you to verify that incoming payloads are authentic and preprocess payloads before field mapping. You can configure your script from the **Settings** tab on the source environment page.
A script must export a `main` function. Knock calls `main` with a context object that contains the following properties:
| Property | Description |
| --------- | ---------------------------------------------- |
| `vars` | Account-level [variables](/concepts/variables) |
| `body` | The parsed request body object |
| `rawBody` | The raw request body string |
| `headers` | HTTP headers from the incoming request |
### Verification
The `main` function must return an object with a `verified` boolean. When the **Enforce verification** toggle is enabled, Knock rejects any request where `verified` is `false` or missing with a `401` response.
If the sending service signs its payloads, store the signing secret as an account-level [variable](/concepts/variables) so your script can access it through `vars`. The default script included with new custom sources compares an `x-webhook-secret` header against a variable you configure, but you can customize the verification logic to match whatever algorithm and header convention the sending service expects.
```javascript
async function main(ctx) {
const { headers, rawBody, vars } = ctx;
const signingSecret = vars.my_signing_secret;
const isValid = await verifySignature(headers, rawBody, signingSecret);
return { verified: isValid };
}
```
Full per-source verification examples are available on the dedicated source integration pages (for example, [Stripe](/integrations/sources/stripe)).
### Preprocessing
Any additional keys you return from `main` alongside `verified` become available in field mappings under the `preprocess` namespace. This is useful when you need to normalize or reshape the incoming payload before mapping it to action parameters.
```javascript
function main(ctx) {
const { body } = ctx;
return {
verified: true,
normalized_event: `${body.schema}.${body.table}:${body.type}`,
item_idempotency_key: `${body.record.id}_${body.record.updated_at}`,
};
}
```
In this example, `normalized_event` becomes `preprocess.normalized_event` and `item_idempotency_key` becomes `preprocess.item_idempotency_key` in field mapping paths.
## Configuring event types
As described in [step 3 of getting started](#getting-started), Knock needs to know how to identify the event type from incoming payloads. The default event type path is `body.type`, but you should update this to match the structure of your payload.
For example, if your service sends payloads like:
```json
{
"event_type": "task.completed",
"timestamp": "2024-09-15T14:30:00Z",
"data": {
"task_id": "task_123",
"assigned_to": "user_456"
}
}
```
You would set the event type path to `body.event_type` so Knock can identify this as a `task.completed` event. Note that all body paths are prefixed with `body.` since Knock exposes the parsed request body under that namespace.
## Event-action mappings
After events start flowing into Knock, you can configure what action Knock should take when it receives each event type. From the source environment configuration page:
1. Select an event type from the list of received events.
2. Click "Create action mapping" to add a new mapping.
3. Choose the action to execute (trigger workflow, identify user, set object, and so on). See the [available actions](/integrations/sources/overview#triggering-actions-from-source-events) in the overview for the full list.
4. Map fields from the incoming payload to the parameters the action requires.
You can create multiple action mappings for a single event type. For example, a `customer.created` event could both identify a user and trigger a welcome workflow.
### Execution order for multiple mappings
If a single event type has multiple action mappings, Knock executes them in a fixed priority order based on action type, not the order in which you create mappings in the dashboard.
1. `users_identify`
2. `users_delete`
3. `objects_set`
4. `objects_delete`
5. `tenants_set`
6. `tenants_delete`
7. `objects_subscribe`
8. `objects_unsubscribe`
9. `audiences_add_member`
10. `audiences_remove_member`
11. `workflows_trigger`
For incoming webhook context and related behavior, see [execution order for multiple mappings](/integrations/sources/overview#execution-order-for-multiple-mappings) in the sources overview.
## Field mapping
Field mappings use dot-notation paths to extract values from the incoming JSON payload and map them to the parameters each action expects.
Given a payload like:
```json
{
"event_type": "task.completed",
"data": {
"task_id": "task_123",
"assigned_to": "user_456",
"project": {
"id": "proj_789",
"name": "Website redesign"
}
}
}
```
You could create the following mappings when triggering a workflow:
| Payload path | Maps to |
| ------------------- | ------------------- |
| `data.assigned_to` | Recipients |
| `data.task_id` | `data.task_id` |
| `data.project.name` | `data.project_name` |
A few things to keep in mind:
- Paths are case-sensitive and follow the structure of your JSON payload.
- If your source has a [preprocessing script](#preprocessing), the values it returns are available under the `preprocess.*` namespace alongside the raw payload paths. For example, a script that returns `normalized_event` can be mapped using the path `preprocess.normalized_event`.
- You can map a single event to multiple action parameters.
- Knock validates that required fields are populated before executing the action. If a required field is missing, the action is skipped and an error appears in the action log.
## Example: task management app
Suppose you have a task management app that sends a webhook when a task is assigned. The payload looks like this:
```json
{
"event_type": "task.assigned",
"data": {
"task_id": "task_123",
"title": "Review pull request",
"assigned_to": "user_456",
"assigned_by": "user_789"
}
}
```
To trigger a notification workflow when a task is assigned:
1. Set the event type path to `body.event_type`.
2. Wait for a `task.assigned` event to arrive (or send a test event).
3. Create an action mapping that triggers your `task-assigned` workflow.
4. Map `data.assigned_to` to **Recipients** and `data.assigned_by` to **Actor**.
5. Map `data.task_id` and `data.title` to workflow data fields so you can reference them in your notification templates.
## Debugging
You can see a log of all events received per source under **Platform** > **Sources** in the Knock dashboard on the "Logs" tab for your configured source. Common issues to look for:
- **Missing fields.** A required field path does not exist in the incoming payload. Check that the dot-notation path matches your payload structure.
- **Invalid paths.** The key path for event type identification does not resolve to a value. Verify the path against a sample payload.
- **Type mismatches.** A field value does not match the expected type (for example, passing a string where a user ID array is expected).
## Event idempotency
You can enable idempotency checks to deduplicate custom webhook events that have already been received and processed. This is useful if the service sending webhooks may deliver the same event more than once.
Because custom webhook payloads vary by service, you need to specify which field in the incoming payload contains the idempotency key. Enable the **Enforce idempotency** toggle in the **Settings** tab for your source environment configuration and set the **Idempotency key path** to the field in your payload that contains a unique event identifier.
For example, if your service sends payloads with a unique event identifier:
```json title="A custom webhook event with an idempotency key."
{
"event_type": "task.completed",
"event_id": "evt_abc123",
"data": {
"task_id": "task_456",
"assigned_to": "user_789"
}
}
```
You would set the idempotency key path to `event_id` so Knock can use it for deduplication.
Events without a value at the configured key path are processed normally. For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## Legacy
## Segment
The legacy Segment source uses webhook destinations to forward track and identify events from Segment to Knock. For new integrations, use the updated Segment source instead.
---
title: Segment source (legacy)
description: The legacy Segment source uses webhook destinations to forward track and identify events from Segment to Knock. For new integrations, use the updated Segment source instead.
metaTitle: Segment source integration (legacy)
metaDescription: Connect Segment to Knock using the legacy webhook destination approach. For new integrations, use the updated Segment source.
section: Integrations > Sources
layout: integrations
---
This is the legacy Segment source integration that uses manual webhook
destinations. It is still supported for existing integrations. For new
integrations, use the updated{" "}
Segment source instead.
}
/>
Knock's Segment integration enables you to use Segment as a [Knock source](/integrations/sources/overview) to power your notifications with track and identify events.
Knock also provides a separate [Segment extension](/integrations/extensions/segment) for sending Knock notification data into Segment for use in your downstream tools.
## Getting started
When using Segment as a Knock source, you also need to configure Knock as a [destination](https://segment.com/docs/connections/destinations/) within Segment. This means you can use events coming through Segment to power actions in Knock, such as triggering a workflow.
To start routing your Segment events to Knock, navigate to **Integrations** > **Sources** under the account settings section of your dashboard, click the "Create Source" button and select Segment. Once created, select it from the list to access the environment configuration page, where you can copy the unique webhook destination URLs for each environment you have configured in Knock.
## Configure a Knock destination in Segment
Knock does not have a first-party integration with Segment, so you will
not find us in Segment's destination catalog. Instead, you'll configure
the connection to Knock via a webhook destination as described below.
}
/>
In your Segment workspace, navigate to the **Destinations** tab and click "Add Destination." From here, search for **Webhooks** or navigate to **Raw Data** in the sidebar and click the "Webhooks (Actions)" option. This is the destination type we'll use for Knock.
Click the "Configure Webhooks (Actions)" button in the top right to enter the setup flow to configure your webhook:
- Select the data source you'd like to receive events from and click "Next."
- Give a name to the destination, like "Knock," and keep the "Fill in settings manually" option selected, then click "Create destination."
Now you'll see a **Settings** page. Check the "Enable Destination" button and click "Save changes."
At the top of the page, navigate to the **Mappings** tab. Click "New Mapping," and under Actions, click "Send".
You will then be directed to a form to configure the webhook:
- Select the events to map and send to Knock. If you'd like to send all events to Knock, you can add the condition **Event type is Track,** a condition for **Event type is Identify,** and change the top operator to **any** instead of all:
- You can load a test or sample event; either way, ensure it matches your trigger conditions (Segment will warn you if it doesn't).
- Click "Test Mapping" to send the loaded or sample event from the previous step to Knock.
- If the test is successful, click "Save" to exit the form, and then click to enable the mapping you just created.
## Viewing Segment track events in Knock
Once your Segment destination is set up, all events you trigger from the Segment source will be forwarded to Knock. Unique events will appear in your list of events under the Source so that you can set up triggers for your workflows.
From the source environment configuration page, click the "View in environment" button on one of the source environments. You'll be taken to the Segment source in the environment you selected, and you should see events sent. If you don't, try clicking the refresh button at the top of the list to refetch any incoming events.
### How Knock translates Segment events
Although Segment has its own event format, Knock translates incoming events into a common format that includes the following fields:
- `user_id`. The ID of the user performing a given action (may not be set if a user has not been identified yet).
- `data`. The primary contents of the event. For a Segment `track` call with associated `properties`, Knock uses those `properties` to set the `data` field.
- `event`. The original event, as originally received by Knock.
## Triggering workflows from received events
You can add a **track event** as a trigger to your workflow directly from the workflow builder. Click on the workflow's trigger step and change the type from "API" to "Source Event." Then you'll be able to select the event and map its properties into the data the workflow needs.
You can have any number of workflows triggered by each event. If no workflow is configured for an event, the event is logged but no action is taken.
When connecting an event to a workflow, you can use any data available within the event payload in the workflow's parameters. For example, if your payload looks like this:
{eventPayload}
and you wanted the commenter from the event to appear as the{" "}
actor in the workflow, then in the{" "}
actor field, you would write{" "}
properties.commenter.id to supply their ID as the actor.
If you wanted to supply the event's userId as the workflow's recipient,
you'd write userId in the Recipients field.
Note: when you edit message templates,
all properties are available to you as data variables. You can access them directly in your templates without
the properties. prefix.
}
/>
If you exceed this limit, Knock will not process your workflow trigger and
instead generate an error log.
If you need to manage a large list of recipients you might want to
consider using our{" "}
subscriptions feature to have Knock
manage the set of recipients who need to be notified instead.
}
/>
## Disabling a trigger
Triggers are automatically enabled when you create them. If you want to stop an event from triggering a workflow, you can go to the trigger page and toggle its status to "Inactive." Keep in mind that this will disable that trigger for the current environment only. When you're ready to trigger the workflow again, you can set it back to "Active."
## Enabling Identify events
When Segment sends identify events, Knock will create and update user information accordingly. Knock will correctly map the `userId` as the user's `id`, as well as `name`, `email`, `phone` (mapped as `phone_number` in Knock), `avatar`, `locale`, `timezone`, and any additional custom properties provided in the `traits` object. All custom properties are stored on the Knock user object and can be used in templates and other parts of Knock that rely on user properties.
To enable the handling of identify events, open the settings for the source in the relevant Knock environment. You can then enable or disable handling identify events accordingly.
if you send Knock an event that includes a recipient not yet identified in
Knock, our system will not generate a workflow run for that user.
For use cases such as new signup events, where events often reach Knock
before identify calls, consider{" "}
inline identification
{" "}
of users in your Segment events.
}
/>
## Inline identify users in a Segment event
Inline identification is not supported by our{" "}
workflow test runner
, which can only trigger test runs for existing users. To test inline identification
with a source event, you should send a test event from Segment.
}
/>
In cases where you send a Segment event to Knock with recipients who may not yet have been identified in our system, it's good practice to [inline identify](/managing-recipients/identifying-recipients#inline-identification) your users. By inline identifying your users within your Segment events, you ensure that those users are identified in Knock when your event triggers a workflow.
As an example, take the user-signed-up event below. We're currently mapping the `properties.recipients` field to the `recipients` field of our workflow in Knock. If we send this event to Knock before the user with id `sam10` has been identified, the user will not be notified.
```json title="A Segment event without inline identify"
{
"event": "user-signed-up",
"email": "sam@example.com",
"userId": "sam10",
"type": "track",
"messageId": "segment-test-message-123",
"properties": {
"recipients": ["sam10"],
"account_id": "123"
},
"timestamp": "2023-05-23T21:49:54Z"
}
```
To ensure the user is notified, we'd change the id reference in `recipients` to a complete user object, as in the example below. This way, Knock has all the information it needs to identify the user during workflow runtime.
```json title="A Segment event with inline identify"
{
"event": "user-signed-up",
"email": "sam@example.com",
"userId": "sam10",
"type": "track",
"messageId": "segment-test-message-123",
"properties": {
"recipients": [
{
"id": "sam10",
"name": "Sam Seely",
"email": "sam@example.com"
}
],
"account_id": "123"
},
"timestamp": "2023-05-23T21:49:54Z"
}
```
You can learn more about inline identification in [our documentation on identifying recipients](/managing-recipients/identifying-recipients).
## Event idempotency
You can enable idempotency checks to deduplicate Segment events that have already been received and processed. This is useful if you know Segment may send duplicate events to Knock.
Knock automatically uses the `messageId` field from the Segment track spec as the idempotency key. No additional field configuration is needed — Segment includes a `messageId` in every track and identify event by default.
To enable idempotency, open the **Settings** tab for your source environment configuration and toggle idempotency checks on.
```json title="An example Segment event with a valid idempotency key."
{
"type": "track",
"event": "user.created",
"messageId": "some-id-from-segment",
"properties": {
"id": "user-1",
"email": "user-1@example.com"
}
}
```
Events without a `messageId` are processed normally. For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## Video walkthrough
## Frequently asked questions
Yes. Under the **Platform** > **Sources** section in your Knock dashboard,
select an event from Segment to view a list of triggers configured for that
event. Then, in the upper right-hand corner, click the "Create workflow
trigger" button to select the additional workflow you want this event to
trigger, then click "Create." You can then make any changes to the schema
mapping before saving and committing the workflow with its new trigger.
Yes. To do so, go to the **Platform** > **Sources** section in your Knock
dashboard, select an event, and then click the "Create workflow trigger"
button in the upper right-hand corner. You will choose the same workflow
from the **Create workflow trigger** modal.
## RudderStack
The legacy RudderStack source uses webhook destinations to forward track and identify events from RudderStack to Knock. For new integrations, use the updated RudderStack source instead.
---
title: RudderStack source (legacy)
description: The legacy RudderStack source uses webhook destinations to forward track and identify events from RudderStack to Knock. For new integrations, use the updated RudderStack source instead.
metaTitle: RudderStack source integration (legacy)
metaDescription: Connect RudderStack to Knock using the legacy webhook destination approach. For new integrations, use the updated RudderStack source.
section: Integrations > Sources
layout: integrations
---
This is the legacy RudderStack source integration that uses manual webhook
destinations. It is still supported for existing integrations. For new
integrations, use the updated{" "}
RudderStack source{" "}
instead.
}
/>
## Video walkthrough
## Getting started
Knock is a **RudderStack Destination**, which means you can use events coming through RudderStack to power actions in Knock, such as triggering a workflow.
You can start routing your RudderStack events to Knock by creating a source of type "RudderStack" in the dashboard. From here, you'll be taken to the environment configuration page for the source which will give you unique URLs for each environment you have configured in Knock.
You'll copy this URL and use it to let RudderStack know where to send events.
## Configuring RudderStack
Knock does not have a first-party integration with RudderStack, so you
will not find us in the list of destinations. Instead, you'll configure
the connection to Knock via a webhook destination as described below.
}
/>
You will need to create a RudderStack destination for each Knock environment that you want to receive events from RudderStack.
1. In your RudderStack workspace, navigate to the "Destinations" page and click "New destination." Search for and select "Webhook"
2. Give the destination a name (e.g. "Knock <environment name>") and click "Continue"
3. Optionally, choose the sources you want to route into this destination. Then, click "Continue"
4. Paste the URL from the Knock dashboard for the Knock environment you want to receive events from RudderStack. Make sure the "URL Method" selected is POST. No other headers or settings are required. Click "Continue"
5. Transformations may be configured as needed, but are typically not required. Click "Continue" to finalize the RudderStack destination
## Viewing RudderStack track events in Knock
Once your RudderStack destination is set up all events you trigger from the RudderStack source will be forwarded to Knock. Unique events will appear in your list of events under the Source so that you can set up triggers for your workflows.
From the source environment configuration page click the "View in environment" button on one of the source environments. You'll be taken to the RudderStack source in the environment you selected and you should see events sent. If you don't, try clicking the refresh button on the top of the list to refetch any incoming events.
### How Knock translates RudderStack events
Although RudderStack has its own event format, Knock translates incoming events into a common format that includes the following fields:
- `user_id`. The ID of the user performing a given action (may not be set if a user has not been identified yet).
- `data`. The primary contents of the event. For a RudderStack `track` call with associated `properties`, Knock uses those `properties` to set the `data` field.
- `event`. The original event, as originally received by Knock.
## Triggering workflows from received events
You can add a **track event** as a trigger to your workflow directly from the workflow builder. Click on the workflow's trigger step and change the type from "API" to "Source Event." Then you'll be able to select the event and map its properties into the data the workflow needs.
You can have any number of workflows triggered by each event. If no workflow is configured for an event, the event is logged but no action is taken.
To use any of the properties fields, you can access them with dot-syntax
by prefixing them with data.. For example, if your payload
looks like this:
{eventPayload}
and you wanted the commenter from the event to appear as the{" "}
Actor in the workflow, then in the{" "}
Actor field you would write{" "}
data.commenter.id to supply their ID as the actor.
}
/>
If you exceed this limit, Knock will not process your workflow trigger and
instead generate an error log.
If you need to manage a large list of recipients you might want to
consider using our{" "}
subscriptions feature to have Knock
manage the set of recipients who need to be notified instead.
}
/>
## Disabling a trigger
Triggers are automatically enabled when you create them. If you want to stop an event from triggering a workflow, you can go to the trigger page and toggle its status to "Inactive." Keep in mind that this will disable that trigger for the current environment only. When you're ready to trigger the workflow again, you can set it back to "Active."
## Enabling Identify Events
When RudderStack sends identify events, Knock will create and update user information accordingly. Knock will correctly map the `userId` as the user's `id`, as well as `name`, `email`, `phone` (mapped as `phone_number` in Knock), `avatar`, `locale`, `timezone`, and any additional custom properties provided in the `traits` object. All custom properties are stored on the Knock user object and can be used in templates and other parts of Knock that rely on user properties.
RudderStack's default Identify{" "}
event schema
{" "}
has the traits object nested under a top-level{" "}
context key.{" "}
Some RudderStack SDKs
{" "}
will also include a top-level traits object.
Knock expects user properties to be contained in a top-level
traits
object when processing an Identify event, so you may need
to apply a data transformation prior to sending these events to Knock depending
on which SDK you're using.
}
/>
To enable handling of identify events, open the settings for the source in the relevant Knock environment. You can then enable or disable handling identify events accordingly.
if you send Knock an event that includes a recipient not yet identified in
Knock, our system will not generate a workflow run for that user.
For use cases such as new signup events, where events often reach Knock
before identify calls, consider{" "}
inline identification
{" "}
of users in your RudderStack events.
}
/>
## Inline identify users in a RudderStack event
Inline identification is not supported by our{" "}
workflow test runner
, which can only trigger test runs for existing users. To test inline identification
with a source event, you should send a test event from RudderStack.
}
/>
In cases where you send a RudderStack event to Knock with recipients that may not yet have been identified into our system, it's good practice to [inline identify](/managing-recipients/identifying-recipients#inline-identification) your users. By inline identifying your users within your RudderStack events, you ensure that those users are identified in Knock when your event triggers a workflow.
As an example, take the user-signed-up event below. We're currently mapping the `properties.recipients` field to the `recipients` field of our workflow in Knock. If we send this event to Knock before the user with id `sam10` has been identified, the user will not be notified.
```json title="A RudderStack event without inline identify"
{
"event": "user-signed-up",
"email": "sam@example.com",
"userId": "sam10",
"type": "track",
"messageId": "rudderstack-test-message-123",
"properties": {
"recipients": ["sam10"],
"account_id": "123"
},
"timestamp": "2023-05-23T21:49:54Z"
}
```
To ensure that the user is notified, we'd change the id reference in `recipients` to a complete user object, as in the example below. This way Knock has all the information it needs to identify the user during workflow runtime.
```json title="A RudderStack event with inline identify"
{
"event": "user-signed-up",
"email": "sam@example.com",
"userId": "sam10",
"type": "track",
"messageId": "rudderstack-test-message-123",
"properties": {
"recipients": [
{
"id": "sam10",
"name": "Sam Seely",
"email": "sam@example.com"
}
],
"account_id": "123"
},
"timestamp": "2023-05-23T21:49:54Z"
}
```
You can learn more about inline identification in [our documentation on identifying recipients](/managing-recipients/identifying-recipients).
## Event idempotency
You can enable idempotency checks to deduplicate RudderStack events that have already been received and processed. This is useful if you know RudderStack may send duplicate events to Knock.
Knock automatically uses the `messageId` field from the RudderStack track spec as the idempotency key. No additional field configuration is needed — RudderStack includes a `messageId` in every track and identify event by default.
To enable idempotency, open the **Settings** tab for your source environment configuration and toggle idempotency checks on.
```json title="An example RudderStack event with a valid idempotency key."
{
"type": "track",
"event": "user.created",
"messageId": "some-id-from-rudderstack",
"properties": {
"id": "user-1",
"email": "user-1@example.com"
}
}
```
Events without a `messageId` are processed normally. For details on how Knock handles idempotent events, key validation rules, and the default 24-hour idempotency window, see the [source event idempotency](/integrations/sources/overview#source-event-idempotency) section of the sources overview.
## Video walkthrough
This video is Segment-specific, but you can apply any of the portions within the Knock dashboard to RudderStack as well.
## HTTP
The legacy HTTP source accepts events using the Segment track spec. For new integrations, use the custom source instead.
---
title: HTTP source (legacy)
description: The legacy HTTP source accepts events using the Segment track spec. For new integrations, use the custom source instead.
metaTitle: HTTP source integration (legacy)
metaDescription: Use the legacy HTTP source to send Segment track spec events into Knock. For new integrations, use the custom source instead.
section: Integrations > Sources
layout: integrations
---
The legacy HTTP source uses the Segment track spec event schema and is
still supported for existing integrations. For new integrations, use the{" "}
custom source instead.
}
/>
The legacy HTTP source creates a generic event ingestion endpoint that accepts events structured according to the Segment track spec. The events you stream into the HTTP source can be used to trigger Knock notification workflows.
Knock can receive any structured event data via the legacy HTTP source, as long as you format the payload as JSON and make an HTTP request from the service that produces or consumes events.
## Getting started
To get started you can create a new HTTP source by going to **Integrations** > **Sources** under your account settings and clicking "Create source." You'll have the opportunity to name the HTTP source and give it a description.
Once your source is created, you'll have a unique ingestion endpoint per environment to send events to. You can get each environment's endpoint by clicking the "Copy webhook destination URL" button.
## Sending event data
To start sending events to Knock, structure a JSON payload that matches the event schema below and submit it via a `POST` request to the ingestion endpoint. A well-formed event payload receives a `204` response code.
You also need to send the following headers with your request:
```txt title="Request headers"
Content-Type: application/json
```
You need to send a single event at a time. There is no batch event ingestion endpoint.
## Event schema
Your events must be structured as JSON with the following schema:
| Name | Type | Description |
| ------------ | ----------------- | ----------------------------------------------------------------------------------------------------------------- |
| `type` | string (required) | The type of event to send. Must be set to `track`. |
| `event` | string (required) | The name of the event you're sending to Knock. |
| `properties` | map | A set of properties associated with the event. |
| `userId` | string | An optional userId to be used as the recipient or actor for the triggered workflow. |
| `messageId` | string | An optional unique identifier for the event message, to be used as a deduplication key. |
| `timestamp` | string | An optional ISO-8601 timestamp indicating when the event occurred. If omitted, defaults to the time of ingestion. |
```json title="An example event payload"
{
"type": "track",
"event": "My event",
"properties": {
"foo": "bar"
}
}
```
## Triggering workflows from received events
Received events can be configured as workflow triggers directly in the workflow editor. Click on the workflow's trigger step and change the type from "API" to "Source Event." Then you can select the event and map its properties into the data the workflow needs.
## Disabling a trigger
Triggers are automatically enabled when you create them. If you want to stop an event from triggering a workflow, go to the trigger page and toggle its status to "Inactive." This disables that trigger for the current environment only. When you're ready to trigger the workflow again, set it back to "Active."
## Mapping workflow trigger properties
When creating workflow triggers from your events, you can optionally configure the schema mapping Knock uses to map your event properties into the corresponding workflow trigger properties.
To target any items under the `properties` key, prefix the schema mapping with `data.propertyKey`. As an example, if you have a property `properties.recipientId` you would map this as `data.recipientId`.
## Debugging events
You can see a log of all events received per source under **Integrations** > **Sources** in the Knock dashboard under the "Logs" page for your configured source. You can also see any workflow triggers that were configured as part of the event ingestion, and any workflow runs that were triggered.
## Frequently asked questions
No, the legacy HTTP source only accepts track events and not user
identifies. Please use the [user identify API](/concepts/users) instead.
Yes. You can use [inline
identification](/managing-recipients/identifying-recipients#inline-identification)
with the source events that you send to Knock. You need to ensure that the
schema mapping for your event maps the **Recipients** of your workflow to
the same field where you provide the recipient object.
There's no rate limit for the event ingestion endpoint, but we ask that if
you're going to be sending more than 1,000 events per second you reach out
to us first so that we can provision additional capacity.
No, the HTTP endpoint only accepts single events at a time.
# Email
## Overview
Learn how to send transactional email notifications with the Knock API.
---
title: Email notifications with Knock
description: Learn how to send transactional email notifications with the Knock API.
section: Integrations > Email
layout: integrations
---
Effortlessly design and deliver email notifications to downstream providers, without the need to keep HTML templates in your backend codebase.
## Features
- **Easy to get started, and extend**: Knock email notifications look great out of the box. We include sensible, well tested, default responsive styles so you can get up and running quickly across all major email clients. Check out the [Settings](/integrations/email/settings) page to learn about available configuration options.
- **Block based visual editor**: Don't want to write HTML? No problem! You can use our drag-and-drop visual editor to get started.
- **Fully flexible templates and styling**: If you need to write custom HTML or CSS you can drop down to a raw code editor to create your email messages. You're never constrained to the templates Knock provides.
- **CSS inlining**: By default, Knock will inline all CSS included with your emails to ensure maximum compatibility across email clients. This behavior can be disabled per-environment as a setting on your email channel's configuration.
- **Text generation**: We'll automatically generate a text version of your emails, so you never need to write both HTML and text templates.
- **Multiple layouts**: We support any number of emails layouts that can "wrap" your email templates and provide styles and shared elements like headers and footers.
- **MJML support**: Use [MJML](/integrations/email/mjml) to build responsive email layouts and templates with built-in mobile compatibility.
- **Attachments support**: It's easy to send attachments alongside your emails, just pass through some Base64 encoded data along with your `workflow.trigger` call and you're done!
- **Knock link and open tracking**: Capture link-click and email-open events right within your Knock account. For more details, see the [Knock link and open tracking documentation](/send-notifications/tracking).
- **Per environment configuration**: Configure different settings for each environment in your Knock account.
- **Sandbox mode**: Use sandbox mode to test your email steps before sending an actual email.
## Supported providers
Knock currently supports sending email notifications to the following email providers. Beyond the universally supported features mentioned above, each provider supports different features for tracking and managing email delivery.
Some providers support multiple methods for delivery tracking. For
example, Amazon SES requires webhook configuration to enable delivery
tracking and bounce support. See each provider's integration page for
setup instructions.
}
/>
If your preferred provider is not listed here, please let us know by
emailing us at support@knock.app.
}
/>
## Layouts
Learn more about how to use layouts with your email templates in Knock.
---
title: Email layouts
description: Learn more about how to use layouts with your email templates in Knock.
section: Integrations
layout: integrations
tags:
[
"precontent",
"css",
"layout",
"styles",
"design system",
"button",
"preview text",
"branding",
"email preview text",
]
---
Knock emails are built from two pieces: layouts and templates.
The **layout** is the shared "frame" of your email. The header, footer, and any HTML or CSS you want applied across templates. You define it once so every email renders consistently.
The **template** is the body of a specific email, authored in an email workflow step. At send time, Knock injects the template into the `{{content}}` variable of its layout to produce the final email.
Here's an example of a transactional email we send at Knock, with the template content merged into the layout. Green is the template, blue is the layout.
Knock provides two system-level variables for use in your layouts:
| Variable | Description |
| -------------- | ---------------------------------------------------------------------------------------------------------------- |
| `content` | The rendered email template is injected here. **Required — must appear somewhere in every layout.** |
| `footer_links` | The footer links configured in the layout editor are injected here. Optional and not required in custom layouts. |
## The Knock default layout
Every Knock account starts with a default layout at **Content** > **Email layouts**. New email templates use this layout by default, so update it to change the shared look and feel of all your emails.
Click the "Default" layout to open the visual editor, where you can configure footer links for HTML emails. Logo, icon, and brand color come from the **Branding** page under your account settings. To edit the HTML and CSS directly, click "Edit in code editor" to open the [custom layout](/integrations/email/layouts#custom-layouts-and-styling) editor.
Each layout also includes a plaintext version under the "Text" tab. It works the same way, the plaintext body of your template is injected into `{{content}}`.
## Select a layout for your email template
New email templates use your `default` layout. To use a different layout on a specific step, open the template editor and pick one from the "Email layout" dropdown.
Email layouts follow the Knock environment commit model — commit them to
your current environment before they'll appear in your email
notifications.
}
/>
## Custom layouts and styling
To create a custom layout, open the layout editor and click "Edit in code editor" to edit HTML and CSS directly. Your layout must include `{{content}}` somewhere inside its `` as that's where Knock injects the template at send time.
Layouts can also use [MJML](/integrations/email/mjml). An MJML layout must have a root `` tag instead of an HTML document, and any plain HTML inside must be wrapped in `` tags.
If you're providing a custom HTML layout for your emails, the layout must
be a valid HTML document. For MJML layouts, the layout must be a valid
MJML document with the <mjml> root tag.
}
/>
### Creating new layouts
To create a new layout, go to **Developers** > **Layouts** and click "Create layout." New layouts open in the visual editor by default; click "Edit in code editor" to switch to HTML and CSS.
### Using custom fonts
Reference custom web fonts inside your layout's `` with a `` tag. The `@import` rule is not supported:
```html
```
Many email clients don't support web fonts, so pair any custom font with a web-safe fallback.
### Using variables and brand attributes in a custom layout
Inject account- and environment-level variables into your layout with the `vars.*` namespace. This is useful for global values that are the same across all emails, like a base URL for embedded links.
Branding properties set in account settings are available under `vars.branding.*`:
| Variable | Description |
| ------------------------------------------- | -------------------------------------------------------------------------------------------- |
| `vars.branding.logo_url` | URL of the logo image for your brand. |
| `vars.branding.icon_url` | URL of the icon image for your brand. |
| `vars.branding.dark_logo_url` | URL of the logo image for dark mode. Defaults to `logo_url` if not set. |
| `vars.branding.dark_icon_url` | URL of the icon image for dark mode. Defaults to `icon_url` if not set. |
| `vars.branding.primary_color` | Primary brand color (hex). Defaults to `#000000`. |
| `vars.branding.primary_color_contrast` | Contrast color for text on primary color backgrounds (hex). Defaults to `#FFFFFF`. |
| `vars.branding.dark_primary_color` | Primary brand color for dark mode (hex). Defaults to `#FFFFFF`. |
| `vars.branding.dark_primary_color_contrast` | Contrast color for text on dark mode primary color backgrounds (hex). Defaults to `#000000`. |
With [per-tenant branding](/multi-tenancy/per-tenant-branding), Knock resolves these properties against the `tenant_id` on the workflow run, falling back to account-level branding if the tenant has none set.
### Dark mode support
The Knock default email layout supports dark mode out of the box via the `prefers-color-scheme` CSS media query.
If your default layout was created before April 21, 2026, it does not
support dark mode. Either create a new layout (which starts from Knock's
latest default) or add dark mode support to your existing layout using the
snippet below.
}
/>
To opt a custom layout in to dark mode, add color scheme meta tags, set `color-scheme` on `:root`, and override colors inside a `@media (prefers-color-scheme: dark)` block:
```html title="Adding dark mode support to a custom layout"
```
#### Swapping logos and icons in dark mode
If your logo or icon doesn't render well on a dark background, upload dark-mode versions in account branding and expose them via `vars.branding.dark_logo_url` and `vars.branding.dark_icon_url`. Render both images in your layout and toggle them with CSS:
```html title="Rendering light and dark logos"
{% assign dark_logo_url = vars.branding.dark_logo_url | default:
vars.branding.logo_url %}
```
Hide the dark image by default and swap them inside your dark mode media query:
```css title="CSS to toggle light and dark images"
.dark-img {
display: none;
visibility: hidden;
}
@media (prefers-color-scheme: dark) {
.dark-img {
display: inline !important;
visibility: visible !important;
}
.light-img {
display: none !important;
visibility: hidden !important;
}
}
```
The `
{{ content }}
```
### Defining a blank email layout
To send a template without any layout wrapper, select "No layout" in the "Email layout" dropdown in your email channel step's template settings.
## Layouts and the visual template editor
You can use the [visual template editor](/template-editor/email-templates#visual-editing-with-drag-and-drop-components) to compose your template's `content` regardless of which layout the email step uses.
Layouts already include <head> and{" "}
<body> tags, so your template shouldn't. If you're
porting email content from elsewhere, strip those tags before saving — or
select "No layout" to skip the layout wrapper entirely.
}
/>
When you insert components like buttons and dividers from the visual editor, Knock auto-generates CSS from a set of base component styles (see below), which you can override to match your design system.
The visual template editor only renders component styles in preview mode,
so any changes to base styles won't show up until you preview.
}
/>
### Updating base component styles
Visual editor components use the base styles below, which Knock auto-injects into the top of your layout's `` at runtime. To match your design system, override them in your layout's ``.
Because these styles are injected at runtime, overrides must use `!important` to win — for example, `font-size: 20px !important;` to change the `block-button-sm` font size.
```css title="Base component styles"
/* Button components */
.block-row.block-row--button_set-v1 .block-button {
display: inline-block;
box-sizing: border-box;
text-decoration: none;
-webkit-text-size-adjust: none;
}
.block-row.block-row--button_set-v1 .block-button.block-button--outline {
border-style: solid;
}
.block-row.block-row--button_set-v1 .block-button.block-button--sm {
font-size: 14px;
line-height: 20px;
min-width: 32px;
padding-top: 4px;
padding-bottom: 4px;
padding-left: 8px;
padding-right: 8px;
}
/* Divider component */
.block-row.block-row--divider-v1 .block-divider {
border-bottom: 1px solid #dddee1;
}
/* Markdown components */
.block-row.block-row--markdown-v1 .block-markdown > :first-child {
margin-top: 0;
}
.block-row.block-row--markdown-v1 .block-markdown > :last-child {
margin-bottom: 0;
}
```
## Automate layout management with the Knock CLI
You can manage layouts programmatically with the [Knock CLI](/developer-tools/knock-cli) or [Management API](/developer-tools/management-api), keeping Knock layouts in sync with files in your application code, and committing and promoting changes as [part of your CI/CD workflow](/tutorials/integrating-into-cicd).
See [Layout file structure](/cli/email-layout/file-structure) for how layout files are organized and the [Knock CLI reference](/cli/overview) for the full command set. Contact us if you have questions.
## MJML
Learn how to use MJML to build responsive email layouts and templates in Knock.
---
title: MJML support
description: Learn how to use MJML to build responsive email layouts and templates in Knock.
section: Integrations
layout: integrations
tags:
[
"mjml",
"responsive",
"email",
"layouts",
"templates",
"mobile",
"liquid",
"mj-raw",
"css inlining",
]
---
Knock supports MJML, a responsive email framework that compiles to HTML that is optimized for email clients. MJML abstracts away the complexity of table-based layouts and media queries, so you can build responsive emails that look great across devices with less code.
## MJML layouts
You can set an [email layout](/integrations/email/layouts) to use MJML. When a layout is configured for MJML, it must contain a root `` tag. The layout structure works the same as HTML layouts: the `{{content}}` variable receives the template content, and `{{footer_links}}` receives footer links when configured.
To include plain HTML within an MJML layout, wrap it in `` tags. MJML will pass through the contents of `` without compiling them, so you can use standard HTML where needed:
```mjml title="MJML layout with for HTML"
Welcome{{ content }}
```
## MJML templates
Email templates can use MJML in two ways:
1. **Full template.** Write your entire template in MJML in the code editor. MJML templates can be used with "No layout" (standalone) or within an MJML layout.
2. **Visual block editor.** Use the visual editor to compose your template. When the template or its layout is MJML, the blocks render as MJML components.
When you use an MJML template with a layout, the layout must also be MJML. When you use "No layout," the template stands alone as a complete MJML document.
## Mixing HTML and MJML
Knock automatically wraps plain HTML inside MJML templates and layouts in `` tags when the HTML appears at the ``, ``, or `` level. This means you can include HTML snippets in your MJML templates and they will render correctly.
### Ending tags
Knock skips auto-wrapping of HTML when the parent element is an MJML ending tag. Ending tags are MJML components that expect plain HTML or text content as their direct children by spec.
The following MJML tags do not have their HTML children wrapped:
- ``
- ``
- ``
- ``
- ``
- ``
- ``
- ``
- ``
- ``
HTML partials cannot
include MJML. When an HTML partial is used in an MJML template and is not
rendered as a direct child of an MJML ending tag, Knock wraps the
partial's content in <mj-raw> tags so that it renders
correctly within the MJML document.
}
/>
## Using Liquid in MJML
You can use [Liquid](/template-editor/reference-liquid-helpers) in MJML layouts and templates to render dynamic content, but where you can place it is determined by the order in which Knock compiles your MJML. Knock renders an MJML email in two steps:
1. **MJML compile.** Knock compiles your MJML document into HTML. Liquid is still unrendered text at this point.
2. **Liquid render.** At send time, Knock renders Liquid tags and variables against the compiled HTML.
Because the MJML compiler runs first, it has to parse your document with the Liquid still in it. Liquid that sits where the compiler expects an MJML component will break compilation, and your final message may not render as expected.
### Where you can use Liquid
| Location | Supported | What to do |
| ------------------------------------------------------------- | --------- | ---------------------------------------------------------------------------------- |
| Inside `` and the components below it | Yes | Write Liquid directly. No wrapping needed. |
| Inside an `` or `` block | Yes | Open and close each Liquid tag inside the same block. |
| Wrapping or outside the `` root tag | No | Branch inside ``, or create a second layout. |
| Bare at the `` level | No | Move the Liquid into an `` or `` block. |
| Wrapping ``, ``, or `` | No | Declare these without a conditional and reference them dynamically in CSS instead. |
Here's an example of an email layout using Liquid in the places it's supported:
```mjml title="Liquid in an MJML layout"
{% if vars.use_dark_mode %}
{% endif %}
{% if vars.use_dark_mode %} .email-body { background-color: #262626; } {%
endif %}
Hello {{ recipient.name }}
{{ content }} {% if recipient.support_plan_enabled %}
Need help? Contact support.
{% endif %}
```
### Troubleshooting
If a preview or email message displays raw CSS styles and `` tags as body text, this indicates an issue with MJML compilation. Check for Liquid outside the `` root, a conditional straddling an `` block, or a Liquid tag wrapping a compile-time component.
#### Common mistakes
The MJML compiler has no position for content outside the root in the document it produces, so compilation fails when you add Liquid outside the `` root tag. This also applies between `` and its `` and `` children.
```mjml title="Incorrect: a conditional wrapping the whole document"
{% if vars.use_marketing_layout %}
{% else %}
{% endif %}
```
Instead, keep one `` root and move the conditional inside ``:
```mjml title="Correct: branching inside "
{% if vars.use_marketing_layout %}
{% endif %}
{{ content }}
```
If the two shapes differ enough that a single document can't express both, create a second layout and select it on the email step.
These MJML tags are used within `` to configure the compiler's output, which means that the limitation mentioned in the table above applies. However, you can't resolve this by simply moving these tags inside an `` block and wrapping them with a condition there, because `` preserves its contents without compiling them. A tag will be emitted as literal `` markup instead of being processed by the compiler.
For example, wrapping `` in a conditional to switch fonts per brand theme won't work:
```mjml title="Incorrect: a conditional around "
{% if vars.brand_theme == "editorial" %}
{% else %}
{% endif %}
```
When the component has a plain-HTML equivalent, write that equivalent instead and keep the conditional inside an `` block. Here, `` becomes the `` tag it would have generated:
```mjml title="Correct: use and conditionally wrap HTML font imports"
{% if vars.brand_theme == "editorial" %}
{% else %}
{% endif %}
```
Alternatively, declare both fonts unconditionally so the compiler loads each one, then pick between them at send time in an `` block:
```mjml title="Correct: declare both fonts, select one conditionally in CSS"
.email-body, .email-body td {
font-family:
{% if vars.brand_theme == "editorial" %}
"Roboto Slab", Georgia, serif
{% else %}
"Inter", Helvetica, sans-serif
{% endif %};
}
```
The tradeoff to this approach is that every declared font is referenced in the final email, so recipients' email clients may load a font that the message doesn't end up using.
`` and `` have no plain-HTML equivalent. For those, declare them without a conditional and branch in CSS instead, similar to the second example above.
Both halves of a Liquid tag pair must sit inside the same block. When a conditional wraps only one of an MJML block's tags, compilation will fail.
```mjml title="Incorrect: the conditional wraps only one of the block's tags"
{% if vars.use_dark_mode %}
{% endif %} .email-body { background-color: #262626; }
```
```mjml title="Correct: the conditional is contained within a single block"
{% if vars.use_dark_mode %}
.email-body { background-color: #262626; }
{% endif %}
```
## Dark mode support in MJML layouts
MJML layouts support dark mode using the `prefers-color-scheme` media query. The Knock default MJML layout includes dark mode support out of the box, automatically swapping colors and images based on the user's system preference.
To add dark mode support to a custom MJML layout, include the color scheme meta tags in `` and define your dark mode styles in an `` block:
```mjml title="MJML layout with dark mode support"
:root { color-scheme: light dark; supported-color-schemes: light dark; }
@media (prefers-color-scheme: dark) { .email-wrapper, .email-body {
background-color: #262626 !important; } p, h1, h2, h3 { color: #ffffff
!important; } }
```
For swapping logos and icons in dark mode, see [Swapping logos and icons in dark mode](/integrations/email/layouts#swapping-logos-and-icons-in-dark-mode) in the email layouts documentation.
## Styling buttons in MJML layouts
The Knock default MJML layout styles buttons using your branding colors, with automatic dark mode support. This applies to both legacy `mj-button` components and visual editor buttons.
#### How branding colors are applied
- **Solid buttons** use `primary_color` as the background and `primary_color_contrast` as the text color.
- **Outline buttons** use a transparent background with `primary_color` as the text and border color.
- **Dark mode** uses `dark_primary_color` (defaults to `#FFFFFF`) and `dark_primary_color_contrast` (defaults to `#000000`).
```mjml title="MJML branding-aware button styling"
/* Light mode button styles */ .block-button--solid { background-color: {{
vars.branding.primary_color | default: "#000000" }}; color: {{
vars.branding.primary_color_contrast | default: "#FFFFFF" }}; }
.block-button--outline { background-color: transparent; color: {{
vars.branding.primary_color | default: "#000000" }}; border-color: {{
vars.branding.primary_color | default: "#000000" }}; } /* Dark mode overrides
*/ @media (prefers-color-scheme: dark) { .block-button--solid {
background-color: {{ vars.branding.dark_primary_color | default: "#FFFFFF" }}
!important; color: {{ vars.branding.dark_primary_color_contrast | default:
"#000000" }} !important; } .block-button--outline { background-color:
transparent !important; color: {{ vars.branding.dark_primary_color | default:
"#FFFFFF" }} !important; border-color: {{ vars.branding.dark_primary_color |
default: "#FFFFFF" }} !important; } }
```
#### Why dark mode uses `!important` overrides
The visual editor renders button colors as static inline styles that don't change between light and dark mode. To ensure buttons remain readable on dark backgrounds, the layout uses `!important` in dark mode to override these inline styles. This means per-button colors from the visual editor are respected in light mode, while dark mode enforces branding-aware colors for readability.
For more details, see [Styling buttons](/integrations/email/layouts#styling-buttons) in the email layouts documentation.
## Limitations
- **MJML layouts require the `` root tag.** Layouts set to MJML mode must be valid MJML documents, with a single `` root and no content outside it.
- **Liquid can't wrap the `` root or compile-time components.** Knock compiles MJML before it renders Liquid. See [Using Liquid in MJML](#using-liquid-in-mjml) for the placement rules.
- **Partials cannot include MJML.** [HTML partials](/template-editor/partials/html-partials) must contain HTML only. When used in an MJML template, their content is automatically wrapped in `` tags where appropriate.
## Settings and overrides
Learn more about how to configure your email channels in Knock.
---
title: Email settings and overrides
description: Learn more about how to configure your email channels in Knock.
section: Integrations
layout: integrations
tags: ["bcc", "cc", "JSON overrides", "email settings", "email overrides"]
---
Knock email channel configurations support a number of settings. These include email-specific fields (such as `cc`, `bcc`, and `reply-to`) as well as JSON overrides to be passed in API calls to the configured provider's API endpoints.
When you configure a setting in a channel's configuration, it will be used on all instances of that channel across all workflows.
## Configuring email settings
You can override email settings on a per-channel basis, or on a per-template basis.
- **At the channel level**. The `to`, `cc`, `bcc`, and `reply-to` fields can be found in the "Overrides" section of the channel's "Settings" tab.
- **At the template level**. The email settings fields can be found at the top of the email template editor.
Email-specific configuration fields support Liquid usage. You can use any variables available in your workflow trigger payloads, as well as system [variables](/template-editor/variables) such as the current workflow, activities, and any other variables you have access to when building templates.
As an example, if you wanted to conditionally change the "From name" on an email depending on whether one is configured on the actor that triggered the notification, you'd use the following liquid in the "From name" field of your email configuration.
```js title="A From name email configuration using Liquid"
{{ actor.from_name | default: "no-reply@knock.app" }}
```
Provider settings like API keys and other send-time credentials do not support dynamic values; check your specific provider's **Channel configuration** documentation for more information about supported values.
## Overriding the default `to` address
By default, Knock will send your emails to the `email` property stored on the `recipient` for the workflow run. If you need to override this, you can do so by setting the `to` field in your email configuration either at the channel or the template level.
As an example, if you wanted to send all emails to a single address, you could set the `to` field at the channel level to either a static value (like `hello@example.com`) or a dynamic value (like `{{ data.email_to_override }}`).
### Using multiple `to` addresses
It's possible to set multiple `to` addresses via an override. However, because Knock is designed to process a unique workflow run for each `recipient` in your workflow trigger, this approach comes with some caveats and limitations:
- You must always provide at least one `recipient` on your workflow trigger.
- Although you may override the `to` email addresses to send an email to more than one address in a given workflow run, that run will reference only the original `recipient`'s properties and notification preferences.
- Delivery and engagement metrics will also be associated with the original `recipient`, because all of the delivered emails will be related to a single Message record in Knock. This means that you won't be able to track per-recipient metrics for the list of email addresses in your override; they'll all be tracked by the workflow `recipient`.
- Knock does not currently support a comma-separated list of `to` addresses in the same way as we do for `cc` and `bcc` addresses (see section below). This means that you will need to provide a [JSON payload override](#provider-json-overrides) in your workflow step's configuration in order to format the `to` list according to your provider's API requirements. Please [reach out to our support team](mailto:support@knock.app) if you need help with this.
## Setting `cc` and `bcc` addresses
The `cc` and `bcc` fields can be used to support a single or multiple addresses. In order to use several addresses on any of these fields, make sure to separate them with a comma.
You can pass multiple cc and bcc addresses using workflow trigger
variables, and configure these fields to use them.
}
/>
## Provider JSON overrides
Sometimes you may want to customize the API call Knock sends to your email provider.
A good example of this is passing custom arguments as part of the API payload.
Take an example where we're using SendGrid as our email provider. SendGrid allows sending custom arguments under the
`custom_args` key of the JSON payload of their API. By default, Knock sends some arguments using that key, such
the Knock message id. If you want to add more arguments, you can check the following image on how to add them as
JSON overrides:
Configuring email channel JSON overrides.
In this example, we want to add two arguments to the `custom_args` attribute of the
API call we send to SendGrid. In this case, the first argument will be hardcoded,
and the second argument's value will be the value of `dynamic_value`, which we
expect to be passed in the payload of the workflow trigger call.
## Sending attachments
Learn more about how to send emails with attachments in Knock.
---
title: Email attachments
description: Learn more about how to send emails with attachments in Knock.
section: Integrations
layout: integrations
---
## How attachments work in Knock
1. Set an attachment key in your email template to tell Knock how to resolve attachments you send in the data payload of your trigger call. To set an attachment key, click the gear icon (⚙️) at the top of the email template editor, then set your desired key under the "Attachment key" field. This key will default to `attachments` if not specified.
2. Include one or more attachment objects in the `data` payload of your trigger call, under the configured attachment key. Each attachment object should have the content of the file to be attached as a base64 encoded value.
3. Knock automatically adds any attachments included in the attachment key of your trigger call to the emails sent by your email provider.
## The attachment object
Every attachment you send to Knock in your `data` payload should include the following properties (those marked with an `*` are required):
| Property | Description |
| ---------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `name`\* | The name of the file |
| `content_type`\* | A mime type for the file |
| `content`\* | The base64-encoded file content. Attachments count toward the 10MB trigger payload limit, which applies to the full request. Note that some email providers may enforce stricter limits. |
| `content_id` | An optional unique `Content-ID` for the attachment. Currently only supported for SendGrid, Postmark, and Resend. See Referencing attachment files inline for more details. |
| `disposition` | An optional disposition for the attachment (`inline` or `attachment`). Currently only supported for SendGrid and Postmark. |
```js title="An example attachment object"
{
name: "my-file.txt",
content: myFileContent,
content_type: "text/plain"
}
```
## Sending attachments in your trigger call
Once you've specified your attachment key in your email template, include the base64-encoded attachment data in the `data` payload of your trigger call. To send multiple attachments, pass an array of attachment objects under the attachment key.
## Sending a different attachment per recipient
If you need to send a different attachment per recipient in a workflow then you'll need to make one trigger call per recipient, such that the data payload is unique to that recipient.
```js title="Unique attachments per recipient"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
const filesAndRecipients = [
{ id: "user-1", file: user1FileContents },
{ id: "user-2", file: user2FileContents },
];
filesAndRecipients.forEach(({ id, file }) => {
knock.workflows.trigger("my-workflow", {
recipients: [id],
data: {
attachment: {
name: "Invoice.pdf",
content_type: "application/pdf",
content: file,
},
},
});
});
```
## Referencing attachment files inline
If you're using [SendGrid](/integrations/email/sendgrid) or [Postmark](/integrations/email/postmark) as your email provider, you can set attachment files to be inline in your email messages by providing a `disposition` property of `inline` on the attachment object you send in your trigger call.
[Resend](/integrations/email/resend) supports inline images (see below), but does not allow you to explicitly set the disposition of an attachment.
### Inline image attachments
When using Resend, you can reference images inline without setting a{" "}
disposition property on the attachment object.
}
/>
To attach image files to your email and reference them inline, add a `content_id` and `disposition` to the attachment object. You can then reference the attachment in your template using the `cid:` prefix and the `content_id` value.
```js title="An example inline image attachment"
{
name: "my-image.png",
content_type: "image/png",
content: imageContent,
content_id: "my-attachment",
disposition: "inline"
}
```
```html title="Referencing an attachment file inline"
```
### Inline calendar invitations
To set calendar files to be inline in your email message, add a `disposition` property of `inline` on the attachment object you send in your trigger call.
```js title="An example attachment object for an inline calendar invitation"
{
name: "invite.ics",
content_type: "text/calendar; charset=utf-8; method=REQUEST",
content: calendarContent,
disposition: "inline"
}
```
We also recommend that your `.ics` file include the following parameters for the best email client support:
- `METHOD:REQUEST`
- `RSVP=TRUE;ROLE=REQ-PARTICIPANT;PARTSTAT=NEEDS-ACTION` (on the `ATTENDEE`, to enable RSVPs)
## Sending attachments with batched workflows
If you trigger a batched workflow with attachment files, email steps after
the batch step will only include the attachment file(s) from the first
activity in the batch.
}
/>
When a workflow includes a [batch step](/designing-workflows/batch-function), only the attachment(s) from the activity that **opened the batch window** will be included in email messages that are sent after the batch window closes. Attachments from subsequent `activities` that are added to the batch will not be included.
To send a single email that includes an attachment file for each batched activity, use a [fetch function](/designing-workflows/fetch-function) step placed after your batch step to collect them once the window closes:
1. **Trigger the workflow per item with identifiers, not file content.** Include a reference to each attachment (such as an ID or URL) in your `data` payload rather than the base64-encoded file content.
2. **Batch by recipient.** Group the per-item triggers using your batch step as you normally would.
3. **Add a fetch step after the batch step.** Using the `activities` array to enumerate every batched item, call back to your service to retrieve a single array of attachment objects under one key. The data returned by the fetch step is merged into the workflow run's `data` and made available to the email channel step that follows.
4. **Point your template's attachment key at the fetched data.** Set the email template's attachment key to [the response path key](/designing-workflows/fetch-function#specifying-the-response-path) that you configured on the fetch step so that all of the collected files are sent with the email. If you don't specify a response path, the fetch step's response data will be merged into the workflow run's `data` at the top level.
The fetch step's request body is a Liquid-compatible input, so you can loop over the `activities` array to build the list of identifiers to send to your service:
```liquid title="Fetch step request body: collecting attachment IDs from the batch"
{
"attachment_ids": [
{% for activity in activities %}
"{{ activity.attachment_id }}"{% unless forloop.last %},{% endunless %}
{% endfor %}
]
}
```
Your service then returns the assembled attachments, which Knock merges into the workflow run's `data`:
```json title="Response data returned by your service"
{
"attachments": [
{
"name": "invoice-1.pdf",
"content_type": "application/pdf",
"content": ""
},
{
"name": "invoice-2.pdf",
"content_type": "application/pdf",
"content": ""
}
]
}
```
In the example above, if no response path key is specified on the fetch step these returned `attachments` will be available under `data.attachments`. This matches the default attachment key for newly-created email templates.
While the example above shows how you can send a single email that
includes an attachment for every batched activity, you should
be aware that email providers and your users' email clients have size
limits on email messages, often between 10MB and 25MB. If you're sending a
large number of attachments, you may need to send multiple emails or use a
different approach, such as sending a single email with links to hosted
files.
}
/>
## Previewing messages with attachments
The Knock dashboard does not currently support previewing the attachment files that are sent with your email messages. This means that you'll need to send a test message (via the [workflow test runner](/send-notifications/testing-workflows) or the API) to your own email inbox to see what the attachment(s) will look like.
This limitation applies to both regular attachment files and inline attachments. Any images that are sent as inline attachments will not be viewable in the dashboard.
## Client previews
Preview your email notifications across different email clients directly in the Knock editor.
---
title: Email client previews
description: Preview your email notifications across different email clients directly in the Knock editor.
section: Integrations > Email
layout: integrations
---
Email client previews are available on all paid plans (Starter and up).
}
/>
## Overview
Email client previews allow you to test how your email notifications will render across different email clients. This feature is embedded directly in the Knock template editor, using Litmus technology to generate accurate previews without requiring you to leave the editor or send test emails.
## Features
- Preview emails in popular clients including Gmail, Outlook, and Apple Mail.
- Access previews directly within the Knock template editor.
- View rendering across multiple desktop and mobile email clients.
- Preview emails in dark mode for supported clients (Outlook for Windows, iOS Outlook, Android Outlook, iOS Gmail, Android Gmail, and Apple Mail).
## Using email client previews
To access and use email client previews:
1. Open the workflow template editor for an email channel.
2. Make sure the preview pane is opened. By default, you'll see the "in browser" preview.
3. Use the toggle option at the top of the preview pane to switch to "client previews."
4. Click on any email client thumbnail to see an expanded view.
This feature uses the Litmus Instant API to generate client-specific previews.
## Knock test emails
Start testing with Knock's built-in email channel.
---
title: Send email with Knock's built-in test channel
description: Start testing with Knock's built-in email channel.
section: Integrations > Email
layout: integrations
---
Knock comes with a built-in email channel to test your email notifications. This is a great way to explore Knock and start testing email notifications before integrating your [email provider of choice](/integrations/email/overview#supported-providers).
This provider is for testing purposes only. Sending is limited to email
addresses associated with the{" "}
members
{" "}
of your Knock account.
}
/>
## Features
- 100 emails per month
- Attachments support
- Delivery tracking
- Bounce support
- Knock link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
You'll find the Knock test channel under the **Channels and sources** page in your account settings. By default, all new Knock accounts will have the channel enabled and ready to use across all environments with no additional configuration required.
### Allowed recipients
The Knock test channel is limited to sending emails to email addresses associated with the **[members](/manage-your-account/managing-members) of your Knock account only**. Attempting to send emails to email addresses that are not associated with a member will result in a delivery error (`knock_recipient_not_allowed`).
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your channel. When enabled, no emails will be sent to your recipients.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings**
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Recipient data requirements
To send an email notification you'll need a valid `email` property set on your recipient.
## Delivery tracking
Delivery tracking can result in the following status updates to your message:
- The message delivery is confirmed and Knock updates the message to `delivered`
- The message was not delivered due to a bounce and Knock updates the message to `bounced`
## Frequently asked questions
You can send up to 100 emails per month for free.
You can only send emails to email addresses that are associated with the [**members**](/manage-your-account/managing-members) of your Knock account. Attempting to send emails to email addresses that are not associated with a member will result in a delivery error.
If you exceed the monthly limit, your emails will be marked as `undelivered`
and will not be sent to the recipient. You will be able to send emails again
at the start of the next month.
You can use the Knock test channel to send email notifications to your
users. To do this, you'll need to create a new workflow or broadcast and add
a step that uses the Knock test channel.
No, this provider is for testing purposes only and is not intended for
production use. For production use, please configure a different provider.
Once you've setup a production email channel, you can change the channel on each of your existing email steps in your workflows to use the new provider. You'll need to commit and promote those changes in order for them to take effect.
## Amazon SES
How to send transactional email notifications to Amazon SES with Knock.
---
title: How to send email with Amazon SES
description: How to send transactional email notifications to Amazon SES with Knock.
tags: ["simple email service", "amazon", "aws", "ses"]
section: Integrations > Email
layout: integrations
---
Knock integrates with Amazon Simple Email Service (Amazon SES) to send email notifications to your users. This page walks through how to get started with SES, including provider configurations and additional data you can pass through to SES.
## Features
- Attachments support
- Knock link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
You can create a new Amazon SES channel in the dashboard under **Channels and sources** in your account settings. From there, you'll need to take some steps in AWS before you can configure your SES channel within Knock.
You'll need to verify the **"From" email address** you plan on using to send emails with AWS if you haven't already. To do so, follow the steps outlined in AWS's documentation on creating and verifying an email address identity.
Knock supports two authentication schemes with Amazon SES:
To send notifications via Amazon SES using an IAM User, Knock requires the **access key ID** and a **secret access key** of an AWS user with SES send permissions. (Specifically, the `ses:SendEmail` and `ses:SendRawEmail` permissions.)
If you don't already have a user with send permissions, you can create an IAM user in AWS to use with the Knock API. You can learn more about creating IAM users in AWS here.
Once you've created your new IAM user, you'll need to provision them with the policy below.
```json title="IAM user policy"
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Action": ["ses:SendEmail", "ses:SendRawEmail"],
"Resource": "*"
}
]
}
```
Now that you have an AWS user created and provisioned with SES send access, grab the **access key ID** and a **secret access key** of the user—we'll use these later when configuring the SES channel within Knock.
To send notifications via Amazon SES by delegating an IAM Role in your AWS account to Knock, secured with an External ID:
1. Create a new AWS Role:
- For "Trusted Entity Type" choose "AWS Account."
- Select "Another AWS account" and put "496685847699" in the Account ID.
- Check "Require external ID" and enter the ID of the SES channel you created in your Knock dashboard.
2. Attach the following permission policy to that role.
```json title="IAM user policy"
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Action": ["ses:SendEmail", "ses:SendRawEmail"],
"Resource": "*"
}
]
}
```
3. Use that role's ARN when configuring your Amazon SES channel in Knock.
4. Enable Security Token Service (STS) for the `us-east-2` region in your AWS account. This enables Knock to generate temporary security credentials for sending email via SES. For more information, review the AWS documentation on enabling STS for another region.
Now that you have a verified "From" address and either an AWS User's credentials or an AWS IAM Role to delegate to Knock, you're ready to [configure your SES channel](#channel-configuration) in the Knock dashboard under the **Channels and sources** page in your account settings.
Here are a few other things to keep in mind once you have your SES channel configured in Knock:
- **SES sandbox mode.** By default, AWS places all new accounts in the SES sandbox. While your account is in the sandbox, you can only send emails to verified email address—keep this in mind if you're testing in development before you've moved your account out of the SES sandbox. For more information on the SES sandbox and how to move your account out of it, see the SES sandbox documentation.
- **Deliverability tracking.** By default, SES channels do not track delivery beyond "Sent". However, you can enable [delivery status webhooks](#delivery-status-webhooks) to receive real-time updates about email delivery and bounces.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your Amazon SES [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your SES channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for Amazon SES**
- **AWS region** (`enum*`) - The region of your verified domain.
- **Authentication scheme** (`enum*`) - The authentication scheme (Access Key or External ID) to use for your SES channel.
- **Access key ID** (`string*`) - The access key ID from your AWS account. Required when using Access Key authentication.
- **Secret access key** (`string*`) - The secret access key from your AWS account. Required when using Access Key authentication.
- **AWS IAM Role ARN to assume** (`string*`) - The ARN of the role in your AWS Account that this channel will use. Required when using External ID authentication.
- **External ID** (`string*`) - The external ID for your AWS IAM Role. Required when using External ID authentication.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Additional data sent
Knock sends the following attributes along with your emails (all as `Tags`):
- `Sender`: always set to `knock.app`
- `knock_message_id`: the ID of the message this email is associated with
- `knock_workflow`: the key of the workflow this message was generated from
- `knock_recipient_id`: the Knock ID of the recipient this email is being sent to
You can learn about the role of these SES attributes in the Amazon SES API documentation.
Amazon SES tags are limited to 256 characters and can only contain ASCII
letters (a-z, A-Z), numbers (0-9), underscores (_), or dashes (-). If your{" "}
knock_recipient_id does not meet these requirements, Knock
will truncate knock_recipient_id to 256 characters and remove
any prohibited characters. See the{" "}
AWS Docs
{" "}
for more information.
}
/>
## Recipient data requirements
In order to send an email notification you'll need a valid `email` property set on your recipient.
## Delivery status webhooks
When enabled, SES will send delivery status updates directly to Knock via webhooks, allowing you to track the full lifecycle of your email messages.
### Prerequisites
Before enabling delivery status webhooks, you need:
1. A verified domain or email address in Amazon SES
2. An SES channel configured in Knock (see the [getting started](#getting-started) section above)
3. Access to AWS SNS (Simple Notification Service) configuration
### Setting up delivery status webhooks
1. Navigate to **Channels and sources** in your Knock dashboard
2. Select your Amazon SES channel
3. Click "Manage configuration" for the environment you want to configure
4. Scroll to the "Incoming message status updates" section and enable incoming webhooks
6. Copy the generated webhook URL - you'll need this in the next step
In the AWS Console, configure an SNS topic to receive SES notifications:
1. Go to the **SNS Console** in AWS
2. Create a new SNS topic (or use an existing one) for SES notifications
3. Configure the topic to send notifications for:
- **Delivery** notifications
- **Bounce** notifications
4. Add an HTTPS subscription to the topic with the webhook URL from Knock
5. Knock will automatically confirm the subscription
In the AWS SES Console, configure your verified domain or email to publish events to SNS:
1. Go to **Verified identities** in the SES Console
2. Select the domain or email address you're using with Knock
3. Go to the **Notifications** tab
4. Under **Feedback notifications**, configure:
- **Bounces**: Select your SNS topic
- **Deliveries**: Select your SNS topic
5. Save your configuration
### Supported delivery statuses
When delivery status webhooks are enabled for SES, Knock will update message statuses based on these SES events:
| SES Event Type | Knock Status | Description |
| -------------- | ------------ | ------------------------------------------------------------------- |
| Delivery | `delivered` | The email was successfully delivered to the recipient's mail server |
| Bounce | `bounced` | The bounced due to invalid recipient or domain |
### Troubleshooting
If delivery status updates aren't appearing in Knock:
1. **Check SNS subscription status.** Verify the subscription is "Confirmed" in the AWS SNS console.
2. **Verify SNS topic configuration.** Ensure the SNS topic is correctly configured for Bounce, Complaint, and Delivery notifications.
3. **Check SES notification settings.** Confirm your verified identity is publishing to the correct SNS topic.
4. **Test with verified addresses.** If in SES sandbox mode, ensure you're sending to verified addresses.
If you're having trouble setting up delivery status webhooks, contact our
support team at support@knock.app.
}
/>
## Cloudflare Email
How to send transactional email notifications with Cloudflare Email Service and Knock.
---
title: How to send email with Cloudflare Email
description: How to send transactional email notifications with Cloudflare Email Service and Knock.
tags: ["cloudflare", "email", "email service", "transactional"]
section: Integrations > Email
layout: integrations
---
Knock supports using Cloudflare Email Service to send email notifications to your users.
Cloudflare Email Service requires your domain's DNS to be configured
correctly on Cloudflare. See{" "}
Email Service domain configuration
{" "}
for DNS record details.
}
/>
Cloudflare Email Service does not currently support delivery status
tracking. Knock will not receive bounce or delivery confirmation events
from Cloudflare for messages sent through this channel.
}
/>
## Features
- Knock link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
1. In the Cloudflare dashboard, create an **API token** (or use a compatible **API key**) with permission to send email for your account, and copy your Cloudflare **account ID**. See Cloudflare's API token documentation and how to find your account ID.
2. In Knock, open **Channels and sources** in your account settings and create a **Cloudflare Email** channel.
3. For each [environment](/concepts/environments), open **Manage configuration** on the channel and enter your **Account ID** and **API key** (your Cloudflare API token or key), plus your default **From** address and optional **From** name. Use addresses on domains you have verified for sending in Cloudflare.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your Cloudflare Email [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your Cloudflare Email channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for Cloudflare Email**
- **Account ID** (`string*`) - Your Cloudflare account ID. Used with Cloudflare's email sending API.
- **API key** (`string*`) - Your Cloudflare API token or API key with permission to send email for this account.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags). Must use a domain you have configured for sending in Cloudflare.
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. See [Settings and overrides](/integrations/email/settings) for more on email channel overrides.
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Recipient data requirements
To send an email notification you'll need a valid `email` property set on your recipient.
## MailerSend
How to send transactional email notifications to MailerSend with Knock.
---
title: How to send email with MailerSend
description: How to send transactional email notifications to MailerSend with Knock.
section: Integrations > Email
layout: integrations
---
Knock integrates with MailerSend to send email notifications to your users. This page describes how to get started with MailerSend in Knock, including necessary provider configurations and additional data you can pass through to MailerSend.
## Features
- Attachments support
- Delivery tracking
- Bounce Support
- Knock link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
You can create a new MailerSend channel in the dashboard under the **Channels and sources** page in your account settings. From there, you'll need to configure the channel for each environment you have.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your MailerSend [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your MailerSend channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for MailerSend**
- **API key** (`string*`) - The API key for your MailerSend account.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Recipient data requirements
In order to send an email notification you'll need a valid `email` property set on your recipient.
## Delivery tracking
Delivery tracking for MailerSend can result in the following status updates to your message:
- The message delivery is confirmed and Knock updates the message to `delivered`
- The message was not delivered due to bad recipient(s) and Knock updates the message to `bounced`
## Mailgun
How to send transactional email notifications to Mailgun with Knock.
---
title: How to send email with Mailgun
description: How to send transactional email notifications to Mailgun with Knock.
section: Integrations > Email
layout: integrations
---
Knock integrates with Mailgun to send email notifications to your users. This page describes how to get started with Mailgun in Knock, including necessary provider configurations and additional data you can pass through to Mailgun.
## Features
- Attachments support
- Delivery tracking
- Bounce Support
- Knock link and open tracking
- Mailgun link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
You can create a new Mailgun channel in the dashboard under the **Channels and sources** page in your account settings. From there, you'll need to configure the channel for each environment you have.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your Mailgun [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your Mailgun channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for Mailgun**
- **API key** (`string*`) - The private API key for your Mailgun account.
- **Domain** (`string*`) - The domain verified with Mailgun for sending emails.
- **Mailgun region** (`enum*`) - The sending region (US or EU) for your Mailgun account.
- **Open tracking** (`boolean`) - Whether to enable Mailgun email-open tracking.
- **Link tracking** (`boolean`) - Whether to enable Mailgun link-click tracking.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Additional data sent
Knock sends the following attributes to Mailgun along with your emails:
- `v:sender`: always set to `knock.app`
- `v:knock_message_id`: the ID of the message this email is associated with
- `v:knock_recipient_id`: the Knock ID of the recipient this email is being sent to
- `o:tag`: the workflow key for the workflow being invoked
You can learn about the role of these Mailgun attributes in the Mailgun API documentation.
## Recipient data requirements
In order to send an email notification you'll need a valid `email` property set on your recipient.
## Delivery status webhooks
When enabled, Mailgun will send delivery status updates directly to Knock via webhooks, allowing you to track the full lifecycle of your email messages in real-time.
### Prerequisites
Before enabling delivery status webhooks, you need:
1. A verified domain in Mailgun
2. A Mailgun channel configured in Knock (see the [getting started](#getting-started) section above)
3. Access to your Mailgun domain webhook settings
### Setting up delivery status webhooks
1. Navigate to **Channels and sources** in your Knock dashboard
2. Select your Mailgun channel
3. Click "Manage configuration" for the environment you want to configure
4. Scroll to the "Incoming message status updates" section and enable incoming webhooks
5. Copy the generated webhook URL - you'll need this in the next step
In the Mailgun dashboard, configure webhooks to send delivery events to Knock:
1. Go to **Sending > Webhooks** in your Mailgun dashboard
2. Select the domain you're using with Knock
3. Add the webhook URL from Knock to these webhook types:
- **Delivered messages** - Click "Add webhook URL", paste the Knock webhook URL, and save
- **Permanent failure** - Click "Add webhook URL", paste the Knock webhook URL, and save
4. Mailgun will automatically begin sending events to Knock
### Supported delivery statuses
When delivery status webhooks are enabled for Mailgun, Knock will update message statuses based on these Mailgun webhook events:
| Mailgun Event Type | Knock Status | Description |
| ------------------ | ------------ | ------------------------------------------------------------------- |
| delivered | `delivered` | The email was successfully delivered to the recipient's mail server |
| failed | `bounced` | The email failed permanently due to invalid recipient or domain |
### Troubleshooting
If delivery status updates aren't appearing in Knock:
1. **Check webhook configuration.** Verify both "Delivered messages" and "Permanent failure" webhooks are configured with the correct Knock webhook URL for your domain.
2. **Verify domain.** Ensure you're sending from a verified domain in Mailgun that matches the domain configured in your webhooks.
3. **Check webhook region.** Ensure your Mailgun region (US or EU) matches the region configured in your Knock channel settings.
4. **Test webhooks.** Send a test email and check the Webhooks page in Mailgun to verify events are being sent.
5. **Review webhook logs.** Check the webhook logs in Mailgun to see if requests are being sent successfully.
If you're having trouble setting up delivery status webhooks, contact our
support team at support@knock.app.
}
/>
## Passing additional tags to Mailgun
It's possible to pass additional tags to Mailgun by setting the "JSON overrides" attribute in the channel configuration or at the message template level.
To pass one or more tags, you can set the `o:tag` attribute to an array of tag names:
```json
{
"o:tag": ["tag1", "{{ workflow.key }}"]
}
```
## Mailjet
How to send transactional email notifications to Mailjet with Knock.
---
title: How to send email with Mailjet
description: How to send transactional email notifications to Mailjet with Knock.
section: Integrations > Email
layout: integrations
---
Knock integrates with Mailjet to send email notifications to your users. This page describes how to get started with Mailjet in Knock, including necessary provider configurations and additional data you can pass through to Mailjet.
## Features
- Attachments support
- Delivery tracking
- Knock link and open tracking
- Mailjet link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
You can create a new Mailjet channel in the dashboard under the **Channels and sources** page in your account settings. From there, you'll need to configure the channel for each environment you have.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your Mailjet [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your Mailjet channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for Mailjet**
- **API key** (`string*`) - The public API key for your Mailjet account.
- **API secret key** (`string*`) - The secret API key for your Mailjet account.
- **Open tracking** (`boolean`) - Whether to enable Mailjet email-open tracking.
- **Link tracking** (`boolean`) - Whether to enable Mailjet link-click tracking.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Additional data sent
Knock sends the following attributes along with your emails:
- `CustomID`: the Knock `message_id` associated with this email.
You can learn about the role of this Mailjet attribute in the Mailjet API documentation.
## Recipient data requirements
In order to send an email notification you'll need a valid `email` property set on your recipient.
## JSON overrides behavior
For this provider, we will merge the JSON overrides with the first object under the `"Messages"` attribute.
## Mailtrap
How to send transactional email notifications to Mailtrap with Knock.
---
title: How to send email with Mailtrap
description: How to send transactional email notifications to Mailtrap with Knock.
section: Integrations > Email
layout: integrations
---
Knock integrates with Mailtrap to send email notifications to your users. This page describes how to get started with Mailtrap in Knock, including necessary provider configurations and additional data you can pass through to Mailtrap.
## Features
- Attachments support
- Delivery tracking
- Knock link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
You can create a new Mailtrap channel in the dashboard under the under the **Channels and sources** page in your account settings. From there, you'll need to configure the channel for each environment you have.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your Mailtrap [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your Mailtrap channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for Mailtrap**
- **API key** (`string*`) - The API key for your Mailtrap account.
- **API** (`enum*`) - Which Mailtrap API (Sending or Testing) to use.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Additional data sent
Knock sends the following attributes along with your emails:
- `custom_variables.knock_message_id`: the ID of the message this email is associated with
- `custom_variables.knock_recipient_id`: the Knock ID of the recipient this email is being sent to
## Recipient data requirements
To send an email notification you'll need a valid `email` property set on your recipient.
## Mandrill
How to send transactional email notifications to Mandrill with Knock.
---
title: How to send email with Mandrill
description: How to send transactional email notifications to Mandrill with Knock.
section: Integrations > Email
layout: integrations
---
Knock integrates with Mandrill to send email notifications to your users. This page describes how to get started with Mandrill in Knock, including necessary provider configurations and additional data you can pass through to Mandrill.
## Features
- Attachments support
- Delivery tracking
- Knock link and open tracking
- Mandrill link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
You can create a new Mandrill channel in the dashboard under the under the **Channels and sources** page in your account settings. From there, you'll need to configure the channel for each environment you have.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your Mandrill [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your Mandrill channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for Mandrill**
- **API key** (`string*`) - The API key for your Mandrill account.
- **Open tracking** (`boolean`) - Whether to enable Mandrill email-open tracking.
- **Link tracking** (`boolean`) - Whether to enable Mandrill link-click tracking.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Additional data sent
Knock sends the following attributes along with your emails:
- `metadata.knock_message_id`: the ID of the message this email is associated with
- `metadata.knock_recipient_id`: the Knock ID of the recipient this email is being sent to
## Recipient data requirements
In order to send an email notification you'll need a valid `email` property set on your recipient.
## Postmark
How to send transactional email notifications to Postmark with Knock.
---
title: How to send email with Postmark
description: How to send transactional email notifications to Postmark with Knock.
section: Integrations > Email
layout: integrations
---
Knock integrates with Postmark to send email notifications to your users. This page describes how to get started with Postmark in Knock, including necessary provider configurations and additional data you can pass through to Postmark.
## Features
- Attachments support
- Delivery tracking
- Bounce Support
- Knock link and open tracking
- Postmark link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
You can create a new Postmark channel in the dashboard under the **Channels and sources** page in your account settings. From there, you'll need to configure the channel for each environment you have.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your Postmark [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your Postmark channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for Postmark**
- **API key** (`string*`) - The API key for your Postmark server.
- **Open tracking** (`boolean`) - Whether to enable Postmark email-open tracking.
- **Link tracking** (`boolean`) - Whether to enable Postmark link-click tracking.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Additional data sent
Knock sends the following attributes along with your emails:
- `Metadata.sender`: always set to `knock.app`
- `Metadata.knock_message_id`: the ID of the message this email is associated with
- `Metadata.knock_recipient_id`: the Knock ID of the recipient this email is being sent to
- `Tag`: the key of the workflow this message was generated from
You can learn about the role of these Postmark attributes in the Postmark API documentation.
## Recipient data requirements
In order to send an email notification you'll need a valid `email` property set on your recipient.
## Delivery status webhooks
When enabled, Postmark will send delivery status updates directly to Knock via webhooks, allowing you to track the full lifecycle of your email messages in real-time.
### Prerequisites
Before enabling delivery status webhooks, you need:
1. A verified sender signature or domain in Postmark
2. A Postmark channel configured in Knock (see the [getting started](#getting-started) section above)
3. Access to your Postmark server webhook settings
### Setting up delivery status webhooks
1. Navigate to **Channels and sources** in your Knock dashboard
2. Select your Postmark channel
3. Click "Manage configuration" for the environment you want to configure
4. Scroll to the "Incoming message status updates" section and enable incoming webhooks
5. Copy the generated webhook URL - you'll need this in the next step
In the Postmark dashboard, configure webhooks to send delivery events to Knock:
1. Go to your Postmark server and select the server you're using with Knock
2. Navigate to the **Webhooks** tab
3. Add the webhook URL from Knock to both webhook configurations:
- **Delivery webhook** - Add the Knock webhook URL and click "Save delivery webhook"
- **Bounce webhook** - Add the Knock webhook URL and click "Save bounce webhook"
4. Postmark will automatically begin sending events to Knock
### Supported delivery statuses
When delivery status webhooks are enabled for Postmark, Knock will update message statuses based on these Postmark webhook events:
| Postmark Event Type | Knock Status | Description |
| ------------------- | ------------ | ------------------------------------------------------------------- |
| Delivery | `delivered` | The email was successfully delivered to the recipient's mail server |
| Bounce | `bounced` | The email bounced due to invalid recipient or domain |
### Troubleshooting
If delivery status updates aren't appearing in Knock:
1. **Check webhook configuration.** Verify both the Delivery and Bounce webhooks are configured with the correct Knock webhook URL in your Postmark server settings.
2. **Verify sender signature.** Ensure you're sending from a verified sender signature or domain in Postmark.
3. **Check Postmark activity.** Review the Activity page in Postmark to ensure emails are being sent successfully.
If you're having trouble setting up delivery status webhooks, contact our
support team at support@knock.app.
}
/>
## Using overrides to customize notifications
We provide full support for [overriding the payload](/email/settings#provider-json-overrides) of your email notifications. This enables you to customize the API request that Knock sends to Postmark on your behalf.
### Targeting a specific `MessageStream`
Knock does not target a specific `MessageStream` when sending your transactional email notifications to Postmark. This means that Postmark defaults your notifications to the `"outbound"` transactional stream.
For marketing use cases such as newsletters or product updates sent to large recipient lists, and particularly when leveraging Knock's [broadcasts](/concepts/broadcasts) feature, we recommend following Postmark's best practices for sending promotional messaging via a separate `MessageStream`.
Configure a `Broadcast`-type message stream in your Postmark account. Read more about the `MessageStream` API here.
Set a payload override in Knock with the ID of the `MessageStream` that you'd like to target. This can be done at either the channel configuration level or directly in the settings of your workflow's email channel step:
```json title="Payload override to target a broadcast MessageStream"
{
"MessageStream": "broadcasts"
}
```
## Resend
How to send transactional email notifications to Resend with Knock.
---
title: How to send email with Resend
description: How to send transactional email notifications to Resend with Knock.
section: Integrations > Email
layout: integrations
---
Knock integrates with Resend to send email notifications to your users. This page describes how to get started with Resend in Knock, including necessary provider configurations and additional data you can pass through to Resend.
## Features
- Attachments support
- Delivery tracking
- Bounce support
- Knock link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
You can create a new Resend channel in the dashboard under the **Channels and sources** page in your account settings. From there, you'll need to configure the channel for each environment you have.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your Resend [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your Resend channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for Resend**
- **API key** (`string*`) - The API key for your Resend account, available from your Resend dashboard.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Recipient data requirements
To send an email notification you'll need a valid `email` property set on your recipient.
## Debugging common errors
### `Identity not found`
If you see an `Identity not found` error in your delivery logs this is because you need to verify your sending domain with Resend (the `From email address`).
## Delivery status webhooks
When enabled, Resend will send delivery status updates directly to Knock via webhooks, allowing you to track the full lifecycle of your email messages in real-time.
### Prerequisites
Before enabling delivery status webhooks, you need:
1. A verified domain in Resend
2. A Resend channel configured in Knock (see the [getting started](#getting-started) section above)
3. Access to your Resend dashboard webhook settings
### Setting up delivery status webhooks
1. Navigate to **Channels and sources** in your Knock dashboard
2. Select your Resend channel
3. Click "Manage configuration" for the environment you want to configure
4. Scroll to the "Incoming message status updates" section and enable incoming webhooks
5. Copy the generated webhook URL - you'll need this in the next step
In the Resend dashboard, configure webhooks to send delivery events to Knock:
1. Go to the Webhooks section in your Resend dashboard
2. Click "Add Endpoint"
3. Paste the webhook URL from Knock
4. Select the events you want to track:
- **email.delivered** - Tracks successful delivery
- **email.bounced** - Tracks bounce events
5. Click "Add Endpoint" to save
6. Resend will automatically verify the endpoint
### Supported delivery statuses
When delivery status webhooks are enabled for Resend, Knock will update message statuses based on these Resend webhook events:
| Resend Event Type | Knock Status | Description |
| ----------------- | ------------ | ------------------------------------------------------------------- |
| email.delivered | `delivered` | The email was successfully delivered to the recipient's mail server |
| email.bounced | `bounced` | The email bounced due to invalid recipient or domain |
### Troubleshooting
If delivery status updates aren't appearing in Knock:
1. **Check webhook endpoint status.** Verify the endpoint shows as "Active" in the Resend webhooks dashboard.
2. **Verify event selection.** Ensure you've enabled both `email.delivered` and `email.bounced` events.
3. **Test with verified domains.** Ensure you're sending from a verified domain in Resend.
4. **Check webhook payload.** Review webhook delivery logs in Resend to ensure events are being sent.
If you're having trouble setting up delivery status webhooks, contact our
support team at support@knock.app.
}
/>
## SendGrid
How to send transactional email notifications to SendGrid with Knock.
---
title: How to send email with SendGrid
description: How to send transactional email notifications to SendGrid with Knock.
section: Integrations > Email
layout: integrations
---
Knock integrates with SendGrid to send email notifications to your users. This page describes how to get started with SendGrid in Knock, including necessary provider configurations and additional data you can pass through to SendGrid.
## Features
- Attachments support
- Delivery tracking
- Bounce support
- Knock link and open tracking
- SendGrid link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
### Connect SendGrid to Knock
You can create a new SendGrid channel in the dashboard under the **Channels and sources** page in your account settings. From there, you'll need to configure the channel for each environment you have.
Here are a few things to note as you configure your SendGrid provider:
- **API key.** At a minimum, Knock needs an API key with full access to the **Mail Send** permission. For webhook-based delivery tracking (recommended), no additional permissions are needed. If you're using polling-based delivery tracking, you'll need to provide an API key with read access to the **Email Activity** permission (requires a SendGrid paid add-on).
- **Delivery tracking.** We recommend using webhook-based delivery tracking, which provides real-time updates without requiring the Email Activity add-on. See the [delivery status webhooks](#delivery-status-webhooks) section below for setup instructions.
- **Enable email open tracking.** If enabled, you can go to the email activity page in SendGrid to check the open status of a given email.
- **Enable email link tracking.** If enabled, you can go to the email activity page in SendGrid to check the link open status of a given email.
If you choose to enable open and link tracking, please keep user privacy top of mind and follow the privacy guidelines outlined in SendGrid's documentation.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your SendGrid [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your SendGrid channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for SendGrid**
- **API key** (`string*`) - The API key for your SendGrid account.
- **Check delivery status** (`boolean`) - When set will attempt to check for the delivery status of a message. Only available with SendGrid's Email Activity add-on.
- **Open tracking** (`boolean`) - Whether to enable SendGrid email-open tracking.
- **Link tracking** (`boolean`) - Whether to enable SendGrid link-click tracking.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Additional data sent
Knock sends the following attributes along with your emails:
- `custom_args.sender`: always set to `knock.app`
- `custom_args.knock_message_id`: the ID of the message this email is associated with
- `custom_args.knock_recipient_id`: the Knock ID of the recipient this email is being sent to
- `tags[0]`: the key of the workflow this message was generated from
You can learn about the role of these SendGrid attributes in the SendGrid API documentation.
## Recipient data requirements
In order to send an email notification you'll need a valid `email` property set on your recipient.
## Delivery status webhooks
Delivery tracking for SendGrid can result in the following status updates to your message:
- The message delivery is confirmed and Knock updates the message to `delivered`
- The message was not delivered and Knock updates the message to `undelivered`
- The message was not delivered due to a synchronous bounce and Knock updates the message to `bounced`
When enabled, SendGrid will send delivery status updates directly to Knock via webhooks, allowing you to track the full lifecycle of your email messages in real-time. This provides more reliable tracking than polling-based methods and captures both synchronous and asynchronous bounce events.
### Prerequisites
Before enabling delivery status webhooks, you need:
1. A verified sender identity or domain in SendGrid
2. A SendGrid channel configured in Knock (see the [getting started](#getting-started) section above)
3. Access to your SendGrid webhook settings
### Setting up delivery status webhooks
1. Navigate to **Channels and sources** in your Knock dashboard
2. Select your SendGrid channel
3. Click "Manage configuration" for the environment you want to configure
4. Scroll to the "Incoming message status updates" section and enable incoming webhooks
5. Copy the generated webhook URL - you'll need this in the next step
In the SendGrid dashboard, configure the Event Webhook to send delivery events to Knock:
1. Go to Settings > Mail Settings > Event Webhook in your SendGrid dashboard
2. Enable the Event Webhook if it's not already enabled
3. In the "HTTP POST URL" field, paste the webhook URL from Knock
4. Under "Select Actions", enable these event types:
5. Click "Save" to activate the webhook
6. SendGrid will begin sending events to Knock immediately
### Supported delivery statuses
When delivery status webhooks are enabled for SendGrid, Knock will update message statuses based on these SendGrid webhook events:
| SendGrid Event Type | Knock Status | Description |
| ------------------- | ------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| delivered | `delivered` | The email was successfully delivered to the recipient's mail server. |
| bounce | `bounced` | The email bounced due to invalid recipient, domain, or mailbox full. Only hard bounces with type `"bounce"` will be updated to the `bounced` status in Knock. Bounce events with type `"blocked"` are considered soft bounces in SendGrid and will not be updated. |
| dropped | `bounced` | The email was not delivered due to invalid or previously-bounced recipient. |
### Troubleshooting
If delivery status updates aren't appearing in Knock:
1. **Check Event Webhook status.** Verify the Event Webhook is enabled in your SendGrid Mail Settings.
2. **Verify event selection.** Ensure both "Delivered" and "Bounce" events are selected in your Event Webhook configuration.
3. **Verify sender identity.** Ensure you're sending from a verified sender identity or domain in SendGrid.
4. **Test the webhook.** Use SendGrid's "Test Your Integration" button to send a test event and verify connectivity.
5. **Check event history.** Review the Event Webhook activity in SendGrid to ensure events are being sent.
If you're having trouble setting up delivery status webhooks, contact our
support team at support@knock.app.
}
/>
## SMTP
How to send transactional email notifications using SMTP with Knock.
---
title: How to send email with SMTP
description: How to send transactional email notifications using SMTP with Knock.
section: Integrations > Email
layout: integrations
---
Knock supports sending email notifications to your users via the Simple Mail Transfer Protocol (SMTP). In this configuration, Knock acts as an SMTP client and sends email notifications to a specified SMTP server. This page describes how to get started sending email notifications using SMTP with Knock.
## Features
- Attachments support
- Knock link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
You can create a new SMTP Relay channel in the dashboard under the **Channels and sources** page in your account settings. From there, you'll need to configure the channel for each environment you have.
The following information is required to configure an SMTP Relay channel:
- SMTP server host
- SMTP server port
- Username
- Password
Please note the following:
- **Knock only supports authenticated SMTP connections.**
- **The port must support TLS.** Email providers commonly use port 587 for TLS, but check your provider's documentation to confirm.
- **We cannot currently track deliverability through SMTP Relay channels.** This means that all notifications sent via SMTP will show up as "Sent" in the Knock messages log, but not "Delivered."
- **Some SMTP relay servers (including Gmail) have rate limits on authentication.** This means that they aren't well-suited to sending transactional email at scale. We recommend taking this into consideration when setting up an SMTP email channel in Knock.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your SMTP [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your SMTP channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for SMTP Relay**
- **SMTP host** (`string*`) - The SMTP server host.
- **Username** (`string*`) - The username to use when authenticating with the SMTP server.
- **Password** (`string*`) - The password to use when authenticating with the SMTP server.
- **Port** (`number*`) - The SMTP server port. This port must support TLS.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - For SMTP Relay channels, only header overrides are supported. See 'Setting SMTP headers' below for more details.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Setting SMTP headers
For SMTP Relay channels, the JSON overrides field can be used to set SMTP headers. Overrides can be set in either the environment settings or per template.
Knock supports overriding existing SMTP headers and adding custom headers.
```json title="Adding a custom SMTP header via JSON overrides"
{
"headers": {
"X-SMTPAPI": "{\"category\": \"transactional\"}"
}
}
```
Headers must be nested under the `headers` key. Other keys will be ignored.
If one of your header overrides is not already a string, Knock will
automatically convert it to a string before sending.
}
/>
## Recipient data requirements
In order to send an email notification you'll need a valid `email` property set on your recipient.
## Frequently asked questions
No, we currently do not support sending Loops emails via SMTP. Instead, you
could use a [webhook channel](/integrations/webhook/overview) with the
[Loops transactional email
API](https://loops.so/docs/api-reference/send-transactional-email).
## SparkPost
How to send transactional email notifications to SparkPost with Knock.
---
title: How to send email with SparkPost
description: How to send transactional email notifications to SparkPost with Knock.
section: Integrations > Email
layout: integrations
---
Knock integrates with SparkPost to send email notifications to your users. This page describes how to get started with SparkPost in Knock, including necessary provider configurations and additional data you can pass through to SparkPost.
## Features
- Attachments support
- Delivery tracking
- Knock link and open tracking
- SparkPost link and open tracking
- Per environment configuration
- Sandbox mode
## Getting started
You can create a new SparkPost channel in the dashboard under the **Channels and sources** page in your account settings. From there, you'll need to configure the channel for each environment you have.
## Channel configuration
The following channel settings should be configured per [environment](/concepts/environments). Navigate to **Channels and sources** in your dashboard account settings, select your SparkPost [channel](/concepts/channels), then click "Manage configuration" under the environment that you'd like to configure.
Fields marked with an `*` are required.
**Knock settings**
- **Sandbox mode** (`boolean`) - Whether to enable sandbox mode for your SparkPost channel.
- **Knock open tracking** (`boolean`) - Whether to enable Knock email-open tracking.
- **Knock link tracking** (`boolean`) - Whether to enable Knock link-click tracking.
- **CSS inlining** (`boolean`) - Whether Knock will inline CSS styles in your emails onto their associated HTML elements before sending, to improve email client compatibility. Defaults to true.
**Provider settings for SparkPost**
- **API key** (`string*`) - The API key for your SparkPost account.
- **SparkPost region** (`enum*`) - The region that your SparkPost account is in, either US or EU.
- **Open tracking** (`boolean`) - Whether to enable SparkPost email-open tracking.
- **Link tracking** (`boolean`) - Whether to enable SparkPost link-click tracking.
- **From email address** (`string | liquid*`) - The default sender email address (can use Liquid tags).
- **From name** (`string | liquid`) - The default sender name (can use Liquid tags).
When configured, these optional overrides will apply to all emails sent from this channel in the configured environment. Learn more about email channel overrides [here](/integrations/email/settings).
- **To** (`string | liquid`) - The To email address that email notifications will be sent to (can use Liquid tags). This value will override the designated recipient's email address.
- **Cc** (`string | liquid`) - The CC email address that email notifications will be sent to (can use Liquid tags).
- **Bcc** (`string | liquid`) - The BCC email address that email notifications will be sent to (can use Liquid tags).
- **Reply-to** (`string | liquid`) - The reply-to email address that will be included on email notifications (can use Liquid tags).
- **Payload overrides** (`JSON (string) | liquid`) - Provide a JSON object to merge into the API payload that is sent to the downstream provider.
Set optional per-environment [conditions](/integrations/overview#channel-conditions) for this channel. These conditions are evaluated each time a workflow run encounters a step that uses this channel in the configured environment. If the conditions are not met, the step will be skipped.
## Additional data sent
Knock sends the following attributes along with your emails:
- `metadata.knock_message_id`: the ID of the message this email is associated with
- `metadata.knock_recipient_id`: the Knock ID of the recipient this email is being sent to
## Recipient data requirements
In order to send an email notification you'll need a valid `email` property set on your recipient.
# Chat
## Overview
Learn how to use Knock to send notifications to chat apps such as Slack, Microsoft Teams, and Discord.
---
title: Chat notifications with Knock
description: Learn how to use Knock to send notifications to chat apps such as Slack, Microsoft Teams, and Discord.
section: Integrations > Chat
layout: integrations
---
We make it effortless to send notifications to chat providers like Slack, Microsoft Teams, and Discord. Meet your users in the tools they use daily.
## Features
- **Markdown template builder**: use our markdown editor to create templates for each platform and let us take care of sending the platform-specific markup.
- **Use JSON to build interactive messages**: if you need to, it's easy to go to a fully customizable JSON template to power your chat notifications.
- **Cross-provider, single template**: you can send the same chat templated message across all chat providers to reduce the amount of templates to maintain.
- **Link tracking**: capture link-click events right within your Knock account. For more details, see the [Knock link tracking documentation](/send-notifications/tracking).
## Supported providers
Knock currently has support for the following chat providers:
- [Slack](/integrations/chat/slack)
- [Discord](/integrations/chat/discord)
- [Microsoft Teams](/integrations/chat/microsoft-teams)
- [WhatsApp](/integrations/chat/whatsapp)
If you want us to add a new provider to this list, please let us know through the feedback button at the top of this page.
## Replying to chat messages
Learn how to reply to messages created by an earlier workflow step or in an existing thread.
---
title: Replying to chat messages
description: Learn how to reply to messages created by an earlier workflow step or in an existing thread.
tags: ["steps", "channels", "chat", "slack", "discord", "msteams"]
section: Integrations > Chat
layout: integrations
---
Chat channel steps can start a new conversation or reply to an existing provider thread. When a parent message was created by the current workflow run, you can send a reply to a previous chat step. To reply to a message that already exists outside the workflow run, you'll provide its provider identifiers instead.
## Reply to a previous chat step
This is the recommended way to create a reply. Knock uses the earlier workflow step's provider message reference and destination, so you do not need to pass provider IDs or configure the destination again.
In the workflow builder:
1. Add a chat channel step after the step that creates the parent message.
2. Set **Message behavior** to **Reply to a previous chat step**.
3. Select the **Parent step**.
A step is available as a parent when it:
- Is a previous chat channel step that is reachable on every execution path to the reply. Chat steps inside conditional [branches](/designing-workflows/branch-function) will not be eligible as a parent to subsequent steps outside of that branch.
- Uses the same single Knock channel as the reply step. Channel groups are not supported.
- Resolves to one provider message and destination for the current recipient workflow run. A chat step that creates multiple messages, such as when a recipient has multiple channel connections, is not eligible as a parent.
The reply step inherits the exact provider message reference and recipient connection from its parent. For Microsoft Teams, Knock keeps the original thread root when the selected parent step is itself a reply. If the parent message is queued or scheduled, Knock waits for its provider message reference before attempting the reply.
## Reply to an existing thread
Use this option when the parent message already exists outside of the current workflow run.
In the workflow builder:
1. Set **Message behavior** to **Reply to an existing thread**.
2. Enter the provider identifiers described below, usually as dynamic Liquid references from your workflow trigger `data`.
3. For Slack, optionally enter the channel ID in **Send to**. See below for more detail on [configuring the destination](#configure-the-destination).
The values depend on the provider:
- For Slack, use the parent message's timestamp (`ts`). Knock sends it to Slack as `thread_ts`.
- For Discord, use the parent Discord message ID.
- For Microsoft Teams, enter the thread's conversation ID in **Conversation ID** and the root activity's ID in **Thread root message ID**. In an incoming Bot Framework activity, these values are `conversation.id` and `id`.
Microsoft Teams replies require a bot-based connection. Incoming webhook connections cannot reply to messages.
For a Slack message sent by Knock, use metadata.external_id
from the message returned by the API or a webhook as the parent message ID.
This is the Slack message's ts.
}
/>
### Configure the destination
For Slack, **Send to** accepts a Slack channel ID, usually from workflow trigger data such as `{{ data.channel_id }}`. Leave it blank to use the recipient's Slack channel connection. In either case, the destination must be the channel that contains the parent message.
For Discord, Knock uses the Discord channel data stored on the recipient. That connection must identify the channel that contains the parent message.
For Microsoft Teams, Knock resolves a bot-based connection from the recipient and, when used, tenant channel data. Together, the channel data must include a Microsoft Entra tenant ID and either a Microsoft Teams channel ID or user ID. See [Microsoft Teams channel data requirements](/integrations/chat/microsoft-teams/overview#how-to-set-channel-data-for-a-microsoft-teams-integration-in-knock).
The configured Slack, Discord, or Microsoft Teams channel supplies authentication. Do not put a bot token in workflow data or in a destination field.
### Slack trigger data example
Send the Slack message timestamp and channel ID in the workflow trigger data:
```javascript title="Triggering a threaded Slack response"
await knock.workflows.trigger("reply-to-slack-message", {
recipients: ["user_123"],
data: {
parent_message_id: "1784920923.818589",
channel_id: "C0123456789",
},
});
```
Then configure the Slack step with:
| Setting | Value |
| ----------------- | ------------------------------ |
| Message behavior | Reply to an existing thread |
| Parent message ID | `{{ data.parent_message_id }}` |
| Send to | `{{ data.channel_id }}` |
At execution time, Knock renders the destination as a recipient connection equivalent to:
```json title="A recipient Slack connection"
{
"channel_id": "C0123456789"
}
```
### Microsoft Teams trigger data example
Send the conversation ID and root activity ID in the workflow trigger data:
```javascript title="Triggering a Microsoft Teams thread reply"
await knock.workflows.trigger("reply-to-microsoft-teams-message", {
recipients: ["user_123"],
data: {
conversation_id: "19:conversation-id@thread.tacv2",
thread_root_message_id: "1742995142123",
},
});
```
Then configure the Microsoft Teams step with:
| Setting | Value |
| ---------------------- | ----------------------------------- |
| Message behavior | Reply to an existing thread |
| Conversation ID | `{{ data.conversation_id }}` |
| Thread root message ID | `{{ data.thread_root_message_id }}` |
The conversation and thread root identifiers select the existing Microsoft Teams thread. The recipient and tenant channel data provide the bot connection that Knock uses to send the reply.
## Troubleshooting
Knock uses the recipient's stored Slack connection, which might point to
another channel. Enter the channel ID that contains the parent message.
The reply does not attach to the expected thread, or Slack rejects the
request. Enter the channel ID that contains the parent message.
Microsoft Teams rejects the reply or cannot attach it to the expected
thread. Use the conversation.id and root activity{" "}
id from the Microsoft Teams Bot Framework activity.
Knock cannot reply because incoming webhooks do not provide the required
bot-based connection. Configure bot-based channel data for the provider.
Knock cannot render a required provider identifier or destination, so it
does not send the reply. Verify the workflow trigger data and Liquid path.
The step is not guaranteed to run first, uses another Knock channel, or is
inside an unsupported group. Adjust the workflow graph or reply to an
existing thread with its provider identifiers.
Knock cannot identify one parent message and destination when the step
produces no message or multiple messages. Make the parent resolve to exactly
one chat message for the recipient run.
## Slack
## Overview
Learn how to use Knock to send Slack notifications to your users.
---
title: Slack notifications with Knock
description: Learn how to use Knock to send Slack notifications to your users.
section: Integrations > Slack
layout: integrations
---
This page covers how to use Knock to send notifications to Slack. You can use Knock's Slack extension to message your own team's workspace, or connect your own Slack app to build a customer-facing integration.
## What can I do with Knock's Slack integration?
Knock's Slack integration enables you to:
- Use [internal Slack messaging](/integrations/chat/slack/sending-an-internal-message) to send messages to your team's Slack workspace.
- [Send messages to channels in your customers' workspaces](/integrations/chat/slack/sending-a-message-to-channels) using your own Slack app.
- [Send direct messages to users in your customers' workspaces](/integrations/chat/slack/sending-a-direct-message) using your own Slack app.
You can create rich message templates using [markdown](#markdown-templates) or [Slack's Block Kit framework](#block-based-templates).
This integration does not support Slack modals, slash commands, shortcuts, or interactive dialogs.
## Connect your own Slack app
The steps below apply when you are building a customer-facing Slack integration with your own Slack app. To send workflow messages to your own team's workspace without creating a Slack app, [create an internal Slack channel](/integrations/chat/slack/sending-an-internal-message) instead.
Knock supports multiple ways to connect your own Slack app depending on your technical requirements:
- Using Knock's managed approach with our [SlackKit components](/in-app-ui/react/slack-kit)
- Using Knock's [Slack-related React hooks](https://docs.knock.app/in-app-ui/react/slack-kit#using-slackkit-headless) with your own components
- Building the UI and OAuth flow entirely yourself
If you haven’t built a Slack app yet, you can get started in Slack’s app documentation.
Once you create your Slack app, you’ll be routed to its app management page within the Slack dashboard. It looks like this.
If you are new to Slack apps, there are a few key concepts to understand:
- A scope is a permission granted to your Slack app when it joins a Slack workspace. You configure which scopes your app asks for in the **OAuth & Permissions** sidebar of your app management page.
- Your Slack app is installed to a customer's workspace through the Slack OAuth flow. In this flow, your app requests scopes and the user installing the app confirms which scopes to grant. You’ll need to surface this OAuth flow to your users wherever you want them to install your Slack app. Knock's [`SlackAuthButton` component](/in-app-ui/react/slack-kit#slackauthbutton--container) can help you with this.
- A Slack app can have bot token scopes and user token scopes. For almost all use cases, you’ll be using bot token scopes (this Slack doc explains why). When you add bot token scopes to an app, you will **also** need to make sure your app has its display information configured. You can do this under the **App Home** sidebar on the app management page.
In this section we'll complete the steps for setting up your Knock account and Slack app.
First, you'll need to create the bot that you'll use to post notifications.
If you already have a Slackbot you want to use, you'll just need to
make sure it has its redirect URL set and that it's publicly distributed, which
is described below.
}
/>
The following steps will be completed in the **OAuth & Permissions** sidebar of your Slack app's management page:
When using an `access_token` stored in Knock to power your Slack integration, that token will need to contain the correct scopes to use the Slack API. Although If you're using SlackKit, the components can help you manage your scopes, but you have to add one in your Slack application's settings to start with so that it exposes the form for you to add a redirect URL.
Here is the list of scopes we recommend adding to your app and the reasons they're required:
- `chat:write`: This scope allows your bot to send messages to channels that the bot has been explicitly invited to, including private channels. It doesn't grant the ability to send messages to public channels without an invite.
- `chat:write.public`: This scope extends the bot's capabilities to send messages to public channels without needing a specific invitation to those channels. It's an addition to the chat:write scope, offering broader access for the bot to interact within the workspace.
- `channels:read`: This scope allows your bot to list all channels in a workspace and view details about specific channels (like name, topic, purpose, members), but does not grant access to private channels.
- `groups:read`: This scope allows your app to list all private channels that the bot or user is a member of and to view details about those channels.
- `users:read`: This scope allows your app to view all people in a workspace and is required if you want to query a user's Slack ID by email. **This scope is required to use [Knock's email-based user ID resolution](/integrations/chat/slack/sending-a-direct-message#enabling-email-based-user-id-resolution).**
- `users:read.email`: This scope allows your app to view the email addresses of people in a workspace and is required if you want to query a user's Slack ID by email. **This scope is required to use [Knock's email-based user ID resolution](/integrations/chat/slack/sending-a-direct-message#enabling-email-based-user-id-resolution).**
Under **OAuth & Permissions** in the **Features** sidebar, you need to add a redirect URL so that Slack knows where to redirect users after they complete the OAuth handshake.
If you plan on using SlackKit, copy and paste this redirect URL:
If you're building your own OAuth flow, you'll need to use a URL in your frontend application. You can reference this documentation on building a Slack OAuth flow from scratch.
Under **Manage Distribution**, click the "Distribute app" button which will show you a list of items to complete to activate public distribution. If you've built the app from scratch and completed the previous steps, you should see all of these complete except for "Remove hard coded information."
Check the box and then click "Activate Public Distribution."
Now that your Slack app is set up, you'll want to reference three attributes in the **Basic Information** section:
1. App ID
2. Client ID
3. Client secret
You need to add this data to a new or existing Slack integration in the Knock dashboard to link your app to Knock. From the dashboard, you can [create a Slack integration](/concepts/channels#managing-channels) by navigating to **Channels and sources** in your account settings.
Once the channel exists, you can click "Manage configuration" to access the "Provider settings" section. This is where you'll paste the three strings referenced above.
Click "Update settings" to save.
In order to test this flow, you'll want to set up a workflow with a Slack channel step. Later on we'll discuss how you can [design your notification templates for Slack](/integrations/chat/slack/overview#designing-notification-templates-for-slack), but for now you can just add the channel step to a workflow. To actually send a notification to Slack, you'll need to add channel data to a user or object in Knock. We'll cover that in the next section.
## How to set channel data for a Slack integration in Knock
In Knock, the [`ChannelData`](/managing-recipients/setting-channel-data) concept provides you a way of storing recipient-specific connection data for a given integration. If you reference the [channel data requirements for Slack](/managing-recipients/setting-channel-data#chat-app-channels), you'll see that there are two different schemas for a `SlackConnection` stored on a [`User`](/concepts/users) or an [`Object`](/concepts/objects) in Knock.
Here's an example of setting channel data on an `Object` in Knock.
In the example above, the KNOCK_SLACK_CHANNEL_ID variable is
the id of the Knock channel you've created to represent your Slack app
within the Knock dashboard. You can find it by going to{" "}
Integrations {">"}{" "}
Channels in the Knock dashboard and
then copying the ID of your Slack app channel.
}
/>
### How Slack delivery works
Every Slack notification needs two things, and Knock lets them live in different places:
- **Auth** — permission to post: either a bot **access token** (`xoxb-…`) from Slack's OAuth flow, or a self-contained **incoming webhook URL**. A bot token authorizes exactly one Slack workspace.
- **Destination** — where the message goes: a `channel_id` (a channel) or a `user_id` (a direct message).
The **destination** is stored on the recipient (a [`User`](/concepts/users) or [`Object`](/concepts/objects)). The **auth** can be stored on the recipient too — or, in a multi-workspace product, once on the [tenant](#tenant-channel-data-requirements), so every recipient in that tenant shares a single connection. The two sections below cover each location.
### Recipient channel data requirements
Here's an overview of the data requirements for [setting recipient channel data](/send-notifications/setting-channel-data) for either an incoming webhook or an access token Slack connection. Both will need to live under the `connections` key.
| Property | Type | Description |
| ----------- | ------------------- | --------------------------------- |
| connections | `SlackConnection[]` | One or more connections to Slack. |
A `SlackConnection` can have one of two schemas, depending on whether you're using standard Slack OAuth scopes or an incoming webhook.
We cover Slack app scopes in detail in our [Slack scopes documentation](/integrations/chat/slack-diy/slack-apps-and-scopes).
If you're using standard Slack OAuth with access token scopes, your `SlackConnection` schema looks like this. You'll use
either a `channel_id` or `user_id` depending on whether you're storing connection data to message a channel or user in Slack:
| Property | Type | Description |
| ------------ | -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| access_token | `string` | A bot access token. Not required when the access token is stored on a tenant. |
| channel_id | `string` | A Slack channel ID. |
| user_id | `string` | A Slack user ID. |
```json title="Slack channel_data with an access token"
{
"connections": [
{
"access_token": "ACCESS_TOKEN",
"channel_id": "CHANNEL_ID",
"user_id": "USER_ID"
}
]
}
```
If you're using a Slack app with the `incoming-webhook` scope your `SlackConnection` schema is quite simple:
| Property | Type | Description |
| -------------------- | -------- | ------------------------------- |
| incoming_webhook.url | `string` | The Slack incoming webhook URL. |
```json title="Slack channel_data with an incoming webhook URL"
{
"connections": [
{
"incoming_webhook": { "url": "https://hooks.slack.com/services/T00000000/B00000000/XXXXXXXXXXXXXXXXXXXXXXXX" }
}
]
}
```
### Tenant channel data requirements
When you [map a Slack workspace to a tenant](/integrations/chat/slack/sending-a-message-to-channels#key-concepts) in Knock (as our [SlackKit](/in-app-ui/react/slack-kit) components do), you store that workspace's access token as `channel_data` on the tenant. At send time, when you trigger a workflow with that `tenant`, Knock takes the [destination](#how-slack-delivery-works) from the recipient's `channel_data` (the `channel_id` or `user_id`) and uses the tenant's access token for auth: the tenant provides the auth, the recipient provides the destination. If the recipient also carries an `access_token`, the tenant's takes precedence — so the `access_token` on the recipient's `SlackConnection[]` above is not required when a tenant holds one.
**Do you need a tenant?** Store the token on a tenant when one Slack workspace connection should serve every recipient or object in that tenant. This keeps the workspace access token in one place while each recipient or object stores only its Slack destination (`channel_id` or `user_id`), which is useful as you add more destinations in the same workspace later. You don't need a tenant if you post to a single internal workspace (use an incoming webhook — there's no token to share) or only ever use one workspace's token and prefer to store it directly on each recipient or object. Knock never auto-creates a tenant for you (though SlackKit can, on the fly), so use one when shared workspace auth should live at the tenant level.
Here's an overview of the data requirements for setting channel data when storing an access token on a tenant.
| Property | Type | Description |
| ------------------ | -------- | ------------------------------------------------------------ |
| token | `object` | An object containing the `access_token` obtained from Slack. |
| token.access_token | `string` | The `access_token` obtained from Slack. |
```json title="Slack channel_data on a tenant"
{
"token": { "access_token": "ACCESS_TOKEN" }
}
```
### Choosing where to store channel data: users vs. objects
Depending on the Slack integration you build into your product, you’ll store the connection data you receive from Slack as `channel_data` on either a `User` or an `Object` in Knock.
If your integration involves a user opting in to receive DMs from your Slack bot, you’ll be storing the channel data [on that user](/api-reference/users/set_channel_data) in Knock. When you want to notify this user, you'll include them as a recipient in a Knock workflow trigger.
For this integration, you'll store a user's Slack `user_id` in the `SlackConnection` object. You can [enable email-based user ID resolution](/integrations/chat/slack/sending-a-direct-message#enabling-email-based-user-id-resolution) if you'd like Knock to automatically resolve these IDs on your behalf.
Alternatively, you can manually find the correct `user_id` by querying Slack's API:
- by a given user's email address
- for a list of all of a workspace's users
You'll need to be sure that you request the appropriate [`scopes`](/integrations/chat/slack/overview#set-up-slack-app) for these methods during the auth process.
If your integration involves a customer connecting a _non-user resource_ in their product (such as a project or a page) to a Slack channel, you’ll want to store that channel data [on an object](/api-reference/objects/set_channel_data) in Knock, as it’s not specific to any single user.
You can find the correct `channel_id` and display a list of channels for your user to select from by querying the Slack API:
- for a list of all of a workspace's channels
The [`SlackChannelCombobox`](/in-app-ui/react/slack-kit#slackchannelcombobox) component of Knock's SlackKit can help you with this.
You can learn more about the Knock object model and see an example how to use it to power Slack notifications in our [Objects documentation](/concepts/objects).
## Designing notification templates for Slack
When you add a new Slack channel step to a workflow in Knock, you'll need to configure a template for that step so Knock knows how to format the message to Slack.
### Markdown templates
Editing a markdown template for Slack is just like editing any other markdown-based template in Knock. You can use Liquid to inject variables and add control tags (e.g. if-then, for-loop) into your template.
Slack uses a markdown-variant syntax called{" "}
mrkdwn
, but Knock handles this for you automatically, so you can write your templates
in good old
{" "}
markdown
.
}
/>
Here's an example Slack template written in Knock using markdown.
```markdown title="A markdown-based Slack template with for-loop iteration"
Hi **{{ recipient.name | split:" " | first }}**,
There are {{ total_activities }} comments left on {{ page_name }}.
{% for activity in activities %}
- From **{{activity.actor.name}}**: "{{activity.comment.body}}""
{% endfor %}
[**View page**]({{vars.base_url}}/{{account_id}}/pages/{{ page_id }})
```
In the example above we're using Liquid's for-loop tag to iterate over the activities array produced by a Knock batch function. You can learn more about Knock batch functions and the state they produce in our [batch function documentation](/send-notifications/designing-workflows/batch-function).
### Block-based templates
For more advanced layouts in your Slack messages, including images and buttons, you'll need to use Slack's block kit UI framework to build your notification templates. The block kit framework is a set of different JSON objects you can use together and arrange to create Slack app and notification layouts.
#### Designing block kit templates
To start you'll want to design your block-based Slack message template. The best way to do this today is to use Slack's block kit builder. It gives you a drag-and-drop interface for building out your Slack templates, and outputs the JSON you'll need to bring into your Knock template.
Once you've designed your Slack template, copy the JSON from the block kit builder and bring it into your Knock notification template. You'll use the "Switch to JSON editor" button at the bottom right of the Knock template editor page to switch to our JSON editor, and then paste in the JSON you copied from the block kit builder.
In the future you'll be able to use a visual, drag-and-drop editor within
Knock to build these block-based Slack templates without having to leave
the Knock product.
If you're interested in this functionality, please shoot us a note at{" "}
support@knock.app or use the feedback
button at the bottom of this page.
}
/>
#### Knock's JSON template editor
You can use liquid in the Knock JSON template editor just as you would in the markdown editor. This is helpful for both injecting variables into the text of your Slack UI blocks, as well as for using liquid control tags to control when certain blocks should be displayed and for iterating through an array and mapping its items into a list of Slack blocks.
Here's an example of a block kit UI template with liquid syntax added to iterate through a list of items.
```json title="A block kit UI template in Knock with for-loop iteration"
{
"blocks": [
{
"type": "header",
"text": {
"type": "plain_text",
"text": "Users marked for onboarding",
"emoji": true
}
},
{
"type": "section",
"text": {
"type": "mrkdwn",
"text": "Hi John,\n\n The following users have been assigned to you for onboarding today:"
}
},
{% for activity in activities %}
{
"type": "section",
"text": {
"type": "mrkdwn",
"text": "*{{activity.assigned_user.name}}* \n {{activity.assigned_user.email}} \n _{{activity.assigned_user.title}}_"
},
"accessory": {
"type": "image",
"image_url": "{{activity.assigned_user.avatar_url}}",
"alt_text": "avatar image"
}
},
{
"type": "divider"
},
{% endfor %}
{
"type": "actions",
"elements": [
{
"type": "button",
"text": {
"type": "plain_text",
"text": "View in dashboard",
"emoji": true
},
"value": "{{dashboard_url}}"
}
]
}
]
}
```
In the template above, we're using the `activities` array produced by a [batch function](/send-notifications/designing-workflows/batch-function) to iterate over a number of items that we want to display in our Slack message. For each one of those items, we're producing a `section` that includes both `text` and `image` blocks which reference variables from the `activity` from our `activities` array.
Here's an example of a Slack message produced with this template. **Note:** this template was produced by three separate workflow trigger calls to the Knock API, all of which were batched into a single message automatically using our batch function.
## Messaging your workspace
Use internal Slack messaging to send Knock workflow messages to channels and people in your team's Slack workspace.
---
title: Sending messages to your team's Slack workspace
description: Use internal Slack messaging to send Knock workflow messages to channels and people in your team's Slack workspace.
tags: ["slack", "chat"]
section: Integrations > Slack
layout: integrations
---
Internal Slack messaging gives your team a managed way to send workflow messages to your own Slack workspace. Connect the Knock Slack extension once, then choose a Slack channel or person as the destination for each workflow step.
You don't need to create a Slack app, manage bot tokens, or store Slack `channel_data` on your workflow recipients.
The internal Slack channel is a managed Knock channel
backed by the Knock Slack extension. A Slack destination{" "}
is the channel or person in your workspace that you select on a workflow
step. One internal Slack channel can be used by many workflow steps, each
with its own destination.
}
/>
## Before you begin
To create an internal Slack channel, you need a Knock [role](/manage-your-account/roles-and-permissions) with permission to manage both channels and extensions. After it is created, team members with permission to edit workflows can use it in workflow steps.
The Knock Slack app can send to:
- Public channels in your workspace.
- Private channels where the Knock Slack app is a member. Invite `@Knock` to a private channel before selecting it.
- Active people in your workspace via direct message.
## Create an internal Slack channel
In the Knock dashboard, open **Settings > Channels and sources** and click
**Create channel**. Select **Chat**, then choose **Slack** with the `Internal`
badge. Click **Next**.
If your project is already connected to Slack through the [Knock Slack
extension](/integrations/extensions/slack) with the required permissions,
Knock uses that connection to create the internal Slack channel.
If Slack is not connected, or if the existing connection needs additional
permissions, Knock opens the Slack authorization flow. Choose your workspace
and approve the requested permissions. After you return to Knock, the
internal Slack channel is created automatically.
The channel configuration shows the Slack workspace managed by the Knock
Slack extension. Its credentials apply across your Knock environments and
cannot be edited from the channel configuration.
You can create one internal Slack channel per Knock account. The same
channel can be reused across any number of workflows.
## Add internal Slack messaging to a workflow
Open a workflow and add a chat app channel step. Select your internal Slack
channel.
Use the **Send to** field to search the connected workspace. Choose a
destination from either the **Channels** or **People** tab.
The destination is stored on this workflow step. Other steps using the same
internal Slack channel can be configured to send elsewhere.
Write the Slack message using Knock's markdown or Block Kit editor, then
commit the workflow. You do not need to configure a recipient connection in
the template settings; Knock supplies the Slack destination and credentials
for you.
## Trigger the workflow
Trigger a workflow that uses internal Slack messaging the same way you trigger any other Knock workflow. A recipient is still required for the workflow run, but that recipient does not need Slack channel data.
```javascript title="Trigger a workflow that uses internal Slack messaging"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await knock.workflows.trigger("support-alert", {
recipients: ["user-1"],
data: {
summary: "A customer needs help with a failed import.",
},
});
```
The workflow recipient still provides the `recipient` variables used in Liquid templates, step conditions, and the rest of the workflow. The destination selected in **Send to** only changes where that internal Slack step is delivered.
To continue an existing Slack thread instead of starting a new message, see [replying to chat messages](/integrations/chat/replying-to-chat-messages). Replies can inherit the destination from a previous chat step or target an existing thread using its message timestamp and matching channel ID.
## How recipient preferences work
Messages sent through internal Slack messaging bypass the workflow recipient's notification [preferences](/preferences/overview) because the message is delivered to a configured destination, not to a Slack connection owned by that recipient. Channel and step [conditions](/concepts/conditions) still evaluate normally against the workflow `recipient`, if set.
Each internal Slack step sends exactly one message to its selected destination. In workflow runs and message details, **Delivered to** shows the Slack channel or person that received the message, while the recipient associated with the message remains the workflow `recipient`.
## Manage or reconnect Slack
The Knock Slack extension owns the workspace connection and credentials used by the internal Slack channel. Manage the connection from **Settings > Extensions**, not from the channel's provider settings.
If the extension is disconnected or needs to be authorized again, Knock preserves the internal Slack channel and its workflow references but skips affected Slack steps until the workspace is reconnected. The workflow run log identifies the disconnected Slack connection as the reason. Open **Settings > Extensions** and reconnect Slack to resume delivery.
## When to use a different Slack setup
Use internal Slack messaging only when you want Knock to message your own team's workspace through the Knock Slack app.
If you are building a customer-facing Slack integration, use [your own Slack app and SlackKit](/integrations/chat/slack/sending-a-message-to-channels).
## Sending a direct message
How to configure and send direct messages to Slack users.
---
title: Sending a direct message to a user in Slack
description: "How to configure and send direct messages to Slack users."
tags: ["slack", "chat"]
section: Integrations > Slack
layout: integrations
---
This page covers how to create a self-serve Slack integration for a multi-tenant application using Knock. It assumes that you have already created a Slack app and created a Slack channel in Knock as outlined in the [Slack integration overview](/integrations/chat/slack/overview).
In this implementation, your application's users will connect their Slack workspace to Knock and be able to send messages to individual users via DM. To make this easier to implement, we'll use Knock's [SlackKit components](/in-app-ui/react/slack-kit) to facilitate the OAuth flow.
## Key concepts
SlackKit connects multiple concepts in Knock to make it easier for your application's users to create a Slack integration. `Tenants` are a concept you'll see throughout the following docs that are foundational to how SlackKit works, but might not be used in every implementation of Knock.
### About tenants
[Tenants](/concepts/tenants) in Knock are meant to represent groups of users who typically share the same resources. You might call these "accounts," "organizations," "workspaces," or something similar. In a standard SlackKit implementation, you'll store a Slack workspace's `access_token` on a corresponding tenant in Knock.
If you already use Knock's tenant concept to power other 'account-based' features, you likely create tenants in Knock when an account or organization is created in your application. If you don't already use tenants in Knock, SlackKit can create tenants for you on the fly if they don't already exist.
Our best-practice recommendation is that tenants in Knock should map
one-to-one to whatever abstraction you use to model accounts,
organizations, or workspaces. You can think of tenants as the top-level
container within your data model that you use to power multi-tenancy in
your application.
}
/>
### Merging channel data
In this implementation, we'll actually store [the required channel data](/integrations/chat/slack/overview#channel-data-requirements) for a `SlackConnection` across two different entities in Knock: a `Tenant` and an `User`. This is because we want to store the `access_token` for the Slack workspace on the `Tenant` and the `user_id` for the Slack user on the `User`.
When you trigger a workflow using this recipient and tenant, Knock will merge the channel data from the `Tenant` and the `User` to send the message to the correct Slack DM channel. By storing the `access_token` on the `Tenant`, your customers only need to complete the OAuth flow once to connect their Slack workspace to Knock. From there, you can create UI that allows users to link their Slack user ID to their Knock user ID or automate this process during user registration.
## Implementing SlackKit
To facilitate the OAuth flow and channel selection process, we'll use Knock's [SlackKit components](/in-app-ui/react/slack-kit). SlackKit is a set of React components that make it easier to build Slack integrations in Knock. You can use SlackKit to build a self-serve Slack integration that allows your users to connect their Slack workspace to Knock.
### Signing a user token
The only access you'll need to manage when using SlackKit are grants for your users to interact with their [Tenant](/concepts/tenants) in Knock. This is necessary because the user in this context is an end user in your application who does not have access to Knock as a [member of the account](/manage-your-account/managing-members). Therefore, these grants provide them elevated privileges to operate on specific resources using the API.
We've made it easy for you to tell Knock which resources your users should have access to by making it a part of their user token. In this section you'll learn how to generate these grants using the Node SDK and, if you're not using the SDK, how to structure them for other languages.
You'll need to generate a token for your user that includes access to the tenant storing the Slack access token as well as any recipient objects storing Slack channel data described in this reference on [SlackKit resource access grants](/in-app-ui/react/slack-kit#resources-access-grants).
Using the below example, you can quickly generate a token with the Node SDK.
```javascript
import {
signUserToken,
buildUserTokenGrant,
Grants,
} from "@knocklabs/node/lib/tokenSigner";
const token = await signUserToken("user-1", {
grants: [
buildUserTokenGrant({ type: "tenant", id: "org_3sh72ds78" }, [
Grants.SlackChannelsRead,
]),
],
});
```
You'll need to pass this token along with the public API key to the `KnockProvider` that wraps `KnockSlackProvider` and the rest of your components. We recommend storing the generated user token in local storage so that your client application has easy access to it.
### Adding provider components
In order to give your components the data they need, they must be wrapped in the `KnockSlackProvider`. We recommend putting this high in your component tree so that any Slack components that you use will be rendered within it. The Slack provider goes inside of the `KnockProvider`. Your hierarchy will look like this:
```javascript title="Wrap your UI components in data providers"
{child components}
```
The `KnockSlackProvider` gives your components access to the status of the connection to your Slack app, so that they can all be in sync when a user is connecting, disconnecting, or experiencing a connection error.
### Implementing the OAuth flow with `SlackAuthButton`
Your users will give your Slack app access to their own Slack workspaces via the `SlackAuthButton`. This button can be used on its own, or nested in the `SlackAuthContainer` for a bigger visual footprint.
The SlackAuthButton component with SlackAuthContainer
Since we'll also be using this `access_token` to resolve a user's email address to their Slack ID, we'll need to add some additional scopes to this OAuth request. We can do that by adding the `users:read` and `users:read.email` scopes to the `SlackAuthButton` component with the `additionalScopes` parameters.
Here's an example of how to use them:
```javascript title="Initiate OAuth and display auth state with SlackAuthButton"
// Without container
// With container
}
/>
```
The `SlackAuthButton` maps a tenant in your product to a customer's Slack workspace. This means in most cases you'll just need a single instance of the `SlackAuthButton`.
Remember to consider which roles in your application can access the `SlackAuthButton` component. Knock does not control access to the component. In most cases, you'll add this connect button and container in the settings area of your product.
### Resolving a user's Slack ID
To send a direct message to a user in Slack, you'll need to resolve their email address to their Slack ID. You can do this one of two ways: automatically using Knock's email-based user ID resolution, or manually by making a request to the Slack API with the `access_token` stored in Knock.
#### Enabling email-based user ID resolution
This feature requires you to store an access_token for the
Slack workspace as{" "}
channel data on a tenant
{" "}
in Knock. Our SlackKit components will do this for you automatically.
}
/>
Knock's email-based user ID resolution handles the complexity of resolving a user's Slack ID for you. Here's how it works.
When the email-based user ID resolution setting is enabled and a workflow is triggered for a user recipient who does not have stored channel data, Knock will automatically make a request to the `users.lookupByEmail` endpoint of the Slack API to resolve the user's Slack ID before sending the message. When this Slack API request succeeds, Knock will automatically add the Slack user ID to the user's channel data so that the API request does not need to be repeated in the future. Note that this API request will only be made when the user has a [valid email attribute](/concepts/users#optional-attributes).
To use this feature, you must request the `users:read` and `users:read.email` scopes during the OAuth flow. See [How to connect Slack to Knock](/integrations/chat/slack/overview#how-to-connect-slack-to-knock) for more information about Slack scopes. If you're using SlackKit's `SlackAuthButton` component to manage the OAuth flow, you can use the `additionalScopes` prop to request these scopes.
```javascript title="Requesting the users:read and users:read.email scopes with SlackAuthButton"
// Without container
```
If you're using the `useSlackAuth` [hook](/in-app-ui/react/sdk/hooks/use-slack-auth) directly instead of `SlackAuthButton`, pass the scopes via the `additionalScopes` option:
```javascript title="Requesting the users:read and users:read.email scopes with the useSlackAuth hook"
const { buildSlackAuthUrl } = useSlackAuth(slackClientId, redirectUrl, {
additionalScopes: ["users:read", "users:read.email"],
});
```
If you enable the email-based user ID resolution setting but you haven't
already been requesting the users:read and{" "}
users:read.email scopes, any of your application's tenants
who have already connected their Slack workspace to Knock will need to
complete the OAuth flow again to re-authorize your app.{" "}
Otherwise, the Slack API request will fail.
}
/>
Once you're confident that all of your application's tenants have granted authorization with the required scopes, you can enable this setting on either a Slack channel or a step in a workflow.
In the dashboard, navigate to the **Channels and sources** page under your account settings and select your Slack integration. Click the “Manage configuration” button for one of your environments to open the channel configuration dialog.
Locate the toggle labeled “Enable email-based user ID resolution” and
toggle it on.
Click the “Update settings” button to save your changes.
In the dashboard, navigate to the **Workflows** page and select your
workflow. Click on an existing Slack step in the workflow.
Under “Channel settings” in the right panel, locate the toggle labeled
“Enable email-based user ID resolution” and toggle it on.
#### Manually resolving a user's Slack ID
If you wish to manually resolve a user's Slack ID from their email address, you can do so from your application's backend by making a request to the Slack API with the `access_token` stored in Knock. Here's an example of how you might create a `fetchUserId` function to do this using the Knock Node SDK:
```javascript
export async function fetchUserId(email: string): Promise {
// First, get the access token from Knock for the user's tenant
const channelData = await knock.objects.getChannelData(
"$tenants",
'knocklabs',
process.env.NEXT_PUBLIC_KNOCK_SLACK_CHANNEL_ID as string,
);
// Next, use that access to make a request to the Slack API
const response = await fetch(
`https://slack.com/api/users.lookupByEmail?email=${email}`,
{
headers: {
Authorization: `Bearer ${channelData.data.token.access_token}`,
},
},
);
const data = await response.json();
if (data.ok) {
// If the request is successful, save the user's Slack ID as channel data on the user
await knock.users.setChannelData(
userId,
process.env.NEXT_PUBLIC_KNOCK_SLACK_CHANNEL_ID as string,
{
data: {
connections: [{ user_id: slackUserId }]
},
},
);
}
return data;
}
```
We'll break this function down step-by-step:
Since your users have already connected their Slack workspace to Knock, you can use the `knockClient.objects.getChannelData` method to get the `access_token` for the user's tenant. Tenants in Knock are stored in a system-reserved object collection called `$tenants`.
```javascript
await knock.objects.getChannelData(
"$tenants",
'knocklabs',
process.env.NEXT_PUBLIC_KNOCK_SLACK_CHANNEL_ID as string,
);
```
Once you have the tenant's `access_token`, you can use it to make a request to the Slack API to resolve the user's email address to their Slack ID using the `users.lookupByEmail` endpoint.
```javascript
const response = await fetch(
`https://slack.com/api/users.lookupByEmail?email=${email}`,
{
headers: {
Authorization: `Bearer ${channelData.data.token.access_token}`,
},
},
);
```
Assuming the request to the Slack API is successful, you can save the user's Slack ID as channel data on the user in Knock. This will allow you to send messages to the user's Slack DM channel.
```javascript
await knock.users.setChannelData(
userId,
process.env.NEXT_PUBLIC_KNOCK_SLACK_CHANNEL_ID as string,
{
data: {
connections: [{ user_id: slackUserId }]
},
},
);
```
## Triggering a workflow
Once you have saved the user's Slack ID as channel data, you can trigger a workflow to send a message to that user's DM channel. Here's an example of how to trigger a workflow using the Knock Node SDK:
```javascript
const workflow_run_id = await knockClient.workflows.trigger("new-issue", {
recipients: ["user_1n38knd"],
tenant: "knocklabs",
data: {
message: formData.get("newIssue"),
},
});
```
## Sending a message to channels
How to configure and send notifications to Slack channels.
---
title: Sending a message to public and private channels
description: "How to configure and send notifications to Slack channels."
tags: ["slack", "chat"]
section: Integrations > Slack
layout: integrations
---
In this documentation we'll cover how to create a self-serve Slack integration for a multi-tenant application using Knock. It assumes that you have already created a Slack app and created a Slack channel in Knock as outlined in the [Slack integration](/integrations/chat/slack/overview) documentation.
In this implementation, your application's users will connect their Slack workspace to Knock and be able to send messages to public and private channels. To make this easier to implement, we'll use Knock's [SlackKit components](/in-app-ui/react/slack-kit) to facilitate the OAuth flow and channel selection process.
## Key concepts
SlackKit connects multiple concepts in Knock to make it easier for your users to create a Slack integration. There are two key concepts you'll see throughout the following docs that are foundational to how SlackKit works, but might not be used in every implementation of Knock: tenants and objects.
### About tenants
[Tenants](/concepts/tenants) in Knock are meant to represent groups of users who typically share the same resources. You might call these "accounts," "organizations," "workspaces," or something similar. In a standard SlackKit implementation, you'll store a Slack workspace's `access_token` on a corresponding tenant in Knock. See [how the tenant access token is used at send time](/integrations/chat/slack/overview#tenant-channel-data-requirements) for the full model.
If you already use Knock's tenant concept to power other 'account-based' features, you likely create tenants in Knock when an account or organization is created in your application. If you don't already use tenants in Knock, SlackKit can create tenants for you on the fly if they don't already exist.
Our best-practice recommendation is that tenants in Knock should map
one-to-one to whatever abstraction you use to model accounts,
organizations, or workspaces. You can think of tenants as the top-level
container within your data model that you use to power multi-tenancy in
your application.
}
/>
### About objects
[Objects](/concepts/objects) in Knock are flexible abstractions meant to map to a resource in your system. Each individual object in Knock exists within a `collection` and requires an `id` unique to that collection.
In the context of SlackKit, objects serve two purposes. First, they store the Slack channel or channels you want to notify. Second, they act as the recipient of the workflow that sends a message to Slack.
You can think of collections as the different tables within your database
that represent resources in your application. Objects are the rows within
those tables.
}
/>
#### Example
Let's say we're building an example source control application like GitHub, where teams can collaborate and share code repositories. In this context, each GitHub organization would map to a tenant in Knock, and each repository would become an object inside of a `repositories` collection.
If we want to be notified in Slack each time an issue is opened against a repository, we would store a Slack channel on each repository object and then trigger a `new-issue` workflow. Knock will use the data stored on the object and tenant to route a message to the correct Slack channel:
```javascript
await knockClient.workflows.trigger("new-issue", {
recipients: [
{
collection: "repositories",
id: "knocklabs/javascript",
},
],
tenant: "knocklabs",
data: {
message: formData.get("newIssue"),
},
});
```
### Merging channel data
In this implementation, we'll actually store [the required channel data](/in-app-ui/react/slack-kit#channel-data-requirements) for a `SlackConnection` across two different entities in Knock: a `Tenant` and an `Object`. This is because we want to store the `access_token` for the Slack workspace on the `Tenant` and the `channel_id` for the Slack channel on the `Object`.
When you trigger a workflow using this recipient and tenant, Knock uses the destination stored on the `Object` (the `channel_id`) and the access token stored on the `Tenant` for auth — if the object also carries a token, the tenant's takes precedence (see [auth vs. destination](/integrations/chat/slack/overview#how-slack-delivery-works)). By storing the `access_token` on the `Tenant`, your customers only need to complete the OAuth flow once to connect their Slack workspace to Knock.
## Implementing SlackKit
To facilitate the OAuth flow and channel selection process, we'll use Knock's [SlackKit components](/in-app-ui/react/slack-kit). SlackKit is a set of React components that make it easier to build Slack integrations in Knock. You can use SlackKit to build a self-serve Slack integration that allows your application's users to connect their Slack workspace to Knock and send messages to public and private channels.
### Signing a user token
The only access you'll need to manage when using SlackKit are grants for your users to interact with their [Tenants](/concepts/tenants) and [Objects](/concepts/objects) in Knock. This is necessary because the user in this context is an end user in your application who does not have access to Knock as a [member of the account](/manage-your-account/managing-members). Therefore, these grants provide them elevated privileges to operate on specific resources using the API.
We've made it easy for you to tell Knock which resources your users should have access to by making it a part of their user token. In this section you'll learn how to generate these grants using the Node SDK and, if you're not using the SDK, how to structure them for other languages.
You'll need to generate a token for your user that includes access to the tenant storing the Slack access token as well as any recipient objects storing Slack channel data described in this reference on [SlackKit resource access grants](/in-app-ui/react/slack-kit#resources-access-grants).
Using the below example, you can quickly generate a token with the Node SDK.
```javascript
import {
signUserToken,
buildUserTokenGrant,
Grants,
} from "@knocklabs/node/lib/tokenSigner";
const token = await signUserToken("user-1", {
grants: [
buildUserTokenGrant({ type: "tenant", id: "org_3sh72ds78" }, [
Grants.SlackChannelsRead,
]),
buildUserTokenGrant(
{ type: "object", id: "repo-1", collection: "repositories" },
[Grants.ChannelDataRead, Grants.ChannelDataWrite],
),
],
});
```
You'll need to pass this token along with the public API key to the `KnockProvider` that wraps `KnockSlackProvider` and the rest of your components. We recommend storing the generated user token in local storage so that your client application has easy access to it.
### Adding provider components
In order to give your components the data they need, they must be wrapped in the `KnockSlackProvider`. We recommend putting this high in your component tree so that any Slack components that you use will be rendered within it. The Slack provider goes inside of the `KnockProvider`. Your hierarchy will look like this:
```javascript title="Wrap your UI components in data providers"
{child components}
```
The `KnockSlackProvider` gives your components access to the status of the connection to your Slack app, so that they can all be in sync when a user is connecting, disconnecting, or experiencing a connection error.
### Implementing the OAuth flow with `SlackAuthButton`
Your users will give your Slack app access to their own Slack workspaces via the `SlackAuthButton`. This button can be used on its own, or nested in the `SlackAuthContainer` for a bigger visual footprint.
The SlackAuthButton component with SlackAuthContainer
Here's an example of how to use them:
```javascript title="Initiate OAuth and display auth state with SlackAuthButton"
// Without container
// With container
}
/>
```
The `SlackAuthButton` maps a tenant in your product to a customer's Slack workspace. This means in most cases you'll just need a single instance of the `SlackAuthButton`.
Remember to consider which roles in your application can access the `SlackAuthButton` component. Knock does not control access to the component. In most cases, you'll add this connect button and container in the settings area of your product.
### Choosing channels with `SlackChannelCombobox`
This combobox contains the list of channels in the connected Slack workspace. Your users will use this combobox to search and select a channel (or more than one channel) to be notified when an event in your application occurs, for example a comment on a video. They can also use this combobox to deselect a connected channel.
The combobox automatically shows which channels are already connected, and gives users an easy way to remove them as well.
The SlackChannelCombobox component showing connected channels
Add your combobox to your application where you'd like the user to select channels to notify:
```javascript title="The SlackChannelCombobox connects an object to one or more channels"
```
The combobox will only show channels for Slack workspaces with fewer
than 1000 channels (public and private; not including archived). If
there are more, the combobox will turn into a text input that accepts
a channel ID to connect.
The combobox will only show private channels from your users' Slack
workspaces if your Slack app has been invited to those channels.
The combobox does not show individual users for Slack direct messages.
}
/>
## Triggering a workflow
Once you have used the `SlackChannelCombobox` to connect an object to one or more channels, you can trigger a workflow to send a message to those channels. Here's an example of how to trigger a workflow using the Knock Node SDK:
```javascript
const workflow_run_id = await knockClient.workflows.trigger("new-issue", {
recipients: [
{
collection: "repositories",
id: "knocklabs/javascript",
},
],
tenant: "knocklabs",
data: {
message: formData.get("newIssue"),
},
});
```
## Overriding recipient connections
Override where a Slack chat message is delivered from the template's settings, instead of using the recipient's stored connections.
---
title: Overriding a message's recipient connection
description: Override where a Slack chat message is delivered from the template's settings, instead of using the recipient's stored connections.
tags: ["slack", "chat"]
section: Integrations > Slack
layout: integrations
---
By default, a Slack step delivers to the [channel data](/managing-recipients/setting-channel-data) stored on the recipient. A **recipient connection override** lets a single message template deliver somewhere else — a fixed channel, a specific user, or an incoming webhook — regardless of the recipient's stored connections.
This is useful when a message should go somewhere other than the recipient's configured destination: an alerts channel, an internal operations channel, or a dynamic destination you compute per-recipient with Liquid.
Recipient connection overrides also determine the destination for [replies to existing Slack threads](/integrations/chat/replying-to-chat-messages#reply-to-an-existing-thread). The parent message timestamp and destination channel are separate values and must refer to the same Slack conversation.
## Setting the override
In the workflow builder, open the Slack step's template, then open **Template settings** (the gear icon) and set the **Recipient connection** field.
The override is stored on the message template, so it travels with the workflow when you commit and promote it across environments.
## How it changes delivery
The override **replaces** the recipient's connections for this message: exactly one message is delivered, to the connection you specify. If the value is empty or renders to invalid JSON at send time, the message is left undelivered with failure details you can inspect on the message.
## What you can specify
The override is a JSON object in one of two shapes.
### Incoming webhook
Post to one fixed Slack incoming webhook URL:
```json
{
"incoming_webhook": {
"url": "https://hooks.slack.com/services/T00000000/B00000000/XXXX"
}
}
```
### Channel or direct message with a bot token
Send to a channel (`channel_id`) or a user's direct message (`user_id`), authenticated with a bot token:
```json
{ "channel_id": "C0123456789", "access_token": "xoxb-your-bot-token" }
```
You can leave out `access_token` and let it come from the [access token stored on the tenant](/integrations/chat/slack/overview#tenant-channel-data-requirements) you trigger the workflow with. In that case, provide only the destination:
```json
{ "channel_id": "C0123456789" }
```
## Using Liquid for dynamic destinations
The value is Liquid-capable and rendered at send time, so you can route each message dynamically from workflow or recipient data:
```json
{ "channel_id": "{{ recipient.slack_channel }}" }
```
Recipient connection overrides are currently supported for Slack chat
channels.
}
/>
## Microsoft Teams
## Overview
Learn how to use Knock to send Microsoft Teams notifications to your users.
---
title: Microsoft Teams notifications with Knock
description: Learn how to use Knock to send Microsoft Teams notifications to your users.
tags: ["msteams", "teams", "chat"]
section: Integrations > Microsoft Teams
layout: integrations
---
This page covers how to use Knock to send notifications to Microsoft Teams. Depending on your use case, there are a few different ways to approach this integration. This documentation serves as a starting point and will cover the basics of setting up a Microsoft Teams integration with Knock regardless of your use case.
## Supported notification methods
Today, Knock supports sending notifications to Microsoft Teams using two different methods:
- Using an incoming webhook URL. This is suitable for [internal or one-off integrations](/integrations/chat/microsoft-teams/sending-an-internal-message).
- As a Microsoft Teams bot registered with Azure. This is suitable for bots published to the Microsoft Teams Store, and supports both [sending notifications to channels](/integrations/chat/microsoft-teams/sending-a-message-to-channels) and [sending direct messages to users](/integrations/chat/microsoft-teams/sending-a-direct-message).
With a bot-based connection, you can [reply to a previous chat step or an existing Microsoft Teams thread](/integrations/chat/replying-to-chat-messages). Incoming webhook connections can only post new messages.
How you configure your Microsoft Teams channel in Knock depends on the method you choose.
## Prerequisites
If you're using an incoming webhook URL, there are no prerequisites. If you're using a Microsoft Teams bot, you'll need to follow the steps below to enable your users to connect your Teams app to their Microsoft Teams workspaces. Knock does not manage deploying and configuring your bot.
Additionally, if you intend to use our [TeamsKit](/in-app-ui/react/teams-kit) SDK or Knock's [Microsoft Teams-related React hooks](/in-app-ui/react/teams-kit#using-teamskit-headless), you'll need to [configure a Graph API-enabled application in the Microsoft Entra admin center](#configure-graph-api-in-microsoft-entra).
### Register a new bot
As of July 31, 2025, Microsoft no longer allows the creation of
multi-tenant bots in Azure. If you're registering a new bot, you'll need
to register it as single-tenant and{" "}
publish it to the Microsoft Teams app store
{" "}
within a cross-tenant app so that it can be installed across customer
workspaces.
}
/>
If you haven't already, you'll need to create a bot with the Bot Framework SDK and register it in Azure. Once your bot is created, you'll need to deploy it to Azure so that it can be used by your customers.
### Configure Graph API in Microsoft Entra
To use TeamsKit, you'll also need to configure the API permissions and OAuth redirect URL associated with a Graph API-enabled application in the Microsoft Entra admin center. You can use the bot application that has already been registered with Azure, or you can use a separate application.
Log in to the Microsoft Entra admin center. In the sidebar, navigate to **Entra ID** > **App registrations**, and locate your application.
On your app's registration page, click **Authentication**. Under **Platform configurations**, click **Add a platform** and select **Web**.
Copy and paste the following URL into the **Redirect URI** text field:
This will allow Knock to handle the OAuth redirect on behalf of your app, and manage connecting a Microsoft Entra tenant to a Knock tenant.
Under **Supported account types**, select **Accounts in any organizational directory (Any Microsoft Entra ID tenant - Multitenant)**.
Click **Configure** to save your changes.
In the top-level sidebar, navigate to **API permissions** and click **Add a permission**. Select **Microsoft Graph** > **Application permissions**.
Under **Select permissions**, add the following permissions:
- `Team.ReadBasic.All`: This permission allows your application to read a list of all teams within a Microsoft Entra tenant.
- `Channel.ReadBasic.All`: This permission allows your application to read a list of all channels within a team.
- `AppCatalog.Read.All`: This permission allows your application to locate itself in the Microsoft Teams app catalog.
- `TeamsAppInstallation.ReadWriteSelfForTeam.All`: This permission allows your application to install itself into a team.
- `TeamsAppInstallation.ReadWriteSelfForUser.All`: This permission allows your application to install itself into a user's personal scope.
Click **Add permissions** to save your changes.
### Publish your app to the Microsoft Teams Store
The Microsoft Teams Store submission process is managed entirely by
Microsoft and typically takes 4–6 weeks to complete. We recommend
reviewing Microsoft's{" "}
app submission guide
{" "}
ahead of time to understand what's required, as there are several steps
involved.
}
/>
Before you can start sending production notifications to your customers, you'll need to publish an app package to the Microsoft Teams Store.
The Teams app package includes a `manifest.json` file that contains the configuration for your bot. The required `scopes` will depend on the specific use case that you're targeting; see the documentation on [sending messages to public channels](/integrations/chat/microsoft-teams/sending-a-message-to-channels#adding-required-scopes-to-your-apps-manifest) and [sending direct messages](/integrations/chat/microsoft-teams/sending-a-direct-message#adding-required-scopes-to-your-apps-manifest) for more details.
While your submission is under review, you can test your integration end-to-end by sideloading your app into a tenant directly. Download your Teams app as a `.zip` package from the Teams Developer Portal, then upload it to the Teams Admin Center of the tenant you want to test in under **Teams apps** > **Manage app** > **Upload**. This makes your app available in that tenant's catalog without needing to wait for store approval.
## How to connect to Teams with Knock
To set up Knock to send notifications as your bot, you'll need your bot's ID and password. These are sometimes called the App ID and App Password, and were provided to you when you registered your bot with Azure or the Microsoft Teams Developer Portal.
### Add Teams to Knock as a channel
First you'll need to add Teams as a channel in Knock. Navigate to Integrations > Channels in your Knock dashboard account settings and click “Create channel” to add Microsoft Teams.
If you're using an incoming webhook URL, no additional environment configuration is required.
If you're using a Microsoft Teams bot, follow these steps to configure your bot in the Knock dashboard.
Click “Manage configuration” and scroll down to “Provider settings”.
Before selecting a bot type in Knock, you'll first want to confirm how your bot is registered in Azure. You can locate both the Bot Type and App (Entra) Tenant ID in the Azure Portal by
navigating to your Azure Bot resource and selecting “Settings” > “Configuration” in the sidebar to view your
bot’s configuration details. The “Bot Type” dropdown menu will indicate whether your bot is single-tenant or multi-tenant (legacy). The “App Tenant ID” text field will display the ID of your Entra tenant.
“Bot Type” and “App Tenant ID” fields on the Azure Bot resource configuration page
If your bot is registered with Azure as a single-tenant bot, select “Single-tenant”.
Then, in the “Entra tenant ID” text field, enter the ID of the Microsoft
Entra tenant in which your bot is registered.
If your bot is registered with Azure as a multi-tenant bot, select “Multi-tenant” in the “Bot type” dropdown.
Entering an “Entra tenant ID” is not required for multi-tenant bots. Note that this applies only to existing legacy multi-tenant bots. New Microsoft Teams bots must be registered as single-tenant in Azure.
In the “Bot ID” and “Bot password” fields, enter the ID and password
associated with your bot. Click the “Update settings” button to save your
changes.
If you intend to use TeamsKit, you'll need to enter the client ID and secret associated with a [Graph API-enabled application](#configure-graph-api-in-microsoft-entra) registered with Microsoft Entra.
In the “Graph API client ID” and “Graph API client secret” fields, enter the client ID and secret associated with your application. If you registered your bot application in Entra for this purpose, the values for these fields will be the same as the bot ID and password in the previous step.
Click the “Update settings” button to save your changes.
### Add a Teams channel step to a workflow
Next, navigate to a workflow in Knock that you want to notify Teams and add a chat channel step. Select the Teams channel you just configured and create a notification template for the channel.
You can learn more about how to write basic and advanced templates for Teams in the [designing notifications templates section](#designing-notification-templates-for-teams) below.
### Trigger the workflow
Now you're ready to notify Teams. [Trigger the workflow](/send-notifications/triggering-workflows) that you added your Teams channel to. You'll need to include a user or object that has [Teams channel data](#how-to-set-channel-data-for-a-microsoft-teams-integration-in-knock) set as the `recipient` on the workflow trigger call; if no `channel_data` is set on the recipient, the Teams step will be skipped.
Your Teams channel should have received a notification. If you need to debug your integration, you can view the logs page in the Knock dashboard.
## How to set channel data for a Microsoft Teams integration in Knock
In Knock, the [`ChannelData`](/managing-recipients/setting-channel-data) concept provides you a way of storing recipient-specific connection data for a given integration. If you reference the [channel data requirements for Microsoft Teams](/managing-recipients/setting-channel-data#microsoft-teams-channel-data), you'll see that there are two different schemas for an `MsTeamsConnection` stored on a [`User`](/concepts/users) or an [`Object`](/concepts/objects) in Knock.
Here's an example of setting channel data on an `Object` in Knock.
In the example above, the KNOCK_TEAMS_CHANNEL_ID variable is
the id of the Knock channel you've created to represent your Microsoft
Teams integration within the Knock dashboard. You can find it by going to{" "}
Integrations {">"}{" "}
Channels{" "}
in the Knock dashboard and then copying the ID of your Microsoft Teams
channel.
}
/>
### How Teams delivery works
When you're sending as a Microsoft Teams bot, every notification needs two things, and Knock lets them live in different places:
- **Scope** — which Microsoft Entra tenant to reach: the `ms_teams_tenant_id`.
- **Destination** — where the message goes: a `ms_teams_channel_id` (a channel) or a `ms_teams_user_id` (a direct message).
The **destination** is stored on the recipient (a [`User`](/concepts/users) or [`Object`](/concepts/objects)). The **scope** can be stored on the recipient too — or, in a multi-workspace product, once on the [tenant](#tenant-channel-data-requirements), so every recipient in that tenant shares the same Entra tenant ID. The two sections below cover each location.
If you're using an incoming webhook instead of a bot, none of the above applies: the webhook URL is self-contained and requires no scope or destination.
### Recipient channel data requirements
Here's an overview of the data requirements for [setting recipient channel data](/send-notifications/setting-channel-data) for either an incoming webhook URL or a Microsoft Teams bot connection. Both will need to live under the `connections` key.
| Property | Type | Description |
| ----------- | --------------------- | ------------------------------------------ |
| connections | `MsTeamsConnection[]` | One or more connections to Microsoft Teams |
An `MsTeamsConnection` can have one of two schemas, depending on whether you're using a Microsoft Teams bot or an incoming webhook.
If you're using a Microsoft Teams bot, your `MsTeamsConnection` schema looks like this. You'll use
either `ms_teams_channel_id` or `ms_teams_user_id` depending on whether you're storing connection data to message a channel or user in Microsoft Teams:
| Property | Type | Description |
| ------------------- | -------- | ------------------------------ |
| ms_teams_tenant_id | `string` | A Microsoft Entra tenant ID |
| ms_teams_team_id | `string` | A Microsoft Teams team ID |
| ms_teams_channel_id | `string` | A Microsoft Teams channel ID |
| ms_teams_user_id | `string` | A Microsoft Teams user ID |
If you're using an incoming webhook, your `MsTeamsConnection` schema is quite simple:
| Property | Type | Description |
| -------------------- | -------- | --------------------------------------------------------------------------- |
| incoming_webhook.url | `string` | The Microsoft Teams incoming webhook URL (to be used instead of the properties above) |
### Tenant channel data requirements
When you [map a Microsoft Entra tenant to a Knock tenant](/integrations/chat/microsoft-teams/sending-a-message-to-channels#key-concepts) (as our [TeamsKit](/in-app-ui/react/teams-kit) components do), you store that Entra tenant's ID as `channel_data` on the Knock tenant. At send time, when you trigger a workflow with that `tenant`, Knock takes the [destination](#how-teams-delivery-works) from the recipient's `channel_data` (the `ms_teams_channel_id` or `ms_teams_user_id`) and uses the tenant's `ms_teams_tenant_id` for scope: the tenant provides the scope, the recipient provides the destination. If the recipient also carries an `ms_teams_tenant_id`, the tenant's takes precedence — so the `ms_teams_tenant_id` on the recipient's `MsTeamsConnection[]` above is not required when a tenant holds one.
**Do you need a tenant?** Store the Entra tenant ID on a Knock tenant when one Microsoft Entra tenant connection should serve every recipient or object in that Knock tenant. This keeps the Entra tenant ID in one place while each recipient or object stores only its Teams destination (`ms_teams_channel_id` or `ms_teams_user_id`), which is useful as you add more destinations within the same Entra tenant later. You don't need a Knock tenant if you post to a single internal workspace (use an incoming webhook — there's no Entra tenant ID to share) or only ever use one Entra tenant's ID and prefer to store it directly on each recipient or object. Knock never auto-creates a `tenant` for you (though TeamsKit can, on the fly), so use one when a shared Entra tenant ID should live at the `tenant` level.
Here's an overview of the data requirements for setting channel data when storing a Microsoft Entra tenant ID on a Knock tenant.
| Property | Type | Description |
| ------------------ | -------- | --------------------------- |
| ms_teams_tenant_id | `string` | A Microsoft Entra tenant ID |
```json title="Microsoft Teams channel_data on a tenant"
{
"ms_teams_tenant_id": "MS_TEAMS_TENANT_ID"
}
```
### Setting channel data: users vs. objects
Depending on the Microsoft Teams integration you build into your product, you'll store the connection data you receive from Microsoft Teams as `channel_data` on either a `User` or an `Object` in Knock.
If your integration involves a user opting in to receive direct messages from your Microsoft Teams integration, you’ll be storing the channel data [on that user](/api-reference/users/set_channel_data) in Knock. When you want to notify this user, you'll include them as a recipient in a Knock workflow trigger.
For this integration, you'll store a user's Microsoft Teams `ms_teams_user_id` in the `MsTeamsConnection` object.
If your integration involves a customer connecting a _non-user resource_ in their product (such as a project or a page) to a Microsoft Teams channel, you’ll want to store that channel data [on an object](/api-reference/objects/set_channel_data) in Knock, as it’s not specific to any single user.
For this integration, you'll store a Microsoft Teams `ms_teams_channel_id` in the `MsTeamsConnection` object. The [`MsTeamsChannelCombobox`](/in-app-ui/react/teams-kit#msteamschannelcombobox) component of Knock's TeamsKit can help you with this.
## Designing notification templates for Teams
When you add a new Teams channel step to a workflow in Knock, you'll need to configure a template for that step so Knock knows how to format the message to Teams.
By default, we provide a basic markdown editor that you can use for sending simple messages to Teams. Just write in Markdown and we'll handle the rest. (Note: As of February 2022, Teams only supports the following markdown styles: bold, italic, unordered lists, ordered lists, hyperlinks. All other markdown styles are not supported.)
### Advanced Teams notifications
If you find yourself wanting to send notifications that include more advanced formatting and interactivity, such as buttons, data layouts, and so on, you'll need to use Microsoft's Adaptive Card format to build your notification templates in Knock. This is essentially a JSON block language you use to lay out your Microsoft Teams message.
To switch to the JSON editor in the Knock template designer, look for the "Switch to JSON editor" button at the bottom of the template editor page. When you're in JSON editing mode, you can provide adaptive card JSON and we'll pass it to Microsoft Teams on your behalf.
Here's an example of the JSON you'll need to provide. Note that you must include your Adaptive Card JSON within the `attachments` array and set the `contentType` to `application/vnd.microsoft.card.adaptive`.
```json title="Example JSON for sending an Adaptive Card to Microsoft Teams"
{
"attachments": [
{
"content": {
"type": "AdaptiveCard",
"$schema": "https://adaptivecards.io/schemas/adaptive-card.json",
"version": "1.5",
"body": [
{
"type": "TextBlock",
"text": "Lorem ipsum dolor sit"
}
],
"speak": "Lorem ipsum dolor sit"
},
"contentType": "application/vnd.microsoft.card.adaptive",
"contentUrl": null
}
],
"type": "message"
}
```
We do not support adaptive card previews in Knock at this time.}
/>
## Sending an internal message
How to send a message to an internal Microsoft Teams workspace using Knock.
---
title: Sending a message to an internal Microsoft Teams workspace
description: How to send a message to an internal Microsoft Teams workspace using Knock.
tags: ["msteams", "teams", "chat"]
section: Integrations > Microsoft Teams
layout: integrations
---
In this documentation we'll cover how to send a message to an internal Microsoft Teams workspace using Knock. It assumes that you have already created a Microsoft Teams channel in Knock as outlined in the [Microsoft Teams integration](/integrations/chat/microsoft-teams/overview) documentation.
## Microsoft Teams channels are connections on Objects
In Knock, we model channels in a Microsoft Teams workspace as connections on Objects. [Objects](/concepts/objects) allow you to model any resource in your system within Knock, and while their primary purpose is to act as non-user recipients, they are very flexible abstractions.
### An overview of Objects
Individual Objects exist within [a collection](/concepts/objects#collection-naming) and always have [a unique ID](/concepts/objects#the-object-identifier) or key within that collection. The Object itself can store any number and type of properties as key-value pairs. You can see some examples of possible Object structures in [the official documentation on setting Object data](/concepts/objects#sending-object-data-to-knock).
Let’s say you are building a devtool product like GitHub and want to set up Microsoft Teams notifications whenever someone comments on an issue within a repository. First, you’ll want to create an Object to model your repository as part of the `repositories` collection:
```javascript
import Knock from "@knocklabs/node";
const knockClient = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await knockClient.objects.set("repositories", "repo-1", {
name: "My repo",
});
```
Once you have a repository object created, you can add the channel data for Microsoft Teams as a connection on the object.
## Objects as workflow recipients
To add channel data, we’ll set up an incoming webhook in Microsoft Teams using the Workflows app (powered by Power Automate). Follow Microsoft’s documentation on creating webhooks using Workflows to generate a webhook URL for the Teams channel you want to post to.
### Set the webhook as channel data
Now that you have the webhook URL, we’ll store that webhook as a special property on the repository Object called channel data. [Channel data is both channel and recipient-specific data](https://docs.knock.app/managing-recipients/setting-channel-data) stored for use with particular channels, like a token used for push notifications or webhooks stored for chat apps like Slack, Teams, and Discord. Both Users and Objects can store channel data.
In the code example below, we’ll use the `knockClient.objects.setChannelData` method to update the channel data for our repository Object.
```javascript
import Knock from "@knocklabs/node";
const knockClient = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await knockClient.objects.setChannelData(
"repositories",
repository.id,
process.env.KNOCK_MS_TEAMS_CHANNEL_ID,
{
connections: [
{
incoming_webhook: { url: "url-from-ms-teams" },
},
],
},
);
```
Here, you’ll also need your `KNOCK_MS_TEAMS_CHANNEL_ID` as the third parameter, which is the channel ID of your Microsoft Teams integration within Knock, so that Knock can reference that channel when it processes workflows that use it. The last parameter is an object of a specific format that varies based on [the type of message provider](/managing-recipients/setting-channel-data#provider-data-requirements). In this case, it is an `MsTeamsConnection` object with an `incoming_webhook` property that contains the URL of an incoming webhook in Microsoft Teams.
### Trigger a workflow with an object recipient
With the channel data in place, you can add Microsoft Teams as a workflow step in any workflow. For this example, we’ll create a `new-issue` workflow that pings users in our connected Microsoft Teams channel whenever someone adds a new issue.
As you create your message template, remember that in this case the repository Object is the recipient of your workflow. That means any properties you reference on your Liquid template tags need to exist as properties of the Object as well:
```markdown
There was an issue opened on the following repo: **{{ recipient.name }}**
```
Finally, we’ll add the workflow trigger to our code with the repository Object as a recipient.
```javascript
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
await knock.workflows.trigger("new-issue", {
recipients: [{ collection: "repositories", id: "repo-1" }],
});
```
With that, you should see a message in your selected Microsoft Teams channel:
## Sending a direct message
How to send a message to a user in Microsoft Teams using Knock.
---
title: Sending a direct message to a user in Microsoft Teams
description: How to send a message to a user in Microsoft Teams using Knock.
tags: ["msteams", "teams", "chat"]
section: Integrations > Microsoft Teams
layout: integrations
---
This page covers how to update a Microsoft Teams bot to send direct messages to Teams users using Knock. It assumes that you have already created a Microsoft Teams channel in Knock as outlined in the [Microsoft Teams integration overview](/integrations/chat/microsoft-teams/overview).
In this implementation, your application's users will connect their Microsoft Entra tenant to Knock and be able to send messages to individual users via direct message. To make this easier to implement, we'll use Knock's [TeamsKit components](/in-app-ui/react/teams-kit) to facilitate the OAuth flow.
## Prerequisites
Make sure your bot has been registered and deployed with Azure. Knock does not manage deploying and configuring your bot. To set up Knock to send notifications as your bot, see [How to connect to Teams with Knock](/integrations/chat/microsoft-teams/overview#how-to-connect-to-teams-with-knock).
## Key concepts
TeamsKit connects multiple concepts in Knock to make it easier for your application's users to start using your Microsoft Teams integration. `Tenants` are a concept you'll see throughout the following docs that are foundational to how TeamsKit works, but might not be used in every implementation of Knock.
### About tenants
[Tenants](/concepts/tenants) in Knock are meant to represent groups of users who typically share the same resources. You might call these "accounts," "organizations," "workspaces," or something similar. In a typical implementation using TeamsKit, you'll store the ID of a Microsoft Entra tenant on a corresponding tenant in Knock. See [how the tenant's Entra tenant ID is used at send time](/integrations/chat/microsoft-teams/overview#tenant-channel-data-requirements) for the full model.
If you already use Knock's tenant concept to power other 'account-based' features, you likely create tenants in Knock when an account or organization is created in your application. If you don't already use tenants in Knock, TeamsKit can create tenants for you on the fly if they don't already exist.
Our best-practice recommendation is that tenants in Knock should map
one-to-one to whatever abstraction you use to model accounts,
organizations, or workspaces. You can think of tenants as the top-level
container within your data model that you use to power multi-tenancy in
your application.
}
/>
### Merging channel data
In this implementation, we'll actually store [the required channel data](/integrations/chat/microsoft-teams/overview#how-to-set-channel-data-for-a-microsoft-teams-integration-in-knock) for an `MsTeamsConnection` across two different entities in Knock: a `Tenant` and an `User`. This is because we want to store the `ms_teams_tenant_id` for the Microsoft Entra tenant on the Knock `Tenant` and the `ms_teams_user_id` for the Microsoft Teams user on the Knock `User`.
When you trigger a workflow using this recipient and tenant, Knock uses the destination stored on the `User` (the `ms_teams_user_id`) and the Entra tenant ID (`ms_teams_tenant_id`) stored on the `Tenant` for scope — if the user also carries an Entra tenant ID, the tenant's takes precedence (see [scope vs. destination](/integrations/chat/microsoft-teams/overview#how-teams-delivery-works)). By storing the `ms_teams_tenant_id` on the Knock `Tenant`, your customers only need to complete the OAuth flow once to connect their Microsoft Entra tenant to Knock. From there, you can create UI that allows users to link their Microsoft Teams user ID to their Knock user ID or automate this process during user registration.
## Adding required scopes to your app's manifest
In order for your bot to send direct messages to users in Microsoft Teams, you'll need to update your Microsoft Teams app's manifest so that it includes the `personal` scope for your bot.
In your `manifest.json` file, add `personal` to your bot's array of scopes:
```json
{
"$schema": "https://developer.microsoft.com/en-us/json-schemas/teams/v1.17/MicrosoftTeams.schema.json",
"manifestVersion": "1.17",
"version": "1.0.0",
"id": "{{YOUR_TEAMS_APP_ID}}",
"bots": [
{
"botId": "{{YOUR_BOT_ID}}",
"scopes": ["personal"]
}
]
}
```
## Implementing TeamsKit
To facilitate the OAuth flow and channel selection process, we'll use Knock's [TeamsKit components](/in-app-ui/react/teams-kit). TeamsKit is a set of React components that make it easier to build Microsoft Teams integrations in Knock. You can use TeamsKit to build a self-serve Microsoft Teams integration that allows your users to connect their Microsoft Teams instances to Knock.
### Signing a user token
The only access you'll need to manage when using TeamsKit are grants for your users to interact with their [Tenant](/concepts/tenants) in Knock. This is necessary because the user in this context is an end user in your application who does not have access to Knock as a [member of the account](/manage-your-account/managing-members). Therefore, these grants provide them elevated privileges to operate on specific resources using the API.
We've made it easy for you to tell Knock which resources your users should have access to by making it a part of their user token. In this section you'll learn how to generate these grants using the Node SDK and, if you're not using the SDK, how to structure them for other languages.
You'll need to generate a token for your user that includes access to the Knock tenant storing the Microsoft Entra tenant ID as well as any recipient objects storing Microsoft Teams channel data described in this reference on [TeamsKit resource access grants](/in-app-ui/react/teams-kit#resource-access-grants).
Using the below example, you can quickly generate a token with the Node SDK.
```javascript
import {
signUserToken,
buildUserTokenGrant,
Grants,
} from "@knocklabs/node/lib/tokenSigner";
const token = await signUserToken("user-1", {
grants: [
buildUserTokenGrant({ type: "tenant", id: "org_3sh72ds78" }, [
Grants.MsTeamsChannelsRead,
]),
],
});
```
You'll need to pass this token along with the public API key to the `KnockProvider` that wraps `KnockMsTeamsProvider` and the rest of your components. We recommend storing the generated user token in local storage so that your client application has easy access to it.
### Adding provider components
In order to give your components the data they need, they must be wrapped in the `KnockMsTeamsProvider`. We recommend putting this high in your component tree so that any TeamsKit components that you use will be rendered within it. The Microsoft Teams provider goes inside of the `KnockProvider`. Your hierarchy will look like this:
```javascript title="Wrap your UI components in data providers"
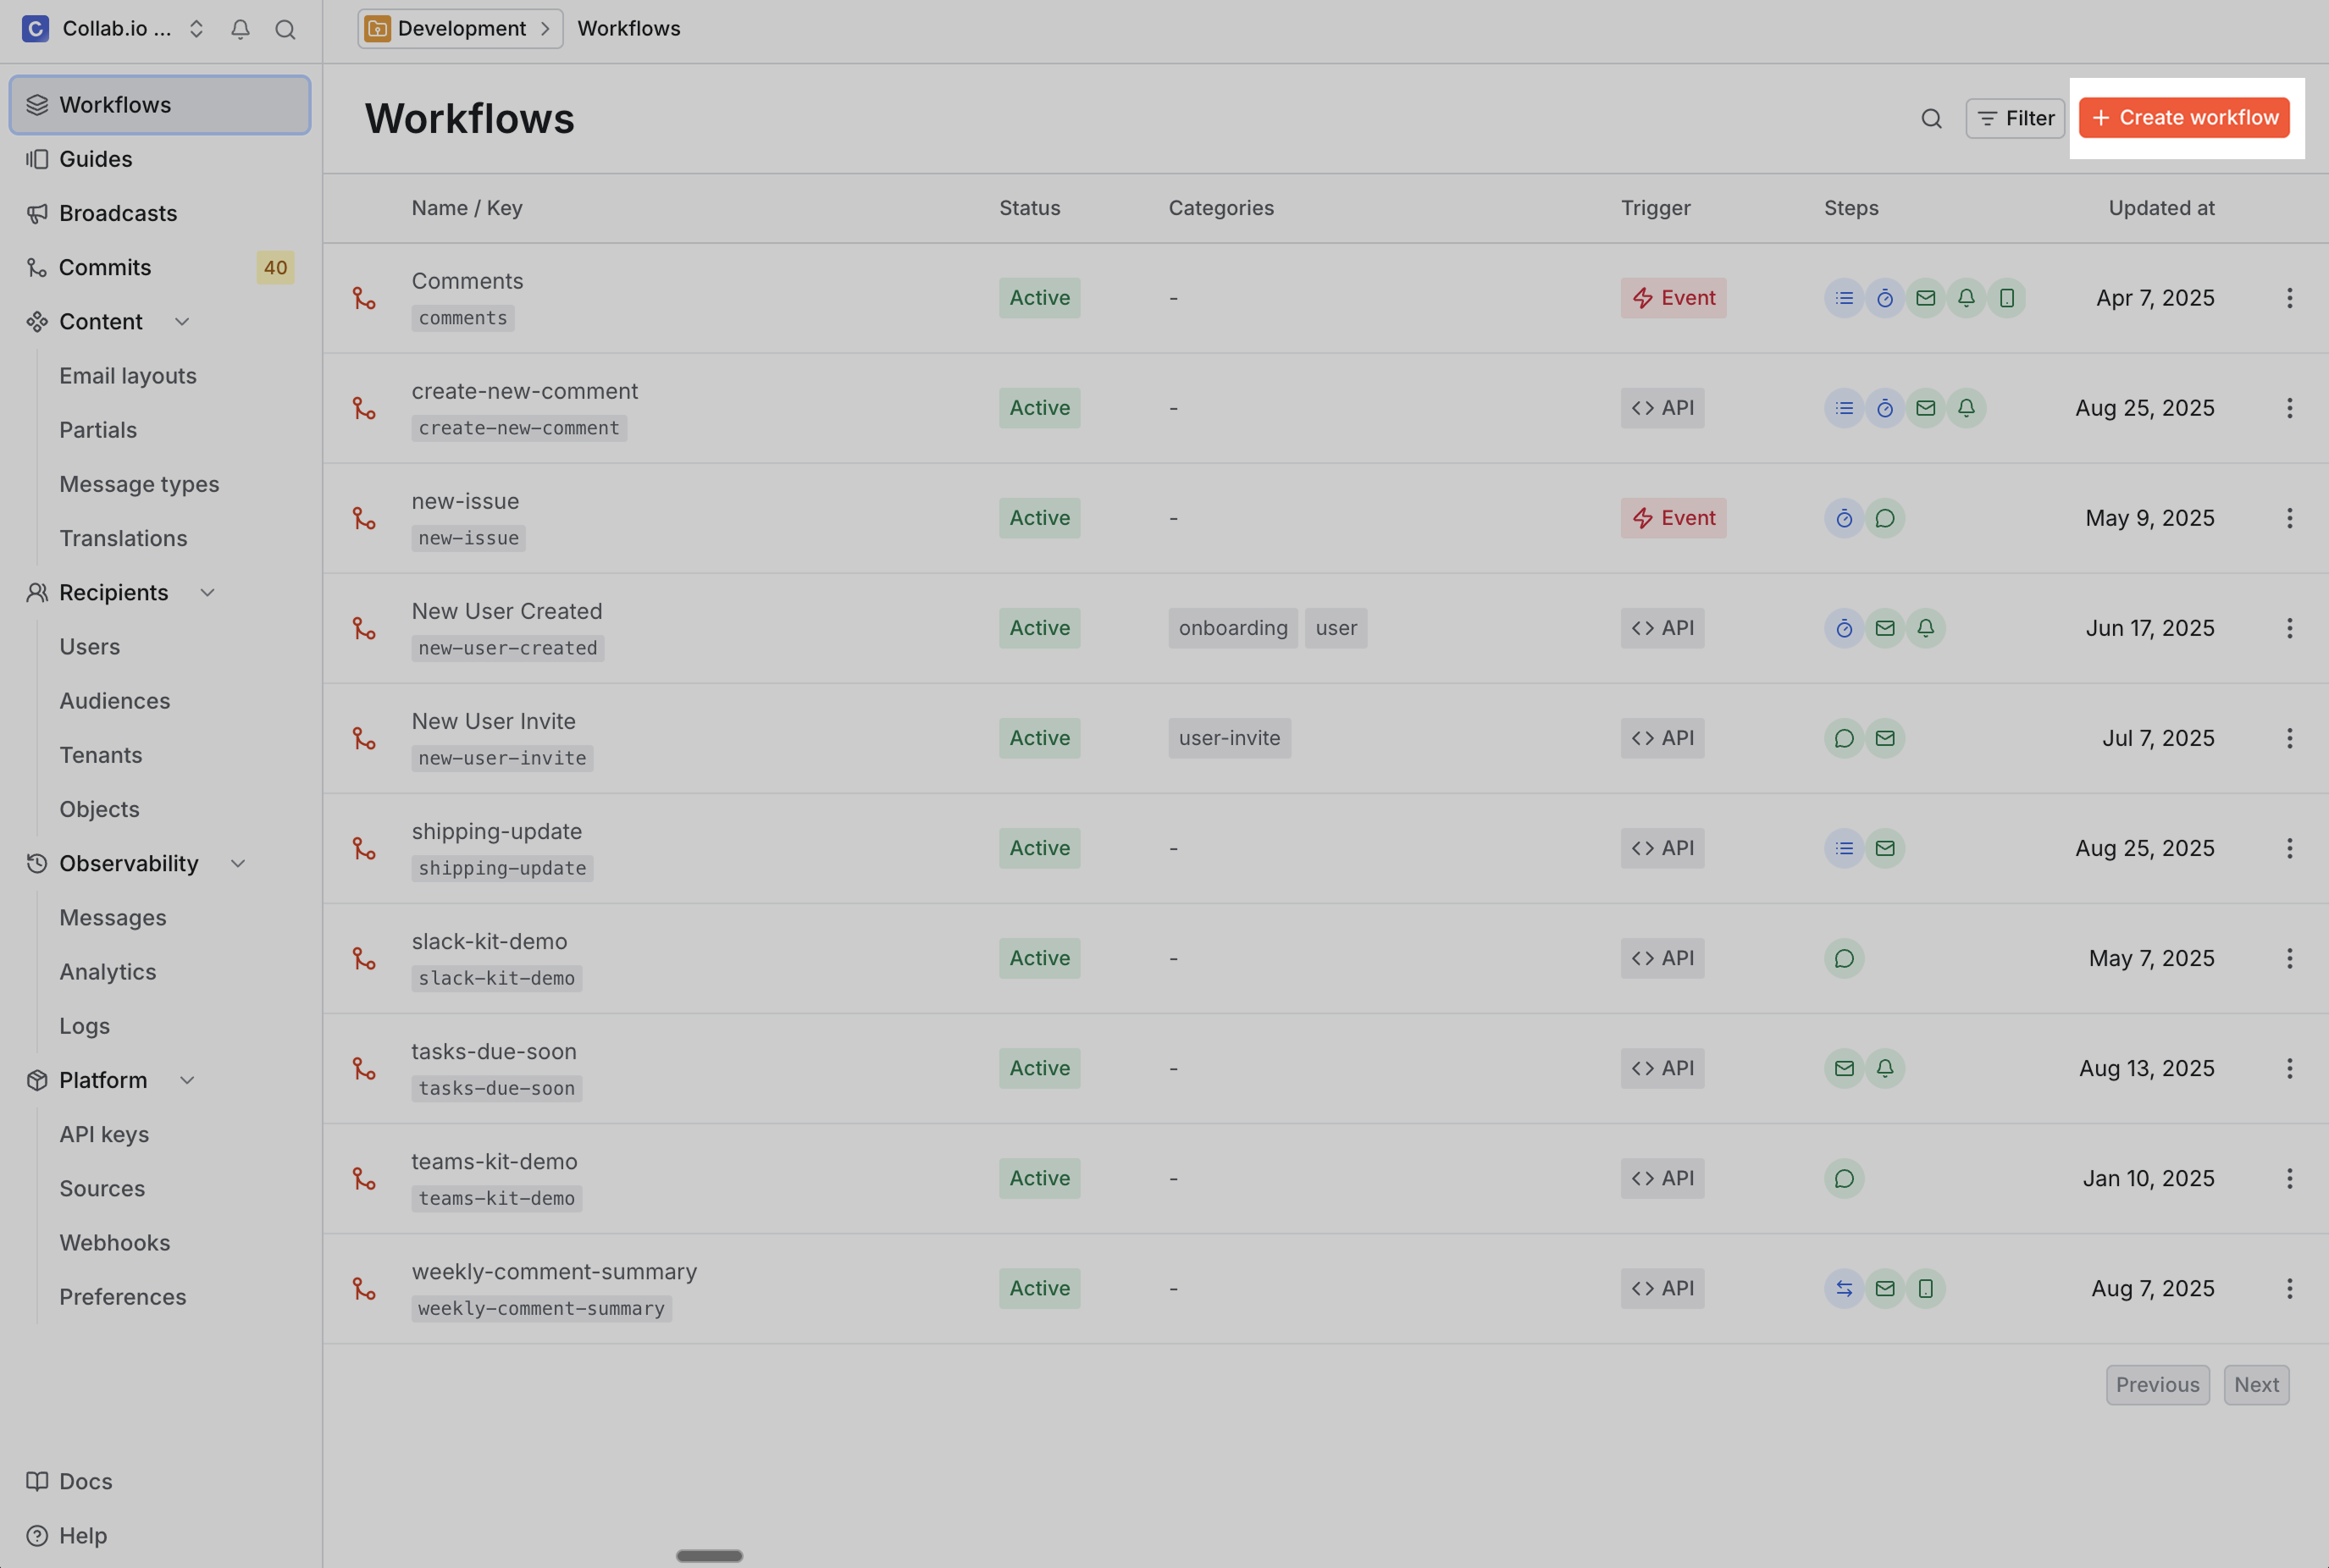
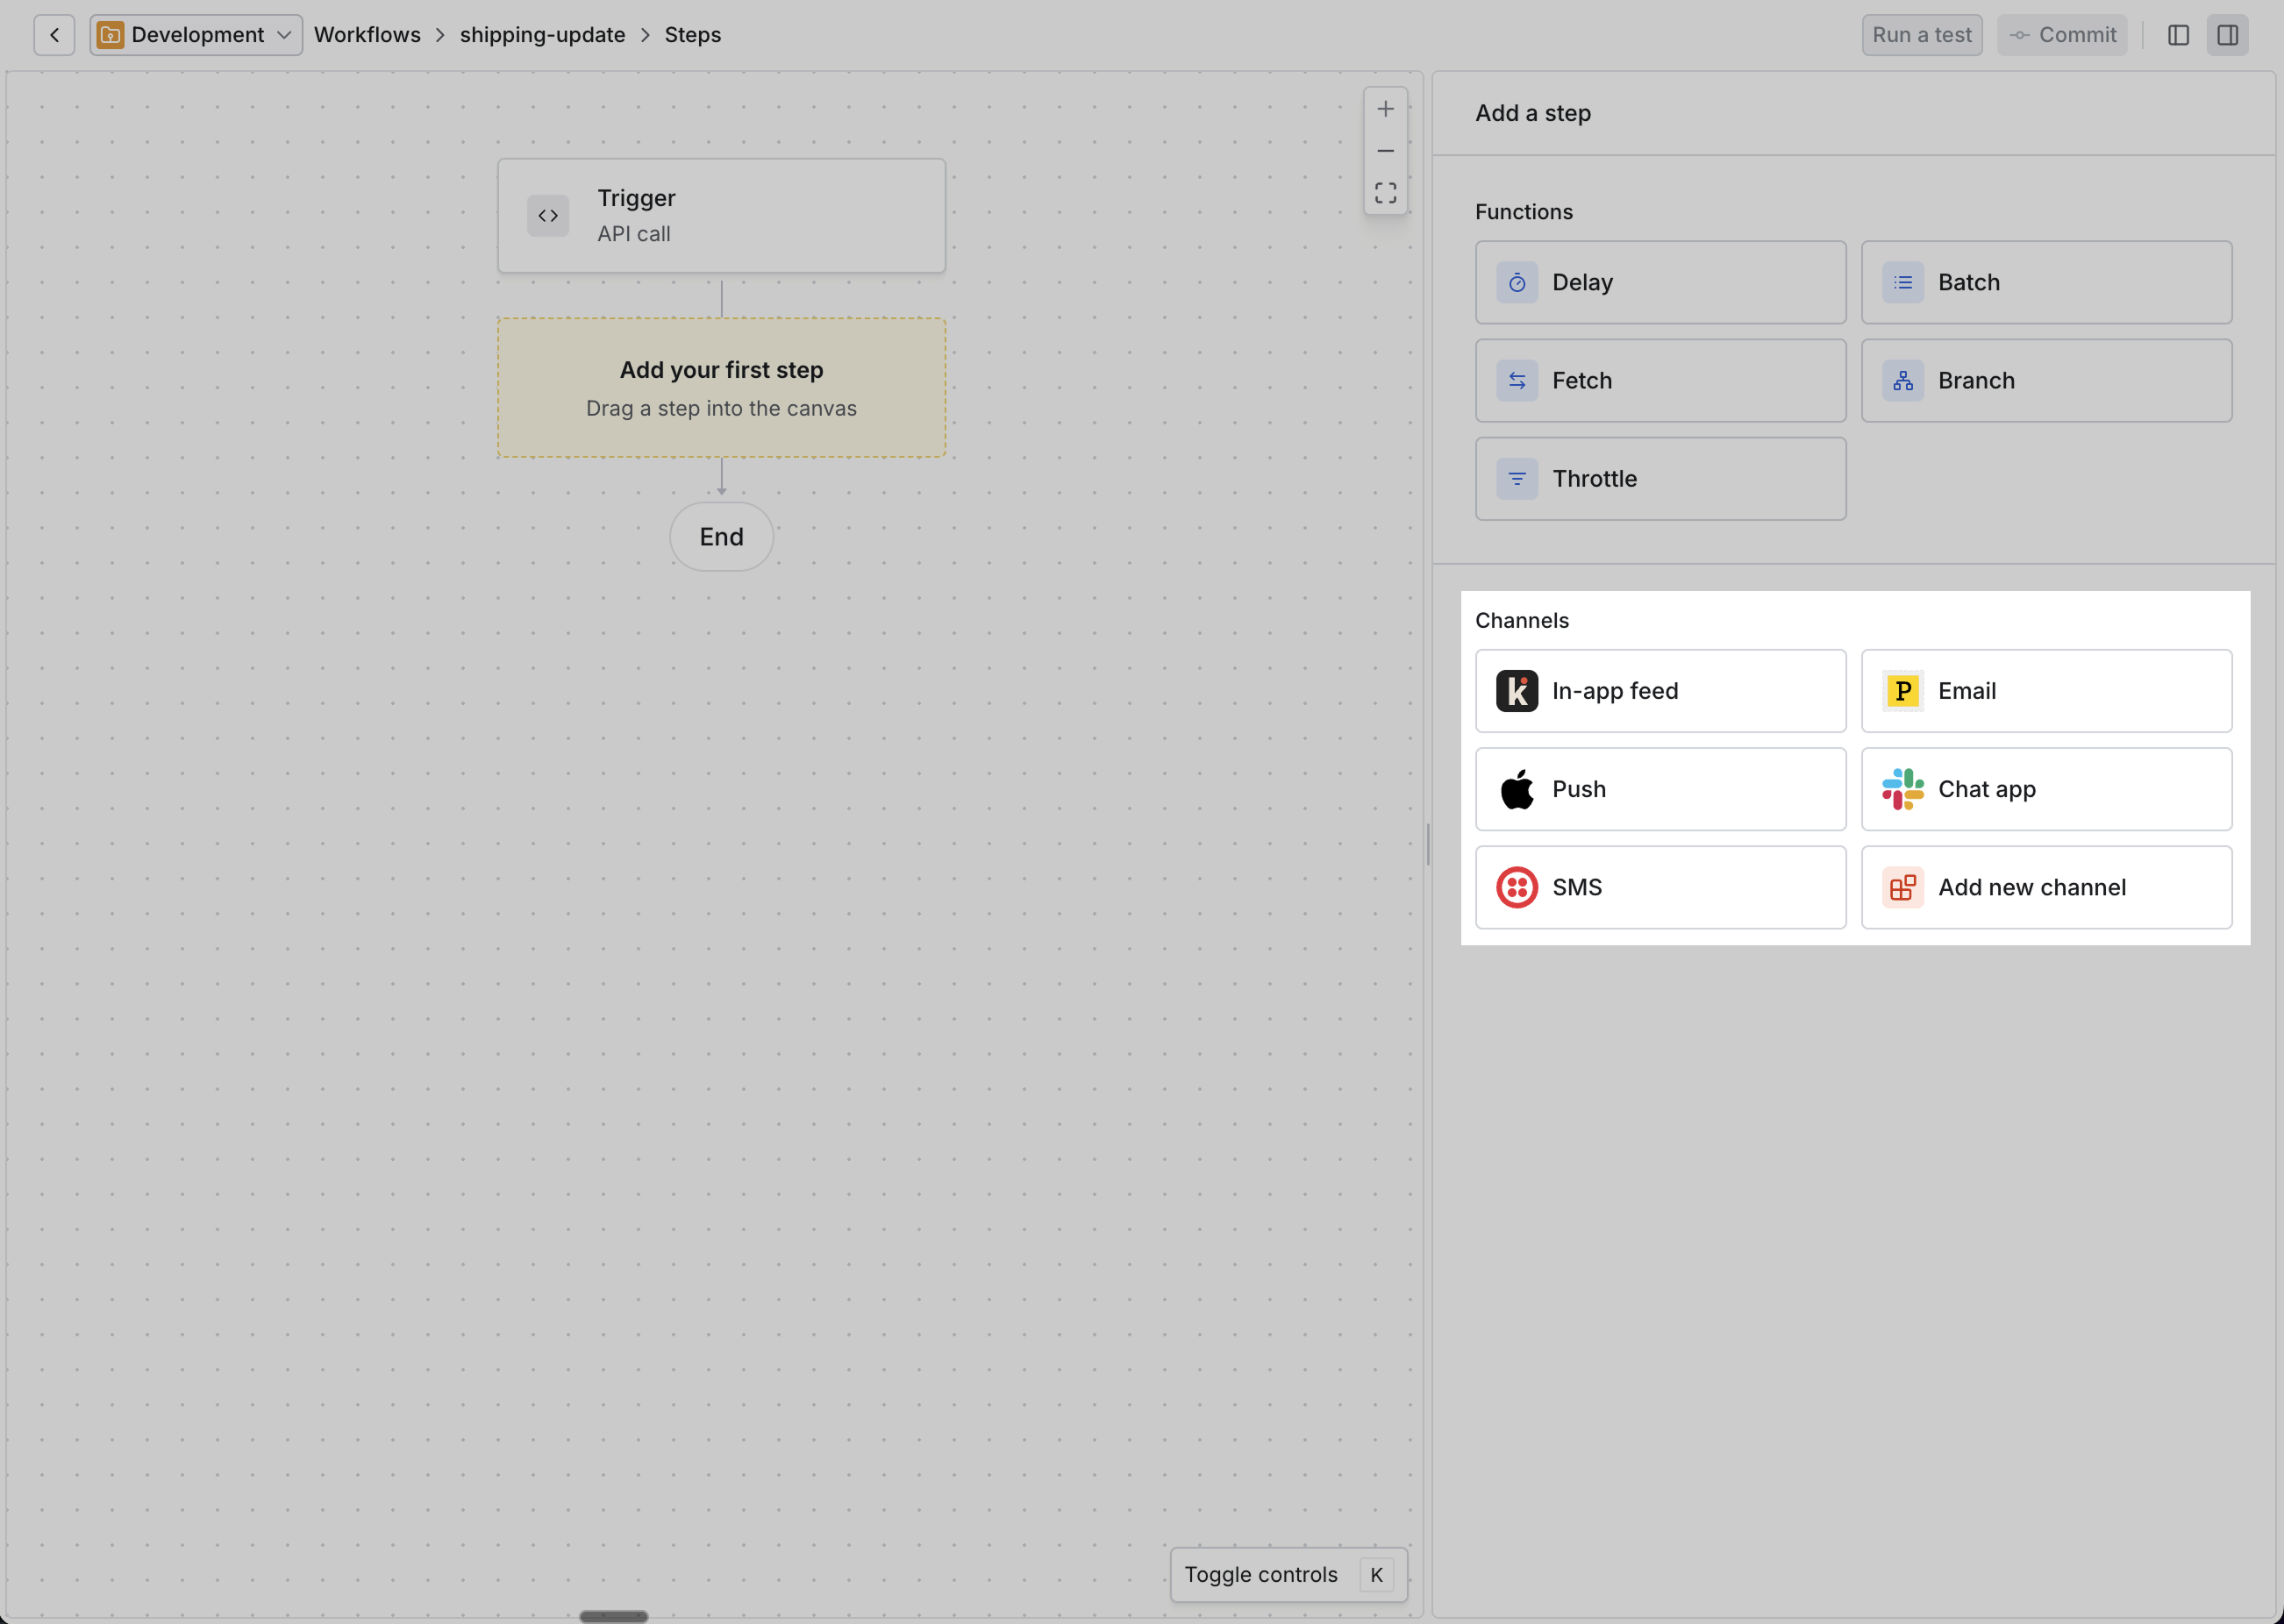 Choose the delivery channel you'd like to use in your workflow and drag it onto the workflow canvas.
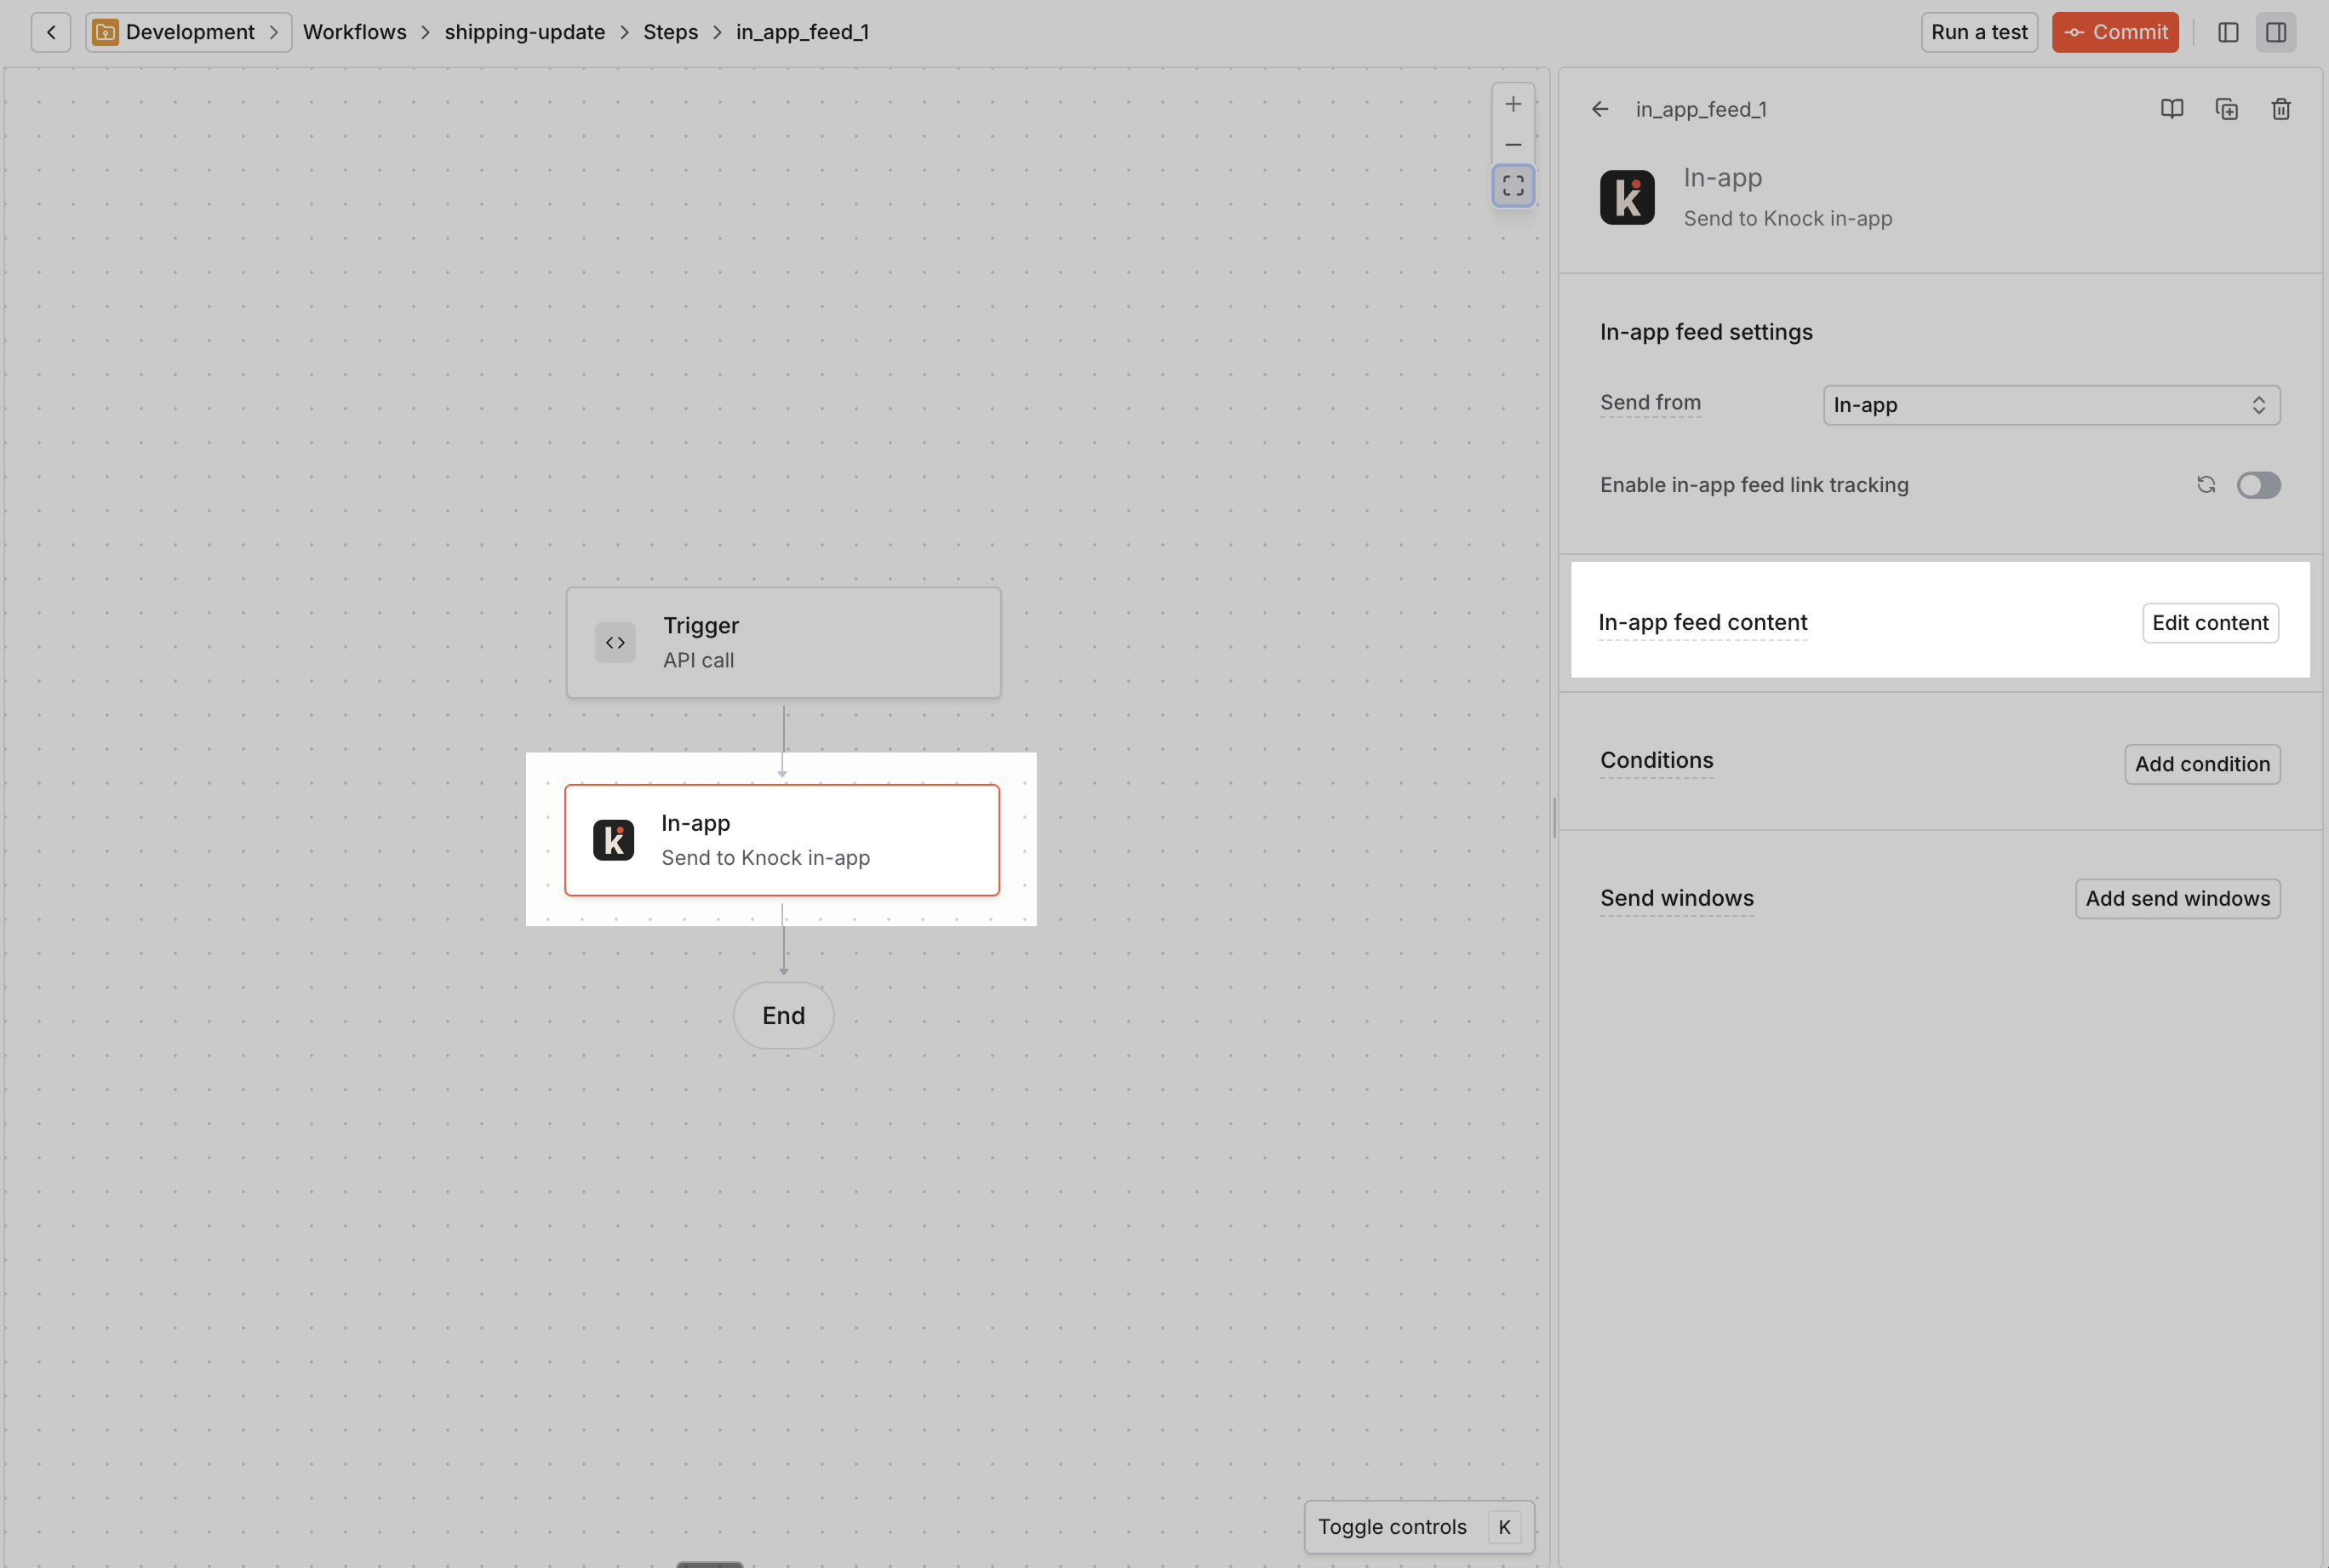 The template starts with default copy, so we'll just use that for now.
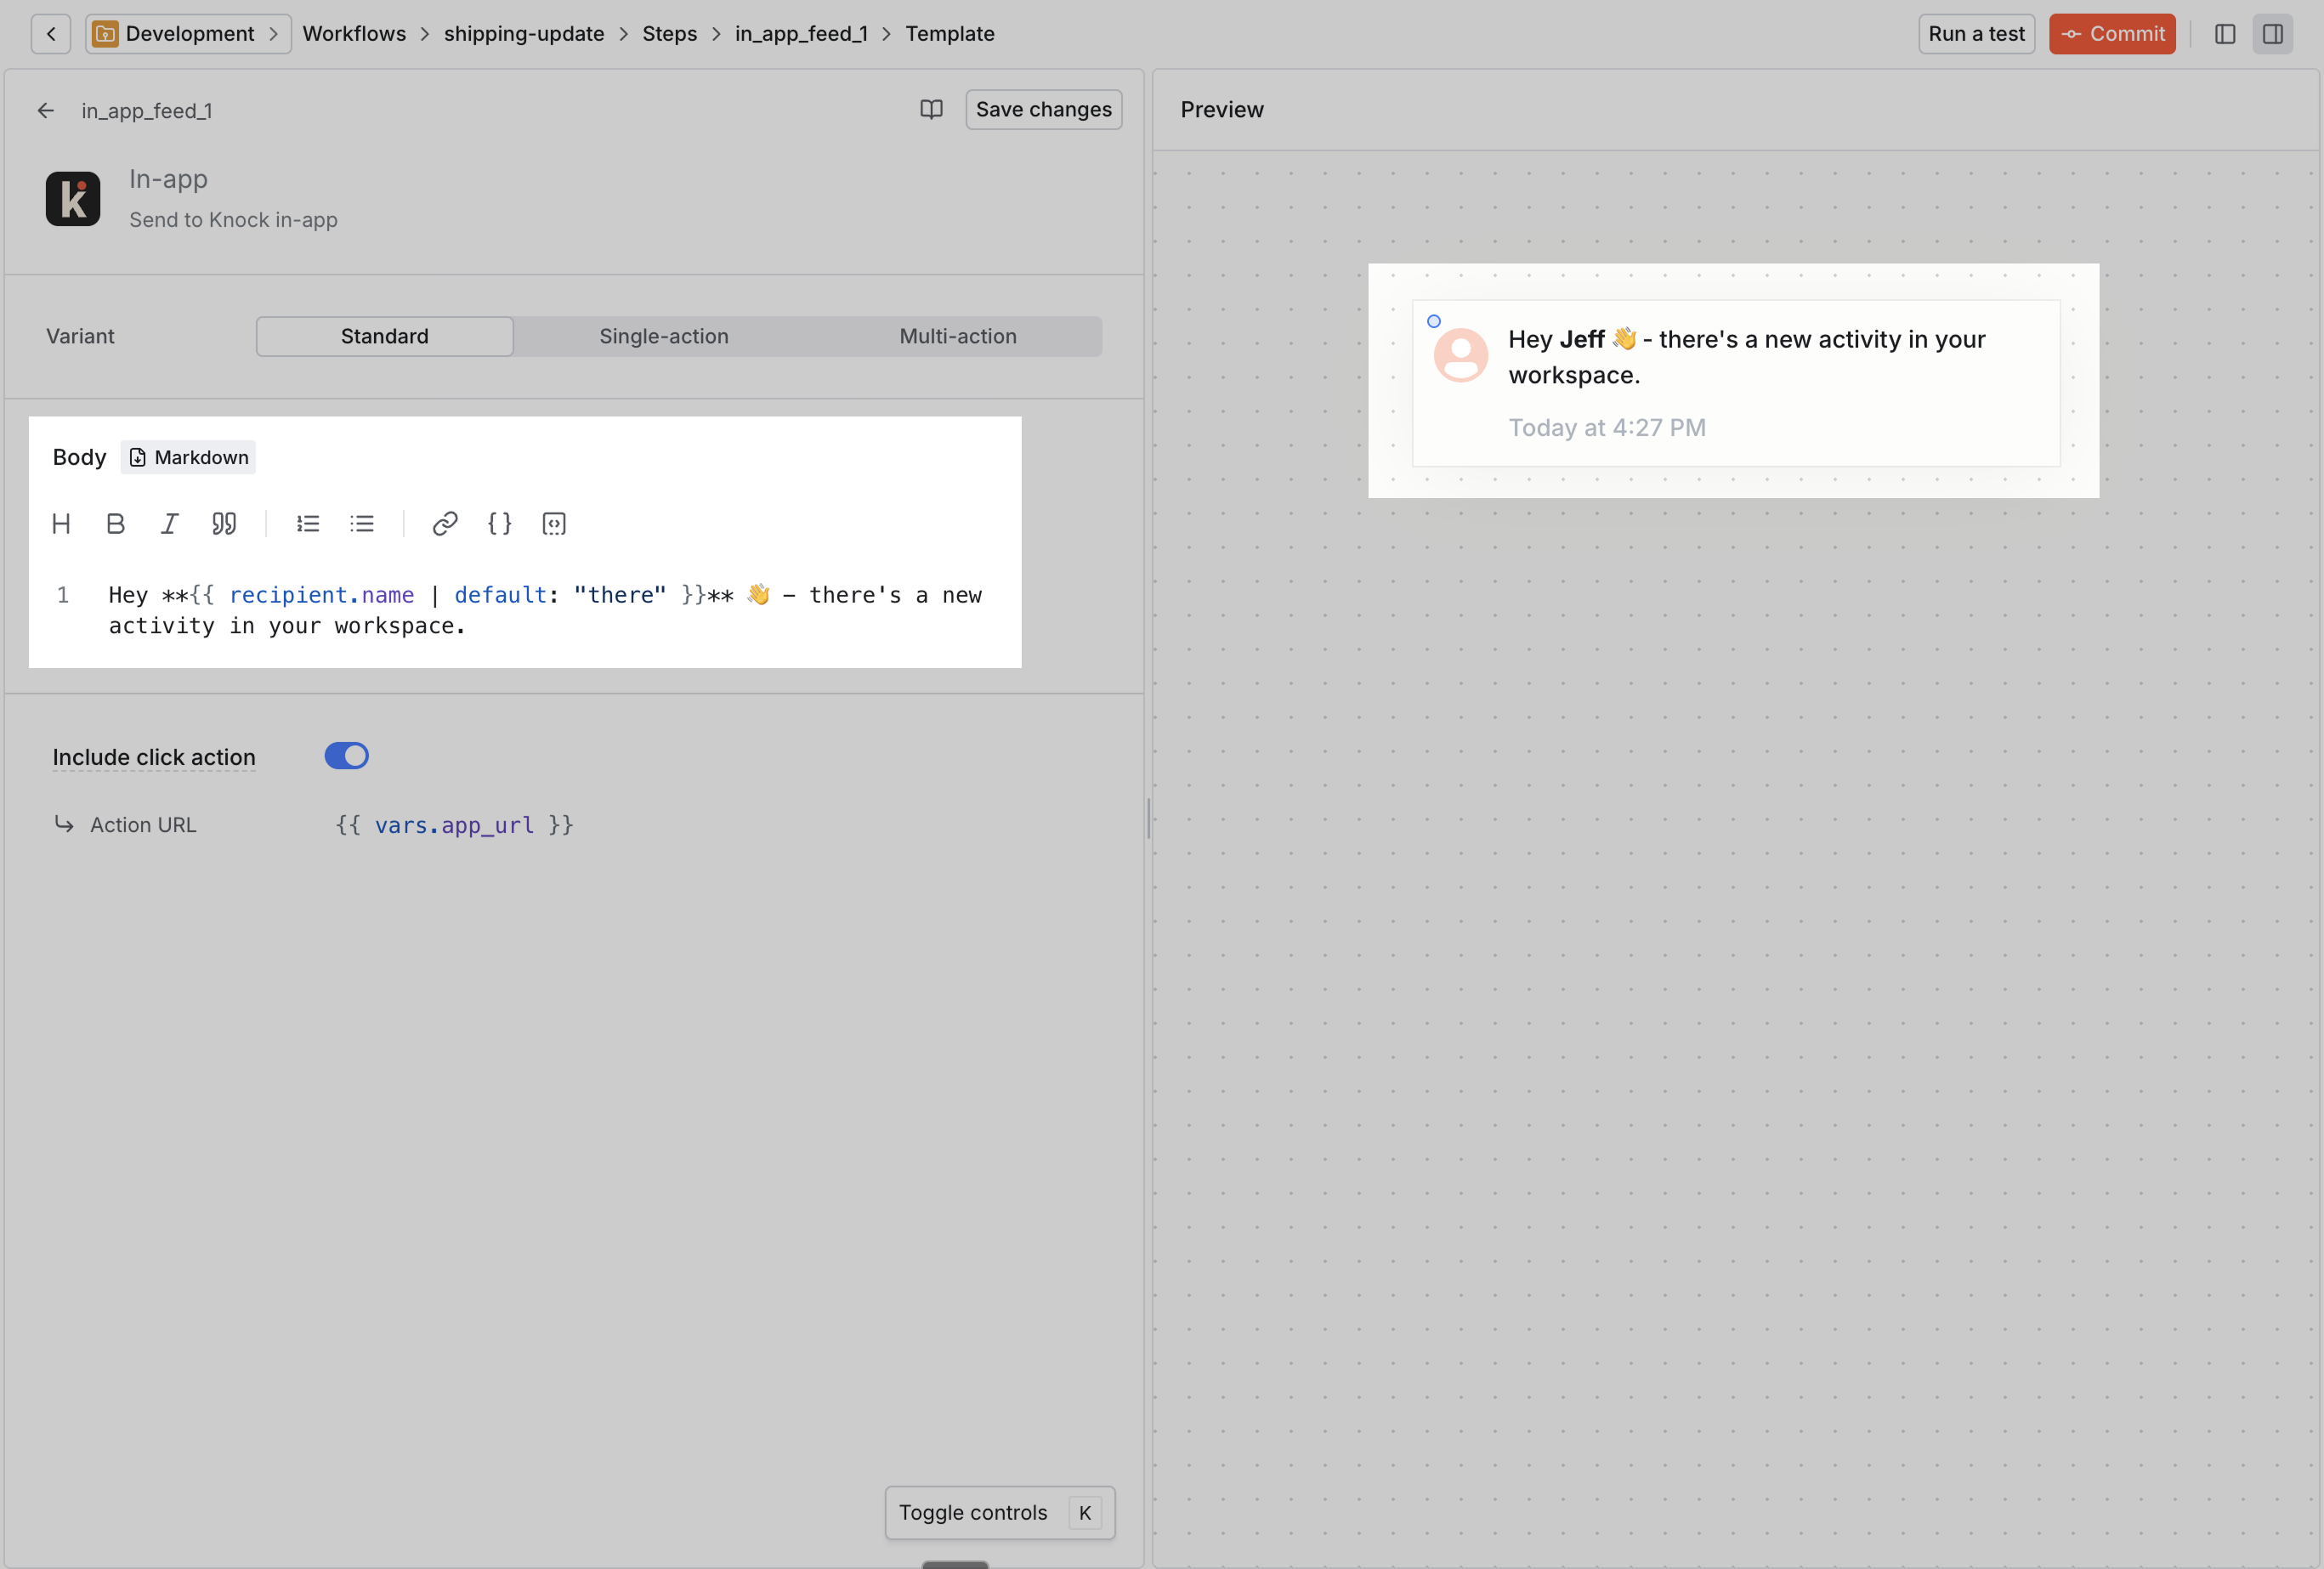
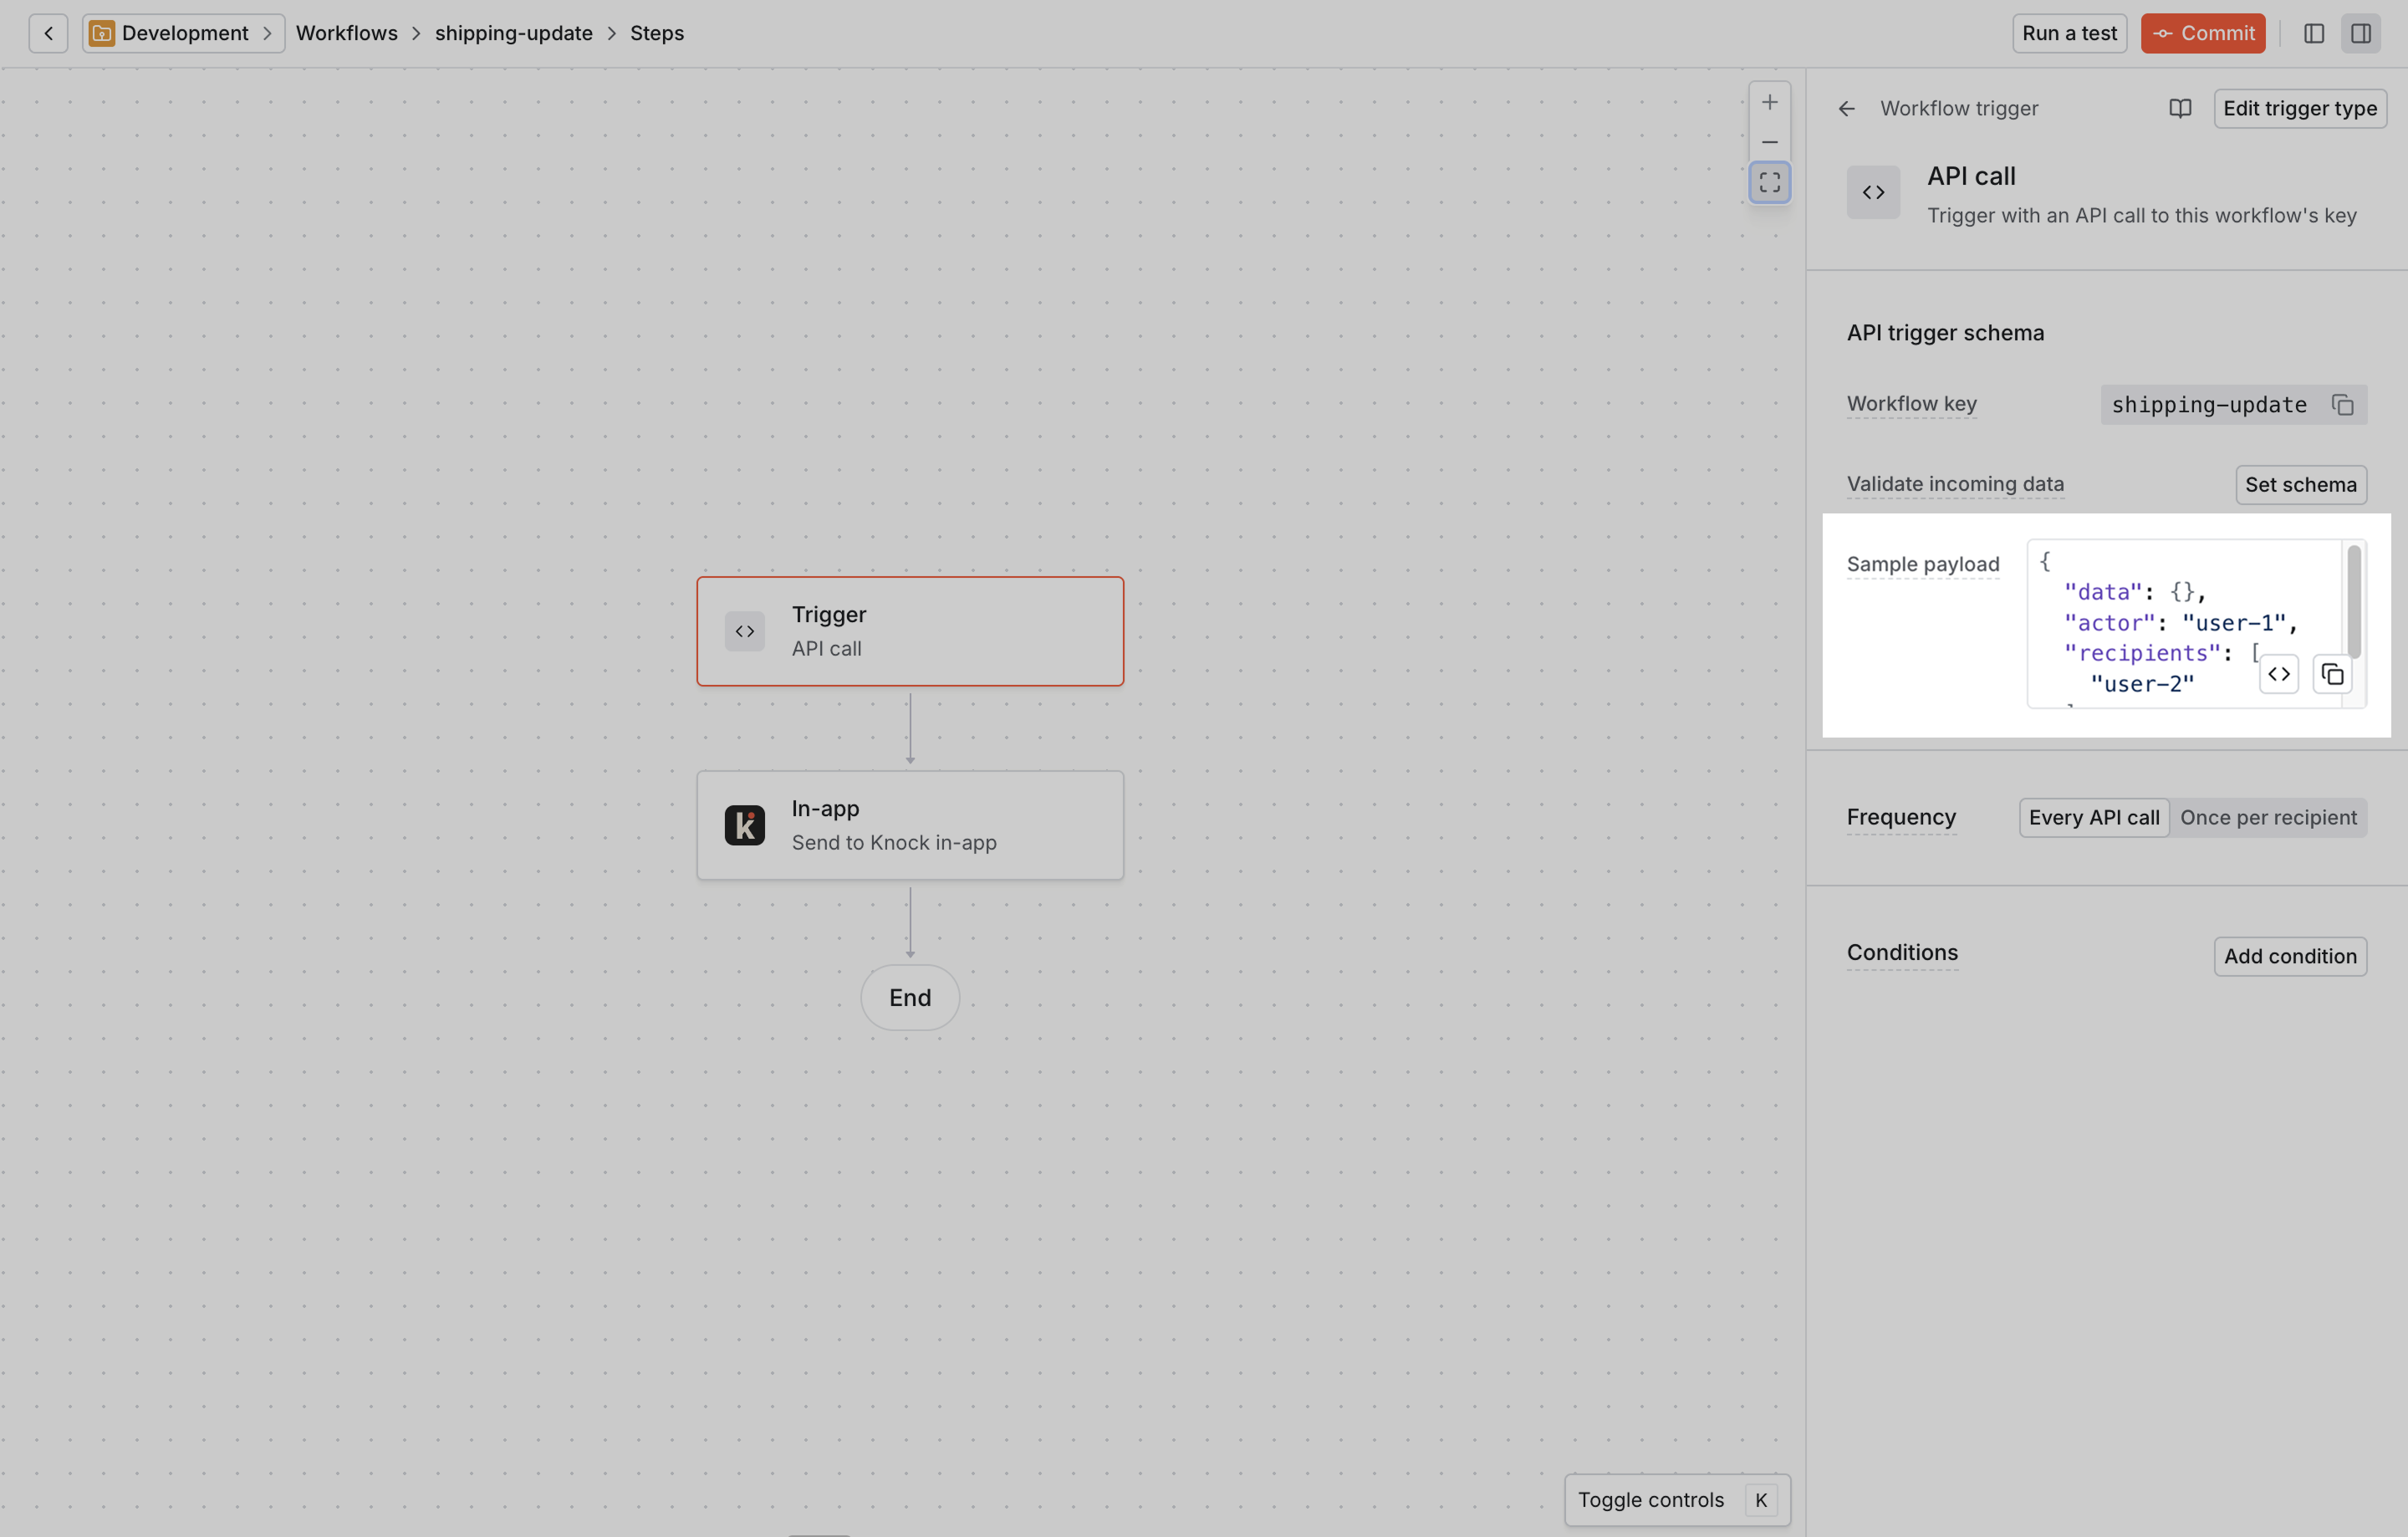 This sample payload is auto-generated when you create a workflow within the Knock dashboard. It gives us the JSON blob we'll need to pass through as `data` in our trigger call in order to populate any of the custom properties defined in our workflow.
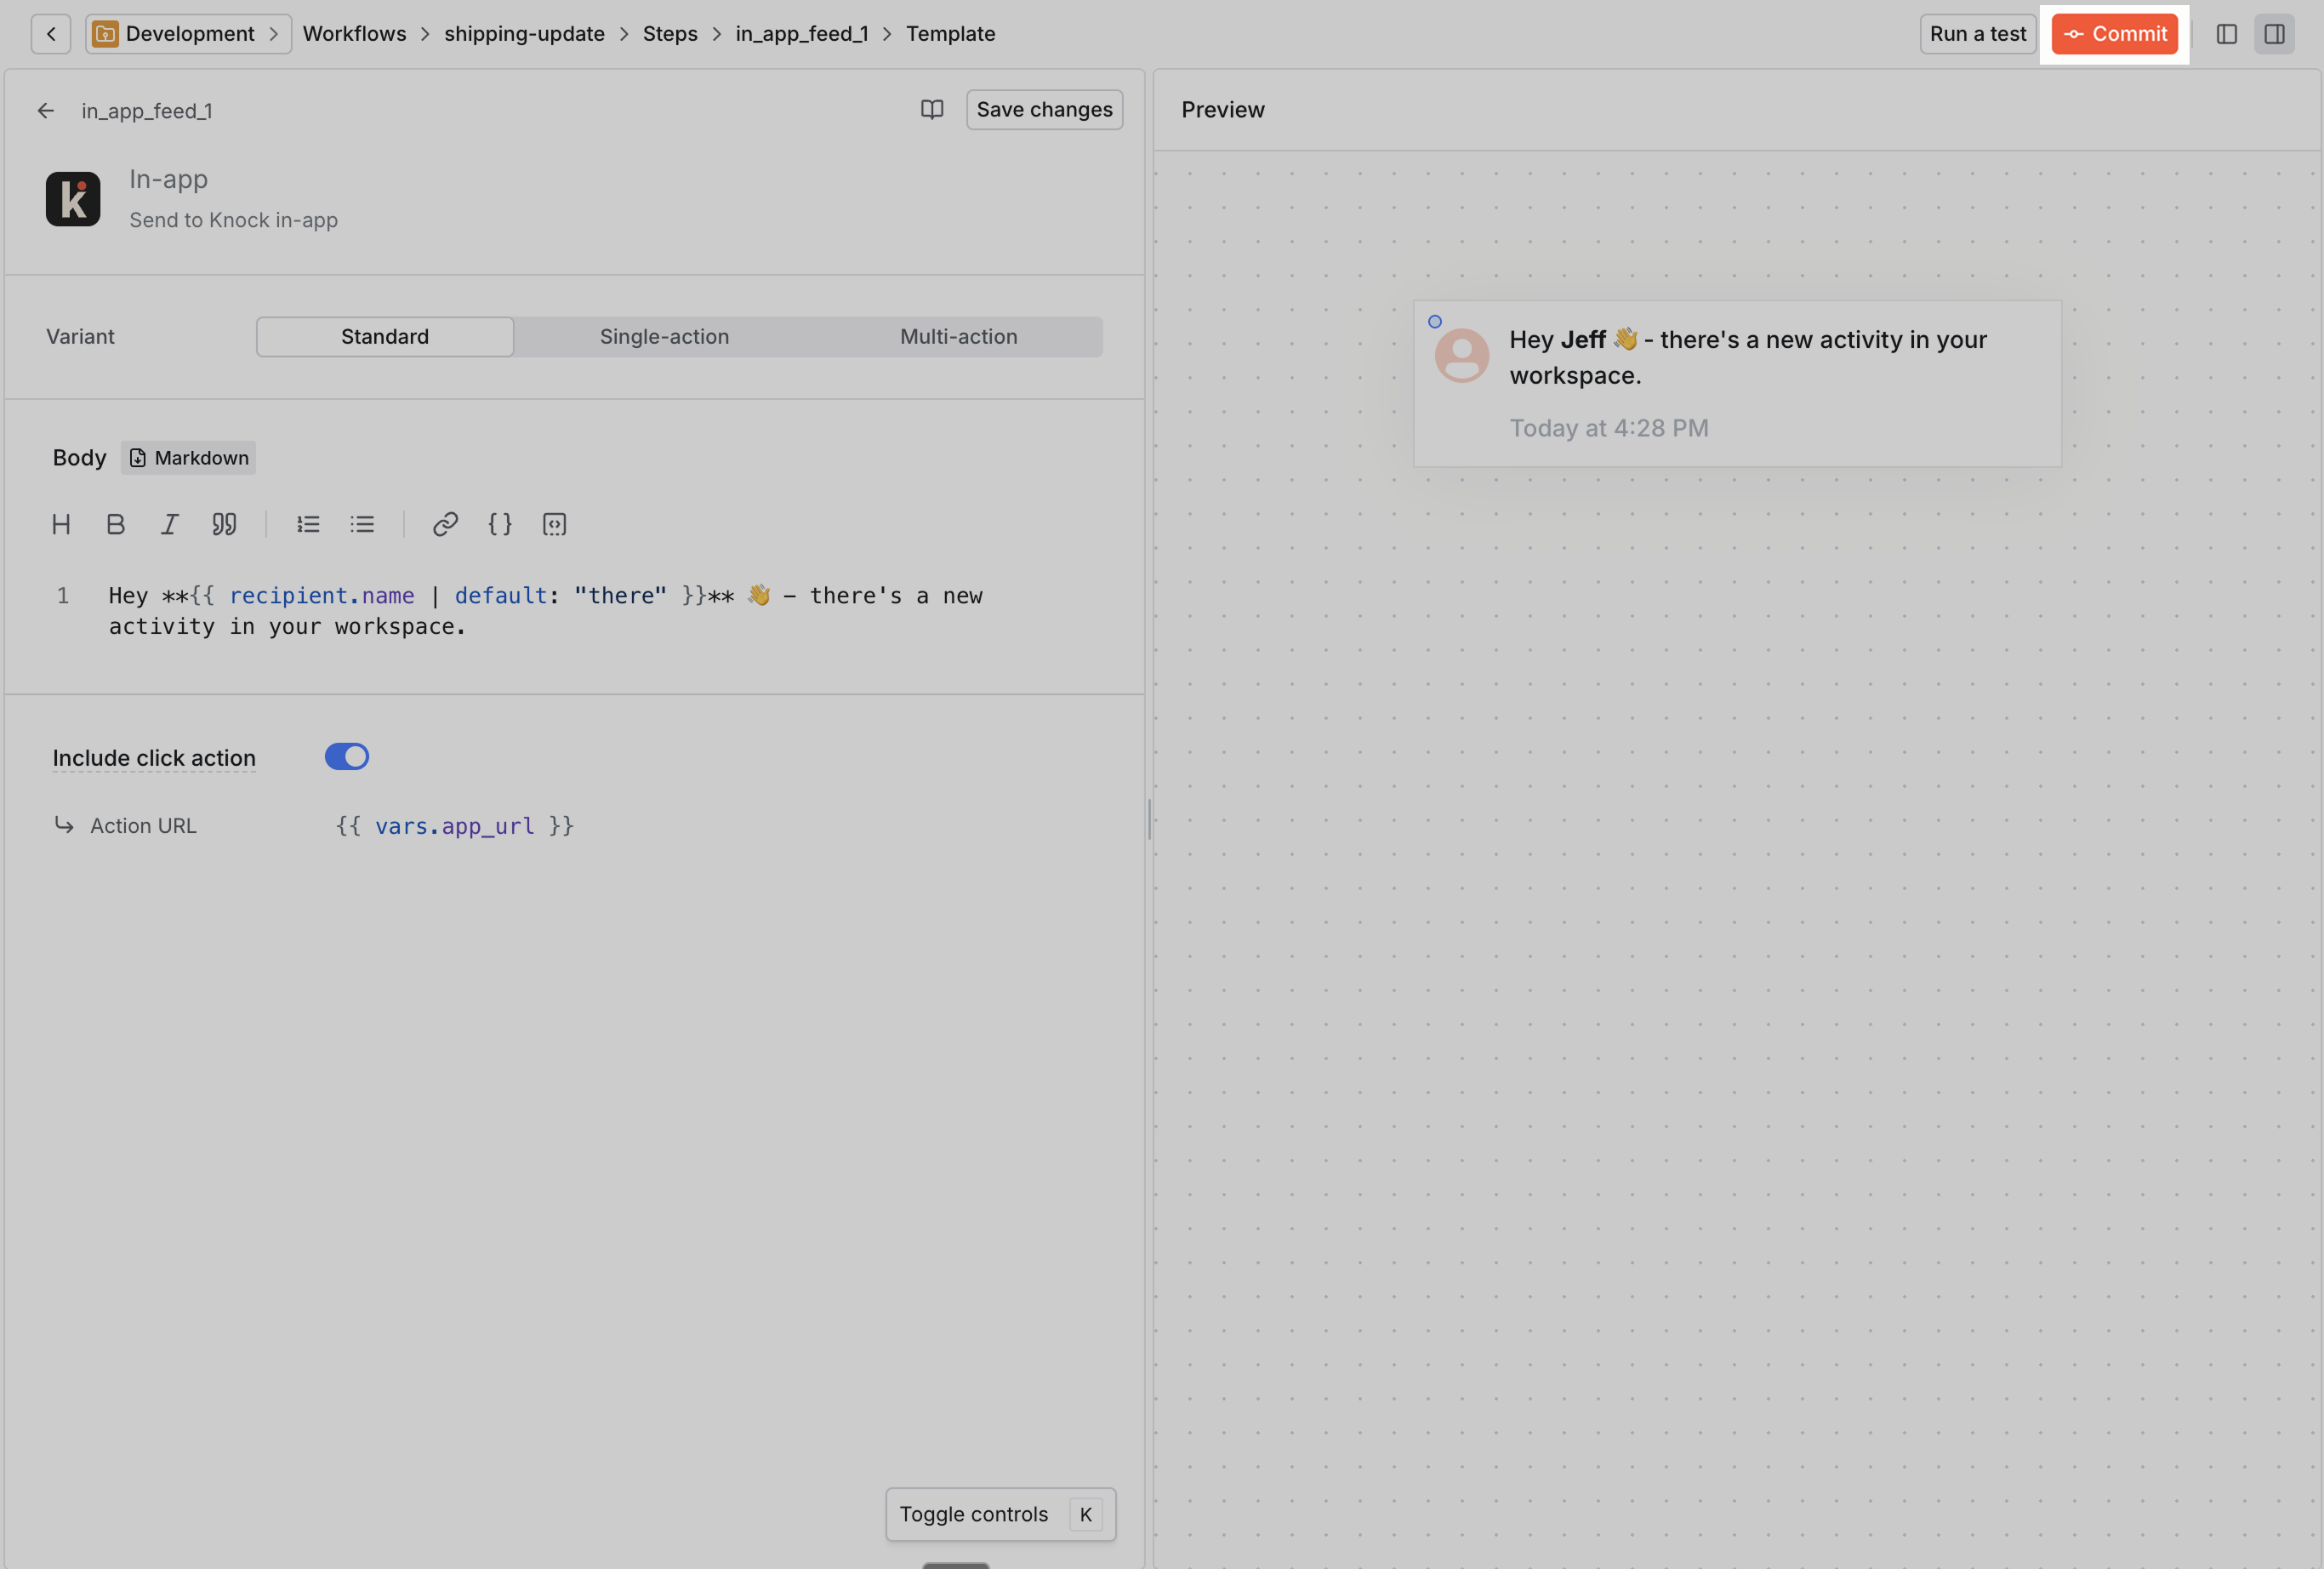 You do this using the `Commit` button in the header of the workflow canvas. You can review your changes using a diff viewer and leave a meaningful commit message about what has changed.
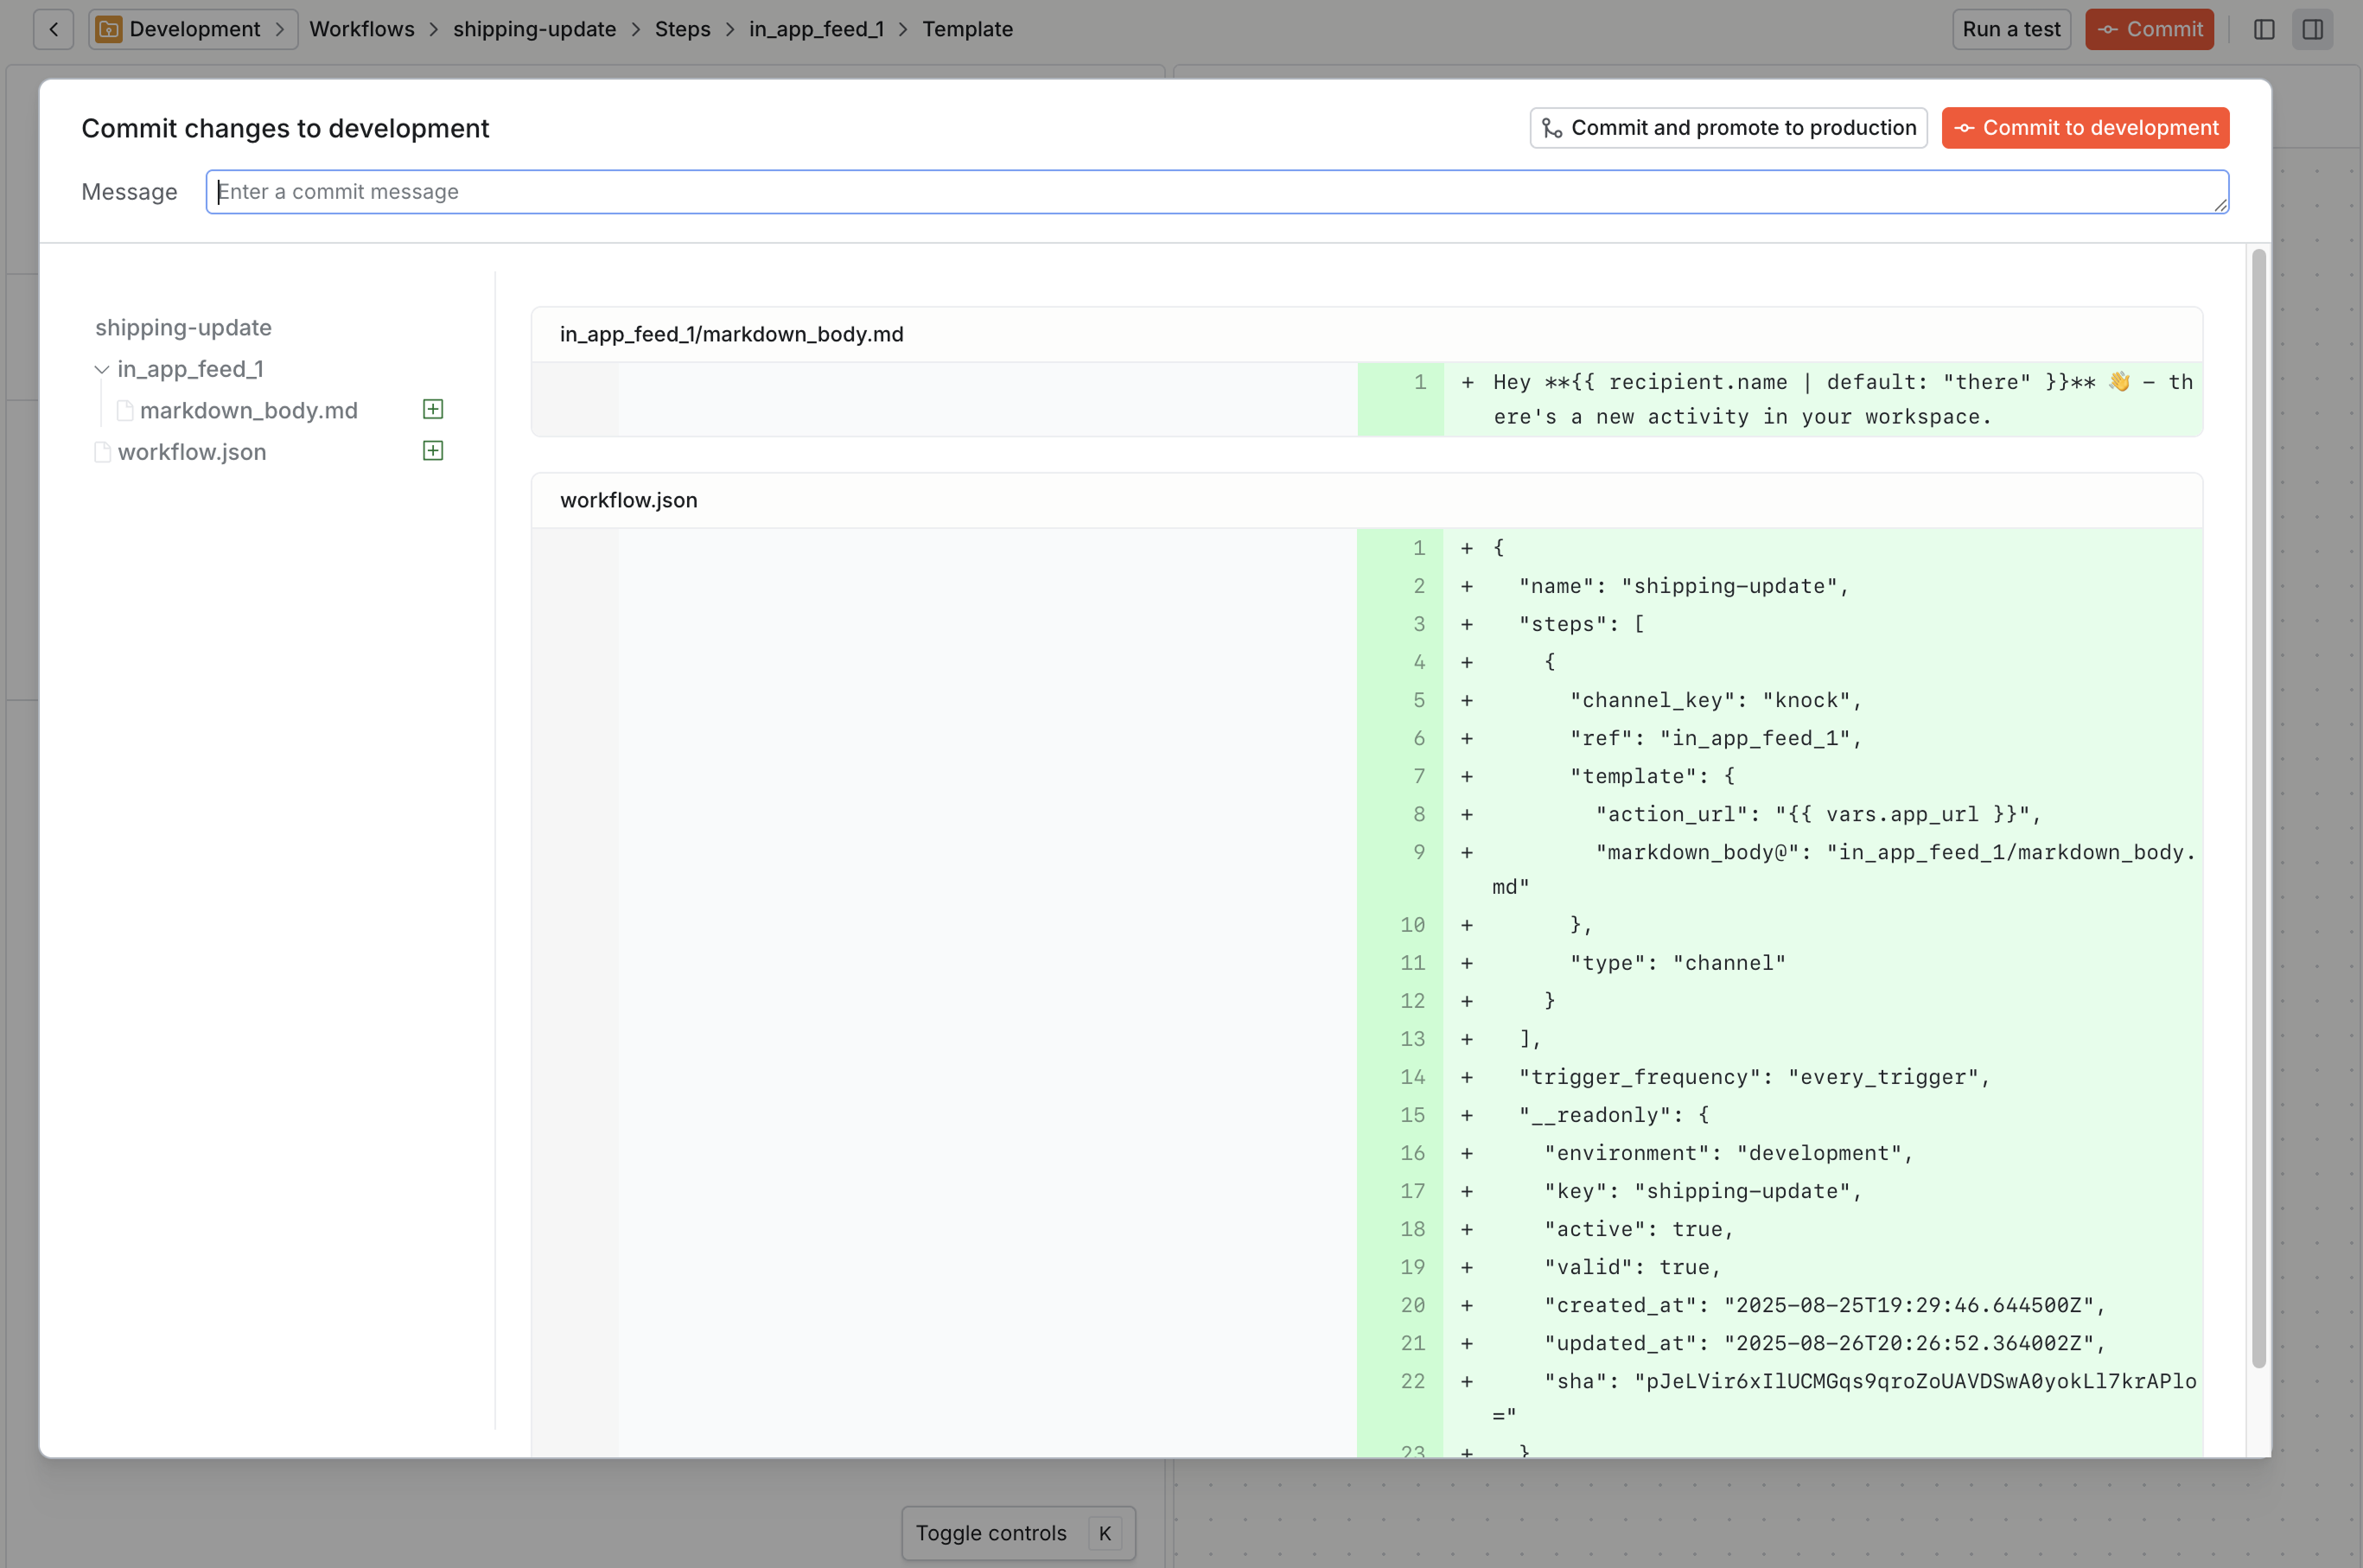
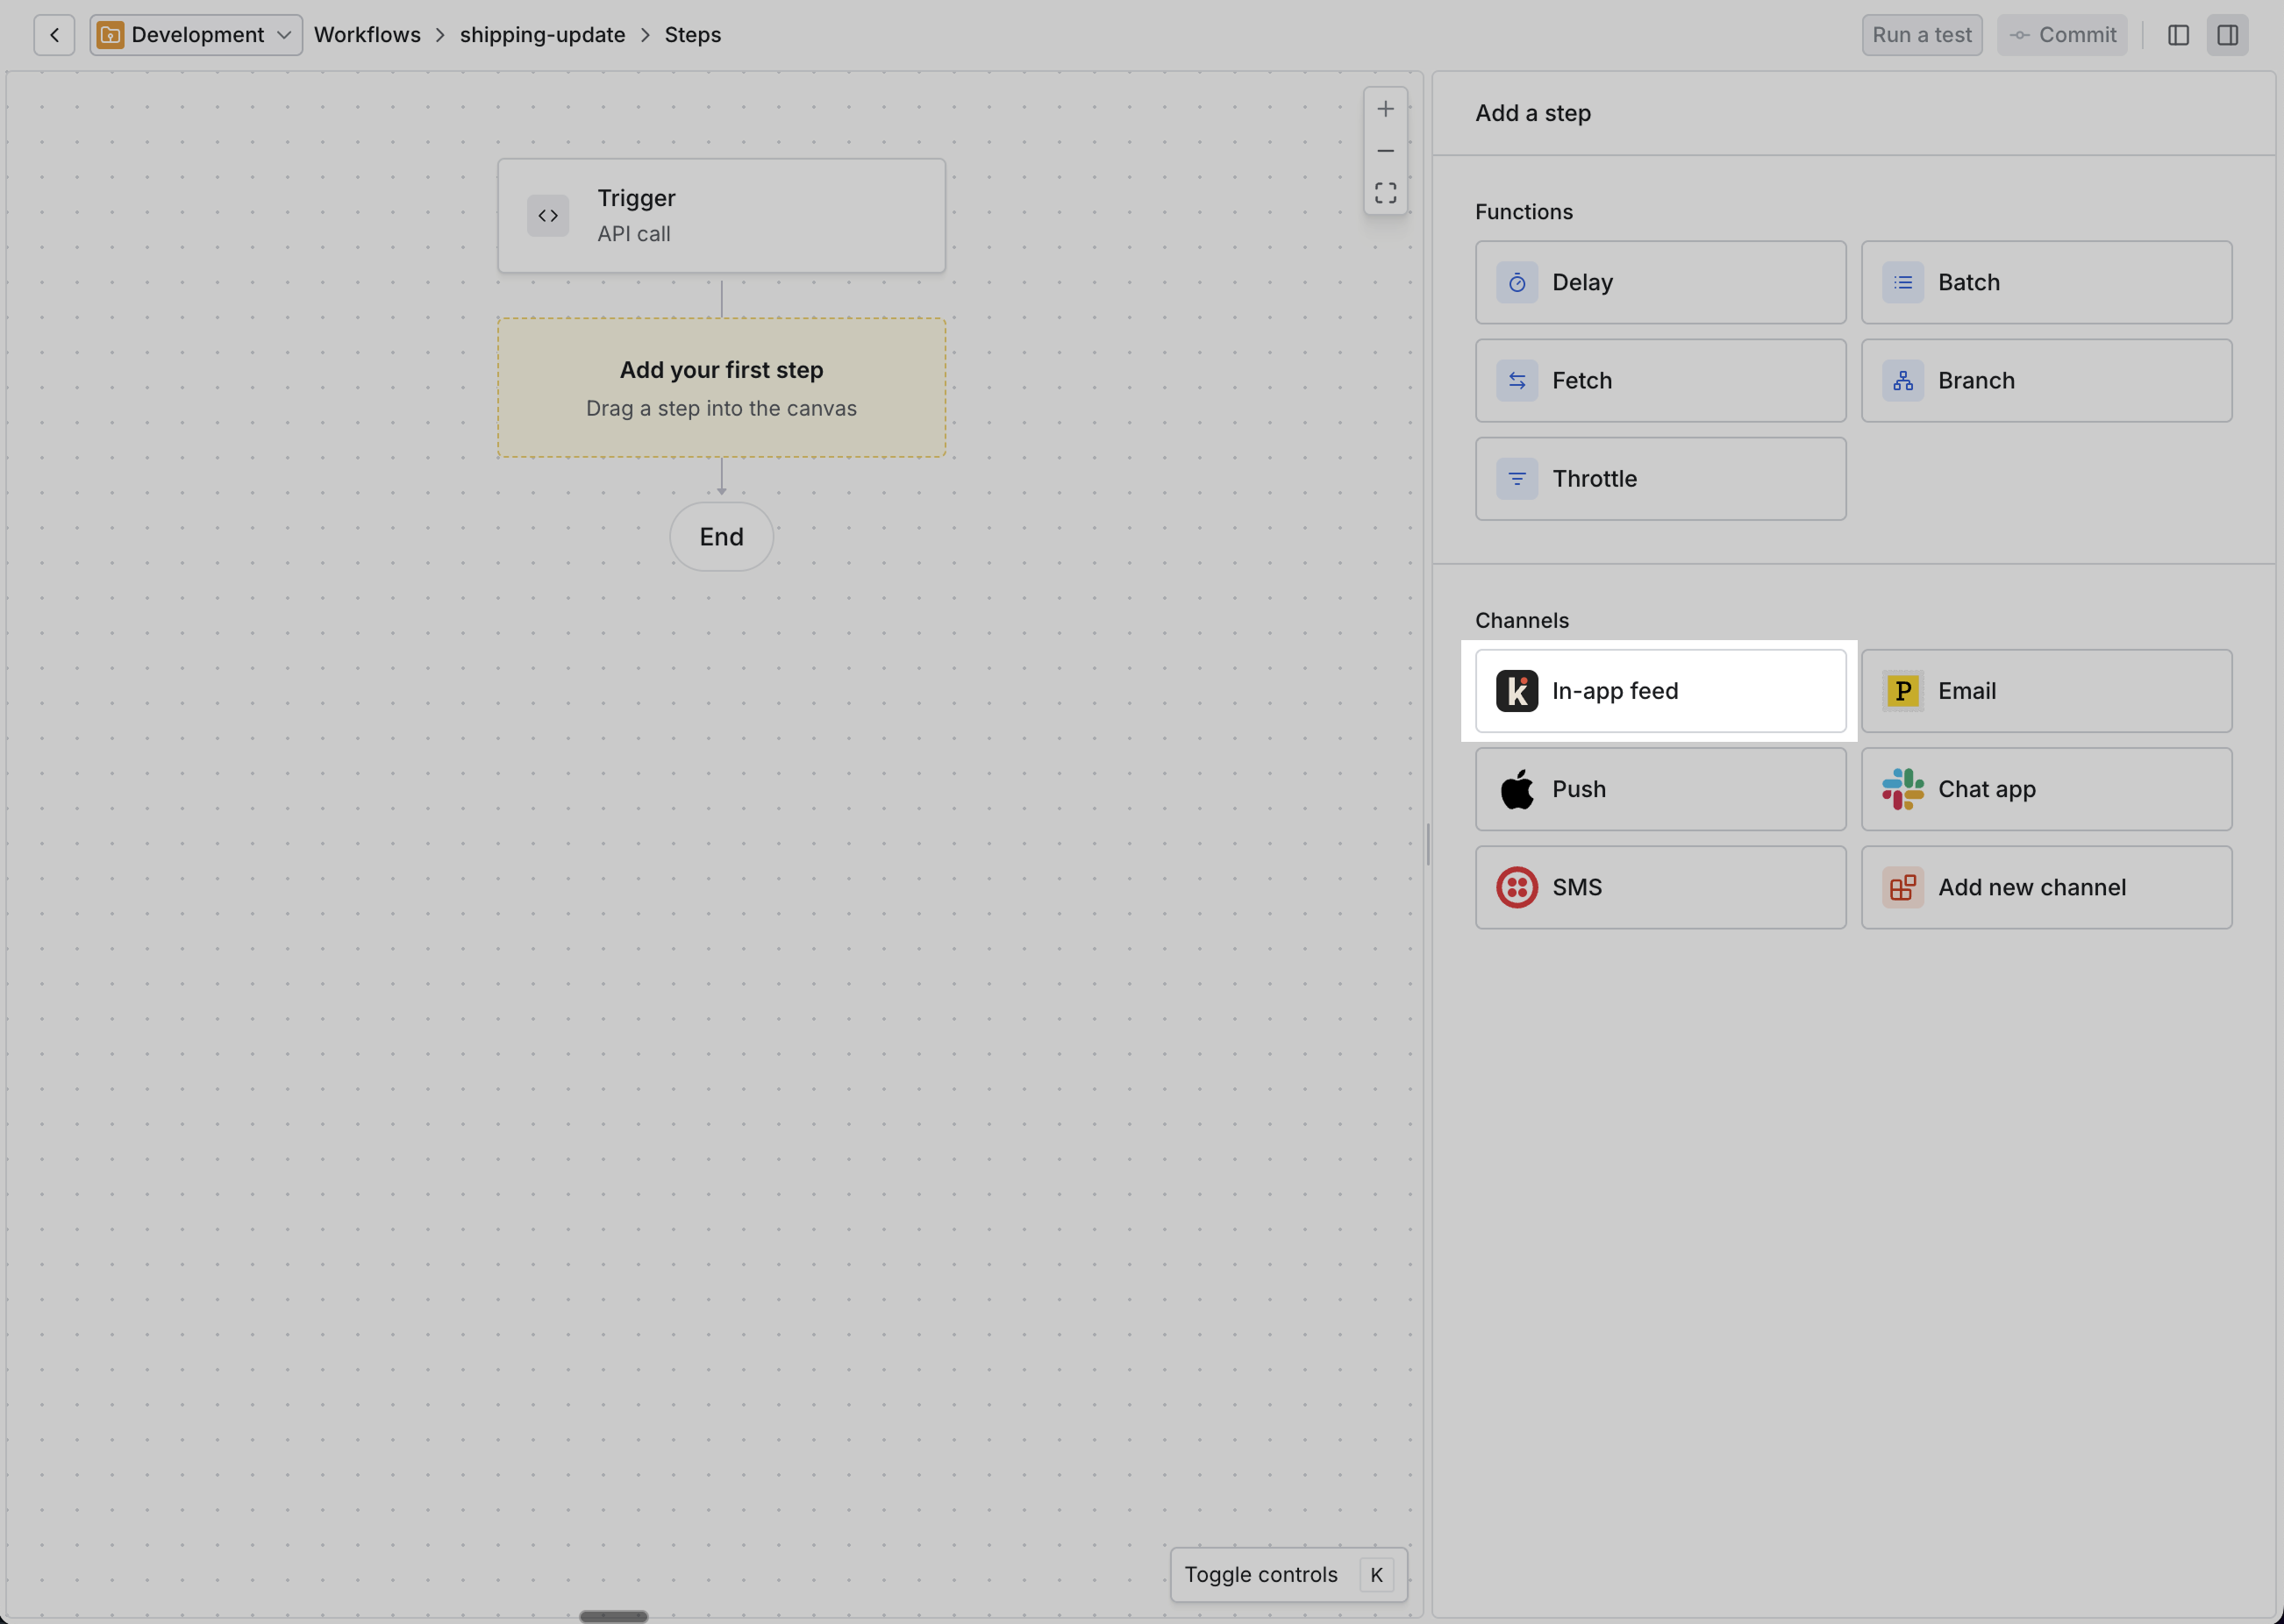 Drag the 'In-app feed' step onto the workflow canvas.
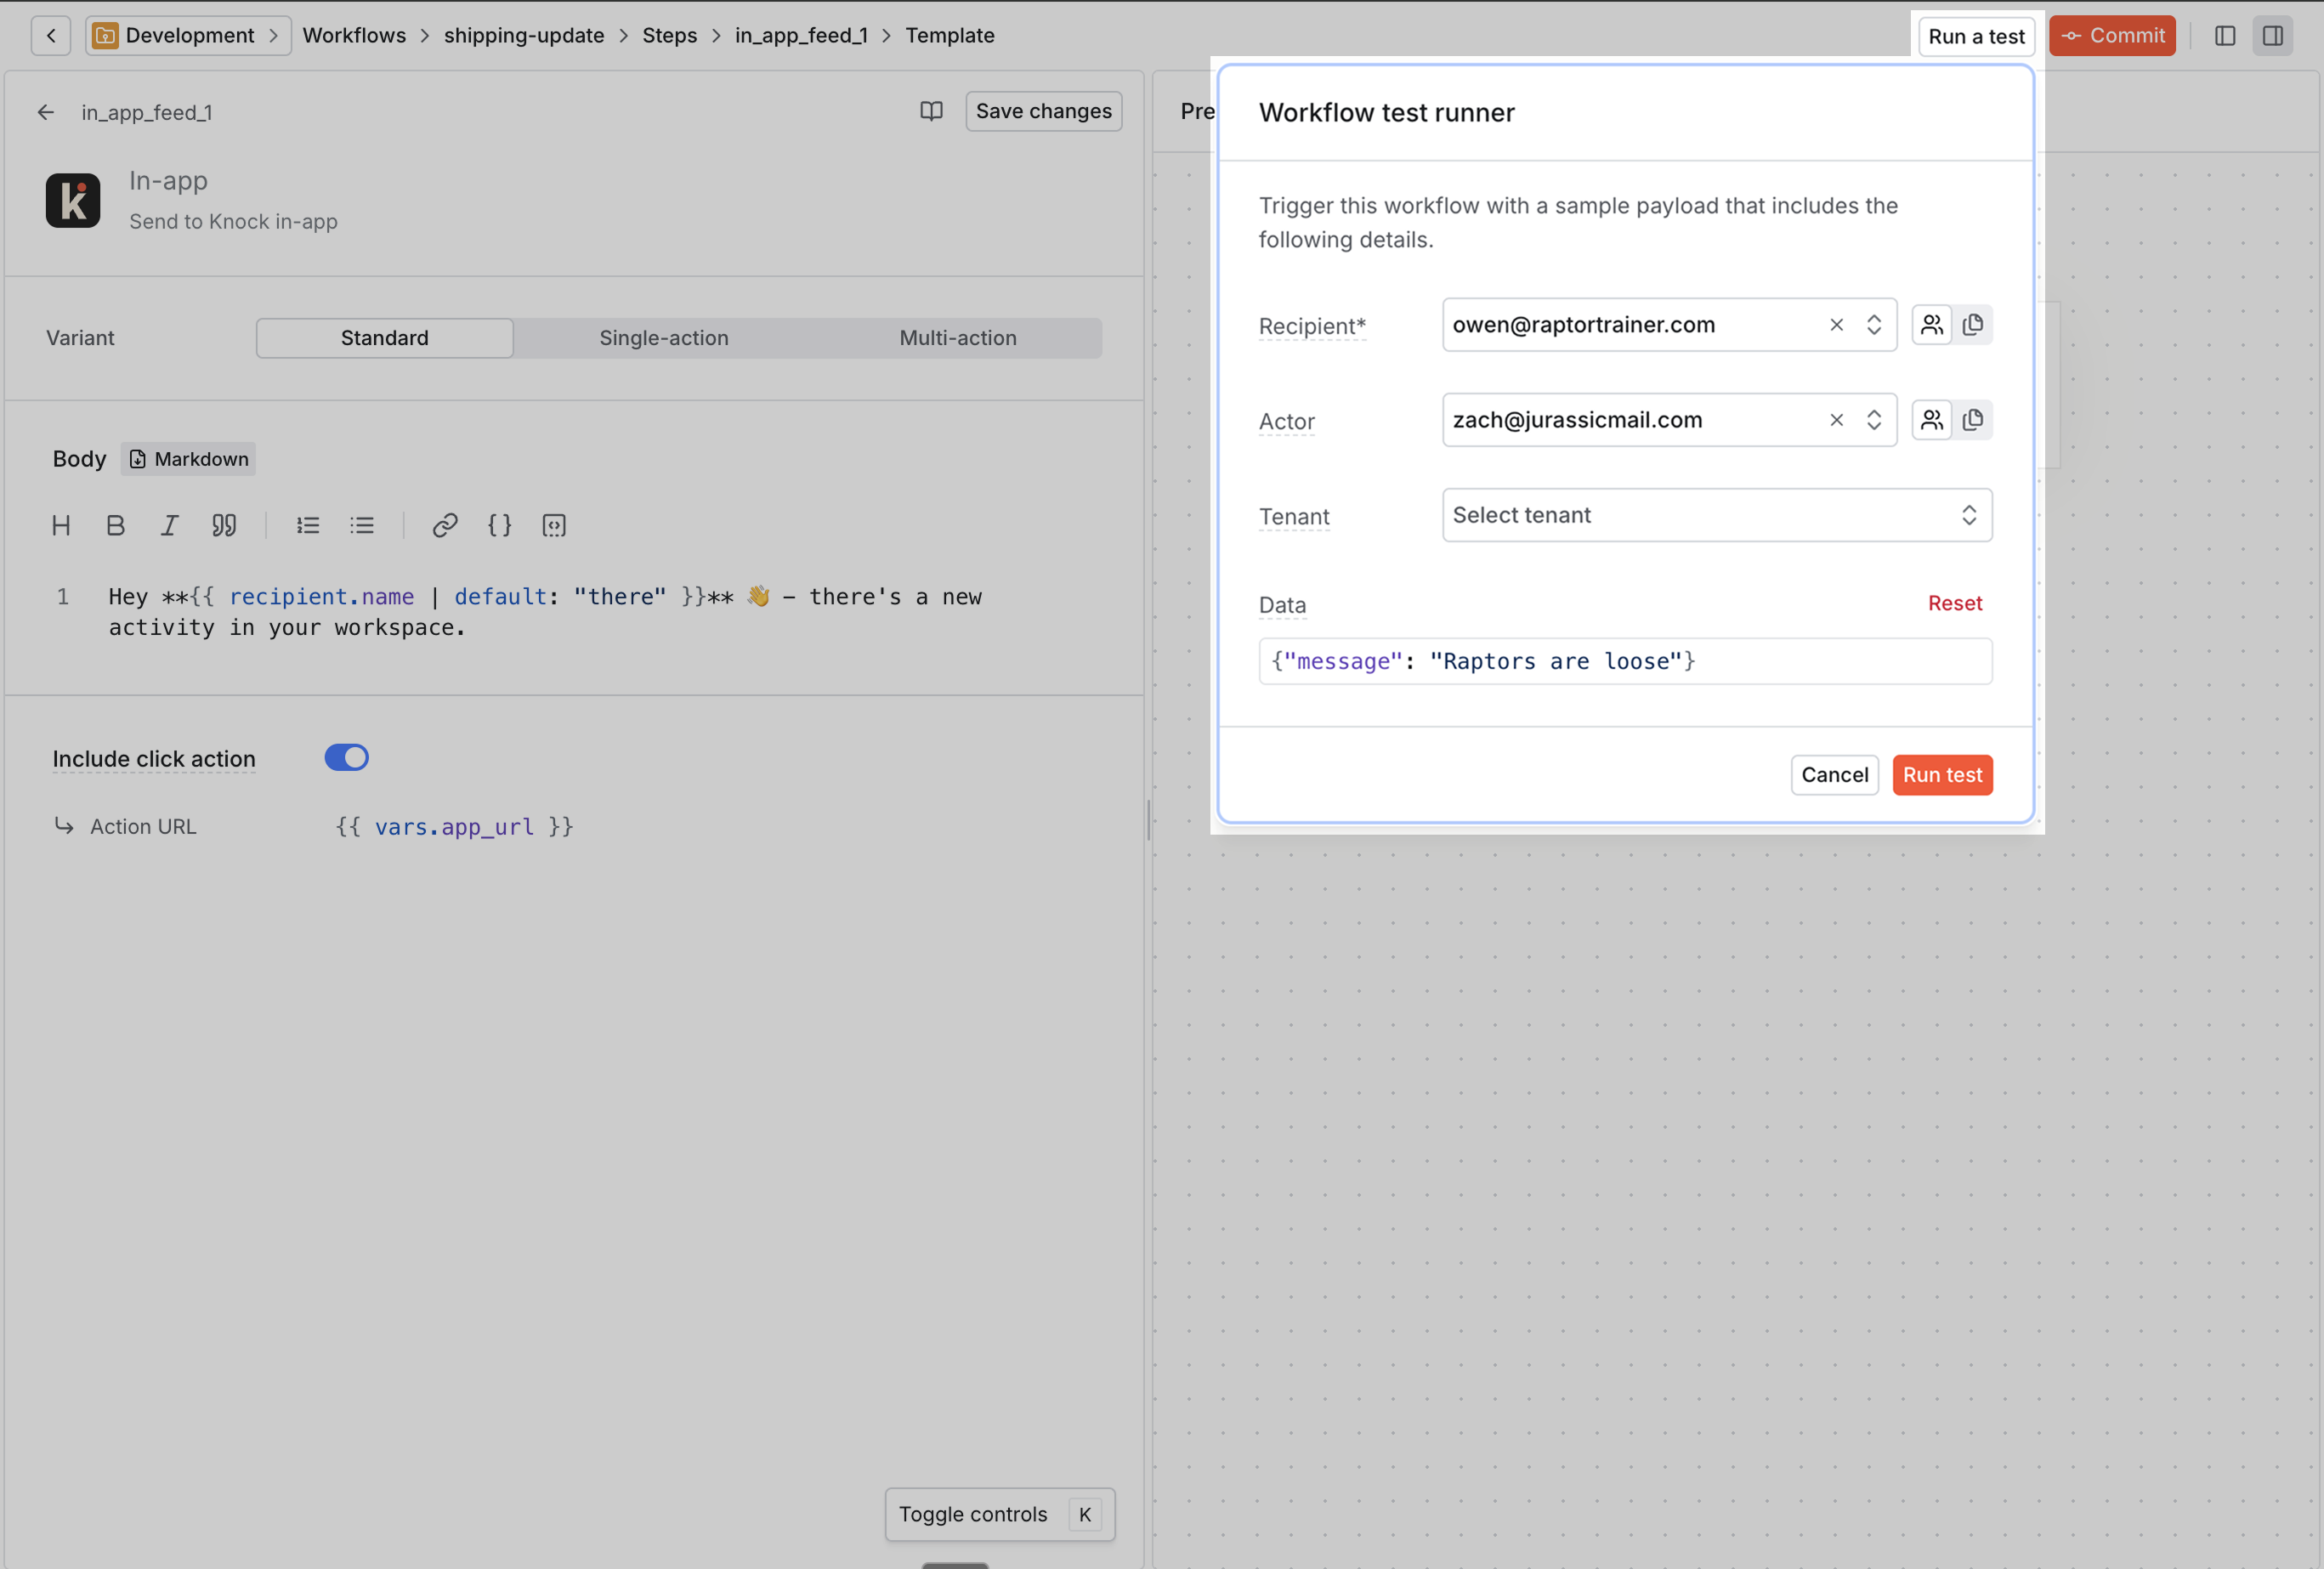 When triggering workflows, you need to provide the following required pieces of data in your call to the Knock API:
- `recipients` – The list of users to notify.
- `data` – The variable data that will populate your notification templates. Here you'll use the sample data payload we grabbed in the previous step.
In the example below, we trigger the `knock-quickstart` workflow for the `user` we identified with the feed.
```javascript title="Example server code to trigger workflow"
import Knock from "@knocklabs/node";
const knock = new Knock({ apiKey: process.env.KNOCK_API_KEY });
const user = {
id: "12c23775-5902-481a-b8ea-d1704aabc769",
};
await knock.workflows.trigger("knock-quickstart", {
data: { message: "Here's a message" },
recipients: [user.id],
});
```
Learn more about trigger calls in our [API reference](/api-reference/workflows/trigger).